diff --git a/CONTRIBUTING.md b/CONTRIBUTING.md
index 7dc8ec84..d6fe42b0 100644
--- a/CONTRIBUTING.md
+++ b/CONTRIBUTING.md
@@ -26,24 +26,33 @@ deceptive characters.
## Release notes: written with the change, not at release time
-Every commit that changes what an operator can observe adds its line to the
+Every commit that implements a new user feature adds its line to the
current unreleased entry in `internal/whatsnew/registry.go`, in that same
-commit. What a change meant to the person running ProxSave is known while it is
+commit. What a feature means to the person running ProxSave is known while it is
being made and reconstructed badly weeks later, so batching the notes to
release time is how entries go missing.
+Individual fixes and refinements do not get their own lines, even when the
+operator can see the change. When a release has no new features, use exactly
+one `Lines` entry:
+
+`This release includes a collection of fixes and corrections.`
+
+If a new feature is added before release, replace that generic line with the
+feature notes.
+
The current unreleased entry is the last one in `notes`: the version above the
newest git tag. When the newest tag already covers that entry, append a new one
for the next version.
-- `Lines` are what changed, from the operator's side. Screen 0 caps them at
+- `Lines` describe new features from the operator's side, with the single
+ generic line above for releases without new features. Screen 0 caps them at
**8**. When the eight are full, do not quietly drop one to make room: say so,
and let the maintainer decide what gives way.
- `Actions` are what the operator has to do about it, and are not capped.
- Every string is ASCII only (no em-dash, en-dash or emoji), 120 characters or
fewer, and free of placeholder text.
-- A change with nothing an operator can observe (a refactor, a test, a comment)
- gets no line. Say it got none rather than inventing one.
+- A fix, a refinement, a refactor, a test or a comment gets no individual line.
`TestRegistryWellFormed` enforces the mechanical rules on every PR, so run
`go test ./internal/whatsnew/` before you commit.
diff --git a/NOTICE b/NOTICE
index 515c5ca2..afd82eaf 100644
--- a/NOTICE
+++ b/NOTICE
@@ -6,7 +6,7 @@ binaries, plus third-party source included directly in the tree.
---
-## charm.land/bubbles/v2 v2.1.1
+## charm.land/bubbles/v2 v2.2.1
**License:** MIT
@@ -38,7 +38,7 @@ SOFTWARE.
---
-## charm.land/bubbletea/v2 v2.0.8
+## charm.land/bubbletea/v2 v2.0.9
**License:** MIT
@@ -70,7 +70,7 @@ SOFTWARE.
---
-## charm.land/lipgloss/v2 v2.0.5
+## charm.land/lipgloss/v2 v2.0.6
**License:** MIT
@@ -102,7 +102,7 @@ SOFTWARE.
---
-## filippo.io/age v1.3.1
+## filippo.io/age v1.3.2
**License:** BSD-3-Clause
@@ -142,7 +142,7 @@ OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
---
-## filippo.io/edwards25519 v1.1.1
+## filippo.io/edwards25519 v1.2.0
**License:** BSD-3-Clause
@@ -218,6 +218,36 @@ OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
---
+## github.com/Masterminds/semver/v3 v3.5.0
+
+**License:** MIT
+
+**Source:** https://github.com/Masterminds/semver
+
+```
+Copyright (C) 2014-2019, Matt Butcher and Matt Farina
+
+Permission is hereby granted, free of charge, to any person obtaining a copy
+of this software and associated documentation files (the "Software"), to deal
+in the Software without restriction, including without limitation the rights
+to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
+copies of the Software, and to permit persons to whom the Software is
+furnished to do so, subject to the following conditions:
+
+The above copyright notice and this permission notice shall be included in
+all copies or substantial portions of the Software.
+
+THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
+IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
+FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
+AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
+LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
+OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN
+THE SOFTWARE.
+```
+
+---
+
## github.com/atotto/clipboard v0.1.4
**License:** BSD-3-Clause
@@ -288,7 +318,7 @@ SOFTWARE.
---
-## github.com/charmbracelet/ultraviolet v0.0.0-20260703014108-f5a850f9c2b7
+## github.com/charmbracelet/ultraviolet v0.0.0-20260811164956-006e29f97886
**License:** MIT
@@ -320,7 +350,7 @@ SOFTWARE.
---
-## github.com/charmbracelet/x/ansi v0.11.7
+## github.com/charmbracelet/x/ansi v0.11.8
**License:** MIT
@@ -512,7 +542,7 @@ SOFTWARE.
---
-## github.com/lucasb-eyer/go-colorful v1.4.0
+## github.com/lucasb-eyer/go-colorful v1.4.1
**License:** MIT
@@ -530,7 +560,7 @@ THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLI
---
-## github.com/mattn/go-runewidth v0.0.24
+## github.com/mattn/go-runewidth v0.0.27
**License:** MIT
@@ -658,7 +688,7 @@ SOFTWARE.
---
-## golang.org/x/crypto v0.53.0
+## golang.org/x/crypto v0.57.0
**License:** BSD-3-Clause
@@ -696,7 +726,7 @@ OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
---
-## golang.org/x/sync v0.21.0
+## golang.org/x/sync v0.23.0
**License:** BSD-3-Clause
@@ -734,7 +764,7 @@ OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
---
-## golang.org/x/sys v0.46.0
+## golang.org/x/sys v0.48.0
**License:** BSD-3-Clause
@@ -772,7 +802,7 @@ OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
---
-## golang.org/x/term v0.44.0
+## golang.org/x/term v0.46.0
**License:** BSD-3-Clause
@@ -810,7 +840,7 @@ OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
---
-## golang.org/x/text v0.38.0
+## golang.org/x/text v0.42.0
**License:** BSD-3-Clause
diff --git a/README.md b/README.md
index f86585bb..3f2f0666 100644
--- a/README.md
+++ b/README.md
@@ -1,202 +1,152 @@
-
+# ProxSave: Proxmox VE and PBS Host Backup and Disaster Recovery
-# ProxSave
-Proxmox PBS & PVE System Files Backup
+[](https://github.com/tis24dev/proxsave/releases/latest)
+[](./LICENSE)
-[](https://opensource.org/licenses/MIT)
-[](https://go.dev/)
-[](https://codecov.io/gh/tis24dev/proxsave)
-[](https://github.com/tis24dev/proxsave/actions/workflows/lint.yml)
-[](https://github.com/tis24dev/proxsave/actions/workflows/security-ultimate.yml)
-[](https://github.com/tis24dev/proxsave/actions/workflows/codeql.yml)
-[](https://github.com/tis24dev/proxsave/network/updates)
-[](https://www.proxmox.com/)
-[](https://rclone.org/)
-[](https://github.com/sponsors/tis24dev)
-[](https://github.com/sponsors/tis24dev)
-[](https://paypal.me/DNoventa)
-
+ProxSave is a free, open-source tool for **online backups of host configuration** on **Proxmox Virtual Environment (PVE)** and **Proxmox Backup Server (PBS)**. It supports configuration restore and disaster recovery after a server failure, a Proxmox reinstall or a move to new hardware.
-## About the Project
+Configuration backups run **without shutting down the host, virtual machines or LXC containers**. The host and its workloads remain online during collection.
-ProxSave is a project created by enthusiasts, with the aim of simplifying recovery in critical moments.
+Backups can be kept locally, copied to a mounted NAS or another disk, uploaded to cloud storage, and **saved directly to a Proxmox Backup Server storage already configured in PVE**. Scheduled backups, encryption, retention policies, selective restore and external monitoring are included.
-Restoring a PVE or PBS server after a disaster (or even just a migration) is always a process that requires skill, time, and patience, **ProxSave** allows you to save your entire environment and restore it at any time, allowing you to prepare the new installation to accommodate your personal data with as few manual changes as possible.
+ProxSave is written in Go and released under the [MIT license](./LICENSE). It is an independent project, with no affiliation to Proxmox and no paid feature tier.
-**ProxSave** allows you to save and restore, integrating advanced features: automatic backups, multi-path saves, intelligent retention, encryption of backups, integrated Telegram and email notifications (cloud relay or Proxmox Notifications), and compatibility with webhooks, Gotify, and Prometheus.
+[Website: proxsave.dev](https://proxsave.dev) · [Documentation](./docs/README.md) · [Releases](https://github.com/tis24dev/proxsave/releases) · [Report an issue](https://github.com/tis24dev/proxsave/issues)
-For more information, take a look at our landing page at [proxsave.dev](https://proxsave.dev).
+## Why back up the Proxmox host?
-## Installation
+A working recovery plan needs both your workloads and the configuration of the server that runs them. After a fresh installation, there may be network bridges, storage definitions, users, permissions, firewall rules and backup jobs to recreate before your environment is usable again.
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)"
-```
+ProxSave keeps that host configuration available for recovery. Typical uses include:
-or: if you need a fully clean reinstall use: (preserves `build/`, `daemon_state/`, `env/`, `guards/`, `identity/`, and `restore/`)
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" _ --new-install
-```
-You can find the installation script source [here](./install.sh).
+- Recovering a Proxmox VE node after a boot disk or hardware failure.
+- Rebuilding the configuration of a Proxmox Backup Server.
+- Preparing for a reinstall or migration to replacement hardware.
+- Restoring selected settings after an unwanted configuration change.
+- Preserving the configuration of standalone nodes, cluster members and hosts running both PVE and PBS.
-The installer ends in the interactive setup, which writes your `configs/backup.env`. Everything after that is done from the dashboard: run `proxsave` on the host and it opens.
+ProxSave complements **PBS and vzdump backups of virtual machines and containers**. It captures VM and LXC configuration, but does not create backups of their running disks or filesystems. It can also collect existing PVE backup files when enabled; those files still need to be created by your normal guest backup jobs. PBS datastore contents need their own protection as well.
-🔒 The installer and `proxsave --upgrade` verify each release's signature before installing, for releases that publish `SHA256SUMS.sig`, so only authentic, untampered builds ever run ([details](./docs/PROVENANCE_VERIFICATION.md#release-signature-sha256sumssig)).
+## What ProxSave backs up
-> [!NOTE]
-> Please refer to the [docs](./docs/INSTALL.md) for more information about the installation.
+ProxSave detects the host's PVE and PBS roles and collects the relevant configuration alongside common Linux system settings. On a host running both products, it collects both roles in one backup run. An optional host-backup mode also supports collection from a host filesystem mounted read-only inside a suitably configured LXC appliance.
-## The Dashboard
+| Area | Configurable backup coverage |
+| --- | --- |
+| **Proxmox VE** | VM and LXC configuration, storage and datacenter settings, backup jobs, replication settings, users and permissions, firewall rules, HA and SDN configuration, PCI/USB resource mappings, Corosync and the cluster database (`/var/lib/pve-cluster/config.db`). |
+| **Proxmox Backup Server** | Datastore definitions, S3 endpoint settings, remotes, sync, prune and verification jobs, users and access control, notifications, node settings, ACME configuration and tape configuration, including tape encryption keys. |
+| **Networking** | Interface configuration, bridges, bonds, hostname and DNS settings, with network inventory and runtime reports for recovery. |
+| **Storage and filesystems** | Mount configuration, ZFS configuration and pool inventory, LVM metadata, iSCSI, multipath, software RAID, encrypted-volume settings and automount configuration. |
+| **System and access** | SSH configuration and keys, TLS certificates, system accounts, service definitions, cron jobs, package sources, kernel settings and boot parameters. |
+| **Personal files and scripts** | Local scripts, root and user home directories, and additional paths you choose to include, with exclusions to control the backup's scope. |
+| **Recovery information** | Hardware and package inventories, command outputs, storage reports and backup metadata that help explain how the original host was configured. |
-`proxsave`, run with no arguments on a terminal, opens the interactive dashboard. This is the normal way to use ProxSave: backing up, restoring, editing the configuration, upgrading, running the diagnostic checks and managing the daemon are all reachable there, and every entry that has a matching command-line flag runs that flag's code. The three `Diagnostic Checks` entries and `Daemon` > `Restart` have no flag and exist only in the dashboard.
+Coverage depends on the host's role, available files and enabled collectors. Some captured information is provided for reference or manual review rather than applied automatically during restore.
-```bash
-proxsave
-```
+## Backup destinations
-| Group | Entry | What it does |
-|-------|-------|--------------|
-| Backup | `Backup` | starts a backup with the current configuration, streamed inside the dashboard |
-| Tools | `Restore` | restores a backup onto this system |
-| Tools | `Decrypt` | converts an encrypted backup into a plaintext bundle |
-| Maintenance | `New key` | creates a new AGE encryption key |
-| Maintenance | `Install` | `Edit install` re-runs the interactive setup (this is how you change the configuration); `Wipe install` resets the install directory first, keeping `build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/` |
-| Maintenance | `Upgrade` | `Check upgrade` updates the binary to a newer release, merging new template variables into `backup.env` as part of the same run; `Check config` runs that merge on its own |
-| Diagnostic Checks | `Telegram`, `Healthchecks`, `Post-install` | verify the Telegram relay pairing, show the monitoring portal details, re-run the post-install audit |
-| Daemon | `Install`, `Disable`, `Restart`, `Status` | switch the scheduler to the resident daemon or back to cron, restart it, show its state. The group is context aware: `Install` appears on a cron install, `Disable` and `Restart` when the daemon is the active scheduler, `Status` always |
-| Recovery | `Cleanup guards` | removes leftover restore mount guards |
-| Recovery | `Support` | runs a support backup and emails the debug log to the maintainer |
+A backup run creates a local archive. It can also save secondary and cloud copies and create a separate native PBS snapshot, so you can keep recovery material outside the host being protected.
-The dashboard opens only when `proxsave` is invoked completely bare (any flag, even `--config`, skips it) and stdin and stdout are both real terminals with `TERM` set to something other than `dumb`. Everything else, cron included, runs the backup directly, and a dashboard that is abandoned or that fails to render exits without doing anything instead of falling through into a backup.
+| Destination | What it provides |
+| --- | --- |
+| **Local storage** | A ProxSave archive on a local filesystem path. |
+| **Secondary storage** | Another archive copy on a mounted filesystem, such as an NFS or SMB share, NAS, external drive or second disk. |
+| **Cloud and remote storage** | Archive copies through rclone, including S3-compatible storage, Backblaze B2, Google Drive, OneDrive and other supported backends. |
+| **Proxmox Backup Server** | A native host snapshot of the collected files, sent directly to a PBS storage configured in Proxmox VE. |
-Screen by screen: [DASHBOARD.md](./docs/DASHBOARD.md).
+### Native Proxmox Backup Server integration
-## Scheduling
+Native PBS uploads require a PVE host, an enabled PBS storage in `/etc/pve/storage.cfg` and `proxmox-backup-client`. ProxSave reads that storage's connection details, datastore, namespace, credentials and encryption key from the PVE configuration and sends the collected file tree directly to PBS. The configured namespace, if used, must already exist.
-The setup offers two scheduler engines and a fresh installation defaults to the **resident daemon** (`proxsave-daemon.service`): it runs the backup itself daily, weekly or monthly (`SCHEDULER_FREQUENCY`) at `SCHEDULER_TIME`, supervises it under the `MAX_RUN_DURATION` hang watchdog, and reports liveness and outcome to healthchecks monitoring. Monitoring only transmits under the daemon, which is the sole pinger; choosing cron turns it off.
+These are native PBS file backups, with [PBS deduplication and incremental transfer of chunks](https://pbs.proxmox.com/docs/technical-overview.html). Each host has its own `host/proxsave-` backup group containing a `proxsave.pxar` file archive. ProxSave checks that the uploaded snapshot exists and has the expected encryption mode, manages retention for that group and attaches the run log to the snapshot.
-System cron is the legacy engine and stays fully supported: `SCHEDULER_MODE=cron` keeps the crontab entry instead. Once the variable is recorded in `backup.env`, an upgrade leaves the engine as it stands and never switches it.
+PBS encryption follows the key configured on the selected PVE storage. It is separate from the age encryption used for ProxSave archive copies. A storage without an encryption key receives unencrypted snapshots.
-Switch between the two from the dashboard's Daemon group, or with `--daemon-setup` / `--daemon-remove` on a headless host.
+Recovery from native PBS snapshots uses PBS tools. ProxSave's built-in restore selector currently discovers its archive backups in local, secondary and rclone storage.
-Details: [DAEMON.md](./docs/DAEMON.md) and [HEALTHCHECKS.md](./docs/HEALTHCHECKS.md).
+[PBS storage reference](./docs/CONFIGURATION.md#pbs-storage-proxmox-backup-server) · [Cloud storage](./docs/CLOUD_STORAGE.md)
-## Upgrading
+## Restore and disaster recovery
-From the dashboard: `Upgrade` > `Check upgrade` downloads and installs a newer release, and the `backup.env` merge is part of that run. `Check config` runs that merge on its own, for when the binary is already current.
+ProxSave provides an interactive restore workflow with four choices: **full configuration**, **storage**, **base system** or **custom categories**. You can recover a broad set of settings or focus on a specific area, such as networking, storage definitions or backup jobs.
-Headless, the same upgrade is `proxsave --upgrade` (append `y` to auto-confirm).
+The workflow checks the backup's compatibility with the target host, presents a restore plan and creates safety copies of the configuration being replaced. Relevant PVE and PBS settings are staged and applied through the appropriate APIs or controlled file updates. Categories belonging to a product the target host does not run are exported for review.
-### External Upgrade
-An in-place `proxsave --upgrade` is started by the binary already installed, so the release check, the download, the signature and checksum verification and the install itself are all executed by the OLD code. From 0.36.0 on, the installed binary hands the post-install finalize (the configuration merge, the docs and symlink refresh, the daemon migration and restart) to the freshly installed release, so that half runs the new code; a binary older than that finalizes with its own code, and a fix shipped in the new release cannot help that upgrade.
+For PVE clusters, **SAFE** mode preserves the running cluster database while recovering supported configuration; **RECOVERY** mode handles cluster database restoration. Network recovery includes interface-name repair, connectivity checks and a rollback timer. Staged PVE firewall, HA and access-control changes also have rollback protection.
-To run the whole upgrade with the new code, fetch the installer instead:
+Recovery logs, exports and safety backups remain available for later review.
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" -- --upgrade
-```
+ProxSave restores configuration onto an installed system. Restoring network or cluster settings may interrupt service, and boot changes require a reboot. VM disks, container filesystems, application state and installed packages remain part of your wider disaster recovery plan.
+
+[Restore guide](./docs/RESTORE_GUIDE.md) · [Proxmox cluster recovery](./docs/CLUSTER_RECOVERY.md)
+
+### IOMMU, VFIO and passthrough configuration
+
+Backups preserve the configuration used for **PCI passthrough, GPU passthrough and USB passthrough**: guest device assignments, PVE resource mappings, IOMMU/VFIO kernel parameters, module options and driver blacklists. Coverage follows the enabled collectors.
+
+When the relevant restore categories are selected, ProxSave restores `/etc/modules` and `/etc/modprobe.d/` automatically. The boot category merges saved kernel parameters into a recognized GRUB or systemd-boot configuration, preserves existing target values, and rebuilds the initramfs and bootloader when required. The source host's boot files and disk identifiers remain available for reference.
-It downloads, verifies and installs the release itself, then calls the new binary with `--upgrade --localfile` to finalize.
+In PVE SAFE mode, the workflow can apply saved PCI/USB resource mappings through the Proxmox API before guest configurations, after confirmation.
-## Command Line
+On different hardware, PCI addresses, device IDs, USB paths and cluster node names may need manual changes. Firmware IOMMU settings, device isolation and hardware compatibility must be checked on the target host. ProxSave does not automatically adapt passthrough assignments to replacement devices.
-The flags stay fully supported, for headless hosts, cron jobs, scripts and recovery when the dashboard cannot run. They are the automation route, not the everyday one.
+[Boot parameter restore](./docs/RESTORE_GUIDE.md#11-kernel-command-line-merge-boot-category) · [PVE resource mapping restore](./docs/RESTORE_GUIDE.md#pvesh-safe-apply-cluster-safe-mode)
-| Flag | What it does |
-|------|--------------|
-| `--backup` | runs the backup now, skipping the dashboard. A non-interactive invocation does this anyway |
-| `--restore` | runs the restore workflow (select bundle, optionally decrypt, apply to system) |
-| `--decrypt` | converts encrypted bundles into plaintext bundles |
-| `--newkey`, `--age-newkey` | resets the AGE recipients and runs the interactive key setup |
-| `--support` | forces debug logging and emails the log to the maintainer. Available for a standard backup run and for `--restore` |
-| `--install` | runs the interactive installer (generate or edit `backup.env`) |
-| `--new-install` | resets the installation directory, preserving `build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/`, then runs the installer |
-| `--upgrade [y]` | downloads and installs the latest release, then upgrades `backup.env`. `y` auto-confirms |
-| `--localfile` | with `--upgrade`: skip the release check and download and finalize against the binary already on disk |
-| `--upgrade-config` | adds missing variables to `backup.env` from the embedded template, preserving existing and custom ones |
-| `--upgrade-config-dry-run` | plans that merge without writing, reporting missing and custom variables |
-| `--daemon` | runs as the resident daemon. This is what `proxsave-daemon.service` starts |
-| `--daemon-setup` | switches this install to daemon mode: installs and enables the service, removes the cron entry |
-| `--daemon-remove` | reverts to cron and prevents future upgrades from reinstalling the daemon |
-| `--daemon-status` | prints scheduler mode, service state, running version and binary alignment |
-| `--cleanup-guards` | removes leftover guard bind mounts and directories. Combine with `--dry-run` to preview |
-| `--show-whatsnew` | shows the release notes screen once and exits |
-| `-c`, `--config ` | configuration file to use (default `configs/backup.env` under the install directory) |
-| `-l`, `--log-level ` | `debug`, `info`, `warning`, `error` or `critical` |
-| `-n`, `--dry-run` | runs without making actual changes |
-| `--cli` | uses plain CLI prompts instead of the TUI, for `--install`, `--new-install`, `--newkey`, `--decrypt` and `--restore` |
-| `-v`, `--version` | shows version and build information |
-| `-h`, `--help` | shows the help message |
+## Automatic backups and monitoring
-A few more flags exist (`--upgrade-config-json`, `--upgrade-finalize` and its companions) purely as internal plumbing for `--upgrade`; they are not meant to be run by hand.
+The resident daemon schedules daily, weekly or monthly backups and supervises each run with a duration limit to detect hangs. Cron remains available as an alternative scheduler.
-Full reference: [CLI_REFERENCE.md](./docs/CLI_REFERENCE.md).
+Retention can keep the newest backups or use **Grandfather-Father-Son (GFS)** rules for daily, weekly, monthly and yearly recovery points. Local, secondary, cloud and native PBS destinations support retention. Archive compression is configurable, including gzip, Zstandard and xz.
-## Guide
+Backup reports can be delivered through **Telegram, email, Gotify and webhooks**. Email supports a relay, local sendmail or Proxmox Notifications integration. Notification failures are recorded separately from failures to create the backup.
-You can find the guide files for the various functions [here](./docs/README.md).
+With the daemon, external healthchecks monitoring can detect a missing backup, an unavailable host or a hung run even when the host cannot send a notification. It also tracks daemon liveness, release updates and notification-channel outcomes. You can use the ProxSave monitoring service or your own healthchecks instance. Prometheus metrics are available through the node_exporter textfile collector.
-## Support
+The interactive terminal dashboard brings backup, restore, configuration, diagnostics, upgrades and daemon management together. Command-line options support headless hosts and automation, and custom scripts can run before and after a backup.
-Every report or issue is important to us. There are various channels you can use to report a problem.
+[Scheduling](./docs/DAEMON.md) · [Monitoring](./docs/HEALTHCHECKS.md) · [Notifications](./docs/NOTIFICATIONS.md)
-The fastest report is the dashboard's `Support` entry, under Recovery: it runs a backup with debug logging and emails that log to the maintainer. On a headless host, `proxsave --support` does the same.
+## Encryption and integrity
-It is important that you provide as much information as possible with each report.
-You will often find these details listed. They are important, so please do not forget to include them:
+ProxSave archive backups can use **age encryption** with passphrase or key-based recipients. Compression and encryption are streamed during archive creation. SHA-256 checksums, archive verification and backup manifests support integrity checks and describe the host and roles a backup came from.
+The installer verifies the release signature and checksum before installing the binary. Release provenance attestations are also available for independent verification.
+
+Host backups can contain credentials and private keys. Encryption covers the saved archive; collected files are temporarily staged in plaintext on the host. The security and encryption guides explain the storage, permissions and recovery-key considerations.
+
+[Encryption](./docs/ENCRYPTION.md) · [Security](./docs/SECURITY.md) · [Release verification](./docs/PROVENANCE_VERIFICATION.md)
+
+## Installation
+
+Run the official installer as root on your Proxmox VE or PBS host (Linux x86-64):
```bash
-example
-===========================================
- Version: 0.11.2
- Build Signature: 60d0d998f* (2025-12-02T14:46:14+01:00) hash=eeb72ef6b8b6ad89
-===========================================
+bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)"
```
-Every run prints that block in its header. The dashboard shows the version in its own header and the build signature in its footer; `proxsave --version` prints the version with the build commit and date.
-
- -
 -
-## Donations
-To stay completely free and open-source, with no feature behind the paywall and evolve the project, we need your help. If you like ProxSave, please consider donating to help us fund the project's future development.
-
-
 -
 -
-Thank you so much!
-
-## Recognitions
-
 -
-## Release Testing & Feedback
-A special thanks to the community members who help by testing releases and reporting issues. 💙
-
-
-
-
-
-## Repo Activity
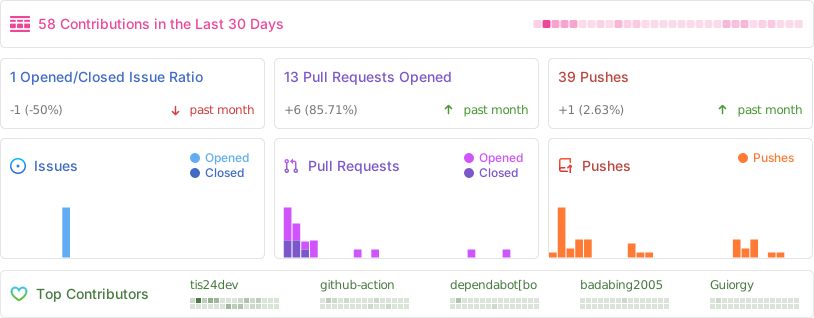
-
+The installer downloads and verifies the latest release, installs the binary and opens the interactive setup. You can [read the installer source](./install.sh) before running it.
+
+After installation, run `proxsave` to open the interactive dashboard.
+
+See the [installation guide](./docs/INSTALL.md) for requirements, alternative installation methods, reinstalling and upgrading.
+
+## Documentation
+
+| Topic | Guide |
+| --- | --- |
+| All user and technical documentation | [Documentation index](./docs/README.md) |
+| Dashboard and everyday operation | [Dashboard guide](./docs/DASHBOARD.md) |
+| Backup settings, destinations and collectors | [Configuration reference](./docs/CONFIGURATION.md) |
+| Recovery workflows and cluster procedures | [Restore guide](./docs/RESTORE_GUIDE.md) and [cluster recovery](./docs/CLUSTER_RECOVERY.md) |
+| Backup scheduling and healthchecks | [Daemon](./docs/DAEMON.md) and [monitoring](./docs/HEALTHCHECKS.md) |
+| Automation and practical configurations | [CLI reference](./docs/CLI_REFERENCE.md) and [examples](./docs/EXAMPLES.md) |
+| Diagnosing problems | [Troubleshooting](./docs/TROUBLESHOOTING.md) |
+| Architecture and development | [Collector architecture](./docs/COLLECTOR_ARCHITECTURE.md) and [developer guide](./docs/DEVELOPER_GUIDE.md) |
+
+## Community and support
+
+Bug reports, recovery feedback and contributions help improve ProxSave. For support, use [GitHub Issues](https://github.com/tis24dev/proxsave/issues) or contact the maintainer on [Telegram](https://t.me/tis24dev). The documentation covers diagnostics and the built-in support report.
+
+Thanks to [@NukeThemTillTheyGlow](https://github.com/NukeThemTillTheyGlow) and [@marc6901](https://github.com/marc6901) for release testing and feedback, and to everyone who reports problems or contributes fixes.
+
+To contribute, read [CONTRIBUTING.md](./CONTRIBUTING.md). To help fund development, you can [sponsor the project](https://github.com/sponsors/tis24dev) or [donate through PayPal](https://paypal.me/DNoventa).
diff --git a/cmd/proxsave/config_integrity_test.go b/cmd/proxsave/config_integrity_test.go
index 0d1d9f39..785b838e 100644
--- a/cmd/proxsave/config_integrity_test.go
+++ b/cmd/proxsave/config_integrity_test.go
@@ -2,6 +2,7 @@ package main
import (
"bytes"
+ "fmt"
"os"
"strings"
"testing"
@@ -234,6 +235,17 @@ func TestTheDebugBlockExplainsEveryDecisionItMade(t *testing.T) {
"EMAIL_ENABLE=true\n" +
"PERSONAL_SCRIPTS_PRERUN=/tmp/x\n" +
"CUSTOM_BACKUP_PATHS=\"\n/etc/a\n\"\n"
+ // Derive positions from this input fixture, not the audit under test or
+ // hardcoded template offsets that change when explanatory comments grow.
+ var customPathLines []int
+ for index, line := range strings.Split(body, "\n") {
+ if strings.HasPrefix(line, "CUSTOM_BACKUP_PATHS=") {
+ customPathLines = append(customPathLines, index+1)
+ }
+ }
+ if len(customPathLines) != 2 {
+ t.Fatalf("expected two input assignments, got %v", customPathLines)
+ }
path := t.TempDir() + "/backup.env"
if err := os.WriteFile(path, []byte(body), 0o600); err != nil {
t.Fatalf("write config: %v", err)
@@ -255,7 +267,7 @@ func TestTheDebugBlockExplainsEveryDecisionItMade(t *testing.T) {
// why the one that was NOT accepted failed every rule
"PERSONAL_SCRIPTS_PRERUN is assigned in the file and matched no rule: not assigned in the template, not documented there, not a webhook endpoint field, not a legacy alias",
// which write form won, since the two resolve in opposite ways
- "CUSTOM_BACKUP_PATHS assigned on lines 442, 530; line 530 wins (block form: it replaces everything before it)",
+ fmt.Sprintf("CUSTOM_BACKUP_PATHS assigned on lines %d, %d; line %d wins (block form: it replaces everything before it)", customPathLines[0], customPathLines[1], customPathLines[1]),
// the template's own two halves, so the counts above can be reconstructed
"template assigns 190 variables and documents",
} {
diff --git a/cmd/proxsave/daemon_setup.go b/cmd/proxsave/daemon_setup.go
index 3ba4e6c9..928cddd8 100644
--- a/cmd/proxsave/daemon_setup.go
+++ b/cmd/proxsave/daemon_setup.go
@@ -332,21 +332,6 @@ func installVerifyVerdict(rv RestartVerifyResult) (orchestrator.HealthcheckSetup
}
}
-// installVerifyContext resolves the base dir + heartbeat interval for a post-install
-// daemon verify from the just-written config (best-effort; ok=false when unreadable).
-func installVerifyContext(configPath string) (baseDir string, interval time.Duration, ok bool) {
- detected, _ := detectedBaseDirOrFallback()
- cfg, err := config.LoadConfigWithBaseDir(configPath, detected)
- if err != nil || cfg == nil {
- return "", 0, false
- }
- baseDir = detected
- if strings.TrimSpace(cfg.BaseDir) != "" {
- baseDir = cfg.BaseDir
- }
- return baseDir, cfg.HealthcheckHeartbeatInterval, true
-}
-
// Seams so a test can drive the daemon setup/teardown paths - applyCronMode's
// ordering, what the cron removal reports, and whether the --upgrade retrofit
// migrated at all - without touching the real crontab or the systemd unit.
@@ -756,65 +741,105 @@ func setBackupEnvKeys(configPath string, kv map[string]string) error {
return installer.WriteConfigFileAtomic(configPath, configPath+".daemon.tmp", content)
}
-// reconcileSchedulerAfterInstall makes the scheduler engine a MUTUALLY EXCLUSIVE
-// choice after an install/reinstall (which always (re)writes the cron line). It
-// takes the mode the wizard picked; when empty (keep-existing / skipped wizard)
-// it reads the mode from the just-written config. daemon -> install the unit and
-// drop the cron line; cron -> tear down any leftover daemon unit so a re-install
-// of a previously-daemon host can never end up double-scheduled (cron + unit).
-//
-// It returns the daemon restart-verify result and verified=true ONLY in the
-// daemon branch that actually ran verifyDaemonAlignedBestEffort; every other
-// path (install failed, verify context unreadable, or cron mode) returns a
-// zero result with verified=false. The existing statement call sites discard
-// both returns; only the TUI finalization captures them to render the outcome.
-func reconcileSchedulerAfterInstall(ctx context.Context, wizardMode, configPath string, execInfo ExecInfo, bootstrap *logging.BootstrapLogger) (rv RestartVerifyResult, verified bool) {
- mode := strings.ToLower(strings.TrimSpace(wizardMode))
- if mode != "cron" && mode != "daemon" {
- mode = readConfiguredSchedulerMode(configPath)
+// reconcileSchedulerAfterInstall applies only incomplete daemon phases for one
+// explicit install. Service application, protected restart and cron handover
+// remain separate: partial failure never becomes permission to run a second scheduler.
+func reconcileSchedulerAfterInstall(ctx context.Context, p *installRuntimePreparation) installRuntimeResult {
+ if ctx.Err() != nil {
+ return p.result
}
-
- if mode == "daemon" {
- if err := installDaemonService(ctx, daemonExecPath, configPath, bootstrap); err != nil {
- logging.Warning("Failed to enable the daemon service (staying on cron): %v", err)
- return RestartVerifyResult{}, false
+ if !p.result.UnitAttempted {
+ _, presence, err := p.ops.inspect(ctx)
+ if err != nil {
+ p.result.Err = err
+ return p.result
}
- cronOutcome, err := removeCanonicalCronEntry(ctx, cronCorrectPaths(execInfo.ExecPath), bootstrap)
+ initial := p.ops.snapshot(ctx, p.cfg)
+ if !presence.Probed && !initial.ProcessAlive {
+ p.result.Err = errors.New("daemon service state could not be determined")
+ return p.result
+ }
+ p.needsRestart = initial.ProcessAlive || presence.Active
+ p.initialState = initial.State
+ if !p.result.EntrypointVerified {
+ if ctx.Err() != nil {
+ return p.result
+ }
+ err := p.ops.entrypoints(ctx)
+ if verifyErr := verifyInstallExecutable(p.canonicalPath, p.execInfo.ExecPath); verifyErr != nil {
+ p.result.Err = errors.Join(err, verifyErr)
+ return p.result
+ }
+ p.result.EntrypointVerified = true
+ if err != nil {
+ p.result.Err = err
+ return p.result
+ }
+ }
+ if ctx.Err() != nil {
+ return p.result
+ }
+ p.result.Err = nil
+ p.result.UnitAttempted = true
+ err = p.ops.install(ctx)
+ p.result.UnitApplied = err == nil
if err != nil {
- logging.Warning("daemon: failed to remove the cron entry (the per-run lock mitigates double execution): %v", err)
+ p.result.Err = err
+ logging.Warning("Failed to enable the daemon service: %v", err)
+ p.applicationErrorLogged = true
+ // enable --now may have enabled the unit or started a process before error.
+ // Retain the attempt; never reinstall solely because its result is an error.
+ p.result.Verification = p.ops.snapshot(ctx, p.cfg)
+ p.result.Verified = true
+ p.result.ActivationConfirmed = p.result.Verification.ProcessAlive || p.result.Verification.State.Active
+ return p.result
}
- // This reconcile installs the daemon just like applyDaemonMode does, and it calls the
- // removal DIRECTLY rather than through applyDaemonMode, so it needs the #298 wrapper
- // warning of its own: an install/reinstall that picked daemon mode on a wrapper host
- // would otherwise end double-scheduled and silent.
- _ = warnIndirectProxsaveCronOnDaemonInstall(ctx, bootstrap)
- // `enable --now` does NOT restart an ALREADY-running daemon, so a reinstall/reconfigure
- // (or a rebuilt binary) would leave it on the OLD inode. Restart so the running process is
- // the freshly installed binary before we report alignment.
- if err := restartDaemonService(ctx); err != nil {
- logging.Debug("daemon: restart to load the installed binary failed: %v", err)
+ }
+ if !p.result.UnitApplied || ctx.Err() != nil {
+ return p.result
+ }
+ if p.needsRestart && !p.result.RestartAttempted {
+ lock, known := p.restartLock()
+ if ctx.Err() != nil {
+ return p.result
}
- logging.Info("Daemon mode enabled: %s is active. %s", daemonUnitName, cronRemovalClause(cronOutcome))
- // Report the daemon's real state (aligned / behind / not running), best-effort
- // (a verify miss is only logged, never fails the install).
- if baseDir, interval, ok := installVerifyContext(configPath); ok {
- return verifyDaemonAlignedBestEffort(ctx, baseDir, interval), true
+ p.result.RestartAttempted = true
+ p.result.Restart = p.ops.restart(ctx, p.cfg.BaseDir, lock, known, p.cfg.HealthcheckHeartbeatInterval)
+ if p.result.Restart.Err != nil {
+ p.result.Err = p.result.Restart.Err
}
- return RestartVerifyResult{}, false
+ p.result.Verification = p.result.Restart
+ p.result.Verified = true
+ } else if !p.result.Verified {
+ logging.Info("Verifying daemon alignment...")
+ p.result.Verification = p.ops.verify(ctx, p.cfg)
+ p.result.Verified = true
}
-
- // cron mode: a previously-installed daemon unit would double-schedule with the
- // cron line just written, so remove it. Gate on the unit FILE existing (not just
- // is-active) so an enabled-but-currently-stopped unit is also torn down, and a
- // host that never had a daemon skips the systemctl calls entirely.
- if daemonUnitInstalled() {
- if err := removeDaemonService(ctx, bootstrap); err != nil {
- logging.Warning("daemon: a previous daemon unit could not be removed (possible double execution): %v", err)
- } else {
- logging.Info("Removed the previous daemon service; this host now uses the cron scheduler.")
+ if ctx.Err() != nil {
+ return p.result
+ }
+ current := p.ops.snapshot(ctx, p.cfg)
+ _, presence, err := p.ops.inspect(ctx)
+ // A remembered successful activation is not current permission to remove cron.
+ active := current.ProcessAlive || current.State.Active || (err == nil && presence.Probed && presence.Active)
+ p.result.ActivationConfirmed = p.result.ActivationConfirmed || active
+ if active && !p.result.CronRemoval.Verified {
+ if ctx.Err() != nil {
+ return p.result
+ }
+ outcome, err := p.ops.removeCron(ctx)
+ p.result.CronRemoval = outcome
+ if err != nil {
+ p.result.Err = errors.Join(p.result.Err, err)
+ logging.Warning("daemon: failed to remove the cron entry (the per-run lock mitigates double execution): %v", err)
+ }
+ if ctx.Err() != nil {
+ return p.result
}
+ p.result.CronRemoval.UnmanagedSchedules = p.ops.warnCron(ctx)
+ logging.Info("Daemon mode enabled: %s is active. %s", daemonUnitName, cronRemovalClause(p.result.CronRemoval))
}
- return RestartVerifyResult{}, false
+ return p.result
}
// readConfiguredSchedulerMode returns "daemon" or "cron" from an existing
diff --git a/cmd/proxsave/healthcheck_setup_cli.go b/cmd/proxsave/healthcheck_setup_cli.go
index 9ea7ab86..7974150a 100644
--- a/cmd/proxsave/healthcheck_setup_cli.go
+++ b/cmd/proxsave/healthcheck_setup_cli.go
@@ -6,6 +6,7 @@ import (
"fmt"
"strings"
+ "github.com/tis24dev/proxsave/internal/installer"
"github.com/tis24dev/proxsave/internal/logging"
"github.com/tis24dev/proxsave/internal/orchestrator"
)
@@ -41,7 +42,18 @@ func logHealthcheckSetupBootstrapOutcome(bootstrap *logging.BootstrapLogger, sta
// (mirrors runTelegramSetupCLI): a short guide, the portal magic-link, and a
// non-blocking connection check with retry/skip. Only renders when the daemon
// engine with centralized monitoring was chosen and the identity/secret exist.
-func runHealthcheckSetupCLI(ctx context.Context, reader *bufio.Reader, baseDir, configPath string, bootstrap *logging.BootstrapLogger) error {
+func runHealthcheckSetupCLI(ctx context.Context, reader *bufio.Reader, baseDir, configPath string, bootstrap *logging.BootstrapLogger, options ...installer.HealthcheckSetupOptions) error {
+ if err := ctx.Err(); err != nil {
+ return err
+ }
+ if len(options) > 0 && options[0].BeforeBootstrap != nil {
+ if err := options[0].BeforeBootstrap(ctx); err != nil {
+ return err
+ }
+ }
+ if err := ctx.Err(); err != nil {
+ return err
+ }
state, err := healthcheckSetupBuildBootstrap(ctx, configPath, baseDir)
if err != nil {
logBootstrapWarning(bootstrap, "Healthcheck setup bootstrap failed (non-blocking): %v", err)
diff --git a/cmd/proxsave/install.go b/cmd/proxsave/install.go
index d58744ee..cb564629 100644
--- a/cmd/proxsave/install.go
+++ b/cmd/proxsave/install.go
@@ -53,9 +53,9 @@ func runInstall(ctx context.Context, configPath string, bootstrap *logging.Boots
done := logging.DebugStartBootstrap(bootstrap, "install workflow (cli)", "config=%s base=%s", configPath, baseDir)
defer func() { done(err) }()
- // Entrypoint cleanup + recreation is deferred to runPostInstallSymlinksAndCron
- // (success path only), so an aborted/non-interactive install never leaves the
- // host without a working proxsave/proxmox-backup command.
+ // Entrypoint changes belong to runtime preparation after the configuration
+ // and optional setup writes have completed. A rejected configuration wizard
+ // never changes the executable entrypoints.
execInfo := getExecInfo()
if bootstrap != nil {
@@ -108,6 +108,7 @@ func runInstall(ctx context.Context, configPath string, bootstrap *logging.Boots
}
// Optional post-install audit: run a dry-run and offer to disable unused collectors.
+ runtimePreparation := newInstallRuntimePreparation(configPath, baseDir, execInfo, bootstrap)
if !configResult.SkipConfigWizard {
logging.DebugStepBootstrap(bootstrap, "install workflow (cli)", "post-install audit")
if err := runPostInstallAuditCLI(ctx, reader, execInfo.ExecPath, configPath, bootstrap); err != nil {
@@ -136,7 +137,7 @@ func runInstall(ctx context.Context, configPath string, bootstrap *logging.Boots
// (self) verify the pasted alive URL is reachable. Only renders when eligible
// (re-reads the written config), non-blocking.
logging.DebugStepBootstrap(bootstrap, "install workflow (cli)", "healthcheck setup")
- if err := runHealthcheckSetupCLI(ctx, reader, baseDir, configPath, bootstrap); err != nil {
+ if err := runHealthcheckSetupCLI(ctx, reader, baseDir, configPath, bootstrap, installer.HealthcheckSetupOptions{BeforeBootstrap: runtimePreparation.Prepare}); err != nil {
return err
}
}
@@ -150,17 +151,13 @@ func runInstall(ctx context.Context, configPath string, bootstrap *logging.Boots
}
logging.DebugStepBootstrap(bootstrap, "install workflow (cli)", "finalizing symlinks and cron")
- runPostInstallSymlinksAndCron(
- ctx,
- baseDir,
- execInfo,
- bootstrap,
- buildInstallCronSchedule(configResult.SkipConfigWizard, configResult.CronSchedule, configPath),
- )
- // Reconcile the scheduler engine (daemon unit vs cron entry) as a mutually
- // exclusive choice, INCLUDING the keep-existing path (SchedulerMode empty ->
- // read from the kept config), so a re-install never leaves both active.
- reconcileSchedulerAfterInstall(ctx, configResult.SchedulerMode, configPath, execInfo, bootstrap)
+ runtimePreparation.cronSchedule = buildInstallCronSchedule(configResult.SkipConfigWizard, configResult.CronSchedule, configPath)
+ if err := runtimePreparation.Finalize(ctx); err != nil {
+ if ctx.Err() != nil {
+ return wrapInstallError(errInteractiveAborted)
+ }
+ return err
+ }
logging.DebugStepBootstrap(bootstrap, "install workflow (cli)", "detecting telegram identity")
telegramCode = detectTelegramCodeWithContext(ctx, baseDir)
@@ -763,12 +760,30 @@ func runPostInstallSymlinksAndCron(ctx context.Context, baseDir string, execInfo
done := logging.DebugStartBootstrap(bootstrap, "post-install setup", "base=%s", baseDir)
defer func() { done(nil) }()
+ if err := runPostInstallEntrypoints(ctx, execInfo, bootstrap); err != nil {
+ return
+ }
+
+ // Ensure a cron entry for the Go binary: preserve an entry that already
+ // targets it, drop outdated proxsave/proxmox-backup binary entries, and if
+ // no entry exists at all create a default one at 02:00 every day.
+ if strings.TrimSpace(cronSchedule) == "" {
+ cronSchedule = resolveCronScheduleFromEnv()
+ }
+ logging.DebugStepBootstrap(bootstrap, "post-install setup", "migrating cron entries")
+ migrateLegacyCronEntries(ctx, baseDir, execInfo.ExecPath, bootstrap, cronSchedule)
+}
+
+// runPostInstallEntrypoints is shared by the early daemon and late cron paths.
+func runPostInstallEntrypoints(ctx context.Context, execInfo ExecInfo, bootstrap *logging.BootstrapLogger) error {
+ if err := ctx.Err(); err != nil {
+ return err
+ }
// Remove stale proxsave/proxmox-backup *symlinks* (PATH, /usr/local/bin,
// /usr/bin) that do not point to this Go binary, then recreate clean ones. Real
// (non-symlink) files are left in place so a package-managed /usr/bin binary is
- // never deleted. This runs here — immediately before recreation and only on the
- // success path — so an aborted or non-interactive install can never leave the
- // host without a working entrypoint.
+ // never deleted. Recreation follows in this explicit installation phase;
+ // callers verify the executable before allowing daemon activation.
logging.DebugStepBootstrap(bootstrap, "post-install setup", "cleaning legacy entrypoints")
cleanupGlobalProxmoxBackupEntrypoints(execInfo.ExecPath, bootstrap)
@@ -777,16 +792,12 @@ func runPostInstallSymlinksAndCron(ctx context.Context, baseDir string, execInfo
bootstrap.Info("Ensuring the 'proxsave' command points to the Go binary")
}
logging.DebugStepBootstrap(bootstrap, "post-install setup", "ensuring go symlink")
+ if err := ctx.Err(); err != nil {
+ return err
+ }
ensureGoSymlink(execInfo.ExecPath, bootstrap)
- // Ensure a cron entry for the Go binary: preserve an entry that already
- // targets it, drop outdated proxsave/proxmox-backup binary entries, and if
- // no entry exists at all create a default one at 02:00 every day.
- if strings.TrimSpace(cronSchedule) == "" {
- cronSchedule = resolveCronScheduleFromEnv()
- }
- logging.DebugStepBootstrap(bootstrap, "post-install setup", "migrating cron entries")
- migrateLegacyCronEntries(ctx, baseDir, execInfo.ExecPath, bootstrap, cronSchedule)
+ return ctx.Err()
}
func detectTelegramCodeWithContext(ctx context.Context, baseDir string) string {
diff --git a/cmd/proxsave/install_outcome.go b/cmd/proxsave/install_outcome.go
index 14d7738d..497e925c 100644
--- a/cmd/proxsave/install_outcome.go
+++ b/cmd/proxsave/install_outcome.go
@@ -23,7 +23,7 @@ import (
// The whole string is caller-pre-styled and passed verbatim to the inline stream screen,
// mirroring how WithSelectorPromptStyled accepts an already-rendered prompt. It never
// renders the CLI footer, which stays the persistent scrollback record after Close.
-func buildInstallOutcomePrompt(rv RestartVerifyResult, verified bool, permStatus, permMessage string) string {
+func buildInstallOutcomePrompt(rv RestartVerifyResult, verified bool, permStatus, permMessage string, runtime ...installRuntimeResult) string {
var b strings.Builder
title, level := installBanner(nil)
@@ -35,6 +35,9 @@ func buildInstallOutcomePrompt(rv RestartVerifyResult, verified bool, permStatus
// Same verdict the install's log line shows (NOT classifyRestartVerify, whose
// success arm needs the Restarted flag the poll-only verify never sets).
level, keyword := installVerifyVerdict(rv)
+ if len(runtime) > 0 {
+ level, keyword, _ = installRuntimeVerdict(runtime[0])
+ }
b.WriteString(renderDaemonStatusLevel(level, keyword))
} else {
// No daemon verify ran (cron scheduler, install-daemon failure, or an
diff --git a/cmd/proxsave/install_runtime.go b/cmd/proxsave/install_runtime.go
new file mode 100644
index 00000000..824c99ef
--- /dev/null
+++ b/cmd/proxsave/install_runtime.go
@@ -0,0 +1,328 @@
+package main
+
+import (
+ "context"
+ "errors"
+ "fmt"
+ "os"
+ "path/filepath"
+ "strings"
+ "syscall"
+ "time"
+
+ "github.com/tis24dev/proxsave/internal/config"
+ "github.com/tis24dev/proxsave/internal/health"
+ "github.com/tis24dev/proxsave/internal/logging"
+ "github.com/tis24dev/proxsave/internal/orchestrator"
+)
+
+// installRuntimeResult keeps application history separate from current liveness.
+// A poll cannot prove that an old process applied the saved configuration.
+type installRuntimeResult struct {
+ Mode string
+ ConfigLoaded bool
+ EntrypointVerified bool
+ UnitAttempted bool
+ UnitApplied bool
+ ActivationConfirmed bool
+ RestartAttempted bool
+ Restart RestartVerifyResult
+ CronRemoval cronRemovalOutcome
+ Verification RestartVerifyResult
+ Verified bool
+ Err error
+}
+
+type installRuntimeOperations struct {
+ loadConfig func(string, string) (*config.Config, error)
+ entrypoints func(context.Context) error
+ inspect func(context.Context) (bool, health.DaemonPresence, error)
+ install func(context.Context) error
+ snapshot func(context.Context, *config.Config) RestartVerifyResult
+ verify func(context.Context, *config.Config) RestartVerifyResult
+ residentConfig func(health.DaemonState, string) (string, bool)
+ restart func(context.Context, string, string, bool, time.Duration) RestartVerifyResult
+ removeCron func(context.Context) (cronRemovalOutcome, error)
+ warnCron func(context.Context) int
+ cronPresent func(context.Context) (bool, bool)
+ configureCron func(context.Context, string) error
+}
+
+type installRuntimePreparation struct {
+ configPath string
+ baseDir string
+ canonicalPath string
+ execInfo ExecInfo
+ bootstrap *logging.BootstrapLogger
+ cronSchedule string
+ ops installRuntimeOperations
+ cfg *config.Config
+ result installRuntimeResult
+ cronComplete bool
+ needsRestart bool
+ initialState health.DaemonState
+ logs []string
+ applicationErrorLogged bool
+}
+
+func newInstallRuntimePreparation(configPath, baseDir string, execInfo ExecInfo, bootstrap *logging.BootstrapLogger) *installRuntimePreparation {
+ p := &installRuntimePreparation{configPath: configPath, baseDir: baseDir, canonicalPath: daemonExecPath, execInfo: execInfo, bootstrap: bootstrap}
+ p.ops = installRuntimeOperations{
+ loadConfig: config.LoadConfigWithBaseDir,
+ entrypoints: func(ctx context.Context) error { return runPostInstallEntrypoints(ctx, execInfo, bootstrap) },
+ inspect: inspectInstallDaemon,
+ install: func(ctx context.Context) error {
+ return installDaemonService(ctx, daemonExecPath, configPath, bootstrap)
+ },
+ snapshot: snapshotInstallDaemon,
+ verify: func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ return verifyDaemonAligned(ctx, cfg.BaseDir, cfg.HealthcheckHeartbeatInterval)
+ },
+ residentConfig: func(state health.DaemonState, base string) (string, bool) {
+ runtime, _ := resolveDaemonRuntime(state, base)
+ return runtime.ConfigPath, runtime.Availability == daemonRuntimeAvailable && strings.TrimSpace(runtime.ConfigPath) != ""
+ },
+ restart: restartAndVerifyDaemon,
+ removeCron: func(ctx context.Context) (cronRemovalOutcome, error) {
+ return removeCanonicalCronEntry(ctx, cronCorrectPaths(execInfo.ExecPath), bootstrap)
+ },
+ warnCron: func(ctx context.Context) int { return warnIndirectProxsaveCronOnDaemonInstall(ctx, bootstrap) },
+ cronPresent: canonicalCronLinePresent,
+ configureCron: func(ctx context.Context, schedule string) error {
+ if err := ctx.Err(); err != nil {
+ return err
+ }
+ runPostInstallSymlinksAndCron(ctx, baseDir, execInfo, bootstrap, schedule)
+ if err := ctx.Err(); err != nil {
+ return err
+ }
+ if daemonUnitInstalled() {
+ if err := removeDaemonService(ctx, bootstrap); err != nil {
+ logging.Warning("daemon: a previous daemon unit could not be removed (possible double execution): %v", err)
+ } else {
+ logging.Info("Removed the previous daemon service; this host now uses the cron scheduler.")
+ }
+ }
+ return ctx.Err()
+ },
+ }
+ return p
+}
+
+// Prepare returns only cancellation. Operational errors belong to the runtime
+// result so the monitoring screen can still diagnose the actual system.
+func (p *installRuntimePreparation) Prepare(ctx context.Context) error {
+ if err := ctx.Err(); err != nil {
+ return err
+ }
+ if !p.result.ConfigLoaded {
+ cfg, err := p.ops.loadConfig(p.configPath, p.baseDir)
+ if err != nil {
+ p.result.Err = err
+ return ctx.Err()
+ }
+ p.cfg = cfg
+ p.result.ConfigLoaded = true
+ p.result.Mode = cfg.SchedulerMode
+ p.result.Err = nil
+ }
+ if p.result.Mode == "daemon" {
+ reconcileSchedulerAfterInstall(ctx, p)
+ }
+ return ctx.Err()
+}
+
+func (p *installRuntimePreparation) Finalize(ctx context.Context) error {
+ if err := p.Prepare(ctx); err != nil {
+ return err
+ }
+ if !p.result.ConfigLoaded {
+ return p.result.Err
+ }
+ if p.result.Mode != "daemon" {
+ if !p.cronComplete {
+ if err := ctx.Err(); err != nil {
+ return err
+ }
+ if err := p.ops.configureCron(ctx, p.cronSchedule); err != nil {
+ return err
+ }
+ p.cronComplete = true
+ }
+ return ctx.Err()
+ }
+ p.RefreshStatus(ctx)
+ if err := ctx.Err(); err != nil {
+ return err
+ }
+ p.logOutcome()
+ // No rollback or fallback can infer safety from an error or an inactive unit.
+ // Existing confirmed scheduling may keep a partial installation nonfatal.
+ if p.result.Verification.ProcessAlive || p.result.Verification.State.Active {
+ return nil
+ }
+ if !p.result.CronRemoval.Verified {
+ if present, verified := p.ops.cronPresent(ctx); present && verified {
+ return nil
+ }
+ }
+ if p.result.Err != nil {
+ return p.result.Err
+ }
+ return errors.New("daemon service is not running")
+}
+
+func (p *installRuntimePreparation) RefreshStatus(ctx context.Context) RestartVerifyResult {
+ if p.cfg != nil && p.result.Mode == "daemon" {
+ p.result.Verification = p.ops.snapshot(ctx, p.cfg)
+ p.result.Verified = true
+ }
+ return p.result.Verification
+}
+
+func verifyInstallExecutable(canonical, expected string) error {
+ actual, err := os.Stat(canonical)
+ if err != nil {
+ return err
+ }
+ wanted, err := os.Stat(expected)
+ if err != nil {
+ return err
+ }
+ if !actual.Mode().IsRegular() || !wanted.Mode().IsRegular() || !os.SameFile(actual, wanted) {
+ return fmt.Errorf("canonical daemon executable %q does not identify %q", canonical, expected)
+ }
+ return nil
+}
+
+// installRuntimeVerdict gives configuration application priority over a later
+// binary probe. The same selector feeds the log and the existing Daemon field.
+func installRuntimeVerdict(result installRuntimeResult) (orchestrator.HealthcheckSetupLevel, string, string) {
+ if !result.UnitApplied && result.Err != nil {
+ return orchestrator.HealthcheckSetupLevelWarn, result.Err.Error(), fmt.Sprintf("Failed to enable the daemon service: %v", result.Err)
+ }
+ if result.RestartAttempted {
+ switch classifyRestartVerify(result.Restart) {
+ case restartVerifyDeferredConfig, restartVerifyDeferredBackup:
+ return orchestrator.HealthcheckSetupLevelWarn, "configuration not applied; manual restart required", "Daemon configuration not applied; manual restart required."
+ case restartVerifyError:
+ level, keyword, _ := restartVerifyStatus(result.Restart)
+ return level, keyword, fmt.Sprintf("Daemon restart failed: %v (it may still run the old binary; restart it manually).", result.Restart.Err)
+ }
+ }
+ level, keyword := installVerifyVerdict(result.Verification)
+ if level == orchestrator.HealthcheckSetupLevelOk {
+ return level, keyword, fmt.Sprintf("Daemon verified: %s.", keyword)
+ }
+ return level, keyword, fmt.Sprintf("Daemon %s.", keyword)
+}
+
+func (p *installRuntimePreparation) logOutcome() {
+ if !p.result.UnitApplied && p.result.Err != nil {
+ if p.applicationErrorLogged {
+ return
+ }
+ p.applicationErrorLogged = true
+ }
+ level, _, line := installRuntimeVerdict(p.result)
+ if level == orchestrator.HealthcheckSetupLevelOk {
+ logging.Info("%s", line)
+ } else {
+ logging.Warning("%s", line)
+ }
+}
+
+// inspectInstallDaemon does not confuse unreadable unit metadata with absence.
+func inspectInstallDaemon(ctx context.Context) (bool, health.DaemonPresence, error) {
+ _, err := os.Stat(daemonUnitPath)
+ if err != nil && !os.IsNotExist(err) {
+ return false, health.DaemonPresence{}, err
+ }
+ return err == nil, daemonPresenceProbe(ctx), nil
+}
+
+func snapshotInstallDaemon(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ st := restartVerifyDaemonState(health.DaemonStateInput{BaseDir: cfg.BaseDir, HeartbeatInterval: cfg.HealthcheckHeartbeatInterval, Now: time.Now(), Presence: daemonPresenceProbe(ctx), ProcAlive: probeProxsaveDaemonAlive, ProcStale: procBinaryStaleProbe})
+ return RestartVerifyResult{ProcessAlive: st.ProcessAlive, Aligned: st.Aligned, FreshInfo: st.HaveInfo, State: st}
+}
+
+// restartLock accepts only an unchanged resident config outside the rewritten
+// install path. A pathname alone cannot identify the lock an already-running
+// backup loaded before the wizard saved a new LOCK_PATH into that same file.
+func (p *installRuntimePreparation) restartLock() (string, bool) {
+ path, known := p.ops.residentConfig(p.initialState, p.cfg.BaseDir)
+ if !known || p.initialState.StartTS <= 0 || os.Getenv("LOCK_PATH") != "" {
+ return "", false
+ }
+ if !filepath.IsAbs(path) {
+ return "", false
+ }
+ resolved, err := filepath.EvalSymlinks(path)
+ if err != nil || resolved != filepath.Clean(path) {
+ return "", false
+ }
+ installed, err := os.Stat(p.configPath)
+ if err != nil {
+ return "", false
+ }
+ before, err := os.Stat(path)
+ if err != nil || !before.Mode().IsRegular() || os.SameFile(installed, before) {
+ return "", false
+ }
+ metadata, ok := before.Sys().(*syscall.Stat_t)
+ if !ok {
+ return "", false
+ }
+ start := time.Unix(p.initialState.StartTS, 0)
+ changed := time.Unix(metadata.Ctim.Sec, metadata.Ctim.Nsec)
+ if !before.ModTime().Before(start) || !changed.Before(start) {
+ return "", false
+ }
+ resident, err := p.ops.loadConfig(path, p.cfg.BaseDir)
+ if err != nil {
+ return "", false
+ }
+ after, err := os.Stat(path)
+ if err != nil || !os.SameFile(before, after) || before.Size() != after.Size() || !before.ModTime().Equal(after.ModTime()) {
+ return "", false
+ }
+ afterMetadata, ok := after.Sys().(*syscall.Stat_t)
+ if !ok || metadata.Ctim != afterMetadata.Ctim {
+ return "", false
+ }
+ // Only BASE_DIR is resolved independently of the installer shell. Other
+ // references may use environment overrides or fall back to its HOME, and
+ // relative paths depend on the resident process's unknown working directory.
+ raw, _ := resident.Get("LOCK_PATH")
+ remainingReferences := strings.Count(raw, "$")
+ safeReferences := true
+ os.Expand(raw, func(name string) string {
+ remainingReferences--
+ if strings.ToUpper(strings.TrimSpace(name)) != "BASE_DIR" {
+ safeReferences = false
+ }
+ return ""
+ })
+ if !safeReferences || remainingReferences != 0 {
+ return "", false
+ }
+ lock, known := backupLockFilePath(resident, resident.BaseDir)
+ if !known || !filepath.IsAbs(lock) {
+ return "", false
+ }
+ return lock, true
+}
+
+// PrepareCaptured drains the capture before returning; replay never logs again.
+func (p *installRuntimePreparation) PrepareCaptured(ctx context.Context) error {
+ restore := captureRunOutput(p.bootstrap, func(line string) { p.logs = append(p.logs, line) })
+ defer restore()
+ return p.Prepare(ctx)
+}
+
+func (p *installRuntimePreparation) Replay(emit func(string)) {
+ for _, line := range p.logs {
+ emit(line)
+ }
+ p.logs = nil
+}
diff --git a/cmd/proxsave/install_runtime_callback_test.go b/cmd/proxsave/install_runtime_callback_test.go
new file mode 100644
index 00000000..9286f96f
--- /dev/null
+++ b/cmd/proxsave/install_runtime_callback_test.go
@@ -0,0 +1,45 @@
+package main
+
+import (
+ "bufio"
+ "context"
+ "errors"
+ "reflect"
+ "strings"
+ "testing"
+
+ "github.com/tis24dev/proxsave/internal/installer"
+ "github.com/tis24dev/proxsave/internal/orchestrator"
+)
+
+// A missing callback or one run after bootstrap exposes the old runtime to the check.
+func TestHealthcheckCLIInstallerPreparationPrecedesDisabledBootstrap(t *testing.T) {
+ stubHealthcheckSetupCLIDeps(t)
+ var order []string
+ healthcheckSetupBuildBootstrap = func(context.Context, string, string) (orchestrator.HealthcheckSetupBootstrap, error) {
+ order = append(order, "bootstrap")
+ return orchestrator.HealthcheckSetupBootstrap{Eligibility: orchestrator.HealthcheckSetupSkipDisabled}, nil
+ }
+ err := runHealthcheckSetupCLI(context.Background(), bufio.NewReader(strings.NewReader("")), "/base", "/cfg", nil, installer.HealthcheckSetupOptions{BeforeBootstrap: func(context.Context) error {
+ order = append(order, "prepare")
+ return nil
+ }})
+ if err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(order, []string{"prepare", "bootstrap"}) {
+ t.Fatalf("order = %v", order)
+ }
+}
+
+func TestHealthcheckCLIPreparationCancellationStopsBootstrap(t *testing.T) {
+ stubHealthcheckSetupCLIDeps(t)
+ healthcheckSetupBuildBootstrap = func(context.Context, string, string) (orchestrator.HealthcheckSetupBootstrap, error) {
+ t.Fatal("bootstrap ran after cancellation")
+ return orchestrator.HealthcheckSetupBootstrap{}, nil
+ }
+ err := runHealthcheckSetupCLI(context.Background(), nil, "/base", "/cfg", nil, installer.HealthcheckSetupOptions{BeforeBootstrap: func(context.Context) error { return context.Canceled }})
+ if !errors.Is(err, context.Canceled) {
+ t.Fatalf("error = %v", err)
+ }
+}
diff --git a/cmd/proxsave/install_runtime_stream_test.go b/cmd/proxsave/install_runtime_stream_test.go
new file mode 100644
index 00000000..5e1c311c
--- /dev/null
+++ b/cmd/proxsave/install_runtime_stream_test.go
@@ -0,0 +1,53 @@
+package main
+
+import (
+ "context"
+ "errors"
+ "testing"
+
+ "github.com/tis24dev/proxsave/internal/ui/shell"
+)
+
+func TestInstallRuntimeFinalizationRetainsBackendFailure(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.cron = false
+ f.installErr = errors.New("start failed after enable")
+ ctx, cancel := context.WithCancel(context.Background())
+ defer cancel()
+ var buf shell.SyncBuffer
+ session := shell.StartForTestWithOutput(ctx, shell.Config{AppName: "ProxSave", Subtitle: "Install Wizard"}, &buf)
+ defer session.Close()
+ done := make(chan error, 1)
+ postRan := false
+ var backendErr error
+ go func() {
+ _, backendErr = runInstallFinalizationTask(ctx, session, f.p, func(context.Context) (string, string) { postRan = true; return "ok", "permissions OK" })
+ done <- backendErr
+ }()
+ // The real stream may expose a failed task until Continue; drive that same control.
+ err := pumpEnter(t, session, done)
+ if !errors.Is(err, f.installErr) || !errors.Is(backendErr, f.installErr) {
+ t.Fatalf("backend failure swallowed: returned=%v backend=%v", err, backendErr)
+ }
+ if postRan {
+ t.Fatal("success finalization ran after backend failure")
+ }
+}
+
+func TestInstallRuntimeClosedSessionDoesNotStartFinalization(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ session := shell.StartForTest(context.Background(), shell.Config{AppName: "ProxSave"})
+ if err := session.Close(); err != nil {
+ t.Fatal(err)
+ }
+ _, backendErr := runInstallFinalizationTask(context.Background(), session, f.p, func(context.Context) (string, string) {
+ t.Error("post-finalization ran on closed session")
+ return "", ""
+ })
+ if !errors.Is(backendErr, shell.ErrClosed) {
+ t.Fatalf("closed session backend=%v", backendErr)
+ }
+ if len(f.events) != 0 {
+ t.Fatalf("closed session mutated scheduler: %v", f.events)
+ }
+}
diff --git a/cmd/proxsave/install_runtime_test.go b/cmd/proxsave/install_runtime_test.go
new file mode 100644
index 00000000..62212cfd
--- /dev/null
+++ b/cmd/proxsave/install_runtime_test.go
@@ -0,0 +1,575 @@
+package main
+
+import (
+ "context"
+ "errors"
+ "fmt"
+ "os"
+ "path/filepath"
+ "reflect"
+ "strings"
+ "testing"
+ "time"
+
+ "github.com/tis24dev/proxsave/internal/config"
+ "github.com/tis24dev/proxsave/internal/health"
+ "github.com/tis24dev/proxsave/internal/installer"
+ "github.com/tis24dev/proxsave/internal/logging"
+ "github.com/tis24dev/proxsave/internal/orchestrator"
+ "github.com/tis24dev/proxsave/internal/ui/theme"
+)
+
+type installRuntimeFixture struct {
+ p *installRuntimePreparation
+ events []string
+ active bool
+ installed bool
+ cron bool
+ installErr error
+ restart RestartVerifyResult
+ resident string
+}
+
+func newInstallRuntimeFixture(t *testing.T) *installRuntimeFixture {
+ t.Helper()
+ dir := t.TempDir()
+ executable := filepath.Join(dir, "binary")
+ if err := os.WriteFile(executable, []byte("binary"), 0700); err != nil {
+ t.Fatal(err)
+ }
+ cfgPath := filepath.Join(dir, "backup.env")
+ if err := os.WriteFile(cfgPath, []byte("BASE_DIR="+dir+"\nSCHEDULER_MODE=daemon\nHEALTHCHECK_ENABLED=false\nLOCK_PATH="+dir+"/new-lock\n"), 0600); err != nil {
+ t.Fatal(err)
+ }
+ f := &installRuntimeFixture{cron: true}
+ p := newInstallRuntimePreparation(cfgPath, dir, ExecInfo{ExecPath: executable}, nil)
+ f.p = p
+ p.canonicalPath = filepath.Join(dir, "proxsave")
+ p.ops.entrypoints = func(ctx context.Context) error {
+ f.events = append(f.events, "entrypoints")
+ return os.Symlink(executable, p.canonicalPath)
+ }
+ p.ops.inspect = func(context.Context) (bool, health.DaemonPresence, error) {
+ return f.installed, health.DaemonPresence{Probed: true, Installed: f.installed, Active: f.active}, nil
+ }
+ p.ops.install = func(context.Context) error {
+ f.events = append(f.events, "install")
+ f.installed = true
+ if f.installErr == nil {
+ f.active = true
+ }
+ return f.installErr
+ }
+ p.ops.snapshot = func(context.Context, *config.Config) RestartVerifyResult {
+ return RestartVerifyResult{ProcessAlive: f.active, Aligned: f.active, State: health.DaemonState{ProcessAlive: f.active, Aligned: f.active, AlignChecked: true, HaveInfo: true}}
+ }
+ p.ops.verify = func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ f.events = append(f.events, "verify")
+ return p.ops.snapshot(ctx, cfg)
+ }
+ p.ops.residentConfig = func(health.DaemonState, string) (string, bool) { return f.resident, f.resident != "" }
+ p.ops.restart = func(ctx context.Context, base, lock string, known bool, interval time.Duration) RestartVerifyResult {
+ f.events = append(f.events, "restart:"+lock)
+ return f.restart
+ }
+ p.ops.removeCron = func(context.Context) (cronRemovalOutcome, error) {
+ f.events = append(f.events, "remove-cron")
+ f.cron = false
+ return cronRemovalOutcome{Removed: 1, Verified: true}, nil
+ }
+ p.ops.warnCron = func(context.Context) int { return 0 }
+ p.ops.cronPresent = func(context.Context) (bool, bool) { return f.cron, true }
+ p.ops.configureCron = func(context.Context, string) error {
+ f.events = append(f.events, "configure-cron")
+ f.cron = true
+ return nil
+ }
+ return f
+}
+
+func TestInstallRuntimeFreshStartsOnceBeforeFinalization(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ if err := f.p.Prepare(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"entrypoints", "install", "verify", "remove-cron"}) {
+ t.Fatalf("preparation=%v", f.events)
+ }
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"entrypoints", "install", "verify", "remove-cron"}) {
+ t.Fatalf("finalization repeated mutations: %v", f.events)
+ }
+ if !f.p.result.ActivationConfirmed || !f.p.result.CronRemoval.Verified {
+ t.Fatalf("result=%+v", f.p.result)
+ }
+}
+
+func TestInstallRuntimeWrongEntrypointNeverStartsDaemon(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ old := filepath.Join(t.TempDir(), "old-binary")
+ if err := os.WriteFile(old, []byte("old"), 0700); err != nil {
+ t.Fatal(err)
+ }
+ f.p.ops.entrypoints = func(context.Context) error { return os.Symlink(old, f.p.canonicalPath) }
+ if err := f.p.Prepare(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if f.p.result.Err == nil || f.installed || !f.cron {
+ t.Fatalf("wrong executable accepted: %+v events=%v", f.p.result, f.events)
+ }
+}
+
+func TestInstallRuntimeServiceInspectionErrorPreventsMutation(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.p.ops.inspect = func(context.Context) (bool, health.DaemonPresence, error) {
+ return false, health.DaemonPresence{}, os.ErrPermission
+ }
+ _ = f.p.Prepare(context.Background())
+ if len(f.events) != 0 || !errors.Is(f.p.result.Err, os.ErrPermission) {
+ t.Fatalf("events=%v error=%v", f.events, f.p.result.Err)
+ }
+}
+
+func TestInstallRuntimeFailedEnableDoesNotInventCronOrRepeatInstall(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.cron = false
+ f.installErr = errors.New("enable failed after enabling unit")
+ _ = f.p.Prepare(context.Background())
+ if err := f.p.Finalize(context.Background()); !errors.Is(err, f.installErr) {
+ t.Fatalf("error=%v", err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"entrypoints", "install"}) || f.cron {
+ t.Fatalf("unsafe fallback/retry: %v", f.events)
+ }
+}
+
+func TestInstallRuntimeCronFailureDoesNotRestartActivatedDaemon(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ attempts := 0
+ f.p.ops.removeCron = func(context.Context) (cronRemovalOutcome, error) {
+ attempts++
+ return cronRemovalOutcome{}, os.ErrPermission
+ }
+ _ = f.p.Prepare(context.Background())
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"entrypoints", "install", "verify"}) || attempts != 2 || f.p.result.CronRemoval.Verified {
+ t.Fatalf("events=%v removal attempts=%d result=%+v", f.events, attempts, f.p.result)
+ }
+}
+
+func TestInstallRuntimeDeferredRestartSurvivesAlignedRefresh(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ f.resident = f.p.configPath
+ f.restart = RestartVerifyResult{BackupWaitTimedOut: true}
+ _ = f.p.Prepare(context.Background())
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !f.p.result.Restart.BackupWaitTimedOut || !f.p.result.Verification.Aligned {
+ t.Fatalf("defer erased: %+v", f.p.result)
+ }
+ restarts := 0
+ for _, e := range f.events {
+ if len(e) >= 8 && e[:8] == "restart:" {
+ restarts++
+ }
+ }
+ if restarts != 1 {
+ t.Fatalf("restarts=%d events=%v", restarts, f.events)
+ }
+}
+
+func TestInstallRuntimeResidentConfigControlsProtectedRestartLock(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ resident := filepath.Join(t.TempDir(), "resident.env")
+ if err := os.WriteFile(resident, []byte("BASE_DIR=/resident\nLOCK_PATH=/resident/custom-lock\n"), 0600); err != nil {
+ t.Fatal(err)
+ }
+ f.resident = resident
+ // The direct resident config predates the running daemon, including its ctime.
+ start := time.Now().Unix() + 1
+ time.Sleep(time.Until(time.Unix(start, 0)))
+ snapshot := f.p.ops.snapshot
+ f.p.ops.snapshot = func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ rv := snapshot(ctx, cfg)
+ rv.State.StartTS = start
+ return rv
+ }
+ f.p.ops.restart = func(_ context.Context, base, lock string, known bool, _ time.Duration) RestartVerifyResult {
+ if !known || lock != "/resident/custom-lock/.backup.lock" {
+ t.Fatalf("restart lock=%q known=%v base=%q", lock, known, base)
+ }
+ return RestartVerifyResult{BackupWaitTimedOut: true}
+ }
+ _ = f.p.Prepare(context.Background())
+ if !f.p.result.Restart.BackupWaitTimedOut {
+ t.Fatal("protected restart was omitted")
+ }
+}
+
+func TestInstallRuntimeUnknownResidentConfigDefersRestart(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ f.p.ops.restart = func(_ context.Context, _, _ string, known bool, _ time.Duration) RestartVerifyResult {
+ if known {
+ t.Fatal("unknown resident config treated as safe")
+ }
+ return RestartVerifyResult{LockPathUnknown: true}
+ }
+ _ = f.p.Prepare(context.Background())
+ if !f.p.result.Restart.LockPathUnknown {
+ t.Fatal("restart not deferred")
+ }
+}
+
+func TestInstallRuntimeCancelledPreparationDoesNotMutate(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ ctx, cancel := context.WithCancel(context.Background())
+ cancel()
+ if err := f.p.Prepare(ctx); !errors.Is(err, context.Canceled) {
+ t.Fatalf("error=%v", err)
+ }
+ if len(f.events) != 0 {
+ t.Fatalf("mutations=%v", f.events)
+ }
+}
+
+func TestInstallRuntimeStopAfterHandoverIsReadOnly(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ _ = f.p.Prepare(context.Background())
+ f.active = false
+ if err := f.p.Finalize(context.Background()); err == nil {
+ t.Fatal("stopped daemon without cron reported success")
+ }
+ if f.p.result.Verification.ProcessAlive || f.cron || !reflect.DeepEqual(f.events, []string{"entrypoints", "install", "verify", "remove-cron"}) {
+ t.Fatalf("events=%v result=%+v", f.events, f.p.result)
+ }
+}
+
+func TestInstallRuntimeCronWaitsForFinalization(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ if err := os.WriteFile(f.p.configPath, []byte("SCHEDULER_MODE=cron\n"), 0600); err != nil {
+ t.Fatal(err)
+ }
+ _ = f.p.Prepare(context.Background())
+ if len(f.events) != 0 {
+ t.Fatalf("early cron mutations=%v", f.events)
+ }
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"configure-cron"}) {
+ t.Fatalf("events=%v", f.events)
+ }
+}
+
+func TestInstallRuntimeOperationalErrorDoesNotBlockMonitoringBootstrap(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installErr = errors.New("service rejected start")
+ stubHealthcheckSetupCLIDeps(t)
+ reached := false
+ healthcheckSetupBuildBootstrap = func(context.Context, string, string) (orchestrator.HealthcheckSetupBootstrap, error) {
+ reached = true
+ return orchestrator.HealthcheckSetupBootstrap{Eligibility: orchestrator.HealthcheckSetupSkipDisabled}, nil
+ }
+ if err := runHealthcheckSetupCLI(context.Background(), nil, f.p.baseDir, f.p.configPath, nil, installer.HealthcheckSetupOptions{BeforeBootstrap: f.p.Prepare}); err != nil {
+ t.Fatal(err)
+ }
+ if !reached || !errors.Is(f.p.result.Err, f.installErr) {
+ t.Fatalf("bootstrap=%v recorded=%v", reached, f.p.result.Err)
+ }
+}
+
+func TestInstallRuntimeConfigFailureDoesNotGuessCron(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ if err := os.Remove(f.p.configPath); err != nil {
+ t.Fatal(err)
+ }
+ _ = f.p.Prepare(context.Background())
+ if err := f.p.Finalize(context.Background()); err == nil {
+ t.Fatal("unreadable configuration accepted")
+ }
+ if len(f.events) != 0 {
+ t.Fatalf("mutations=%v", f.events)
+ }
+}
+
+func TestInstallRuntimeCancelledAfterStartResumesOnlyVerification(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ ctx, cancel := context.WithCancel(context.Background())
+ install := f.p.ops.install
+ f.p.ops.install = func(ctx context.Context) error { err := install(ctx); cancel(); return err }
+ if err := f.p.Prepare(ctx); !errors.Is(err, context.Canceled) {
+ t.Fatalf("error=%v", err)
+ }
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"entrypoints", "install", "verify", "remove-cron"}) {
+ t.Fatalf("resume repeated completed phases: %v", f.events)
+ }
+}
+
+func TestInstallRuntimeReadinessTimeoutDoesNotRepeatActivation(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.p.ops.verify = func(context.Context, *config.Config) RestartVerifyResult {
+ f.events = append(f.events, "verify-timeout")
+ return RestartVerifyResult{TimedOut: true}
+ }
+ _ = f.p.Prepare(context.Background())
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if !reflect.DeepEqual(f.events, []string{"entrypoints", "install", "verify-timeout", "remove-cron"}) {
+ t.Fatalf("events=%v", f.events)
+ }
+}
+
+func TestInstallRuntimeCaptureReplaysOnceWithoutLoggingAgain(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ bootstrap := logging.NewBootstrapLogger()
+ f.p.bootstrap = bootstrap
+ prepare := f.p.ops.entrypoints
+ f.p.ops.entrypoints = func(ctx context.Context) error {
+ bootstrap.Info("captured installer operation")
+ logging.Info("captured global operation")
+ fmt.Println("captured raw output")
+ return prepare(ctx)
+ }
+ outer := captureStdout(t, func() {
+ if err := f.p.PrepareCaptured(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ })
+ if strings.Contains(outer, "captured") {
+ t.Fatalf("escaped capture: %q", outer)
+ }
+ count := bootstrap.EntryCount()
+ var lines []string
+ f.p.Replay(func(s string) { lines = append(lines, s) })
+ f.p.Replay(func(s string) { lines = append(lines, s) })
+ output := strings.Join(lines, "\n")
+ for _, want := range []string{"captured installer operation", "captured global operation", "captured raw output"} {
+ if strings.Count(output, want) != 1 {
+ t.Fatalf("%q not displayed exactly once: %q", want, output)
+ }
+ }
+ if bootstrap.EntryCount() != count {
+ t.Fatalf("replay persisted duplicate logs: before=%d after=%d", count, bootstrap.EntryCount())
+ }
+}
+
+func TestInstallRuntimeUnknownSystemdStatePreventsActivation(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.p.ops.inspect = func(context.Context) (bool, health.DaemonPresence, error) { return false, health.DaemonPresence{}, nil }
+ _ = f.p.Prepare(context.Background())
+ if len(f.events) != 0 || f.p.result.Err == nil {
+ t.Fatalf("unknown service state allowed activation: events=%v error=%v", f.events, f.p.result.Err)
+ }
+}
+
+func TestInstallRuntimeOutcomeKeepsPendingApplication(t *testing.T) {
+ for _, restart := range []RestartVerifyResult{{BackupWaitTimedOut: true}, {LockPathUnknown: true}, {Err: errors.New("restart rejected")}} {
+ result := installRuntimeResult{Mode: "daemon", RestartAttempted: true, Restart: restart, Verification: RestartVerifyResult{ProcessAlive: true, Aligned: true}}
+ out := buildInstallOutcomePrompt(result.Verification, true, "ok", "permissions OK", result)
+ if strings.Contains(out, "running and aligned") {
+ t.Fatalf("pending application shown as aligned success: %q", out)
+ }
+ }
+}
+
+func TestInstallRuntimeApplicationFailureCannotBecomeAlignedSuccess(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ f.installErr = errors.New("systemctl daemon-reload failed")
+ _ = f.p.Prepare(context.Background())
+ if err := f.p.Finalize(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ out := buildInstallOutcomePrompt(f.p.result.Verification, true, "ok", "permissions OK", f.p.result)
+ if strings.Contains(out, "running and aligned") || !strings.Contains(out, f.installErr.Error()) {
+ t.Fatalf("application failure hidden by alignment: %q", out)
+ }
+}
+
+func TestInstallRuntimeRewrittenResidentConfigCannotProveActiveBackupLock(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ f.resident = f.p.configPath
+ // Exercise the rewritten-file guard with a real positive start timestamp,
+ // after the file metadata so the timestamp guard alone cannot pass this test.
+ start := time.Now().Unix() + 1
+ time.Sleep(time.Until(time.Unix(start, 0)))
+ snapshot := f.p.ops.snapshot
+ f.p.ops.snapshot = func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ rv := snapshot(ctx, cfg)
+ rv.State.StartTS = start
+ return rv
+ }
+ // The installer saved /new-lock, but a child that already started still holds /old-lock.
+ oldLock := filepath.Join(f.p.baseDir, "old-lock", ".backup.lock")
+ previousRestart, previousBackup := daemonRestartService, restartVerifyBackupRunning
+ t.Cleanup(func() { daemonRestartService = previousRestart; restartVerifyBackupRunning = previousBackup })
+ restarts := 0
+ daemonRestartService = func(context.Context) error { restarts++; return errors.New("unsafe restart") }
+ restartVerifyBackupRunning = func(path string) bool { return path == oldLock }
+ f.p.ops.restart = restartAndVerifyDaemon
+ _ = f.p.Prepare(context.Background())
+ if restarts != 0 || !f.p.result.Restart.LockPathUnknown {
+ t.Fatalf("rewritten config hid live backup lock: restarts=%d result=%+v", restarts, f.p.result.Restart)
+ }
+}
+
+func TestInstallRuntimeResidentLockRequiresIndependentResolution(t *testing.T) {
+ tests := []struct {
+ name string
+ content string
+ envKey string
+ envValue string
+ wantKnown bool
+ wantSuffix string
+ }{
+ {name: "default", wantKnown: true, wantSuffix: "lock/.backup.lock"},
+ {name: "literal", content: "LOCK_PATH=/resident/lock\n", wantKnown: true, wantSuffix: "/resident/lock/.backup.lock"},
+ {name: "base variable", content: "LOCK_PATH=$BASE_DIR/custom\n", wantKnown: true, wantSuffix: "custom/.backup.lock"},
+ {name: "braced base variable", content: "LOCK_PATH=${BASE_DIR}/custom\n", wantKnown: true, wantSuffix: "custom/.backup.lock"},
+ {name: "backup override", content: "BACKUP_PATH=/resident/backups\nLOCK_PATH=${BACKUP_PATH}/lock\n", envKey: "BACKUP_PATH", envValue: "/installer/backups"},
+ {name: "home fallback", content: "LOCK_PATH=${HOME}/lock\n", envKey: "HOME", envValue: "/installer/home"},
+ {name: "relative path", content: "LOCK_PATH=relative/lock\n"},
+ {name: "whitespace override", content: "LOCK_PATH=/resident/lock\n", envKey: "LOCK_PATH", envValue: " "},
+ }
+ residentDir := t.TempDir()
+ for i, tc := range tests {
+ if err := os.WriteFile(filepath.Join(residentDir, fmt.Sprintf("%d.env", i)), []byte(tc.content), 0600); err != nil {
+ t.Fatal(err)
+ }
+ }
+ // All distinct resident files must predate the resident process, including ctime.
+ start := time.Now().Unix() + 1
+ time.Sleep(time.Until(time.Unix(start, 0)))
+ for i, tc := range tests {
+ t.Run(tc.name, func(t *testing.T) {
+ t.Setenv("LOCK_PATH", "")
+ if tc.envKey != "" {
+ t.Setenv(tc.envKey, tc.envValue)
+ }
+ f := newInstallRuntimeFixture(t)
+ f.installed, f.active = true, true
+ f.resident = filepath.Join(residentDir, fmt.Sprintf("%d.env", i))
+ snapshot := f.p.ops.snapshot
+ f.p.ops.snapshot = func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ rv := snapshot(ctx, cfg)
+ rv.State.StartTS = start
+ return rv
+ }
+ calls := 0
+ f.p.ops.restart = func(_ context.Context, _, lock string, known bool, _ time.Duration) RestartVerifyResult {
+ calls++
+ if known != tc.wantKnown {
+ t.Errorf("resident lock=%q known=%v, want known=%v", lock, known, tc.wantKnown)
+ }
+ if known {
+ want := tc.wantSuffix
+ if !filepath.IsAbs(want) {
+ want = filepath.Join(f.p.baseDir, want)
+ }
+ if lock != want {
+ t.Errorf("resident lock=%q, want %q", lock, want)
+ }
+ }
+ return RestartVerifyResult{LockPathUnknown: !known}
+ }
+ if err := f.p.Prepare(context.Background()); err != nil {
+ t.Fatal(err)
+ }
+ if calls != 1 || f.p.result.Restart.LockPathUnknown == tc.wantKnown {
+ t.Fatalf("protected restart calls=%d result=%+v", calls, f.p.result.Restart)
+ }
+ })
+ }
+}
+
+func TestInstallRuntimeDeferredApplicationUsesApprovedWarning(t *testing.T) {
+ for _, restart := range []RestartVerifyResult{{LockPathUnknown: true}, {BackupWaitTimedOut: true}} {
+ result := installRuntimeResult{Mode: "daemon", UnitApplied: true, RestartAttempted: true, Restart: restart, Verification: RestartVerifyResult{ProcessAlive: true, Aligned: true}}
+ level, field, log := installRuntimeVerdict(result)
+ if level != orchestrator.HealthcheckSetupLevelWarn || field != "configuration not applied; manual restart required" || log != "Daemon configuration not applied; manual restart required." {
+ t.Errorf("deferred outcome: level=%v field=%q log=%q", level, field, log)
+ }
+ out := buildInstallOutcomePrompt(result.Verification, true, "ok", "permissions OK", result)
+ if !strings.Contains(out, theme.SymbolWarning+" "+"configuration not applied; manual restart required") {
+ t.Errorf("missing approved warning in final Daemon field: %q", out)
+ }
+ }
+}
+
+func TestInstallRuntimeResidentLockRejectsInstallerEnvironment(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ resident := filepath.Join(t.TempDir(), "resident.env")
+ if err := os.WriteFile(resident, []byte("LOCK_PATH=/resident/lock\n"), 0600); err != nil {
+ t.Fatal(err)
+ }
+ f.resident = resident
+ start := time.Now().Unix() + 1
+ time.Sleep(time.Until(time.Unix(start, 0)))
+ snapshot := f.p.ops.snapshot
+ f.p.ops.snapshot = func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ rv := snapshot(ctx, cfg)
+ rv.State.StartTS = start
+ return rv
+ }
+ t.Setenv("LOCK_PATH", "/installer/override")
+ known := true
+ f.p.ops.restart = func(_ context.Context, _, _ string, k bool, _ time.Duration) RestartVerifyResult {
+ known = k
+ return RestartVerifyResult{LockPathUnknown: !k}
+ }
+ _ = f.p.Prepare(context.Background())
+ if known {
+ t.Fatal("installer's LOCK_PATH treated as resident process evidence")
+ }
+}
+
+func TestInstallRuntimeChangedResidentMetadataDefersRestart(t *testing.T) {
+ f := newInstallRuntimeFixture(t)
+ f.installed = true
+ f.active = true
+ resident := filepath.Join(t.TempDir(), "resident.env")
+ if err := os.WriteFile(resident, []byte("LOCK_PATH=/resident/lock\n"), 0600); err != nil {
+ t.Fatal(err)
+ }
+ // Preserving mtime alone cannot disguise a file replaced after the daemon started.
+ old := time.Now().Add(-time.Hour)
+ if err := os.Chtimes(resident, old, old); err != nil {
+ t.Fatal(err)
+ }
+ f.resident = resident
+ snapshot := f.p.ops.snapshot
+ f.p.ops.snapshot = func(ctx context.Context, cfg *config.Config) RestartVerifyResult {
+ rv := snapshot(ctx, cfg)
+ rv.State.StartTS = time.Now().Add(-time.Minute).Unix()
+ return rv
+ }
+ known := true
+ f.p.ops.restart = func(_ context.Context, _, _ string, k bool, _ time.Duration) RestartVerifyResult {
+ known = k
+ return RestartVerifyResult{LockPathUnknown: !k}
+ }
+ _ = f.p.Prepare(context.Background())
+ if known {
+ t.Fatal("post-start config ctime ignored")
+ }
+}
diff --git a/cmd/proxsave/install_runtime_ui.go b/cmd/proxsave/install_runtime_ui.go
new file mode 100644
index 00000000..e222b66e
--- /dev/null
+++ b/cmd/proxsave/install_runtime_ui.go
@@ -0,0 +1,30 @@
+package main
+
+import (
+ "context"
+
+ "github.com/tis24dev/proxsave/internal/ui/components"
+ "github.com/tis24dev/proxsave/internal/ui/shell"
+)
+
+// runInstallFinalizationTask keeps a backend failure independently of the stream
+// presentation result, which can be nil when the user dismisses a failed task.
+func runInstallFinalizationTask(ctx context.Context, session *shell.Session, p *installRuntimePreparation, finish func(context.Context) (string, string)) (streamErr, backendErr error) {
+ streamErr = components.RunStreamTask(ctx, session, "Finalizing installation", func(taskCtx context.Context, emit func(string)) (string, error) {
+ select {
+ case <-session.Done():
+ backendErr = shell.ErrClosed
+ return "", backendErr
+ default:
+ }
+ p.Replay(emit)
+ defer captureRunOutput(p.bootstrap, emit)()
+ backendErr = p.Finalize(taskCtx)
+ if backendErr != nil {
+ return "", backendErr
+ }
+ permStatus, permMessage := finish(taskCtx)
+ return buildInstallOutcomePrompt(p.result.Verification, p.result.Mode == "daemon", permStatus, permMessage, p.result), nil
+ })
+ return streamErr, backendErr
+}
diff --git a/cmd/proxsave/install_tui.go b/cmd/proxsave/install_tui.go
index e9e0f82f..00b9ac74 100644
--- a/cmd/proxsave/install_tui.go
+++ b/cmd/proxsave/install_tui.go
@@ -11,7 +11,6 @@ import (
"github.com/tis24dev/proxsave/internal/installer"
"github.com/tis24dev/proxsave/internal/logging"
"github.com/tis24dev/proxsave/internal/orchestrator"
- "github.com/tis24dev/proxsave/internal/ui/components"
"github.com/tis24dev/proxsave/internal/ui/flows/agesetup"
flowinstall "github.com/tis24dev/proxsave/internal/ui/flows/install"
"github.com/tis24dev/proxsave/internal/ui/shell"
@@ -56,9 +55,9 @@ func runInstallTUI(ctx context.Context, configPath string, bootstrap *logging.Bo
baseDir, _ := detectedBaseDirOrFallback()
_ = os.Setenv("BASE_DIR", baseDir)
- // Entrypoint cleanup + recreation is deferred to runPostInstallSymlinksAndCron
- // (success path only), so an aborted/non-interactive install never leaves the
- // host without a working proxsave/proxmox-backup command.
+ // Entrypoint changes belong to runtime preparation after the configuration
+ // and optional setup writes have completed. A rejected configuration wizard
+ // never changes the executable entrypoints.
execInfo := getExecInfo()
if bootstrap != nil {
@@ -233,6 +232,7 @@ func runInstallTUI(ctx context.Context, configPath string, bootstrap *logging.Bo
// Optional post-install audit: run a dry-run and offer to disable unused collectors
// based on actionable warning hints like "set BACKUP_*=false to disable".
+ runtimePreparation := newInstallRuntimePreparation(configPath, baseDir, execInfo, bootstrap)
if !skipConfigWizard {
auditRes, auditErr := flowinstall.RunPostInstallAudit(ctx, session, execInfo.ExecPath, configPath, false)
if abortErr := abortInstallOnOptionalStep(ctx, bootstrap, "Post-install audit", auditErr); abortErr != nil {
@@ -294,7 +294,7 @@ func runInstallTUI(ctx context.Context, configPath string, bootstrap *logging.Bo
// the user + (centralized) show the portal magic-link + a connection check, or
// (self) verify the pasted alive URL is reachable. Eligibility is decided solely
// by RunHealthcheckSetup (re-reads the written config); Shown=false with no UI otherwise.
- hcRes, hcErr := flowinstall.RunHealthcheckSetup(ctx, session, baseDir, configPath, false)
+ hcRes, hcErr := flowinstall.RunHealthcheckSetup(ctx, session, baseDir, configPath, false, installer.HealthcheckSetupOptions{BeforeBootstrap: runtimePreparation.PrepareCaptured})
if abortErr := abortInstallOnOptionalStep(ctx, bootstrap, "Healthcheck setup", hcErr); abortErr != nil {
return abortErr
}
@@ -321,26 +321,9 @@ func runInstallTUI(ctx context.Context, configPath string, bootstrap *logging.Bo
logScheduleLines(bootstrap, seedSchedulerTimeFromCrontabFn(ctx, configPath).Block.lines())
}
- cronSchedule := buildInstallCronSchedule(skipConfigWizard, wizardCronSchedule, configPath)
- wizardMode := ""
- if wizardData != nil {
- wizardMode = wizardData.SchedulerMode
- }
-
- streamErr := components.RunStreamTask(ctx, session, "Finalizing installation",
- func(taskCtx context.Context, emit func(line string)) (string, error) {
- // Route the loggers AND raw os.Stdout (fmt.Println spacers) through one
- // pipe into the panel; restored on return/panic. So the panel shows the
- // same colored lines + blank section spacers as the CLI. (captureRunOutput
- // is defined in backup_stream.go.)
- defer captureRunOutput(bootstrap, emit)()
-
- // Finalize legacy-symlink cleanup, entrypoint cleanup/recreation, and cron
- // via the shared post-install engine (the same runPostInstallSymlinksAndCron
- // the CLI uses), so TUI and CLI behave identically here.
- runPostInstallSymlinksAndCron(taskCtx, baseDir, execInfo, bootstrap, cronSchedule)
- rv, verified := reconcileSchedulerAfterInstall(taskCtx, wizardMode, configPath, execInfo, bootstrap)
-
+ runtimePreparation.cronSchedule = buildInstallCronSchedule(skipConfigWizard, wizardCronSchedule, configPath)
+ streamErr, backendFinalizeErr := runInstallFinalizationTask(ctx, session, runtimePreparation,
+ func(taskCtx context.Context) (string, string) {
// Attempt to resolve or create a server identity for Telegram pairing.
if info, idErr := identity.DetectWithContext(taskCtx, baseDir, nil); idErr == nil {
if code := info.ServerID; code != "" {
@@ -361,11 +344,11 @@ func runInstallTUI(ctx context.Context, configPath string, bootstrap *logging.Bo
permStatus, permMessage = fixPermissionsAfterInstall(taskCtx, configPath, baseDir, bootstrap, nil)
logging.DebugStepBootstrap(bootstrap, "install workflow (tui)", "permissions status=%s", permStatus)
- return buildInstallOutcomePrompt(rv, verified, permStatus, permMessage), nil
+ return permStatus, permMessage
})
if streamErr != nil {
- // Finalization is best-effort (the CLI ignores these errors too): an abort
- // or UI-death here never fails the install, so only trace it.
+ // Stream presentation errors are best-effort; backend failures are
+ // retained separately and returned below.
logging.DebugStepBootstrap(bootstrap, "install workflow (tui)", "finalization stream: %v", streamErr)
}
@@ -387,6 +370,9 @@ func runInstallTUI(ctx context.Context, configPath string, bootstrap *logging.Bo
return wrapInstallError(errInteractiveAborted)
}
+ if backendFinalizeErr != nil {
+ return backendFinalizeErr
+ }
return nil
}
diff --git a/cmd/proxsave/main.go b/cmd/proxsave/main.go
index 467af351..5f327681 100644
--- a/cmd/proxsave/main.go
+++ b/cmd/proxsave/main.go
@@ -10,7 +10,7 @@ import (
)
const (
- goRuntimeMinVersion = "1.26.8"
+ goRuntimeMinVersion = "1.26.9"
networkPreflightTimeout = 2 * time.Second
bytesPerMegabyte int64 = 1024 * 1024
defaultDirPerm = 0o755
diff --git a/cmd/proxsave/main_support_email_flow_test.go b/cmd/proxsave/main_support_email_flow_test.go
new file mode 100644
index 00000000..a4a23f3b
--- /dev/null
+++ b/cmd/proxsave/main_support_email_flow_test.go
@@ -0,0 +1,108 @@
+package main
+
+import (
+ "context"
+ "io"
+ "testing"
+ "time"
+
+ "github.com/tis24dev/proxsave/internal/cli"
+ "github.com/tis24dev/proxsave/internal/config"
+ "github.com/tis24dev/proxsave/internal/environment"
+ "github.com/tis24dev/proxsave/internal/logging"
+ "github.com/tis24dev/proxsave/internal/orchestrator"
+ "github.com/tis24dev/proxsave/internal/support"
+ "github.com/tis24dev/proxsave/internal/types"
+)
+
+func TestDeferredSupportEmailGates(t *testing.T) {
+ for _, tc := range []struct {
+ name string
+ supportMode bool
+ hasStats bool
+ alreadySent bool
+ wantCalls int
+ }{
+ {"normal_run", false, true, false, 0},
+ {"no_stats", true, false, false, 0},
+ {"already_attempted_in_dashboard", true, true, true, 0},
+ {"pending_support_run", true, true, false, 1},
+ } {
+ t.Run(tc.name, func(t *testing.T) {
+ original := emitSupportEmail
+ t.Cleanup(func() { emitSupportEmail = original })
+ calls := 0
+ emitSupportEmail = func(context.Context, *config.Config, *logging.Logger, types.ProxmoxType, *orchestrator.BackupStats, support.Meta) {
+ calls++
+ }
+ rt := &appRuntime{args: &cli.Args{Support: tc.supportMode}, envInfo: &environment.EnvironmentInfo{}}
+ state := &appRunState{supportEmailSent: tc.alreadySent}
+ if tc.hasStats {
+ state.pendingSupportStat = &orchestrator.BackupStats{ExitCode: 2}
+ }
+ sendDeferredSupportEmail(rt, state)
+ if calls != tc.wantCalls {
+ t.Errorf("support email attempts = %d; want %d", calls, tc.wantCalls)
+ }
+ })
+ }
+}
+
+func TestDeferredSupportEmailPayloadAndLifetime(t *testing.T) {
+ for _, tc := range []struct {
+ name string
+ cfg *config.Config
+ timeout time.Duration
+ }{
+ {"nil_config", nil, 30 * time.Second},
+ {"default_timeout", &config.Config{}, 30 * time.Second},
+ {"negative_timeout", &config.Config{WorkerTimeout: -1}, 30 * time.Second},
+ {"configured_timeout", &config.Config{WorkerTimeout: 7}, 7 * time.Second},
+ } {
+ t.Run(tc.name, func(t *testing.T) {
+ original := emitSupportEmail
+ t.Cleanup(func() { emitSupportEmail = original })
+ logger := logging.New(types.LogLevelDebug, false)
+ logger.SetOutput(io.Discard)
+ stats := &orchestrator.BackupStats{Hostname: "pbs-test", ExitCode: 2, LogFilePath: "/tmp/support-test.log"}
+ meta := support.Meta{GitHubUser: "alice", IssueID: "#42"}
+ runCtx, cancel := context.WithCancel(context.Background())
+ cancel()
+ rt := &appRuntime{
+ ctx: runCtx, cfg: tc.cfg, logger: logger,
+ args: &cli.Args{Support: true, SupportGitHubUser: meta.GitHubUser, SupportIssueID: meta.IssueID},
+ envInfo: &environment.EnvironmentInfo{Type: types.ProxmoxBS},
+ }
+ var finalCtx context.Context
+ var deadline time.Time
+ calls := 0
+ emitSupportEmail = func(ctx context.Context, cfg *config.Config, gotLogger *logging.Logger, platform types.ProxmoxType, gotStats *orchestrator.BackupStats, gotMeta support.Meta) {
+ calls++
+ finalCtx = ctx
+ if ctx.Err() != nil {
+ t.Errorf("support finalization inherited the cancelled run context: %v", ctx.Err())
+ }
+ var ok bool
+ deadline, ok = ctx.Deadline()
+ if !ok {
+ t.Error("support finalization has no timeout")
+ }
+ if cfg != tc.cfg || gotLogger != logger || platform != types.ProxmoxBS || gotStats != stats || gotMeta != meta {
+ t.Error("deferred support email lost configuration, log, host identity, stats or issue metadata")
+ }
+ }
+ before := time.Now()
+ sendDeferredSupportEmail(rt, &appRunState{pendingSupportStat: stats})
+ after := time.Now()
+ if calls != 1 || finalCtx == nil {
+ t.Fatal("deferred support email was not attempted exactly once")
+ }
+ if deadline.Before(before.Add(tc.timeout)) || deadline.After(after.Add(tc.timeout)) {
+ t.Errorf("finalization deadline = %v; want configured timeout %v", deadline, tc.timeout)
+ }
+ if finalCtx.Err() != context.Canceled {
+ t.Errorf("finalization context was not released after sending: %v", finalCtx.Err())
+ }
+ })
+ }
+}
diff --git a/cmd/proxsave/testdata/install_characterization/edit_noop.env b/cmd/proxsave/testdata/install_characterization/edit_noop.env
index b10be5c1..3412acbe 100644
--- a/cmd/proxsave/testdata/install_characterization/edit_noop.env
+++ b/cmd/proxsave/testdata/install_characterization/edit_noop.env
@@ -350,15 +350,17 @@ METRICS_PATH=${BASE_DIR}/metrics
# Collector options
# ----------------------------------------------------------------------
# PVE
-# BACKUP_CLUSTER_CONFIG controls both cluster config collection and cluster runtime commands
-# (corosync.conf / pve-cluster data, pvecm status/nodes, and HA status collection).
+# BACKUP_CLUSTER_CONFIG controls Corosync and cluster-specific data/runtime collection.
+# config.db and the base /etc/pve snapshot are collected independently, including on standalone hosts.
+# To exclude config.db and its sidecars, add config.db* to BACKUP_EXCLUDE_PATTERNS.
+# Missing Corosync files do not warn on a confirmed standalone host.
# NOTE: If a feature is enabled but not configured on this node, ProxSave logs a WARNING (exit code 1). Disable unused features via the BACKUP_* flags below.
BACKUP_CLUSTER_CONFIG=true
BACKUP_PVE_FIREWALL=true
BACKUP_VZDUMP_CONFIG=true
# BACKUP_PVE_ACL=false also excludes the credential files /etc/pve/priv/{shadow,token,tfa}.cfg
-# (password hashes, API token secrets, TFA secrets) from the /etc/pve snapshot. NOTE: those secrets
-# also live inside the cluster database config.db; to exclude them entirely also set BACKUP_CLUSTER_CONFIG=false.
+# from the /etc/pve snapshot. Their secrets remain in config.db; to exclude the database
+# and its sidecars, add config.db* to BACKUP_EXCLUDE_PATTERNS.
BACKUP_PVE_ACL=true # Access control (users/roles/groups/ACL + priv credentials; realms when configured)
BACKUP_PVE_JOBS=true
BACKUP_PVE_SCHEDULES=true
diff --git a/cmd/proxsave/testdata/install_characterization/fresh_decline_all.env b/cmd/proxsave/testdata/install_characterization/fresh_decline_all.env
index 5ecfd8c8..3b21ce93 100644
--- a/cmd/proxsave/testdata/install_characterization/fresh_decline_all.env
+++ b/cmd/proxsave/testdata/install_characterization/fresh_decline_all.env
@@ -350,15 +350,17 @@ METRICS_PATH=${BASE_DIR}/metrics
# Collector options
# ----------------------------------------------------------------------
# PVE
-# BACKUP_CLUSTER_CONFIG controls both cluster config collection and cluster runtime commands
-# (corosync.conf / pve-cluster data, pvecm status/nodes, and HA status collection).
+# BACKUP_CLUSTER_CONFIG controls Corosync and cluster-specific data/runtime collection.
+# config.db and the base /etc/pve snapshot are collected independently, including on standalone hosts.
+# To exclude config.db and its sidecars, add config.db* to BACKUP_EXCLUDE_PATTERNS.
+# Missing Corosync files do not warn on a confirmed standalone host.
# NOTE: If a feature is enabled but not configured on this node, ProxSave logs a WARNING (exit code 1). Disable unused features via the BACKUP_* flags below.
BACKUP_CLUSTER_CONFIG=true
BACKUP_PVE_FIREWALL=true
BACKUP_VZDUMP_CONFIG=true
# BACKUP_PVE_ACL=false also excludes the credential files /etc/pve/priv/{shadow,token,tfa}.cfg
-# (password hashes, API token secrets, TFA secrets) from the /etc/pve snapshot. NOTE: those secrets
-# also live inside the cluster database config.db; to exclude them entirely also set BACKUP_CLUSTER_CONFIG=false.
+# from the /etc/pve snapshot. Their secrets remain in config.db; to exclude the database
+# and its sidecars, add config.db* to BACKUP_EXCLUDE_PATTERNS.
BACKUP_PVE_ACL=true # Access control (users/roles/groups/ACL + priv credentials; realms when configured)
BACKUP_PVE_JOBS=true
BACKUP_PVE_SCHEDULES=true
diff --git a/cmd/proxsave/testdata/install_characterization/fresh_enable_all.env b/cmd/proxsave/testdata/install_characterization/fresh_enable_all.env
index 551f6c5b..610bdbc5 100644
--- a/cmd/proxsave/testdata/install_characterization/fresh_enable_all.env
+++ b/cmd/proxsave/testdata/install_characterization/fresh_enable_all.env
@@ -350,15 +350,17 @@ METRICS_PATH=${BASE_DIR}/metrics
# Collector options
# ----------------------------------------------------------------------
# PVE
-# BACKUP_CLUSTER_CONFIG controls both cluster config collection and cluster runtime commands
-# (corosync.conf / pve-cluster data, pvecm status/nodes, and HA status collection).
+# BACKUP_CLUSTER_CONFIG controls Corosync and cluster-specific data/runtime collection.
+# config.db and the base /etc/pve snapshot are collected independently, including on standalone hosts.
+# To exclude config.db and its sidecars, add config.db* to BACKUP_EXCLUDE_PATTERNS.
+# Missing Corosync files do not warn on a confirmed standalone host.
# NOTE: If a feature is enabled but not configured on this node, ProxSave logs a WARNING (exit code 1). Disable unused features via the BACKUP_* flags below.
BACKUP_CLUSTER_CONFIG=true
BACKUP_PVE_FIREWALL=true
BACKUP_VZDUMP_CONFIG=true
# BACKUP_PVE_ACL=false also excludes the credential files /etc/pve/priv/{shadow,token,tfa}.cfg
-# (password hashes, API token secrets, TFA secrets) from the /etc/pve snapshot. NOTE: those secrets
-# also live inside the cluster database config.db; to exclude them entirely also set BACKUP_CLUSTER_CONFIG=false.
+# from the /etc/pve snapshot. Their secrets remain in config.db; to exclude the database
+# and its sidecars, add config.db* to BACKUP_EXCLUDE_PATTERNS.
BACKUP_PVE_ACL=true # Access control (users/roles/groups/ACL + priv credentials; realms when configured)
BACKUP_PVE_JOBS=true
BACKUP_PVE_SCHEDULES=true
diff --git a/docs/BACKUP_GUIDE.md b/docs/BACKUP_GUIDE.md
new file mode 100644
index 00000000..fc00065f
--- /dev/null
+++ b/docs/BACKUP_GUIDE.md
@@ -0,0 +1,142 @@
+# Host configuration backup
+
+Use this guide to understand what ProxSave collects, run your first backup from the dashboard and check the result
+
+- [What ProxSave backs up](#what-proxsave-backs-up)
+- [Run and verify your first backup](#run-and-verify-your-first-backup)
+- [Choose what to collect](#choose-what-to-collect)
+- [How a backup runs](#how-a-backup-runs)
+
+
+
+## What ProxSave backs up
+
+ProxSave backs up the host configuration of Proxmox VE and Proxmox Backup Server. It collects configuration files and recovery information for restoring settings after a reinstall, host failure or hardware replacement
+
+Collection runs on the installed host without requiring the host, VMs or containers to shut down. The collected files describe the system during the run; this is not a single atomic snapshot of every service. A restore is a separate operation that can change configuration and restart affected services
+
+### Configuration coverage
+
+| Area | Saved configuration and recovery information |
+| --- | --- |
+| Proxmox VE | VM and container configuration, storage definitions, jobs, permissions, firewall, HA, SDN, resource mappings and cluster configuration, including `/var/lib/pve-cluster/config.db` |
+| Proxmox Backup Server | Datastore definitions, remotes, jobs, users, access rules, notifications, certificates and server settings |
+| Linux host | Networking, mount configuration, storage stack, services, users, scheduled tasks, SSH material, kernel and boot settings |
+| Additional files | Selected scripts, home-directory content and explicitly configured custom paths, subject to collection settings and exclusions |
+| Recovery information | Inventories, command output and manifests that help inspect the original system |
+
+Coverage depends on the detected host role, available files, enabled collectors and successful collection. On a host with both PVE and PBS installed, ProxSave can collect both roles in one archive with shared Linux configuration
+
+VM disks, container filesystems and PBS datastore contents are outside the normal host-configuration backup. Protect workload data separately. A package inventory does not include installation packages, and an exported inventory is not necessarily something the restore workflow can apply
+
+Custom paths and optional collection of existing PVE backup files can add files beyond the normal scope. They do not turn ProxSave into a VM backup scheduler or an image-based disk recovery tool
+
+### Where backups can go
+
+Archives can be kept locally, copied to mounted secondary storage such as a NAS, or sent through rclone. Native PBS integration stores a snapshot of the collected tree using a configured PVE PBS storage. Read [backup destinations](STORAGE.md#choose-and-verify-backup-destinations) to choose the appropriate format and recovery path
+
+Start with [installation](INSTALL.md#fast-install), then [run and verify a backup](#run-and-verify-your-first-backup). For recovery, use the [restore guide](RESTORE_GUIDE.md#quick-start)
+
+
+
+
+
+## Run and verify your first backup
+
+Before starting, complete installation, confirm the configured destinations are available and keep any decryption keys somewhere you can access after losing the host. A local archive on the same failed disk will not help recover that disk
+
+### Start from the dashboard
+
+1. Open an interactive terminal on the installed host and run `proxsave` without arguments
+2. If release notes appear, read and acknowledge them to reach the dashboard
+3. To review the installation settings, choose **Maintenance > Install > Edit install**. Use the [configuration reference](CONFIGURATION.md#editing-the-configuration-from-the-dashboard) for settings that the form does not expose
+4. Choose **Diagnostic Checks > Post-install** to review the installation checks. These checks are useful preparation; they do not replace a real backup and recovery test
+5. Choose **Backup** in the Backup group. The dashboard displays the run output and its final outcome
+
+Opening the dashboard requires an interactive terminal. Bare `proxsave` starts a backup when those terminal checks fail, and passing command-line options also bypasses the dashboard. See [dashboard behavior](DASHBOARD.md#when-the-dashboard-opens) before using a pipe, a script or a remote session without a terminal
+
+### Check the result
+
+Read the collection summary and warnings before relying on the backup. Investigate missing files or an incomplete product role even when an archive was produced
+
+Check the result for each destination you enabled. A successful local archive does not establish that the NAS, cloud copy or PBS snapshot succeeded. Confirm that the expected archive set or snapshot is accessible using the destination's own browser or management interface
+
+Keep the archive and its associated metadata/checksum files together, or keep the complete bundle when bundling is enabled. Those files describe the backup and are used when discovering and verifying it for recovery. For encrypted backups, confirm that the required private key or passphrase recovery material is available independently of the backed-up host
+
+Open **Daemon > Status** to inspect the active scheduler. If using healthchecks, open **Diagnostic Checks > Healthchecks** and verify the monitoring setup as described in the [monitoring guide](HEALTHCHECKS.md). Receiving a notification does not prove that a future missed backup will be detected
+
+### Verify recovery separately
+
+Before depending on the backup for disaster recovery, test the applicable recovery procedure on a disposable, compatible host. Follow the [restore guide](RESTORE_GUIDE.md#quick-start) and check the recovered settings there. Archive verification is not proof that every setting is suitable for different hardware or that workload data has been recovered
+
+For problems, use [troubleshooting](TROUBLESHOOTING.md#common-issues). Keep diagnostic logs private until you have checked them for sensitive information
+
+
+
+
+
+## Choose what to collect
+
+ProxSave chooses collectors for the detected PVE, PBS or combined host role, then collects common Linux configuration. Collection settings control optional parts of that process. Restore categories are a later selection from the files actually present in the backup
+
+### Adjust the collection settings
+
+Start in **Maintenance > Install > Edit install** for settings exposed by the configuration form. Other collection keys must be edited in the active `backup.env` file using the [configuration reference](CONFIGURATION.md#collector-options). Do not assume that every key has a dashboard control
+
+The pmxcfs database `config.db` is collected on every PVE host, including standalone hosts, independently of `BACKUP_CLUSTER_CONFIG`. That flag controls Corosync and cluster-specific collection. To exclude the database and its sidecars, add `config.db*` to `BACKUP_EXCLUDE_PATTERNS`; this also removes the database recovery artifact.
+
+Review related settings together. For example, disabling a dedicated credential or VM configuration collector does not guarantee that the same information is absent from a larger database or directory snapshot. PVE's `config.db` can still contain access-control secrets when the separate ACL files are excluded
+
+Use encryption and appropriate access controls for archives that contain credentials. Read [encryption](ENCRYPTION.md#encrypt-backups-and-preserve-recovery-keys) before collecting material you do not want stored in plaintext at the destinations
+
+### Include custom files
+
+`CUSTOM_BACKUP_PATHS` adds explicitly selected files or directories. Paths are collected under their corresponding host-relative locations in the archive. Missing paths do not prove a successful copy, so inspect the collection log and the resulting content
+
+Keep the list focused. Broad paths can collect large amounts of application data or secrets that are unrelated to host recovery. User homes and scripts also deserve review for sensitive material
+
+Custom collection does not create a new automatic restore category. A custom file may match an existing category, but arbitrary application paths require separate inspection and a deliberate recovery procedure
+
+### Exclusions and optional inventories
+
+Use the documented blacklist and `BACKUP_EXCLUDE_PATTERNS` behavior to exclude unwanted files. Review the resulting backup instead of assuming that one exclusion removes every equivalent representation of a setting. The [collection exclusions](CONFIGURATION.md#collection-exclusions) and [custom paths](CONFIGURATION.md#custom-paths--blacklist) reference describes their scope
+
+PBS datastore and PVE backup-file inventories provide recovery information. They are distinct from collecting live VM disks or PBS datastore payloads. Enable optional scans only when their results are useful and check their collection time on the actual host
+
+### Verify a changed policy
+
+After changing the collection policy, run **Backup** from the dashboard and inspect the collection warnings, output size and destination results. Retain a known usable backup while validating the new policy. Use a disposable recovery target to check that the settings you need can actually be recovered
+
+
+
+
+
+## How a backup runs
+
+The dashboard and scheduled runs use the same backup workflow. Understanding its stages helps distinguish a collection problem from an archive, destination or notification problem
+
+1. **Load and check the configuration.** ProxSave resolves its configuration, detects the host roles and performs the applicable environment, permission, dependency and destination checks
+2. **Collect files and recovery information.** Role-specific collectors and common Linux collectors write into a temporary working tree. Some collectors record warnings and continue, so the summary matters as much as the presence of an archive
+3. **Prepare the archive.** Configured optimizations run on the collected tree. ProxSave creates the archive with the selected compression and, when configured, AGE encryption
+4. **Verify and finalize the archive set.** The stored archive is checked and its associated metadata is written. A failed archive creation is not treated as a completed archive
+5. **Handle archive destinations.** Local retention and configured secondary/cloud copies are processed, with destination-specific results
+6. **Handle native PBS.** When enabled, the PBS destination sends the collected tree through `proxmox-backup-client` and checks the resulting snapshot. This is a separate format from the AGE archive
+7. **Report the run.** ProxSave records outcomes and attempts the enabled notifications. A notification failure does not undo an already saved backup; notification delivery can still extend the run time
+
+### What the results mean
+
+An archive can contain useful configuration while some requested files were unavailable. A combined PVE/PBS run can preserve one role when collection of the other fails, with the incomplete target recorded. Review these warnings rather than treating every produced archive as complete
+
+Temporary collection includes plaintext, even when the final archive is encrypted. Encryption of the archive or PBS snapshot does not encrypt the host's collection workspace. See [encryption and staging](ENCRYPTION.md#plaintext-staging)
+
+The resident daemon adds scheduling, supervision and health reporting around the backup process. Direct notification delivery and detection of a backup that never started are separate concerns. Use the [daemon guide](DAEMON.md) and [healthchecks guide](HEALTHCHECKS.md) to configure both
+
+### Recovery uses the saved format
+
+For local, secondary and rclone archive sets, choose **Tools > Restore** in the dashboard and follow the [restore workflow](RESTORE_GUIDE.md#quick-start). Native PBS snapshots require the PBS recovery path described in [native PBS backups](STORAGE.md#create-native-pbs-backups). Neither workflow restores VM disk contents that were never part of the backup
+
+
+
+## Implementation references
+
+For contributors, [collector architecture](COLLECTOR_ARCHITECTURE.md) explains recipes and combined-role collection. The backup pipeline lives in [backup_run_phases.go](../internal/orchestrator/backup_run_phases.go), and [block_adapter.go](../internal/orchestrator/block_adapter.go) passes the collected tree to native destination blocks
diff --git a/docs/CLI_REFERENCE.md b/docs/CLI_REFERENCE.md
index 713e9b17..8f289b9b 100644
--- a/docs/CLI_REFERENCE.md
+++ b/docs/CLI_REFERENCE.md
@@ -1,83 +1,8 @@
# Command-Line Reference
-Complete reference for all ProxSave command-line options and flags.
-
-**This page is the automation surface, not the everyday one.** On a normal host you drive
-ProxSave from the interactive dashboard: run `proxsave` with no arguments on a terminal and
-it opens, with installing, configuring, upgrading, running a backup, restoring, the daemon
-and the support report all a keypress away. See [DASHBOARD.md](DASHBOARD.md). Reach for the
-flags below when there is no terminal to open the dashboard on: headless hosts, cron entries,
-provisioning scripts, remote automation, and recovery when the TUI cannot run.
-
-## Table of Contents
-
-- [Dashboard first, flags for automation](#dashboard-first-flags-for-automation)
-- [Overview](#overview)
-- [Interface Modes](#interface-modes)
-- [Basic Operations](#basic-operations)
-- [Installation & Setup](#installation--setup)
-- [Encryption & Decryption](#encryption--decryption)
-- [Restore Operations](#restore-operations)
-- [Logging](#logging)
-- [Support & Diagnostics](#support--diagnostics)
-- [Command Examples](#command-examples)
-- [Scheduling with Cron](#scheduling-with-cron)
-- [Related Documentation](#related-documentation)
-- [Quick Reference](#quick-reference)
-- [Environment Variables](#environment-variables)
-- [Exit Codes](#exit-codes)
+Use the [dashboard](DASHBOARD.md#when-the-dashboard-opens) for normal interactive operation. This reference covers explicit operations, automation, interface fallback and diagnostic invocations.
----
-
-## Dashboard first, flags for automation
-
-`proxsave` with **no arguments at all**, on an interactive terminal, opens the dashboard.
-That is the route to use, and the route to give an operator, unless something prevents it.
-
-The gate is narrow, and knowing why matters as soon as you script ProxSave:
-
-- **No arguments at all.** A single flag is enough to skip the dashboard, including a
- harmless one: `proxsave -c /etc/proxsave/prod.env` runs a backup with that config, it does
- not open the menu.
-- **A real terminal.** stdin and stdout must both be TTYs, and `TERM` must be set and not
- `dumb`. cron, systemd, pipes and `ssh` without a pty all fail this and run the backup
- directly, which is exactly what a scheduler wants.
-
-Most flags on this page have a dashboard row that runs the same code: some rows set the flag
-internally and fall through to the identical flow, the rest call the same function in-session.
-
-| Dashboard menu path | Flag |
-|---------------------|------|
-| Backup | `--backup` |
-| Restore | `--restore` |
-| Decrypt | `--decrypt` |
-| New key | `--newkey` |
-| Install > Edit install | `--install` |
-| Install > Wipe install | `--new-install` |
-| Upgrade > Check upgrade | `--upgrade` |
-| Upgrade > Check config | `--upgrade-config` (its read-only check step is `--upgrade-config-dry-run`) |
-| Daemon > Install | `--daemon-setup` |
-| Daemon > Disable | `--daemon-remove` |
-| Daemon > Status | `--daemon-status` |
-| Cleanup guards | `--cleanup-guards` |
-| Support | `--support` |
-| (opens by itself once per release) | `--show-whatsnew` |
-
-Four dashboard rows have no flag at all. **Telegram**, **Healthchecks** and **Post-install**
-are diagnostic check screens that exist only inside the dashboard, and **Daemon > Restart**
-restarts the running service without changing the scheduler engine, which no flag does.
-Going the other way, `--config`, `--dry-run`, `--log-level` and `--cli`
-are run modifiers with no menu row, and `--daemon` is what `proxsave-daemon.service`
-executes, never something you type.
-
-**Scheduling**: on a fresh install the resident daemon (`proxsave-daemon.service`) is the
-scheduler, and it is the only thing that transmits healthcheck pings; a backup started by
-hand or from the dashboard hands its outcome to the daemon to report. Cron is the
-legacy/opt-out engine, kept for the schedules the daemon cannot express. See
-[DAEMON.md](DAEMON.md), [HEALTHCHECKS.md](HEALTHCHECKS.md) and
-[Scheduling with Cron](#scheduling-with-cron) below.
-
----
+
## Overview
@@ -145,422 +70,143 @@ proxsave --install --cli
---
-## Basic Operations
+## Quick Reference
-### Run Backup
+### All Flags
-An operator at a terminal runs a backup from the dashboard's **Backup** row. The forms below
-are for cron entries, scripts and headless hosts.
+The **Dashboard** column names the menu row that does the same thing at a terminal; a dash
+means the flag has no menu row.
-```bash
-# Run the backup now (explicit; always skips the interactive dashboard)
-proxsave --backup
+| Flag | Short | Dashboard | Description |
+|------|-------|-----------|-------------|
+| `--help` | `-h` | - | Show help message |
+| `--version` | `-v` | - | Display version information |
+| `--config ` | `-c` | - | Path to configuration file. Passing it suppresses the dashboard, like any other flag |
+| `--dry-run` | `-n` | - | Simulate a backup without creating or uploading archives; diagnostic logs are still written. Refused with `--upgrade`, `--upgrade-finalize`, `--daemon`, `--daemon-setup`, `--daemon-remove` and `--restore` |
+| `--log-level ` | `-l` | - | Set log level (debug\|info\|warning\|error\|critical) |
+| `--cli` | - | - | Force CLI mode instead of TUI (only for: --install, --new-install, --newkey, --decrypt, --restore) |
+| `--install` | - | Install > Edit install | Interactive installation wizard |
+| `--new-install` | - | Install > Wipe install | Wipe the install dir, keeping only `build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/`, then run the wizard. Deletes local backups and `configs/backup.env` with stock paths |
+| `--upgrade` | - | Upgrade > Check upgrade | Download and install latest binary from GitHub releases. Executed by the OLD binary; from 0.36.0 on it hands the finalize to the new one |
+| `--upgrade-config` | - | Upgrade > Check config | Upgrade config from embedded template |
+| `--upgrade-config-dry-run` | - | Upgrade > Check config (check step) | Preview config upgrade |
+| `--newkey` | - | New key | Generate new AGE encryption key |
+| `--age-newkey` | - | New key | Alias for `--newkey` |
+| `--decrypt` | - | Decrypt | Decrypt existing backup |
+| `--restore` | - | Restore | Restore from backup to system |
+| `--backup` | - | Backup | Run the backup now and skip the interactive dashboard (default when non-interactive, e.g. cron) |
+| `--daemon` | - | - | Run as the resident backup daemon (installed as `proxsave-daemon.service`; not run by hand) |
+| `--daemon-setup` | - | Daemon > Install | Switch this install to daemon mode (install+enable the service, remove the cron entry) |
+| `--daemon-remove` | - | Daemon > Disable | Revert to the cron scheduler, disable the service, and block future upgrades from reinstalling the daemon |
+| `--daemon-status` | - | Daemon > Status | Read-only daemon and personal-script status; add `--log-level debug` for UID/path evidence. Scripts are not executed; exit is `0` only when the daemon is running and aligned |
+| `--show-whatsnew` | - | (opens by itself) | Show the release-notes screen once and exit, then mark it seen |
+| `--cleanup-guards` | - | Cleanup guards | Remove leftover ProxSave mount guards under `/guards` and the legacy `/var/lib/proxsave/guards` (use with `--dry-run` to preview) |
+| `--support` | - | Support | Run in support mode (force DEBUG logging and email log). Available for the standard backup run and `--restore` |
-# Bare invocation: runs the backup when non-interactive (cron, pipe, systemd),
-# opens the interactive dashboard on an interactive terminal
-proxsave
+### Internal Flags
-# Use custom config file. NOTE: passing any flag, this one included, suppresses the
-# dashboard, so on a terminal these run the backup instead of opening the menu.
-proxsave --config /path/to/config.env
-proxsave -c /path/to/config.env
+These exist so one ProxSave process can drive another. They are documented for completeness
+and for reading a debug log; do not put them in a script of your own.
-# Dry-run mode (test without changes)
-proxsave --dry-run
-proxsave -n
+| Flag | Used by | Description |
+|------|---------|-------------|
+| `--localfile` | `install.sh --upgrade`, `upgrade-beta.sh` | Only with `--upgrade`: skip the release check and the download, and finalize using the binary already on disk, which those scripts have already swapped in themselves. Rejected on its own: `--localfile` without `--upgrade` is an error |
+| `--upgrade-config-json` | `--upgrade` | Upgrade the config and print a JSON summary to stdout |
+| `--upgrade-finalize` | `--upgrade` (installed version 0.36.0 or newer) | Run only the post-install finalize phase (config merge, docs/symlinks, daemon migrate and restart, permissions, footer, release notes) and exit. `--upgrade` re-invokes the freshly installed binary with it, so the finalize policy that runs belongs to the release being installed rather than to the one being replaced. Run by hand it restarts the daemon and prints an upgrade footer for a version nobody installed |
+| `--upgrade-finalize-version ` | `--upgrade-finalize` | The version the caller installed, for the footer the child prints. The child cannot read it from its own build info on the `--localfile` path, where the on-disk binary may predate the tag |
+| `--upgrade-finalize-skip-whatsnew` | `--upgrade-finalize` | Do not open the release-notes screen. `--upgrade` forwards it when nobody is there to close it (`--upgrade y`) or when the dashboard owns the presentation |
+| `--upgrade-finalize-skip-daemon-restart` | `--upgrade-finalize` | Do not restart the resident daemon, because the caller restarts it itself. `--upgrade` forwards this when the dashboard is driving, since the suppression lives in a package variable a child process cannot see. Without it the daemon is restarted twice |
-# Show version
-proxsave --version
-proxsave -v
+## Basic Operations
-# Show help
-proxsave --help
-proxsave -h
-```
+### Run Backup
-### Flag Reference
+```bash
+proxsave --backup
+proxsave --backup --config /path/to/backup.env
+proxsave --dry-run --log-level debug
+```
-| Flag | Short | Description |
-|------|-------|-------------|
-| `--config ` | `-c` | Path to configuration file (default `configs/backup.env`, resolved under the install dir, e.g. `/opt/proxsave/configs/backup.env`). An absolute path is used as-is; a relative path is joined onto the install dir, not the current directory. |
-| `--dry-run` | `-n` | Test mode - no actual changes made. Refused with `--upgrade` and `--upgrade-finalize`: neither has ever honoured it, so the combination is an error rather than a silent full upgrade. Refused with `--daemon`, `--daemon-setup` and `--daemon-remove` for the same reason. Refused with `--restore`, and a restore is refused while `DRY_RUN=true` too: a restore cannot run without modifying the system |
-| `--version` | `-v` | Display version information |
-| `--help` | `-h` | Show help message |
-| `--backup` | | Run the backup now and skip the interactive dashboard. This is the default behavior when proxsave runs non-interactively (cron, pipe, systemd). Dashboard: **Backup**. |
-| `--daemon` | | Run as the resident backup daemon (schedules + supervises runs, reports to healthchecks). Invoked by `proxsave-daemon.service`; not run by hand, and it has no dashboard row for that reason. See [docs/DAEMON.md](DAEMON.md) and [docs/HEALTHCHECKS.md](HEALTHCHECKS.md). |
-| `--daemon-setup` | | Switch this install to daemon mode: install+enable the service and remove the cron entry. Dashboard: **Daemon > Install** (shown while the host is on cron). |
-| `--daemon-remove` | | Revert to the cron scheduler, disable the service, and block future upgrades from reinstalling the daemon. Dashboard: **Daemon > Disable** (shown while the daemon is installed). |
-| `--daemon-status` | | Read-only daemon status (scheduler/service state, version/alignment, and personal pre/post script readiness) and exit. `--log-level debug` adds daemon-UID and path-component evidence without executing scripts. Exit code remains based only on daemon health: `0` when running and aligned, non-zero otherwise. Dashboard: **Daemon > Status** (same screen, no exit code). |
-| `--show-whatsnew` | | Show the release-notes screen once and exit, then mark it seen. `--upgrade` calls it for you on an interactive terminal, but not under `--upgrade y`; run it by hand after an unattended upgrade to stop the "unseen release notes" warning. Dashboard: opens by itself before the first menu, once per release. |
+A relative configuration path is resolved against the installation directory, not the current directory. Any argument bypasses the dashboard. Bare invocation without interactive terminal eligibility also runs the normal backup path.
----
+Dry-run writes diagnostic logs but skips archive creation and upload; it is not a restore preview. `DRY_RUN=true` also refuses restore. See [backup verification](BACKUP_GUIDE.md#run-and-verify-your-first-backup) for the complete operational checks.
## Installation & Setup
### Installation Wizard
-The very first install is the one thing the dashboard cannot do, since there is no binary to
-open it with: bootstrap with the installer one-liner in [INSTALL.md](INSTALL.md). Everything
-after that is a dashboard row: **Install > Edit install** re-runs the wizard, **Install >
-Wipe install** resets first. The flags below are the same two flows for headless hosts and
-provisioning scripts.
-
```bash
-# Interactive installation wizard (TUI mode - default)
proxsave --install
-
-# Interactive installation wizard (CLI mode - for debugging)
proxsave --install --cli
-
-# Clean reinstall: wipes the install dir except build/, daemon_state/, env/, guards/, identity/ and restore/, then runs
-# the wizard. With stock paths that deletes local backup archives and configs/backup.env.
-proxsave --new-install
-
-# Clean reinstall with CLI mode
-proxsave --new-install --cli
```
-**Interface modes**:
-```bash
-# TUI mode (default) - terminal interface
-proxsave --install
-
-# CLI mode - text prompts (for debugging)
-proxsave --install --cli
-```
-
-**Use `--cli` when**: TUI rendering issues occur or advanced debugging is needed.
-
-**Existing configuration**:
-- If the configuration file already exists, **both TUI and CLI** now offer the same choices:
- - **Overwrite** (start from embedded template)
- - **Edit existing** (use current file as base and pre-fill wizard fields)
- - **Keep existing & continue** (leave file untouched and skip configuration wizard)
- - **Cancel** (abort installation)
-- In **Keep existing & continue** mode, config-dependent post-steps are skipped (encryption setup, post-install audit, Telegram pairing), while finalization steps still run (docs install, symlink and scheduler finalization, permissions normalization).
-
-**Wizard workflow**:
-1. Generates/updates the configuration file (`configs/backup.env` by default)
-2. Optionally configures secondary storage (`SECONDARY_PATH` required if enabled; `SECONDARY_LOG_PATH` optional; invalid secondary paths are re-prompted/rejected; disabling secondary storage clears both saved secondary paths)
-3. Optionally configures cloud storage (rclone)
-4. Optionally enables firewall rules collection (`BACKUP_FIREWALL_RULES=false` by default)
-5. Optionally sets up notifications (Telegram, Email; Email asks for a delivery mode and defaults to `EMAIL_DELIVERY_METHOD=relay` with `EMAIL_FALLBACK_SENDMAIL=true`)
-6. Optionally configures encryption (AGE setup)
-7. Selects the schedule: the frequency (daily, weekly or monthly, default daily), the day it uses, and the run time (HH:MM, default `02:00`). On fresh installs the scheduler defaults to the resident daemon; cron is offered as the alternative engine (see [INSTALL.md](INSTALL.md) and [DAEMON.md](DAEMON.md))
-8. Optionally runs a post-install dry-run audit and offers to disable unused collectors (actionable hints like `set BACKUP_*=false to disable`)
-9. (If Telegram centralized mode is enabled and config + Server ID resolve successfully) Shows Server ID and offers pairing verification (retry/skip supported); otherwise install continues and logs why pairing was skipped
-10. Finalizes installation (symlinks, scheduler setup for the chosen engine, permission checks)
-
-**Install log**: The installer writes a session log under `/tmp/proxsave/install-*.log` (includes audit results and Telegram pairing outcome).
+Use [installation](INSTALL.md#fast-install) for bootstrap and wizard behavior. `--new-install` is a destructive reset, preserving only `build`, `daemon_state`, `env`, `guards`, `identity` and `restore`. With stock paths it deletes local archives, logs and `configs/backup.env`. Copy and verify required files independently before invoking it; it is not a migration command.
### Configuration Upgrade
-Dashboard: **Upgrade > Check config** runs the read-only plan below, lists the variables it
-would add, and only offers `Apply` when there is something to add. Both steps call the same
-functions as the two flags here.
-
```bash
-# Upgrade configuration file from embedded template
-proxsave --upgrade-config
-
-# Preview configuration upgrade (dry-run)
proxsave --upgrade-config-dry-run
+proxsave --upgrade-config
```
-**`--upgrade-config` use case**: After installing a new binary version, this command merges your current configuration with the latest embedded template, preserving your values while adding new options.
-
-**Upgrade process**:
-1. Reads current `configs/backup.env`
-2. Extracts embedded template from binary
-3. Merges your values with new template
-4. Backs up old config (`backup.env.backup.YYYYMMDD_HHMMSS`, next to the config file)
-5. Writes updated configuration
-6. Reports added keys, preserved values, and any merge warnings
-
-**Nothing is ever removed from your configuration.** Keys you set that are not in the
-template (including keys that differ from a template key only by upper/lower case) are
-preserved in place with their original value and casing, and are reported as such. The
-upgrade only adds keys the template has and your config lacks.
-
-If the merged configuration fails validation, the backup from step 4 is restored
-automatically and the command reports the error, so a failed upgrade leaves your
-configuration as it was.
-
-> **Keep `backup.env` a regular file.** The config upgrade (`--upgrade`, `--upgrade-config`) writes the new configuration atomically (temp file + rename), so if `configs/backup.env` is a **symlink** it is replaced by a regular file and the symlink target is left unchanged. For a centrally managed configuration, deploy a regular `backup.env` (for example copied or templated by your config-management tool) instead of symlinking it.
+The first invocation reports the merge plan without writing configuration. The second applies it. Supported and custom values are preserved, missing keys are added, and retired keys are removed. Validation failure restores the timestamped config backup. Atomic replacement replaces a symlink itself rather than updating its target. See [merge effects](INSTALL.md#what-gets-updated) for the complete pruning list and scheduler boundaries.
### Binary Upgrade
-At a terminal, upgrade from the dashboard: **Upgrade > Check upgrade** runs the same
-`--upgrade` code in-session, showing the available version and the release notes before you
-commit to it. The flag forms below are for unattended upgrades and headless hosts.
-
```bash
-# Upgrade binary to latest version
proxsave --upgrade
-
-# Non-interactive upgrade (auto-confirm)
proxsave --upgrade y
-
-# Full upgrade including configuration
-proxsave --upgrade
-proxsave --upgrade-config
```
-**`--upgrade` use case**: Update ProxSave binary to the latest version from GitHub releases while preserving your configuration and backup data. The upgrade process is safe and atomic, with checksum verification and automatic permission fixes.
-
-**Which binary executes the upgrade.** `proxsave --upgrade` is run by the binary you already
-have. It is the old binary that fetches the release list, downloads the archive, verifies the
-signature and checksum, and replaces itself, and that cannot move: a freshly downloaded
-binary is untrusted until the installed one has verified it, so it can never be the party
-that verifies itself. A fix to the download-and-verify half therefore only takes effect on
-the upgrade *after* the one that ships it. From 0.36.0 on, the rest of the upgrade (the
-config merge, docs and symlinks, the scheduler reconciliation, permissions, the footer) is
-handed to the binary that was just installed via the internal `--upgrade-finalize`, so that
-half is already the new release's code; the decision to hand it over lives in the old binary,
-so a host coming from a release older than 0.36.0 still finalizes with the old code.
-
-The externally fetched installer is the way around it. It downloads and verifies the release
-itself, swaps the new binary in, and only then runs it with `--upgrade --localfile`, so
-everything after the download is the new release's code:
-
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" -- --upgrade
-```
-
-Use it when the built-in upgrade cannot help itself: the release notes say the upgrade or
-migration logic changed, you are coming from a release older than 0.36.0, or a built-in
-upgrade failed part-way. It installs into `/opt/proxsave` unconditionally (the path is fixed
-in the script) and always installs the latest **stable** release. See
-[INSTALL.md](INSTALL.md) for the full comparison.
-
-**Upgrade workflow**:
-1. Validates configuration file exists
-2. Queries GitHub API for latest release version
-3. Downloads binary archive, SHA256SUMS and SHA256SUMS.sig from GitHub
-4. Creates temporary directory for download
-5. Verifies authenticity first (the `SHA256SUMS.sig` ECDSA signature against the release key pinned in the binary), then archive integrity against that authenticated `SHA256SUMS`. Both are mandatory: an unsigned or mismatched release aborts the upgrade, there is no checksum-only fallback
-6. Extracts binary from tar.gz archive
-7. Atomically replaces current binary (write to .tmp, then rename)
-8. Updates the `proxsave` symlink in `/usr/local/bin/` (and removes the legacy `proxmox-backup` symlink if present)
-9. Upgrades the configuration file (adds any new keys from the template to `backup.env`, preserving your existing and custom values, after backing up the current file) and fixes file permissions. After a successful binary install, the resident daemon (`proxsave-daemon.service`) is installed only on a host that has never recorded a scheduler engine, i.e. one where this upgrade's config merge had to add `SCHEDULER_MODE`; any host that already carries the key keeps the engine it records. The daemon runs at the configured schedule (`SCHEDULER_FREQUENCY`: daily, weekly or monthly, at `SCHEDULER_TIME`, default daily at `02:00`). Where `backup.env` records no schedule yet, the upgrade takes it from the proxsave cron line when that line is daily, weekly or monthly; a cadence the daemon cannot express (hourly, several times a day, a day of the month 29-31) is not adopted and the upgrade warns. Run `--daemon-remove` to stay on cron if you need such a schedule.
-
-**Post-upgrade steps**:
-1. New config template keys are merged into `backup.env` automatically (existing and custom values preserved; previous file backed up)
-2. Run `--upgrade-config` only to re-run that merge without upgrading the binary
-3. Test functionality with dry-run: `proxsave --dry-run`
-4. Verify backups continue to work as expected
-5. Check the scheduler: `proxsave --daemon-status` for daemon installs, or `crontab -l` on cron installs
-
-**Important notes**:
-- **Internet required**: Must be able to reach GitHub releases
-- **Configuration kept current**: `--upgrade` merges new template keys into `backup.env`, preserving your existing and custom values and backing up the previous file first; it never changes or removes values you set
-- **Platform support**: Linux only (amd64)
-- **Incompatible flags**: Cannot use with `--install` or `--new-install`
-- **Automatic maintenance**: Symlinks and permissions are updated automatically. The daemon is installed only on a host that has never recorded a scheduler engine; re-run `--install` to change the run time or engine
-- **Safe replacement**: Old binary is replaced atomically (no backup created)
-- **Standalone config upgrade**: `--upgrade` already merges new template keys; use `--upgrade-config` to run that merge without upgrading the binary
-
-See also: [upgrading configuration](#configuration-upgrade)
-
-### Flag Reference
-
-| Flag | Description |
-|------|-------------|
-| `--install` | Interactive installation wizard. Dashboard: **Install > Edit install** |
-| `--new-install` | Wipe the install directory, keeping only `build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/`, then launch the wizard. With stock paths this deletes your local backup archives and `configs/backup.env`. Dashboard: **Install > Wipe install** |
-| `--upgrade` | Download and install latest ProxSave binary from GitHub releases. Dashboard: **Upgrade > Check upgrade** |
-| `--upgrade-config` | Merge current config with latest template. Dashboard: **Upgrade > Check config**, whose `Apply` runs this |
-| `--upgrade-config-dry-run` | Preview config upgrade without changes. Dashboard: the check step of **Upgrade > Check config**, which runs it before offering `Apply` |
-
-`--upgrade` and `install.sh` drive a second ProxSave process with six more flags
-(`--localfile`, `--upgrade-config-json` and the four `--upgrade-finalize*` ones). They are
-documented once, under [Internal Flags](#internal-flags).
-
----
+Appending `y` auto-confirms and suppresses interactive release notes. The currently installed binary discovers, downloads, verifies and replaces the release; versions from 0.36.0 delegate finalization to the new binary. Configuration merging is included. See [upgrade procedure](INSTALL.md#upgrading-proxsave-binary) for permissions, failure handling, daemon alignment and the external installer fallback. After an unattended upgrade, `proxsave --show-whatsnew` acknowledges unseen notes.
## Encryption & Decryption
-### Generate Encryption Keys
-
-Dashboard: **New key** runs this same flow.
+### Generate AGE Key
```bash
-# Generate new AGE encryption key (TUI mode - default)
proxsave --newkey
-proxsave --age-newkey # Alias
-
-# Generate new AGE encryption key (CLI mode - for debugging)
+proxsave --age-newkey
proxsave --newkey --cli
```
-**Interface modes**:
-```bash
-# TUI mode (default) - terminal interface
-proxsave --newkey
-
-# CLI mode - text prompts (for debugging or when TUI rendering is unavailable)
-proxsave --newkey --cli
-```
-
-**Use `--cli` when**: TUI rendering issues occur or advanced debugging is needed.
-
-**`--newkey` workflow**:
-1. Uses the configured `AGE_RECIPIENT_FILE` when present; otherwise falls back to `${BASE_DIR}/identity/age/recipient.txt`
-2. Prompts for one of:
- - **Existing public recipient**: paste an `age1...` recipient
- - **Passphrase-derived**: enter a passphrase (proxsave derives the recipient; the passphrase is **not stored**)
- - **Private key-derived**: paste an `AGE-SECRET-KEY-...` key (not stored; proxsave stores only the derived public recipient)
-3. Writes/overwrites the recipient file after confirmation
-
-**Note**: Both CLI and TUI `--newkey` flows support adding multiple recipients and de-duplicate repeated entries before saving.
-
-**For complete encryption guide**, see: **[Encryption Guide](ENCRYPTION.md)**
+These invoke the same recipient setup. They support existing recipients, passphrase derivation or deriving the public recipient from a private key, and multiple recipients with deduplication. The setup stores public recipients, not the passphrase or supplied private key. See [encryption setup](ENCRYPTION.md).
### Decrypt Backup
-Dashboard: **Decrypt** runs this same flow.
-
-```bash
-# Decrypt existing backup archive (TUI mode - default)
-proxsave --decrypt
-
-# Decrypt existing backup archive (CLI mode - for debugging)
-proxsave --decrypt --cli
-```
-
-**Interface modes**:
```bash
-# TUI mode (default) - terminal interface
proxsave --decrypt
-
-# CLI mode - text prompts (for debugging)
proxsave --decrypt --cli
```
-**Use `--cli` when**: TUI rendering issues occur or advanced debugging is needed.
-
-**`--decrypt` workflow**:
-1. Scans configured storage locations (local/secondary/cloud)
-2. Lists available backups with metadata
-3. Prompts for destination folder (default `./decrypt`)
-4. Requests passphrase or AGE private key (`AGE-SECRET-KEY-...`)
-5. Decrypts backup to temporary location
-6. Creates a decrypted bundle and moves it to the destination directory
-
-**Output**: Decrypted bundle (e.g., `pve01-backup-20240115-023000.tar.xz.decrypted.bundle.tar`)
-
-### Flag Reference
-
-| Flag | Alias | Description |
-|------|-------|-------------|
-| `--newkey` | `--age-newkey` | Generate new AGE encryption key. Dashboard: **New key** |
-| `--decrypt` | - | Decrypt existing backup archive. Dashboard: **Decrypt** |
-
----
+This interactive selector uses configured local, secondary or cloud sources. Its output is a plaintext bundle, not necessarily the inner compressed archive. Inspect the outer bundle before choosing an inner archive. See [decryption](ENCRYPTION.md#decrypting-backups) for the complete procedure and plaintext handling.
## Restore Operations
### Restore from Backup
-Dashboard: **Restore** runs this same workflow. The flag is what you use on a host recovered
-far enough to run the binary but not to paint a TUI, or when the restore is driven from a
-script.
-
```bash
-# Restore data from backup to system (TUI mode - default)
proxsave --restore
-
-# Restore data from backup to system (CLI mode - for debugging)
proxsave --restore --cli
```
-**Interface modes**:
-```bash
-# TUI mode (default) - terminal interface
-proxsave --restore
-
-# CLI mode - text prompts (for debugging)
-proxsave --restore --cli
-```
-
-**Use `--cli` when**: TUI rendering issues occur or advanced debugging is needed.
-**Note**: CLI and TUI run the same workflow logic; `--cli` only changes the interface (prompts/progress rendering), not the restore/decrypt behavior.
-
-**`--restore` workflow** (16 phases):
-1. Scans configured storage locations (local/secondary/cloud)
-2. Lists available backups with metadata (encrypted or unencrypted)
-3. If encrypted, prompts for decryption key/passphrase and decrypts
-4. Detects the current host role (`pve`, `pbs`, `dual`, or `unknown`)
-5. Validates compatibility using capability overlap and backup targets
- - exact match: proceed normally
- - partial match: continue with warning, then filter categories automatically
- - no overlap: warn strongly before continuing
-6. Analyzes backup categories
-7. Presents restore mode selection:
- - **Full Restore**: all compatible categories
- - **Storage Restore**: storage/datastore-focused categories
- - **Base System Restore**: network, SSH, system files
- - **Custom Restore**: select specific categories
-8. For cluster backups: prompts for **SAFE** (export+API) or **RECOVERY** (full restore) mode
-9. Shows detailed restore plan with selected categories
-10. Requires confirmation: type `RESTORE` to proceed
-11. Creates safety backup of existing files
-12. Stops services if needed (PVE: pve-cluster, pvedaemon, pveproxy, pvestatd; PBS: proxmox-backup-proxy, proxmox-backup)
-13. Extracts selected categories to system root (`/`)
-14. Exports export-only categories to separate directory
-15. For SAFE cluster mode: offers to apply configs via `pvesh` API
-16. Recreates storage/datastore directories, checks ZFS pools, restarts services, and displays completion summary
-
-**Compatibility model**:
-- `dual` backups persist explicit targets (`pve`, `pbs`)
-- restoring a `dual` backup to a single-role host is allowed
-- ProxSave restores only categories compatible with the current host role; on a
- single-role host the categories of the other role are extracted to the export
- directory instead, in every restore mode
-- `common` categories remain available across roles
-
-**WARNING**: Restore operations overwrite files in-place. **Always test in a VM or snapshot your system first!**
-
-**For complete restore workflows**, see:
-- **[Restore Guide](RESTORE_GUIDE.md)** - Complete user guide with all restore modes
-- **[Restore Technical](RESTORE_TECHNICAL.md)** - Technical implementation details
-- **[Cluster Recovery](CLUSTER_RECOVERY.md)** - Disaster recovery procedures
-
-### Flag Reference
-
-| Flag | Description |
-|------|-------------|
-| `--restore` | Run interactive restore workflow (select bundle, decrypt if needed, apply to system). Dashboard: **Restore** |
-| `--cleanup-guards` | Cleanup ProxSave mount guards under `/guards`, and those older versions left in `/var/lib/proxsave/guards` (useful after restores with offline mountpoints; use with `--dry-run` to preview). Dashboard: **Cleanup guards**, which previews first and only then offers `Apply` |
-
----
+Both run the same interactive restore logic. The flag does not imply unattended confirmation. Restore overwrites selected system files and has no dry-run mode; test on a disposable host and review the plan before confirming. Mode, category compatibility, export-only behavior and cluster SAFE/RECOVERY are separate choices. Use the [restore guide](RESTORE_GUIDE.md) and [cluster recovery guide](CLUSTER_RECOVERY.md) for their prerequisites and scoped safety rules.
### Cleanup Mount Guards (Optional)
-During some restores (notably PBS datastores and PVE network storages on mountpoints under `/mnt`), ProxSave may apply a **read-only bind-mount guard** over a mountpoint to prevent accidental writes to `/` when the underlying storage is offline/not mounted yet. If the bind mount cannot be created, ProxSave logs a warning and proceeds unguarded, and no longer sets a persistent `chattr +i` immutable flag (older versions did; that flag survived reboots and could silently re-block the mountpoint when the storage was later unmounted).
-
-`--cleanup-guards` unmounts bind-mount guards **and** clears any **legacy** `chattr +i` immutable flags left by older versions. For safety it only acts on mountpoints that are **not currently mounted** (a real mount on top shadows the guard; clearing it then would touch the wrong inode), prints a summary (unmounted / hidden-remaining / immutable-cleared / immutable-pending), and keeps the guard directory until nothing is pending.
-
-Dashboard: **Cleanup guards** does both steps in one screen, running the read-only check
-first and offering `Apply` only when guards are found. It calls the same routine as the flag.
-
```bash
-# Preview (no changes)
proxsave --cleanup-guards --dry-run --log-level debug
-
-# Apply cleanup (requires root)
proxsave --cleanup-guards
```
-Notes:
-- Bringing the storage back online is enough to *use* it again (a real mount stacks on top of the guard automatically); `--cleanup-guards` just removes the leftover guard. A bind-mount guard also clears on reboot. A legacy `chattr +i` flag does **not** clear on reboot; it persists until cleared.
-- To clear a legacy flag while the storage is mounted: unmount it, run `--cleanup-guards` again (or `chattr -i `), then remount.
-- If you deleted the guard directory (`/guards`, or `/var/lib/proxsave/guards` from an older version) manually and a mountpoint is still read-only, ProxSave has no record left: check `lsattr -d ` and run `chattr -i ` while the storage is unmounted.
+Preview first; applying cleanup requires root. Cleanup removes recorded bind-mount guards and legacy immutable flags only where the actual storage is not mounted. A live storage mount can hide the guard; unmount it safely and retry. Exit `17` means guards remain or the remaining count could not be confirmed. A bind guard clears on reboot, while a legacy immutable flag persists. See [restore guidance](RESTORE_GUIDE.md) before changing storage mount state.
## Logging
### Set Log Level
+`proxsave --log-level debug` bypasses the dashboard and runs the normal backup path with debug logging, subject to configuration and runtime checks. It does not open a debug dashboard. Add `--dry-run` when you need diagnostic simulation rather than a real backup.
+
```bash
# Set log level
proxsave --log-level debug
@@ -579,7 +225,7 @@ proxsave -l info # debug|info|warning|error|critical
**Log output**:
- **Console**: Colored output (if `USE_COLOR=true`)
-- **File**: `LOG_PATH/backup-$(hostname)-YYYYMMDD-HHMMSS.log`
+- **File**: `LOG_PATH/backup--YYYYMMDD-HHMMSS.log`
The level threshold mutes the **console only** for warnings and above: a warning or
error raised below the chosen level is still counted (footer, exit code) and still
@@ -609,341 +255,58 @@ Some log lines use a label to make the output easier to scan:
### Flag Reference
-| Flag | Short | Description |
-|------|-------|-------------|
-| `--log-level ` | `-l` | Set log level: debug\|info\|warning\|error\|critical |
+The complete flag table is maintained under [All Flags](#all-flags).
---
## Support & Diagnostics
-### Support Mode
-
-Dashboard: **Support** collects the consent and the GitHub metadata in a form and then runs
-the same support backup, streamed in the frame. The flag is the headless equivalent, which
-asks for the same two answers on stdin.
-
```bash
-# Run in support mode: force DEBUG logging and send log to developer
proxsave --support
+proxsave --restore --support
+proxsave --daemon-status --log-level debug
```
-**Support mode workflow**:
-1. Displays consent notice about log sharing
-2. Requests GitHub username
-3. Requests GitHub issue number
-4. Runs backup with **forced DEBUG logging** (overrides config)
-5. Collects complete log file
-6. Emails the log to the maintainer address baked into the build, with the GitHub username and issue number in the subject
-7. Returns log file path for user review
-
-**Requirements**:
-- Existing GitHub issue for tracking
-- A build with the maintainer recipient compiled in (`EMAIL_SUPPORT`). The recipient is injected at build time, not hardcoded; a build without it (for example a local dev build) skips the email and logs a warning.
-- Working local mail delivery on the node (`/usr/sbin/sendmail` via Postfix/Exim/Sendmail). Support mode always hands the email to the local MTA; it does not use the notification relay.
-
-**Privacy considerations**:
-- Logs may contain sensitive information (paths, hostnames, file names)
-- Credentials and keys are **never logged**
-- Review log file before submitting if concerned
-
-**When to use**:
-- Persistent errors that need developer investigation
-- Complex configuration issues
-- Unexpected behavior requiring detailed diagnostics
-
-### Flag Reference
-
-| Flag | Description |
-|------|-------------|
-| `--support` | Run in support mode (force DEBUG logging and email log to developer). Available for the standard backup run and `--restore`. Dashboard: **Support** |
+Support mode forces debug logging and asks for the GitHub nickname, existing issue number and consent. Once consent is given, it sends the run log automatically at completion; there is no final review screen. A compiled maintainer recipient and working local sendmail are required. It does not use the normal notification relay. Registered secrets are redacted, but arbitrary diagnostics can still contain sensitive information. To review before sharing, use debug logging without support mode and submit only the reviewed log. See [support preparation](TROUBLESHOOTING.md).
### Diagnostics with no flag
-Three checks exist only inside the dashboard and have no command-line equivalent:
-**Telegram** (verify the relay pairing), **Healthchecks** (verify monitoring and show the
-portal details) and **Post-install** (re-run the post-install audit). If you need them on a
-headless host, open the dashboard over an interactive SSH session; there is no flag that
-runs them. `--daemon-status` is the one diagnostic that does have a flag, and it is the one
-built to be read by a script.
-
----
+Telegram pairing, Healthchecks verification and Post-install checks are dashboard screens. Daemon Restart also has no dedicated flag; the external service command is `systemctl restart proxsave-daemon.service`. Daemon status inspects personal-script readiness without executing scripts. Debug adds UID and path evidence; its exit verdict remains daemon health and binary alignment.
## Command Examples
-These are the scripted forms. Most of them are a dashboard row at a terminal; see
-[Dashboard first, flags for automation](#dashboard-first-flags-for-automation) for the
-mapping.
-
-### Standard Operations
-
```bash
-# Run a backup now (bare `proxsave` opens the dashboard on a TTY)
-proxsave --backup
+# Explicit backup with a separate profile
+proxsave --backup -c /etc/proxsave/production.env
-# Dry-run with debug logging
-proxsave --dry-run --log-level debug
-
-# Use custom config
-proxsave -c /etc/proxmox-backup/prod.env
-
-# Generate encryption keys
-proxsave --newkey
+# Diagnostic simulation, still writes logs
+proxsave --dry-run -l debug
-# Decrypt specific backup
-proxsave --decrypt
-# ... follow interactive prompts ...
+# Normal backup path with debug output, bypasses the dashboard
+proxsave --log-level debug
-# Full restore (DANGEROUS - test in VM first!)
-proxsave --restore
-# ... type RESTORE to confirm ...
+# Read-only daemon status
+proxsave --daemon-status
```
-### Installation & Setup
+### Separate collection profile on a disposable host
-```bash
-# Re-run the install wizard against the current configuration
-proxsave --install
-
-# Full reset + installation (preserves build/daemon_state/env/guards/identity/restore)
-proxsave --new-install
-
-# Upgrade binary to latest release
-proxsave --upgrade
-
-# Upgrade configuration after binary update
-proxsave --upgrade-config
-
-# Preview upgrade changes
-proxsave --upgrade-config-dry-run
-
-# Full upgrade workflow (binary + config)
-proxsave --upgrade
-proxsave --upgrade-config
-proxsave --dry-run # Verify everything works
-```
-
-### Troubleshooting
+A fixture or mounted-root profile is not a sandbox. `SYSTEM_ROOT_PREFIX` affects collection only and is not an environment override. Use the separate configuration and isolation prerequisites in [the disposable-host example](EXAMPLES.md#example-9-test-in-a-chrootfixture): independent backup/log/lock paths and disabled external destinations and notifications. Run only on a disposable compatible host.
```bash
-# Test configuration without running backup
-proxsave --dry-run
-
-# Debug mode with extreme verbosity
-DEBUG_LEVEL=extreme proxsave --log-level debug
-
-# Test encryption setup
-proxsave --newkey
-
-# Verify backup integrity
-proxsave --decrypt --log-level debug
-
-# Support mode for developer assistance
-proxsave --support
+proxsave -c /opt/proxsave/configs/snapshot.env --dry-run --log-level debug
+proxsave -c /opt/proxsave/configs/snapshot.env --backup
```
----
+Review the diagnostic log before the second invocation. Both bypass the dashboard; the second creates a real backup under that profile. Neither redirects upgrade, restore, security checks or service management into the fixture root.
## Scheduling with Cron
-**Cron is the opt-out engine, not the recommended one.** The resident daemon is what a fresh
-install schedules with, and it is the only thing that transmits healthcheck pings: on a cron
-host, monitoring stays silent (see [HEALTHCHECKS.md](HEALTHCHECKS.md)). Put a host back on
-the daemon from the dashboard's **Daemon > Install** row, or with `--daemon-setup`. The rest
-of this section is for the hosts that stay on cron because they need a cadence the daemon
-cannot express.
-
-> On fresh installs ProxSave schedules backups through the **resident daemon** (`proxsave-daemon.service`) by default; see [DAEMON.md](DAEMON.md). The daemon runs daily, weekly or monthly, so a schedule below that it cannot express (hourly, every 6 hours, several times a day) requires the daemon-less **cron** engine. Do not add a cron entry while the daemon is active, or the backup runs twice.
->
-> **ProxSave owns your crontab, so a hand-written schedule does not survive.** `--install`, `--new-install` and `--daemon-remove` each rewrite it: they delete **every** cron line whose command is named `proxsave` or `proxmox-backup`, not only the one they wrote themselves, and append a single entry at the configured schedule (`SCHEDULER_FREQUENCY`, the day it uses and `SCHEDULER_TIME`). The deletion happens in both scheduler modes; whether the appended line stays depends on where the run ends. `--daemon-remove` ends on cron, so it keeps it. `--install` and `--new-install` write that line first and then, when the selected (or already configured) mode is `daemon`, drop it again while enabling the unit, so a daemon installation ends with no proxsave cron entry, unless the unit install itself fails and the host stays on cron with the line it just wrote. A custom cadence from this section is therefore silently replaced by the configured schedule on a cron reinstall, and removed outright by a daemon one. `--upgrade` is the exception: it only repoints legacy paths and leaves the schedule alone.
->
-> The practical order is: run `proxsave --daemon-remove` first, which switches to cron, writes the line for you, and records `SCHEDULER_MODE=cron`, **then** edit that line to the cadence you want. Adding a second entry afterwards leaves two, and both will fire.
->
-> That record is also what makes the line survive. `--upgrade` installs the daemon only on a host that has never recorded a scheduler engine, i.e. one where the upgrade's own config merge had to add `SCHEDULER_MODE`. Any host whose `backup.env` already carries the key is left as it is, so a hand-edited cadence on a 0.30 or later install survives every upgrade. `--daemon-setup` still removes it, because there you asked for the daemon.
-
-### Cron Setup
-
-Write the entry the way ProxSave writes its own, ` /usr/local/bin/proxsave
---backup`: every install and upgrade repoints that symlink at the current binary, and
-`--backup` pins the non-interactive behaviour, so the run can never land on the dashboard
-even if something in the chain allocates a pty.
-
-```bash
-# Edit crontab
-crontab -e
-
-# Daily backup at 2 AM
-0 2 * * * /usr/local/bin/proxsave --backup >> /var/log/pbs-backup.log 2>&1
-
-# Hourly backup
-0 * * * * /usr/local/bin/proxsave --backup
-
-# Weekly backup (Sunday 3 AM)
-0 3 * * 0 /usr/local/bin/proxsave --backup
-```
-
-### Cron Cadences
-
-| Frequency | Cron Expression | Use Case |
-|-----------|----------------|----------|
-| **Hourly** | `0 * * * *` | High-change environments, critical systems |
-| **Every 6 hours** | `0 */6 * * *` | Moderate-change environments |
-| **Daily (2 AM)** | `0 2 * * *` | Standard production; this is the one cadence the daemon already covers, so prefer the daemon for it |
-| **Daily (off-hours)** | `0 22 * * *` | After business hours |
-| **Weekly** | `0 3 * * 0` | Low-change environments, archival |
-
-### Advanced Cron Patterns
-
-```bash
-# Weekday backups only (Mon-Fri, 2 AM)
-0 2 * * 1-5 /usr/local/bin/proxsave --backup
-
-# Multiple daily backups (8 AM, 2 PM, 10 PM)
-0 8,14,22 * * * /usr/local/bin/proxsave --backup
-
-# First day of month (monthly report)
-0 3 1 * * /usr/local/bin/proxsave --backup --log-level info
-
-# With custom config
-0 2 * * * /usr/local/bin/proxsave --backup -c /etc/pbs-prod.env
-```
-
-### Logging Best Practices
-
-```bash
-# Separate cron log file
-0 2 * * * /usr/local/bin/proxsave --backup >> /var/log/pbs-cron.log 2>&1
-
-# Rotate logs (logrotate config)
-# /etc/logrotate.d/proxsave
-/var/log/pbs-cron.log {
- daily
- rotate 7
- compress
- missingok
- notifempty
-}
-```
-
----
+Scheduler installation, ownership and custom-cadence rules are maintained in the [scheduler guide](DAEMON.md). Do not add cron backups while the daemon is active. The explicit command used in an external schedule is `/usr/local/bin/proxsave --backup`; install/reinstall and daemon removal can replace recognized ProxSave cron entries with the configured schedule. Review ownership before editing a custom cadence.
## Related Documentation
-### The everyday interface
-- **[Dashboard](DASHBOARD.md)** - The interactive menu these flags mirror
-- **[Resident daemon](DAEMON.md)** - The default scheduler, and how to move a host on or off it
-- **[Installation](INSTALL.md)** - Bootstrap install and the two upgrade paths
-
-### Configuration
-- **[Configuration Guide](CONFIGURATION.md)** - Complete variable reference
-
-### Operations
-- **[Encryption Guide](ENCRYPTION.md)** - AGE encryption setup and usage
-- **[Restore Guide](RESTORE_GUIDE.md)** - Complete restore workflows
-- **[Cloud Storage Guide](CLOUD_STORAGE.md)** - rclone integration
-
-### Reference
-- **[Examples](EXAMPLES.md)** - Real-world usage examples
-- **[Troubleshooting](TROUBLESHOOTING.md)** - Common issues and solutions
-- **[Developer Guide](DEVELOPER_GUIDE.md)** - Contributing and development
-
-### Main Documentation
-- **[README](../README.md)** - Project overview and quick start
-
----
-
-## Quick Reference
-
-### All Flags
-
-The **Dashboard** column names the menu row that does the same thing at a terminal; a dash
-means the flag has no menu row.
-
-| Flag | Short | Dashboard | Description |
-|------|-------|-----------|-------------|
-| `--help` | `-h` | - | Show help message |
-| `--version` | `-v` | - | Display version information |
-| `--config ` | `-c` | - | Path to configuration file. Passing it suppresses the dashboard, like any other flag |
-| `--dry-run` | `-n` | - | Test mode - no actual changes. Refused with `--upgrade`, `--upgrade-finalize`, `--daemon`, `--daemon-setup`, `--daemon-remove` and `--restore` |
-| `--log-level ` | `-l` | - | Set log level (debug\|info\|warning\|error\|critical) |
-| `--cli` | - | - | Force CLI mode instead of TUI (only for: --install, --new-install, --newkey, --decrypt, --restore) |
-| `--install` | - | Install > Edit install | Interactive installation wizard |
-| `--new-install` | - | Install > Wipe install | Wipe the install dir, keeping only `build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/`, then run the wizard. Deletes local backups and `configs/backup.env` with stock paths |
-| `--upgrade` | - | Upgrade > Check upgrade | Download and install latest binary from GitHub releases. Executed by the OLD binary; from 0.36.0 on it hands the finalize to the new one |
-| `--upgrade-config` | - | Upgrade > Check config | Upgrade config from embedded template |
-| `--upgrade-config-dry-run` | - | Upgrade > Check config (check step) | Preview config upgrade |
-| `--newkey` | - | New key | Generate new AGE encryption key |
-| `--age-newkey` | - | New key | Alias for `--newkey` |
-| `--decrypt` | - | Decrypt | Decrypt existing backup |
-| `--restore` | - | Restore | Restore from backup to system |
-| `--backup` | - | Backup | Run the backup now and skip the interactive dashboard (default when non-interactive, e.g. cron) |
-| `--daemon` | - | - | Run as the resident backup daemon (installed as `proxsave-daemon.service`; not run by hand) |
-| `--daemon-setup` | - | Daemon > Install | Switch this install to daemon mode (install+enable the service, remove the cron entry) |
-| `--daemon-remove` | - | Daemon > Disable | Revert to the cron scheduler, disable the service, and block future upgrades from reinstalling the daemon |
-| `--daemon-status` | - | Daemon > Status | Read-only daemon and personal-script status; add `--log-level debug` for UID/path evidence. Scripts are not executed; exit is `0` only when the daemon is running and aligned |
-| `--show-whatsnew` | - | (opens by itself) | Show the release-notes screen once and exit, then mark it seen |
-| `--cleanup-guards` | - | Cleanup guards | Remove leftover ProxSave mount guards under `/guards` and the legacy `/var/lib/proxsave/guards` (use with `--dry-run` to preview) |
-| `--support` | - | Support | Run in support mode (force DEBUG logging and email log). Available for the standard backup run and `--restore` |
-
-### Internal Flags
-
-These exist so one ProxSave process can drive another. They are documented for completeness
-and for reading a debug log; do not put them in a script of your own.
-
-| Flag | Used by | Description |
-|------|---------|-------------|
-| `--localfile` | `install.sh --upgrade`, `upgrade-beta.sh` | Only with `--upgrade`: skip the release check and the download, and finalize using the binary already on disk, which those scripts have already swapped in themselves. Rejected on its own: `--localfile` without `--upgrade` is an error |
-| `--upgrade-config-json` | `--upgrade` | Upgrade the config and print a JSON summary to stdout |
-| `--upgrade-finalize` | `--upgrade` (installed version 0.36.0 or newer) | Run only the post-install finalize phase (config merge, docs/symlinks, daemon migrate and restart, permissions, footer, release notes) and exit. `--upgrade` re-invokes the freshly installed binary with it, so the finalize policy that runs belongs to the release being installed rather than to the one being replaced. Run by hand it restarts the daemon and prints an upgrade footer for a version nobody installed |
-| `--upgrade-finalize-version ` | `--upgrade-finalize` | The version the caller installed, for the footer the child prints. The child cannot read it from its own build info on the `--localfile` path, where the on-disk binary may predate the tag |
-| `--upgrade-finalize-skip-whatsnew` | `--upgrade-finalize` | Do not open the release-notes screen. `--upgrade` forwards it when nobody is there to close it (`--upgrade y`) or when the dashboard owns the presentation |
-| `--upgrade-finalize-skip-daemon-restart` | `--upgrade-finalize` | Do not restart the resident daemon, because the caller restarts it itself. `--upgrade` forwards this when the dashboard is driving, since the suppression lives in a package variable a child process cannot see. Without it the daemon is restarted twice |
-
-### Common Command Patterns
-
-For scripts, cron and headless hosts. At a terminal, `proxsave` with no arguments opens the
-dashboard and every pattern here except the modifiers is a row on it.
-
-```bash
-# Run a backup now (bare `proxsave` opens the dashboard on a TTY)
-proxsave --backup
-
-# Test before running
-proxsave --dry-run --log-level debug
-
-# Re-run the install wizard
-proxsave --install
-
-# Full reset (preserve build/daemon_state/env/guards/identity/restore) then setup
-proxsave --new-install
-
-# Upgrade binary to latest version
-proxsave --upgrade
-
-# After binary upgrade, optionally update config
-proxsave --upgrade-config
-
-# Use CLI mode instead of TUI (for debugging)
-proxsave --install --cli
-proxsave --new-install --cli
-proxsave --newkey --cli
-proxsave --decrypt --cli
-proxsave --restore --cli
-
-# Encryption workflow
-proxsave --newkey # Generate keys
-proxsave --backup # Run encrypted backup
-proxsave --decrypt # Decrypt when needed
-
-# Restore workflow (test in VM first!)
-proxsave --restore
-
-# Troubleshooting
-proxsave --dry-run --log-level debug
-proxsave --support
-```
-
----
+Use [configuration](CONFIGURATION.md#editing-the-configuration-from-the-dashboard) for key definitions, [dashboard navigation](DASHBOARD.md#the-menu) for interactive actions and [troubleshooting](TROUBLESHOOTING.md) for failure diagnosis.
## Environment Variables
@@ -964,7 +327,7 @@ proxsave -c /etc/pbs/prod.env
# Dry-run mode: overridden via this environment variable
# (a restore is refused while DRY_RUN is true, from the environment or from backup.env)
-DRY_RUN=true proxsave
+DRY_RUN=true proxsave --backup
# BASE_DIR is not an override; it is detected from the installed executable.
# BASE_DIR in the environment or backup.env is deprecated and ignored.
@@ -976,9 +339,11 @@ DRY_RUN=true proxsave
DEBUG_LEVEL=extreme proxsave --log-level debug
# Disable colors
-USE_COLOR=false proxsave
+USE_COLOR=false proxsave --backup
```
+The examples use an explicit operation because environment assignments alone do not suppress the dashboard.
+
**Priority**: for a key on the allowlist, environment variable > configuration file > default. One exception: if the file still carries the **legacy alias** of that key (see Legacy key names in [CONFIGURATION.md](CONFIGURATION.md)), the legacy line in the file wins over the environment, because the allowlist only carries the canonical name. For every other key the environment is not consulted at all. `BASE_DIR` is always runtime-detected and is not overridable from either place.
---
@@ -1027,3 +392,5 @@ same hosts. Filter on the code, not on the log level.
**Note**: Cloud storage is non-critical. A cloud upload failure does **not** abort the
run with a storage error (`5`): the local backup is kept, but the failure is recorded as a
warning, so the run finishes with a non-zero exit code (`1`, generic error), not `0`.
+
+
diff --git a/docs/CLOUD_STORAGE.md b/docs/CLOUD_STORAGE.md
index 032db59f..2e856dcd 100644
--- a/docs/CLOUD_STORAGE.md
+++ b/docs/CLOUD_STORAGE.md
@@ -1,38 +1,209 @@
# Cloud Storage with rclone
-Complete guide to configuring rclone for cloud backup storage.
-
-## Table of Contents
-
-- [Overview](#overview)
-- [Architecture](#architecture)
-- [Prerequisites](#prerequisites)
-- [Supported Cloud Providers](#supported-cloud-providers)
-- [Configuring rclone](#configuring-rclone)
-- [Securing Configuration](#securing-configuration)
-- [Configure proxsave](#configure-proxsave)
-- [Performance Tuning](#performance-tuning)
-- [Testing](#testing)
-- [Troubleshooting](#troubleshooting)
-- [Disaster Recovery](#disaster-recovery)
-- [Related Documentation](#related-documentation)
+
----
+## Set up and recover cloud backups
-## Overview
+Cloud storage copies ProxSave's configuration archives through rclone. It is an
+additional recovery destination, not a VM or container backup service. Keep remote
+credentials and AGE recovery material independently of the protected node. A credential
+copy inside the same remote cannot be the only way to regain access to that remote.
-Proxsave integrates with [rclone](https://rclone.org/) to provide seamless cloud backup storage across 40+ cloud providers. Cloud storage serves as a **non-critical tertiary backup layer** for long-term archival and disaster recovery.
+### Prepare the remote
-**Key capabilities**:
-- **Multi-provider support**: Google Drive, S3, Backblaze B2, OneDrive, MinIO, and 40+ more
-- **Non-critical uploads**: the local backup is written first and an upload failure never fails the run. The upload itself is synchronous and inside the run, so it does add to the total duration. Under the resident daemon that duration is bounded: the upload counts against `MAX_RUN_DURATION` (default `1h`), after which the child is killed and the run is reported as a hang. Size that key, not just the schedule
-- **Automatic retry logic**: Configurable retry attempts with exponential backoff
-- **Bandwidth management**: Upload rate limiting for shared networks
-- **Parallel/sequential modes**: Optimize for network speed and API limits
-- **GFS retention**: Advanced retention policies applied to cloud backups
-- **Verification**: size check plus SHA256 checksum comparison after upload (falls back to size-only on backends without a native SHA256)
+Install rclone on the backup host and configure it under the account that runs
+ProxSave, normally root. Provider account creation, authentication and any provider
+cold-storage retrieval happen outside the dashboard.
----
+```bash
+rclone version
+rclone config
+rclone listremotes
+rclone config file
+```
+
+The configuration wizard creates a named remote such as `gdrive` or `s3backup`.
+Use your provider's storage type, permissions and authentication requirements. Keep
+the resulting configuration private, normally mode `0600`, and check its parent
+directory permissions. See [provider examples](#configuring-rclone) and
+[credential protection](#securing-configuration) for the detailed reference.
+
+Verify access to the intended directory, substituting your actual remote and path:
+
+```bash
+rclone lsf 'gdrive:proxsave/node1/backup'
+```
+
+A successful listing proves read/list access, not upload and deletion access. A
+restricted token may need a write test instead; see [restricted token issues](#restricted-api-token-issues).
+Use a dedicated prefix for each host. Retention scans recursively and limits deletion
+by backup ownership, but separate prefixes also keep listings and recovery choices clear.
+
+### Connect ProxSave to the remote
+
+Run `proxsave` without arguments on an interactive terminal and choose
+**Maintenance** > **Install** > **Edit install**. Enable `Cloud backups (rclone)`,
+then fill `Rclone backup remote` and `Rclone log remote`.
+The wizard requires both text fields while enabled. It does not configure rclone
+itself. Turning the toggle off blanks both keys.
+
+Advanced paths, retention and upload settings require a hand edit of the active
+`configs/backup.env`. A straightforward example is:
+
+```bash
+CLOUD_ENABLED=true
+CLOUD_REMOTE=gdrive
+CLOUD_REMOTE_PATH=proxsave/node1/backup
+CLOUD_LOG_PATH=proxsave/node1/log
+```
+
+`CLOUD_REMOTE` identifies the remote name. `CLOUD_REMOTE_PATH` supplies the path inside
+it. The shorthand `CLOUD_REMOTE=gdrive:proxsave/node1/backup` also works with an empty
+path setting. A base path in `CLOUD_REMOTE` and another in `CLOUD_REMOTE_PATH` are
+combined, so review both before running. `CLOUD_LOG_PATH` can be a path on the same
+remote or an explicit `otherremote:path`; blanking it by hand disables cloud log upload.
+A blank log path is valid at runtime even though the wizard requires one.
+
+See [remote path formats](#recommended-remote-path-formats-important) for examples and
+the [configuration reference](#configuration-reference) for all supported tuning keys.
+Choose [retention](STORAGE.md#set-backup-retention) deliberately before storing backups.
+
+### Verify a saved backup
+
+Choose **Backup** in the dashboard. Check remote initialization, upload and verification
+results. A dry run checks accessibility and skips storage dispatch; it cannot prove
+that an archive was uploaded. Automation and dry-run flags belong in
+[CLI_REFERENCE.md](CLI_REFERENCE.md).
+
+List the remote after the run and confirm the exact named artifact exists. With default
+bundling there is one `.bundle.tar` per backup. With bundling disabled retain the
+archive and its matching metadata, manifest and checksum files as a complete set.
+If log upload is configured, check its separate path too.
+
+Choose **Tools** > **Decrypt** for an encrypted archive inspection test or **Tools** >
+**Restore** to select the cloud source and review a recovery plan. A successful listing
+or upload is not proof that your key can decrypt the backup. Test a full restore on an
+appropriate isolated recovery host.
+
+Upload verification may compare size only when the backend exposes no native SHA256.
+`CLOUD_VERIFY_DOWNLOAD=true` enables download-and-hash verification in that case and
+uses additional bandwidth. Upload workers and rclone transfer settings do not make
+one `copyto` object upload into multiple independent file jobs. Review the
+[performance reference](#performance-tuning) before changing concurrency or rate limits.
+
+### Recover after losing the original host
+
+1. Install ProxSave and rclone on the replacement host using the
+ [installation guide](INSTALL.md#fast-install).
+2. Recover the independent rclone configuration or authenticate again through
+ `rclone config`. Restore private permissions and verify remote access.
+3. Configure the correct remote and backup path, then choose **Tools** > **Restore**
+ and select the cloud source. Select the exact complete backup, not a log or sidecar.
+4. Verify and decrypt it, choose categories and review the target-specific restore
+ plan. Follow [restore safety and verification](RESTORE_GUIDE.md#restore-modes).
+
+If you need an external manual download, use a private directory and the exact bundle
+name from the listing:
+
+```bash
+umask 077
+RECOVERY_DIR=$(mktemp -d /root/proxsave-recovery.XXXXXX)
+rclone copyto 'gdrive:proxsave/node1/backup/EXACT-BACKUP.bundle.tar' "$RECOVERY_DIR/backup.bundle.tar"
+```
+
+Make the downloaded copy available through the configured primary or secondary archive
+path before selecting it in the dashboard. Do not copy a fully extracted configuration
+tree over `/`; that bypasses restore safeguards. For provider archive tiers that require
+retrieval, follow [cold-storage recovery](#recover-archives-from-cold-object-storage)
+before selecting the backup.
+
+### If cloud storage fails
+
+Check the remote name, combined path, account used by ProxSave, token permissions,
+provider quota, connectivity and operation timeout. Distinguish failure to upload from
+failure to verify or rotate an already saved copy. Keep the successful local copy.
+The [troubleshooting reference](#troubleshooting) lists specific errors and token tests.
+For diagnostic backup logging see [troubleshooting](TROUBLESHOOTING.md#diagnose-backup-and-restore-failures):
+the debug invocation starts a backup and bypasses the dashboard.
+
+
+
+
+
+## Recover archives from cold object storage
+
+Use this procedure when a cloud lifecycle rule has moved a ProxSave backup into an
+archive tier that cannot be read immediately. Retrieving an archived object makes
+the backup readable; restoring host configuration is a separate step in ProxSave.
+
+ProxSave uses rclone to inspect and download cloud backups. It does not initiate the
+provider's archive retrieval request. A backup can appear in a remote listing while
+its contents are still unavailable, so listing the filename is not a recovery test.
+
+### Identify the complete recovery copy
+
+Find the exact backup for the host and recovery point you need. With default bundling,
+retain the complete `.bundle.tar` object. With bundling disabled, retain the archive
+and its matching `.manifest.json`, `.metadata` and `.sha256` files where present.
+Keep their original names and do not mix files from different runs.
+
+Recover access to the provider account and the configured rclone remote independently
+of the failed host. For encrypted backups, keep the matching private identity or
+original passphrase available. Passphrase recovery also needs the salt in the backup
+manifest; creating a new recipient cannot decrypt an old archive. See
+[recovery keys](ENCRYPTION.md#choose-recovery-material-you-can-retain).
+
+### Make the objects readable at the provider
+
+For Amazon S3 Glacier Flexible Retrieval or Deep Archive, select the required objects
+in the S3 console and request retrieval. Choose an availability period long enough
+to download and check the complete backup. Wait for completion and check the expiry
+date of the temporary copy. S3 Intelligent-Tiering archive tiers return retrieved
+objects to the Frequent Access tier instead. Retrieval options, time and charges
+depend on the storage class; follow the current
+[AWS archived-object recovery instructions](https://docs.aws.amazon.com/AmazonS3/latest/userguide/restoring-objects.html).
+
+If sidecars were archived separately, make those objects readable too. For another
+provider, follow its documented retrieval process. Advanced rclone users can consult
+the [S3 backend retrieval reference](https://rclone.org/s3/#restore); these provider
+operations run outside the ProxSave dashboard.
+
+### Restore through the dashboard
+
+1. Prepare a compatible recovery host using the [installation guide](INSTALL.md#fast-install)
+ and the [cloud remote setup](#prepare-the-remote). Keep enough local space for the
+ downloaded backup, decryption and extracted configuration.
+2. Configure the remote and the directory containing the retrieved backup. Run
+ `proxsave` without arguments on an interactive terminal, choose **Tools** >
+ **Restore**, then select the cloud source and the exact backup.
+3. Let ProxSave inspect the backup and verify integrity. Supply the matching recovery
+ secret when requested, select the required categories and review the restore plan.
+ Follow the [host restore procedure](RESTORE_GUIDE.md#restore-a-host) before applying
+ changes. Retrieving an object at the provider does not establish target compatibility.
+4. Inspect the restore result and test the affected services. A completed download
+ alone does not prove that host configuration was restored successfully.
+
+If you first download a local recovery copy, keep the complete bundle or matching
+archive and sidecars together, then place them in a configured primary or secondary
+archive path. Select that source in the dashboard. Preserve the original recovery
+material until verification is complete; do not unpack configuration directly over `/`.
+
+### If the backup cannot be selected or downloaded
+
+Check the retrieval status and expiry at the provider, read permissions, the configured
+remote path and whether every required object is accessible. ProxSave reads metadata
+while discovering cloud backups, so an unreadable bundle or sidecar can prevent a
+backup from being offered for selection. Discovery lists the selected directory,
+not all nested directories.
+
+Inspect the reported discovery or download error before starting another retrieval.
+Use the [diagnostic guide](TROUBLESHOOTING.md#diagnose-backup-and-restore-failures) for
+logging and support evidence. Keep the recovered copy readable for long enough to
+complete a recovery test on an isolated host.
+
+
+
+## Implementation appendix
## Architecture
@@ -64,7 +235,7 @@ Proxsave uses a **3-tier storage system**:
### Execution Flow
```text
-1. Create backup locally ✓ Critical (must succeed)
+1. Create backup locally Critical (must succeed)
└─> BACKUP_PATH/
2. Copy to secondary storage ○ Optional (warn on failure)
@@ -75,7 +246,7 @@ Proxsave uses a **3-tier storage system**:
├─> Verification: size + SHA256 (size-only fallback if backend lacks native hash)
└─> Retry: 3 attempts with backoff
-4. Apply retention policies ✓ Per-tier retention
+4. Apply retention policies Per-tier retention
├─> Local: MAX_LOCAL_BACKUPS or GFS
├─> Secondary: MAX_SECONDARY_BACKUPS or GFS
└─> Cloud: MAX_CLOUD_BACKUPS or GFS
@@ -121,47 +292,19 @@ this allowlist.
---
-## Prerequisites
-
-### Install rclone
-
-```bash
-# Verify installation
-which rclone
-rclone version
-
-# Install via official script (recommended)
-curl https://rclone.org/install.sh | sudo bash
-
-# Or via package manager
-# Debian/Ubuntu
-sudo apt-get update && sudo apt-get install rclone
-# CentOS/RHEL
-sudo yum install rclone
-# Or manual download
-wget https://downloads.rclone.org/rclone-current-linux-amd64.zip
-unzip rclone-current-linux-amd64.zip
-sudo cp rclone-*/rclone /usr/local/bin/
-sudo chmod 755 /usr/local/bin/rclone
+## Detailed reference
-# Verify
-rclone version # Should show v1.60+
-```
-
-**Minimum version**: rclone v1.60+
-**Recommended version**: Latest stable (v1.65+)
-
----
+The task above is the operator procedure. The following material preserves detailed behavior, limits and implementation context.
## Supported Cloud Providers
| Provider | rclone Type | Use Case | Free Tier |
|----------|-------------|----------|-----------|
| **Google Drive** | `drive` | Small/medium businesses, easy OAuth | 15GB |
-| **Amazon S3** | `s3` | Enterprise, scalable, highly available | 5GB (12 months) |
-| **Backblaze B2** | `b2` | Cost-effective archival | 10GB + 1GB/day egress |
+| **Amazon S3** | `s3` | Enterprise, scalable, highly available | Account-dependent; see [AWS Free Tier](https://aws.amazon.com/free/) |
+| **Backblaze B2** | `b2` | Cost-effective archival | See [B2 pricing and allowances](https://www.backblaze.com/cloud-storage/pricing) |
| **Microsoft OneDrive** | `onedrive` | Microsoft 365 integration | 5GB |
| **Dropbox** | `dropbox` | Simple, limited free space | 2GB |
| **MinIO** | `s3` | Self-hosted S3-compatible | Unlimited (self-hosted) |
@@ -177,7 +320,7 @@ rclone version # Should show v1.60+
### Interactive Configuration
-```bash
+```text
# Launch interactive wizard
rclone config
@@ -296,20 +439,24 @@ q # Quit
```
**B2 notes**:
-- Cost-effective: $0.005/GB/month (vs S3 $0.023)
-- 10GB free storage + 1GB/day free download
+- Check [current B2 pricing](https://www.backblaze.com/cloud-storage/pricing) for storage charges and allowances
+- Download allowances depend on the plan and stored volume; see [transaction and egress pricing](https://www.backblaze.com/cloud-storage/transaction-pricing)
- Lower API rate limit than S3
- Ideal for long-term archival
### Verify Configuration
+`rclone config show` prints sensitive configuration, including credentials or tokens.
+Use [config redacted](https://rclone.org/commands/rclone_config_redacted/) for diagnostics
+and review its output before sharing it.
+
```bash
# List configured remotes
rclone listremotes
# Output: gdrive:, s3backup:, minio:, b2:
-# Show configuration (no passwords)
-rclone config show gdrive
+# Show a redacted configuration (rclone 1.64 or newer)
+rclone config redacted gdrive
# Test connectivity
rclone lsf gdrive:
@@ -349,206 +496,18 @@ This ensures rclone config is backed up with your system, enabling disaster reco
---
-## Configure proxsave
-
-### From the dashboard
-
-Configure the rclone remote itself first (previous section): the dashboard does not run
-`rclone config` for you. Once the remote exists, run `proxsave` with no arguments on a TTY
-to open the dashboard, then **Install** > **Edit install**. That re-runs the install wizard
-against your existing configuration and three of its fields are the cloud ones:
-
-| Wizard field | Key it writes |
-|--------------|---------------|
-| `Cloud backups (rclone)` | `CLOUD_ENABLED` |
-| `Rclone backup remote` | `CLOUD_REMOTE` (the wizard accepts the legacy `remote:path` form here) |
-| `Rclone log remote` | `CLOUD_LOG_PATH` |
-
-The wizard requires both text fields once the toggle is on: it refuses an empty value
-rather than writing `CLOUD_ENABLED=true` with an empty `CLOUD_REMOTE`, which is a hard
-configuration error at run time. `CLOUD_LOG_PATH` is required by the wizard only: blanking
-it by hand later is legal and simply turns cloud log upload off. Turning the toggle off
-blanks both keys.
-
-Every other key in this guide is a hand edit of `backup.env`, `CLOUD_REMOTE_PATH` and the
-retention and tuning keys included. `--install` reaches the same wizard without going
-through the dashboard, for headless hosts and scripts; add `--cli` for text-mode prompts.
-
-### Minimal Configuration
-
-```bash
-# Edit backup.env
-nano /opt/proxsave/configs/backup.env
-
-# Enable cloud storage
-CLOUD_ENABLED=true
-# rclone remote NAME (from `rclone config`)
-CLOUD_REMOTE=GoogleDrive
-# Full path (or prefix) inside the remote
-CLOUD_REMOTE_PATH=/proxsave/backup
-
-# Retention
-MAX_CLOUD_BACKUPS=30
-```
-
-This is sufficient to start! Other options use sensible defaults.
-
-### Recommended Production Configuration
-
-```bash
-# Cloud storage
-CLOUD_ENABLED=true
-CLOUD_REMOTE=GoogleDrive
-CLOUD_REMOTE_PATH=/proxsave/backup # Folder path inside the remote
-CLOUD_LOG_PATH=/proxsave/log # Optional: log folder inside the same remote
-
-# Upload mode
-CLOUD_UPLOAD_MODE=parallel
-CLOUD_PARALLEL_MAX_JOBS=2
-CLOUD_PARALLEL_VERIFICATION=true
-CLOUD_VERIFY_CHECKSUM=true
-CLOUD_VERIFY_DOWNLOAD=false
-
-# Timeouts
-RCLONE_TIMEOUT_CONNECTION=30
-RCLONE_TIMEOUT_OPERATION=300 # 5 minutes
-
-# Bandwidth
-RCLONE_BANDWIDTH_LIMIT= # Empty = unlimited
-RCLONE_TRANSFERS=4
-
-# Retry & verification
-RCLONE_RETRIES=3
-RCLONE_VERIFY_METHOD=primary
-
-# Batch deletion
-CLOUD_BATCH_SIZE=20
-CLOUD_BATCH_PAUSE=1
-
-# GFS retention
-RETENTION_POLICY=gfs
-RETENTION_DAILY=7
-RETENTION_WEEKLY=4
-RETENTION_MONTHLY=12
-RETENTION_YEARLY=3
-```
-
-### Configuration Reference
-
-| Variable | Default | Description |
-|----------|---------|-------------|
-| `CLOUD_ENABLED` | `false` | Enable cloud storage |
-| `CLOUD_REMOTE` | _(empty)_ | rclone remote **name** from `rclone config` (legacy `remote:path` still supported), or an absolute local directory such as a mounted share (`/mnt/cloud`). **Required** when `CLOUD_ENABLED=true`: leaving it empty is a hard configuration error, and the run aborts with exit `2` before anything is backed up, locally included. Set both keys together, or neither. |
-| `CLOUD_REMOTE_PATH` | _(empty)_ | Folder path/prefix inside the remote (e.g., `/proxsave/backup`) |
-| `CLOUD_LOG_PATH` | _(empty)_ | Optional log folder (recommended: path-only on the same remote; use `otherremote:/path` only when using a different remote) |
-| `CLOUD_UPLOAD_MODE` | `parallel` | `parallel` or `sequential`. Inert under the default bundle layout: there is only one file to upload, so nothing runs concurrently either way |
-| `CLOUD_PARALLEL_MAX_JOBS` | `2` | Max concurrent uploads. Only has an effect with `BUNDLE_ASSOCIATED_FILES=false`, which is what creates more than one upload |
-| `CLOUD_PARALLEL_VERIFICATION` | `true` | Also verify each sidecar file. Only reachable with `BUNDLE_ASSOCIATED_FILES=false`; the setting is honoured in sequential mode too |
-| `CLOUD_VERIFY_CHECKSUM` | `true` | Compare remote SHA256 to the local checksum after upload; size-only fallback when the backend has no native hash |
-| `CLOUD_VERIFY_DOWNLOAD` | `false` | When the backend lacks native SHA256, download the object and hash it locally (uses bandwidth) |
-| `CLOUD_WRITE_HEALTHCHECK` | `false` | Use write test for connectivity check |
-| `RCLONE_TIMEOUT_CONNECTION` | `30` | Seconds. On the backup path this is the budget for the **whole** accessibility check, up to 3 attempts with 2s and 4s backoffs between them and up to 3 rclone calls each, not per command. The restore/decrypt cloud scan does apply it per command. Raise it if a slow remote makes the preflight give up |
-| `RCLONE_TIMEOUT_OPERATION` | `300` | Per-operation upload timeout (seconds). `0` means **unbounded** uploads (no per-op deadline). Management/query ops (list, delete, retention) are always bounded: they use this value when it is > 0, otherwise a built-in 300s floor. So raising it also raises the management ceiling, and a positive value below 300 also shortens management ops. |
-| `RCLONE_BANDWIDTH_LIMIT` | _(empty)_, template ships `10M` | Upload rate limit (e.g., `5M` = 5 MB/s) |
-| `RCLONE_TRANSFERS` | `4`, template ships `16` | Number of parallel transfers |
-| `RCLONE_RETRIES` | `3` | Retry attempts on failure |
-| `RCLONE_VERIFY_METHOD` | `primary` | How the remote object is located for verification: `primary` (`rclone lsl`) or `alternative` (`rclone ls`). The SHA256 comparison (see `CLOUD_VERIFY_CHECKSUM`) runs on top of either. |
-| `CLOUD_BATCH_SIZE` | `20` | Files per batch (deletion) |
-| `CLOUD_BATCH_PAUSE` | `1` | Seconds between batches |
-| `MAX_CLOUD_BACKUPS` | `30`, template ships `15` | Simple retention (ignored if GFS enabled) |
-| `RCLONE_FLAGS` | _(empty)_ | Extra global rclone flags, split on whitespace and injected verbatim into **every backup-path** rclone command (right after the subcommand). The restore and decrypt cloud scan builds its rclone calls separately and does **not** receive them: see [How ProxSave invokes rclone](#how-proxsave-invokes-rclone). No shell quoting or validation, so keep each flag a single token (e.g. `--fast-list --checkers 8`). |
-| `BUNDLE_ASSOCIATED_FILES` | `true` | Bundle the archive and its sidecars into one `.bundle.tar` before upload (the default cloud layout). Set `false` to upload the raw archive plus separate sidecars. See [Cloud layout](#cloud-layout-bundle-vs-raw). |
-
-**Legacy env-var aliases.** For backward compatibility ProxSave also accepts these
-older names. **When both are present the winner is not consistent**, so never leave
-both in the file:
-
-| Canonical | Legacy alias | Which wins if both are set |
-|---|---|---|
-| `CLOUD_ENABLED` | `ENABLE_CLOUD_BACKUP` | the legacy key, even with an empty value |
-| `CLOUD_REMOTE` | `RCLONE_REMOTE` | the legacy key |
-| `MAX_CLOUD_BACKUPS` | `CLOUD_RETENTION_DAYS` | the canonical key |
-| `RCLONE_TIMEOUT_CONNECTION` | `CLOUD_CONNECTIVITY_TIMEOUT` | the canonical key |
-
-So adding `CLOUD_REMOTE=NewRemote` to a config that still carries
-`RCLONE_REMOTE=OldRemote` keeps uploading to `OldRemote`. Prefer the canonical names in
-new configs, and delete the legacy line rather than leaving it alongside.
-
-For complete configuration reference, see: **[Configuration Guide](CONFIGURATION.md)**
-
-### Recommended Remote Path Formats (Important)
-
-ProxSave supports both "new style" (path-only) and "legacy style" (`remote:path`) values, but using a consistent format avoids confusion.
-
-**Recommended:**
-- `CLOUD_REMOTE` should be just the **remote name** (no `:`), e.g. `nextcloud` or `GoogleDrive`.
-- `CLOUD_REMOTE_PATH` should be a **path inside the remote** (no remote prefix). Use **no trailing slash**. A leading `/` is accepted
- and dropped: the path is always relative to the remote's root, which for an `sftp` remote is the login user's home directory.
- For a folder on this host, set `CLOUD_REMOTE` to its absolute path instead (for example `CLOUD_REMOTE=/mnt/backup`).
-- `CLOUD_LOG_PATH` should be a **folder path** for logs. When logs are stored on the **same remote**, prefer **path-only** here too (no remote prefix). Use `otherremote:/path` only if logs must go to a different remote than `CLOUD_REMOTE`.
-
-**Examples (same remote):**
-```bash
-CLOUD_REMOTE=nextcloud-katerasrael
-CLOUD_REMOTE_PATH=B+K/BACKUP/marcellus
-CLOUD_LOG_PATH=B+K/BACKUP/marcellus/logs
-```
-
-**Examples (different remotes for backups vs logs):**
-```bash
-CLOUD_REMOTE=nextcloud-backups
-CLOUD_REMOTE_PATH=proxsave/backup/host1
-CLOUD_LOG_PATH=nextcloud-logs:proxsave/log/host1
-```
-
-### Understanding CLOUD_REMOTE vs CLOUD_REMOTE_PATH
-
-**How CLOUD_REMOTE and CLOUD_REMOTE_PATH work together**
-
-1. **Recommended (remote name + full path in `CLOUD_REMOTE_PATH`)**
- - `CLOUD_REMOTE=GoogleDrive`
- - `CLOUD_REMOTE_PATH=/proxsave/backup/server1`
- → backups in: `GoogleDrive:/proxsave/backup/server1`
-
-2. **Legacy compatibility (remote already contains a base path)**
- - `CLOUD_REMOTE=GoogleDrive:/proxsave/backup`
- - `CLOUD_REMOTE_PATH=server1` *(optional extra suffix)*
- → backups in: `GoogleDrive:/proxsave/backup/server1`
-
-In both cases ProxSave combines the base path and the optional prefix into a single
-path inside the remote, and uses that consistently for:
-- **uploads** (cloud backend);
-- **cloud retention**;
-- **restore / decrypt menus** (entry "Cloud backups (rclone)").
- - Restore/decrypt cloud scanning applies `RCLONE_TIMEOUT_CONNECTION` per rclone command (the timer resets on each `lsf`/manifest read).
-
-You can choose the style you prefer; they are equivalent from the tool's point of view.
-
-3. **Local directory (an absolute path, for example a mounted share)**
- - `CLOUD_REMOTE=/mnt/cloud`
- - `CLOUD_REMOTE_PATH=server1` *(optional)*
- → backups in: `/mnt/cloud/server1`; with `CLOUD_LOG_PATH=/proxsave/log` the logs go to `/mnt/cloud/proxsave/log`.
- The copy still goes through rclone. ProxSave creates the directory when it is missing (not in a dry run) and gives the backups the same owner and mode as on the secondary path.
-
-**When to use CLOUD_REMOTE_PATH**:
-- Organizing multiple servers' backups: `server1/`, `server2/`
-- Separating environments: `production/`, `staging/`
-- Version control: `v1/`, `v2/`
-
-> **Give every host its own prefix.** Retention lists the remote **recursively**, with no depth limit, then keeps only the archives this host owns. The owner is the hostname recorded in the manifest, or the host token the filename carries (`-backup-`) when no manifest can be read. A host answers to the name the kernel reports and to the name it stamps into its own archives (`hostname -f`, so usually the FQDN), and to nothing else: `pve.siteA.example` and `pve.siteB.example` stay two machines, and so do `pve` and `pve.siteB.example` on a host whose FQDN does not resolve, unless the archives record this host's server identity: then they are this host's whatever name they carry. Archives left out of scope are never deleted and are not reported (a run with `--log-level debug` lists them). If `hostname -f` stops resolving the way it did when the archives were written, archives without this host's server identity stop rotating and the run says so (` Named , not rotated: backups`). A per-host prefix is still worth having on its own merits: smaller listings, counts in the log that match what you expect, and restore menus that show only this host's backups. Leave `CLOUD_REMOTE_PATH` empty only when the remote, or the sub-path in `CLOUD_REMOTE`, belongs to this host alone.
-
----
-
## Performance Tuning
Two things to know before you tune.
-Every upload is a single-file `rclone copyto`, and under the default bundle layout
-there is exactly one per backup. So `RCLONE_TRANSFERS` has nothing to parallelize
-either: like `CLOUD_UPLOAD_MODE` and `CLOUD_PARALLEL_MAX_JOBS`, it only starts mattering
-once `BUNDLE_ASSOCIATED_FILES=false` gives rclone more than one file. What actually
-moves the needle on a single large object is `RCLONE_BANDWIDTH_LIMIT` and the backend's
-own chunk and concurrency options, which belong in the rclone remote definition.
+Every upload is a single-file `rclone copyto`, including raw sidecars. Increasing
+`RCLONE_TRANSFERS` does not create concurrent file transfers inside that invocation.
+With the default bundle layout there is one backup object. With
+`BUNDLE_ASSOCIATED_FILES=false`, `CLOUD_UPLOAD_MODE` and `CLOUD_PARALLEL_MAX_JOBS`
+control ProxSave workers that launch separate uploads. For a large object, check
+`RCLONE_BANDWIDTH_LIMIT` and the backend's supported chunk and concurrency options
+in the rclone remote definition. The examples below are starting settings, not
+measured performance guarantees.
Integer keys are parsed strictly and fall back to their default without a warning if
parsing fails, so write a number: `RCLONE_TRANSFERS=16`, never `8-16`. A range silently
@@ -662,67 +621,6 @@ CLOUD_BATCH_PAUSE=0
---
-## Testing
-
-### Dry-Run Test
-
-```bash
-# Build
-cd /opt/proxsave
-make build
-
-# Dry-run test. --backup is what keeps this a run: a bare invocation on a terminal
-# opens the dashboard instead. --dry-run is the flag form of DRY_RUN=true.
-./build/proxsave --backup --dry-run
-
-# Check output:
-# ✓ " Accessible" under "Checking cloud remote accessibility..."
-# ✓ "✓ Cloud storage: initialized"
-#
-# A dry run returns before the storage phase, so there is no upload line to look for.
-# You will see "Storage dispatch skipped (dry run mode)" instead. Reaching the two
-# lines above already proves the remote is configured and reachable.
-```
-
-### Real Backup Test
-
-On an installed host the everyday way to run one now is the dashboard's **Backup** row.
-Against a development build, or on a headless host, use the flag:
-
-```bash
-# Real backup
-./build/proxsave --backup
-
-# Verify upload
-rclone ls gdrive:pbs-backups/
-# Should show backup files
-
-# Verify logs
-rclone ls gdrive:/pbs-logs/
-# Should show log files
-```
-
-### Manual rclone Test
-
-```bash
-# Test upload
-echo "test" > /tmp/test.txt
-rclone copy /tmp/test.txt gdrive:pbs-backups/ --verbose
-
-# Verify
-rclone lsl gdrive:pbs-backups/test.txt
-
-# Test download
-rclone copy gdrive:pbs-backups/test.txt /tmp/test-download.txt
-cat /tmp/test-download.txt
-
-# Cleanup
-rclone deletefile gdrive:pbs-backups/test.txt
-rm /tmp/test*.txt
-```
-
----
-
## Troubleshooting
### Common Errors
@@ -730,12 +628,12 @@ rm /tmp/test*.txt
| Error | Cause | Solution |
|-------|-------|----------|
| `rclone not found in PATH` | Not installed | `curl https://rclone.org/install.sh \| sudo bash` |
-| `couldn't find configuration section 'gdrive'` | Remote not configured | `rclone config` → create remote |
+| `couldn't find configuration section 'gdrive'` | Remote not configured | `rclone config` to create remote |
| `401 unauthorized` | Credentials expired | `rclone config reconnect gdrive` or regenerate keys |
| `connection timeout (30s)` | Slow network | Increase `RCLONE_TIMEOUT_CONNECTION=60` |
| `Timed out while scanning ... (rclone)` | Slow remote / huge directory | Increase `RCLONE_TIMEOUT_CONNECTION` and ensure the remote path points to the directory that contains the backups (scan is non-recursive) |
| `operation timeout (300s exceeded)` | Large file + slow network | Increase `RCLONE_TIMEOUT_OPERATION=900` |
-| `429 Too Many Requests` | API rate limiting | Reduce `RCLONE_TRANSFERS=2`, increase `CLOUD_BATCH_PAUSE=3` |
+| `429 Too Many Requests` | API rate limiting | Reduce ProxSave upload workers for raw files; for retention, reduce `CLOUD_BATCH_SIZE` and increase `CLOUD_BATCH_PAUSE` |
| `directory not found` | Path doesn't exist | `rclone mkdir gdrive:pbs-backups` |
| `403 Forbidden` | Insufficient permissions | Check bucket/remote ACL/IAM |
| `507 Insufficient Storage` | Quota exceeded | Reduce retention, increase quota, or change provider |
@@ -764,6 +662,8 @@ This creates a temporary test file (`.pbs-backup-healthcheck-`) and d
#### Enable Debug Logging
+`proxsave --log-level debug` starts a backup with diagnostic logging. Because it has an argument, it bypasses the dashboard; it does not open a debug dashboard. It may create and upload a real backup.
+
```bash
# Run with debug level
proxsave --log-level debug
@@ -785,9 +685,7 @@ DEBUG_LEVEL=extreme
# Check parsed configuration
grep -E "^CLOUD_|^RCLONE_" /opt/proxsave/configs/backup.env
-# Test with dry-run
-proxsave --dry-run --log-level debug
-# Check output for loaded config values
+# Dry-run diagnostic invocations are documented in CLI_REFERENCE.md.
```
#### Analyze Log Files
@@ -808,129 +706,10 @@ grep -i "cloud.*error\|cloud.*fail\|cloud.*warning" /opt/proxsave/log/backup-*.l
---
-## Disaster Recovery
-
-### Backup Configuration
-
-```bash
-# Save critical configs
-tar -czf /tmp/pbs-config-backup.tar.gz \
- /root/.config/rclone/rclone.conf \
- /opt/proxsave/configs/backup.env
-
-# Upload to cloud (manual)
-rclone copy /tmp/pbs-config-backup.tar.gz gdrive:/pbs-disaster-recovery/
-
-# Or automate via backup.env
-CUSTOM_BACKUP_PATHS="
-/root/.config/rclone/rclone.conf
-/opt/proxsave/configs/
-"
-```
-
-### Recovery Procedure
-
-Complete step-by-step recovery process:
-
-**Step 1: Setup New Server**
-
-```bash
-apt-get update && apt-get install rclone
-```
-
-**Step 2: Restore rclone Config**
-
-```bash
-# Option A: From separate backup
-rclone copy gdrive:/pbs-disaster-recovery/rclone.conf /root/.config/rclone/
-
-# Option B: Reconfigure manually
-rclone config
-```
-
-**Step 3: Verify Access**
-
-```bash
-rclone ls gdrive:pbs-backups/
-```
-
-**Step 4: Download Latest Backup**
-
-```bash
-LATEST=$(rclone lsf gdrive:pbs-backups/ --format "t;p" | sort -r | head -1 | cut -d';' -f2)
-echo "Latest: $LATEST"
-rclone copy "gdrive:pbs-backups/$LATEST" /tmp/recovery/
-```
-
-**Step 5: Extract Bundle** (the default layout ships one `.bundle.tar` per backup; skip this step only if you set `BUNDLE_ASSOCIATED_FILES=false`)
-
-```bash
-cd /tmp/recovery
-tar -xf *.bundle.tar
-```
-
-**Step 6: Verify Checksum**
-
-```bash
-sha256sum -c *.sha256
-```
-
-**Step 7: Decrypt** (if encrypted)
-
-```bash
-age --decrypt -i /path/to/key.txt -o backup.tar.xz backup.tar.xz.age
-```
-
-**Step 8: Extract Archive**
-
-```bash
-tar -xJf backup.tar.xz -C /restore/
-```
-
-**Step 9: Restore Files**
-
-```bash
-# Review extracted files first
-ls -la /restore/
-
-# Restore selectively (recommended)
-cp -a /restore/etc/pve/* /etc/pve/
-cp -a /restore/etc/proxmox-backup/* /etc/proxmox-backup/
-
-# Or restore all (use with caution)
-cp -a /restore/* /
-```
-
-**For complete restore workflows**, see: **[Restore Guide](RESTORE_GUIDE.md)**
-
----
-
-## Related Documentation
-
-### Configuration
-- **[Configuration Guide](CONFIGURATION.md)** - Complete variable reference including all cloud/rclone settings
-- **[Encryption Guide](ENCRYPTION.md)** - AGE encryption for cloud-stored backups
-
-### Restore Operations
-- **[Restore Guide](RESTORE_GUIDE.md)** - Complete restore workflows from cloud backups
-- **[Restore Technical](RESTORE_TECHNICAL.md)** - Technical implementation details
-
-### Reference
-- **[Dashboard](DASHBOARD.md)** - The interactive menu, including the Install wizard that writes the cloud keys
-- **[Daemon](DAEMON.md)** - The resident scheduler and its `MAX_RUN_DURATION` watchdog
-- **[Examples](EXAMPLES.md)** - Real-world cloud backup scenarios
-- **[Troubleshooting](TROUBLESHOOTING.md)** - Cloud storage troubleshooting
-- **[CLI Reference](CLI_REFERENCE.md)** - Command-line flags
-
-### Main Documentation
-- **[README](../README.md)** - Project overview and quick start
-
----
-
## FAQ
**Q: Can I use multiple cloud providers?**
-A: No, currently only one `CLOUD_REMOTE` is supported. Workaround: Use `rclone union` to combine multiple backends.
+A: ProxSave supports one `CLOUD_REMOTE`. An rclone union combines backends, but its default create policy chooses one upstream; it does not create an independent copy on every provider. Replication needs an explicit policy and a review of read, delete and failure behavior. See [rclone union policies](https://rclone.org/union/).
**Q: Can I use a network address like "192.168.0.10/folder" for SECONDARY_PATH?**
A: **No**. `SECONDARY_PATH` and `BACKUP_PATH` require **absolute local filesystem paths**. For network shares, mount them first using NFS/CIFS/SMB, then use the local mount point path (e.g., `/mnt/nas-backup`).
@@ -938,10 +717,10 @@ A: **No**. `SECONDARY_PATH` and `BACKUP_PATH` require **absolute local filesyste
If you want to use a direct network address without mounting, configure it as `CLOUD_REMOTE` using rclone with an S3-compatible backend (like MinIO) or appropriate protocol.
Example comparison:
-- ✗ WRONG: `SECONDARY_PATH=192.168.0.10:/backup`
-- ✗ WRONG: `SECONDARY_PATH=//server/share`
-- ✓ RIGHT: Mount first: `sudo mount 192.168.0.10:/backup /mnt/backup`, then `SECONDARY_PATH=/mnt/backup`
-- ✓ ALTERNATIVE: Use `CLOUD_REMOTE=minio` with `CLOUD_REMOTE_PATH=/backup` (requires rclone configuration for MinIO/S3 on LAN)
+- Invalid: `SECONDARY_PATH=192.168.0.10:/backup`
+- Invalid: `SECONDARY_PATH=//server/share`
+- Mounted filesystem: Mount first: `sudo mount 192.168.0.10:/backup /mnt/backup`, then `SECONDARY_PATH=/mnt/backup`
+- rclone alternative: Use `CLOUD_REMOTE=minio` with `CLOUD_REMOTE_PATH=/backup` (requires rclone configuration for MinIO/S3 on LAN)
**Q: Do cloud logs consume too much space?**
A: Logs follow backup retention automatically. To disable cloud log upload: `CLOUD_LOG_PATH=""` (empty).
@@ -950,10 +729,10 @@ A: Logs follow backup retention automatically. To disable cloud log upload: `CLO
A: Yes. The local backup completes first (critical), but the upload runs inside the same run, so it delays completion. There is no upload-only mode and no way to hand the upload to a separate job: the run owns it. On a host scheduled by the resident daemon this matters twice over, because the upload counts against `MAX_RUN_DURATION` (default `1h`), and a run that overruns it is killed and reported as a hang rather than finishing slowly. Size that key for the slowest upload you expect, and remember that `RCLONE_BANDWIDTH_LIMIT` makes the run longer, not shorter.
**Q: Can I backup directly to cloud only (no local)?**
-A: No, local storage is mandatory (critical). Cloud is always secondary/tertiary. Philosophy: fast local backup → slow cloud archival.
+A: No, local storage is mandatory (critical). Cloud is always secondary/tertiary. Philosophy: fast local backup to slow cloud archival.
**Q: How much RAM does rclone use?**
-A: Depends on `RCLONE_TRANSFERS`. Each transfer uses ~10-50MB. With `RCLONE_TRANSFERS=8` → ~80-400MB. For low-RAM systems: `RCLONE_TRANSFERS=2`.
+A: Memory use depends on backend buffers, chunk sizes and the number of ProxSave upload workers. Each worker invokes a single-file `copyto`; multiplying a per-file estimate by `RCLONE_TRANSFERS` does not describe this path. Measure a representative run and reduce `CLOUD_PARALLEL_MAX_JOBS` for raw uploads or backend buffering when needed.
**Q: Can I test upload without creating backup?**
A: Yes, use existing file:
@@ -975,8 +754,8 @@ A: Set `CLOUD_WRITE_HEALTHCHECK=true` in `configs/backup.env`. This uses write t
# List remotes
rclone listremotes
-# Show remote config
-rclone config show gdrive
+# Show redacted remote config; review before sharing
+rclone config redacted gdrive
# List files (long format)
rclone lsl gdrive:pbs-backups/
@@ -987,10 +766,10 @@ rclone lsf gdrive:pbs-backups/
# Check quota
rclone about gdrive:
-# Copy local → remote
+# Copy local to remote
rclone copy /local/file.txt gdrive:pbs-backups/
-# Copy remote → local
+# Copy remote to local
rclone copy gdrive:pbs-backups/file.txt /local/
# Sync (WARNING: deletes non-matching files)
@@ -1037,3 +816,136 @@ CLOUD_BATCH_PAUSE=1
---
**For official rclone documentation**, see: https://rclone.org/
+
+### Configuration Reference
+
+| Variable | Default | Description |
+|----------|---------|-------------|
+| `CLOUD_ENABLED` | `false` | Enable cloud storage |
+| `CLOUD_REMOTE` | _(empty)_ | rclone remote **name** from `rclone config` (legacy `remote:path` still supported), or an absolute local directory such as a mounted share (`/mnt/cloud`). **Required** when `CLOUD_ENABLED=true`: leaving it empty is a hard configuration error, and the run aborts with exit `2` before anything is backed up, locally included. Set both keys together, or neither. |
+| `CLOUD_REMOTE_PATH` | _(empty)_ | Folder path/prefix inside the remote (e.g., `/proxsave/backup`) |
+| `CLOUD_LOG_PATH` | _(empty)_ | Optional log folder (recommended: path-only on the same remote; use `otherremote:/path` only when using a different remote) |
+| `CLOUD_UPLOAD_MODE` | `parallel` | `parallel` or `sequential`. Inert under the default bundle layout: there is only one file to upload, so nothing runs concurrently either way |
+| `CLOUD_PARALLEL_MAX_JOBS` | `2` | Max concurrent uploads. Only has an effect with `BUNDLE_ASSOCIATED_FILES=false`, which is what creates more than one upload |
+| `CLOUD_PARALLEL_VERIFICATION` | `true` | Also verify each sidecar file. Only reachable with `BUNDLE_ASSOCIATED_FILES=false`; the setting is honoured in sequential mode too |
+| `CLOUD_VERIFY_CHECKSUM` | `true` | Compare remote SHA256 to the local checksum after upload; size-only fallback when the backend has no native hash |
+| `CLOUD_VERIFY_DOWNLOAD` | `false` | When the backend lacks native SHA256, download the object and hash it locally (uses bandwidth) |
+| `CLOUD_WRITE_HEALTHCHECK` | `false` | Use write test for connectivity check |
+| `RCLONE_TIMEOUT_CONNECTION` | `30` | Seconds. On the backup path this is the budget for the **whole** accessibility check, up to 3 attempts with 2s and 4s backoffs between them and up to 3 rclone calls each, not per command. The restore/decrypt cloud scan does apply it per command. Raise it if a slow remote makes the preflight give up |
+| `RCLONE_TIMEOUT_OPERATION` | `300` | Per-operation upload timeout (seconds). `0` means **unbounded** uploads (no per-op deadline). Management/query ops (list, delete, retention) are always bounded: they use this value when it is > 0, otherwise a built-in 300s floor. So raising it also raises the management ceiling, and a positive value below 300 also shortens management ops. |
+| `RCLONE_BANDWIDTH_LIMIT` | _(empty)_, template ships `10M` | Upload rate limit (e.g., `5M` = 5 MB/s) |
+| `RCLONE_TRANSFERS` | `4`, template ships `16` | Passed as rclone `--transfers`; each ProxSave upload is a single-file `copyto`, so this does not set ProxSave upload concurrency |
+| `RCLONE_RETRIES` | `3` | Retry attempts on failure |
+| `RCLONE_VERIFY_METHOD` | `primary` | How the remote object is located for verification: `primary` (`rclone lsl`) or `alternative` (`rclone ls`). The SHA256 comparison (see `CLOUD_VERIFY_CHECKSUM`) runs on top of either. |
+| `CLOUD_BATCH_SIZE` | `20` | Files per batch (deletion) |
+| `CLOUD_BATCH_PAUSE` | `1` | Seconds between batches |
+| `MAX_CLOUD_BACKUPS` | `30`, template ships `15` | Simple retention (ignored if GFS enabled) |
+| `RCLONE_FLAGS` | _(empty)_ | Extra global rclone flags, split on whitespace and injected verbatim into **every backup-path** rclone command (right after the subcommand). The restore and decrypt cloud scan builds its rclone calls separately and does **not** receive them: see [How ProxSave invokes rclone](#how-proxsave-invokes-rclone). No shell quoting or validation, so keep each flag a single token (e.g. `--fast-list --checkers 8`). |
+| `BUNDLE_ASSOCIATED_FILES` | `true` | Bundle the archive and its sidecars into one `.bundle.tar` before upload (the default cloud layout). Set `false` to upload the raw archive plus separate sidecars. See [Cloud layout](#cloud-layout-bundle-vs-raw). |
+
+**Legacy env-var aliases.** For backward compatibility ProxSave also accepts these
+older names. **When both are present the winner is not consistent**, so never leave
+both in the file:
+
+| Canonical | Legacy alias | Which wins if both are set |
+|---|---|---|
+| `CLOUD_ENABLED` | `ENABLE_CLOUD_BACKUP` | the legacy key, even with an empty value |
+| `CLOUD_REMOTE` | `RCLONE_REMOTE` | the legacy key |
+| `MAX_CLOUD_BACKUPS` | `CLOUD_RETENTION_DAYS` | the canonical key |
+| `RCLONE_TIMEOUT_CONNECTION` | `CLOUD_CONNECTIVITY_TIMEOUT` | the canonical key |
+
+So adding `CLOUD_REMOTE=NewRemote` to a config that still carries
+`RCLONE_REMOTE=OldRemote` keeps uploading to `OldRemote`. Prefer the canonical names in
+new configs, and delete the legacy line rather than leaving it alongside.
+
+For complete configuration reference, see: **[Configuration Guide](CONFIGURATION.md)**
+
+### Recommended Remote Path Formats (Important)
+
+ProxSave supports both "new style" (path-only) and "legacy style" (`remote:path`) values, but using a consistent format avoids confusion.
+
+**Recommended:**
+- `CLOUD_REMOTE` should be just the **remote name** (no `:`), e.g. `nextcloud` or `GoogleDrive`.
+- `CLOUD_REMOTE_PATH` should be a **path inside the remote** (no remote prefix). Use **no trailing slash**. A leading `/` is accepted
+ and dropped: the path is always relative to the remote's root, which for an `sftp` remote is the login user's home directory.
+ For a folder on this host, set `CLOUD_REMOTE` to its absolute path instead (for example `CLOUD_REMOTE=/mnt/backup`).
+- `CLOUD_LOG_PATH` should be a **folder path** for logs. When logs are stored on the **same remote**, prefer **path-only** here too (no remote prefix). Use `otherremote:/path` only if logs must go to a different remote than `CLOUD_REMOTE`.
+
+**Examples (same remote):**
+```bash
+CLOUD_REMOTE=nextcloud-katerasrael
+CLOUD_REMOTE_PATH=B+K/BACKUP/marcellus
+CLOUD_LOG_PATH=B+K/BACKUP/marcellus/logs
+```
+
+**Examples (different remotes for backups vs logs):**
+```bash
+CLOUD_REMOTE=nextcloud-backups
+CLOUD_REMOTE_PATH=proxsave/backup/host1
+CLOUD_LOG_PATH=nextcloud-logs:proxsave/log/host1
+```
+
+### Understanding CLOUD_REMOTE vs CLOUD_REMOTE_PATH
+
+**How CLOUD_REMOTE and CLOUD_REMOTE_PATH work together**
+
+1. **Recommended (remote name + full path in `CLOUD_REMOTE_PATH`)**
+ - `CLOUD_REMOTE=GoogleDrive`
+ - `CLOUD_REMOTE_PATH=/proxsave/backup/server1`
+ to backups in: `GoogleDrive:/proxsave/backup/server1`
+
+2. **Legacy compatibility (remote already contains a base path)**
+ - `CLOUD_REMOTE=GoogleDrive:/proxsave/backup`
+ - `CLOUD_REMOTE_PATH=server1` *(optional extra suffix)*
+ to backups in: `GoogleDrive:/proxsave/backup/server1`
+
+In both cases ProxSave combines the base path and the optional prefix into a single
+path inside the remote, and uses that consistently for:
+- **uploads** (cloud backend);
+- **cloud retention**;
+- **restore / decrypt menus** (entry "Cloud backups (rclone)").
+ - Restore/decrypt cloud scanning applies `RCLONE_TIMEOUT_CONNECTION` per rclone command (the timer resets on each `lsf`/manifest read).
+
+You can choose the style you prefer; they are equivalent from the tool's point of view.
+
+3. **Local directory (an absolute path, for example a mounted share)**
+ - `CLOUD_REMOTE=/mnt/cloud`
+ - `CLOUD_REMOTE_PATH=server1` *(optional)*
+ to backups in: `/mnt/cloud/server1`; with `CLOUD_LOG_PATH=/proxsave/log` the logs go to `/mnt/cloud/proxsave/log`.
+ The copy still goes through rclone. ProxSave creates the directory when it is missing (not in a dry run) and gives the backups the same owner and mode as on the secondary path.
+
+**When to use CLOUD_REMOTE_PATH**:
+- Organizing multiple servers' backups: `server1/`, `server2/`
+- Separating environments: `production/`, `staging/`
+- Version control: `v1/`, `v2/`
+
+> **Give every host its own prefix.** Retention lists the remote **recursively**, with no depth limit, then keeps only the archives this host owns. The owner is the hostname recorded in the manifest, or the host token the filename carries (`-backup-`) when no manifest can be read. A host answers to the name the kernel reports and to the name it stamps into its own archives (`hostname -f`, so usually the FQDN), and to nothing else: `pve.siteA.example` and `pve.siteB.example` stay two machines, and so do `pve` and `pve.siteB.example` on a host whose FQDN does not resolve, unless the archives record this host's server identity: then they are this host's whatever name they carry. Archives left out of scope are never deleted and are not reported (a run with `--log-level debug` lists them). If `hostname -f` stops resolving the way it did when the archives were written, archives without this host's server identity stop rotating and the run says so (` Named , not rotated: backups`). A per-host prefix is still worth having on its own merits: smaller listings, counts in the log that match what you expect, and restore menus that show only this host's backups. Leave `CLOUD_REMOTE_PATH` empty only when the remote, or the sub-path in `CLOUD_REMOTE`, belongs to this host alone.
+
+---
+
+
+## Earlier guide entry points
+
+## Configure proxsave
+
+See the complete [operator procedure](#set-up-and-recover-cloud-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Disaster Recovery
+
+See the complete [operator procedure](#set-up-and-recover-cloud-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Overview
+
+See the complete [operator procedure](#set-up-and-recover-cloud-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Prerequisites
+
+See the complete [operator procedure](#set-up-and-recover-cloud-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Related Documentation
+
+See the complete [operator procedure](#set-up-and-recover-cloud-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Testing
+
+See the complete [operator procedure](#set-up-and-recover-cloud-backups). Detailed settings and implementation material remain in the reference sections above.
diff --git a/docs/CLUSTER_RECOVERY.md b/docs/CLUSTER_RECOVERY.md
index d913ed99..048e5662 100644
--- a/docs/CLUSTER_RECOVERY.md
+++ b/docs/CLUSTER_RECOVERY.md
@@ -4,6 +4,7 @@ Advanced disaster recovery procedures for Proxmox VE cluster database restoratio
## Table of Contents
+- [Choose a cluster recovery procedure](#recover-a-proxmox-cluster)
- [Overview](#overview)
- [Starting a restore](#starting-a-restore)
- [Understanding PVE Cluster Architecture](#understanding-pve-cluster-architecture)
@@ -21,6 +22,54 @@ Advanced disaster recovery procedures for Proxmox VE cluster database restoratio
---
+
+
+## Recover a Proxmox cluster
+
+Start by deciding whether the target is standalone, an isolated surviving member, a fresh replacement joining a healthy cluster, or the first node of a complete rebuild. Those are different recovery states. Configuration restoration does not recover VM/CT disks, shared storage data or PBS chunks, and a service starting does not prove correct membership or quorum.
+
+### Establish the recovery boundary
+
+Keep console or IPMI access, recover the complete backup and decryption credentials independently, and record the expected hostname, node membership and network/storage layout. Confirm which peers are alive before any destructive database operation. Isolate the intended recovery target and account for HA workloads and fencing. Never rename a live member, remove yourself with `pvecm delnode`, delete the pmxcfs tree or use a blind expected-votes override to make a restore proceed.
+
+Run `proxsave` without arguments as root on an interactive console and choose **Tools > Restore**. The workflow verifies the archive, decrypts if needed, lists available categories and asks for scope. Direct entry for consoles where the dashboard cannot render is documented in [CLI reference](CLI_REFERENCE.md#restore-from-backup); it remains interactive.
+
+### Choose the complete scenario before applying
+
+| Situation | Canonical procedure | Boundary |
+| --- | --- | --- |
+| Failed standalone PVE host | [Single-Node Recovery](#scenario-1-single-node-recovery) | Confirm that the destination is truly standalone; an isolated member is not the same state. |
+| Entire cluster lost | [Complete Cluster Rebuild](#scenario-2-complete-cluster-rebuild) | Recover the first isolated node deliberately, then rebuild membership through the reviewed joining procedure. Do not restore an independent database on each joined node. |
+| Healthy peers remain and one node failed | [Multi-Node Cluster with Failed Master](#scenario-3-multi-node-cluster-with-failed-master) | Use a clean replacement and the healthy cluster's current configuration. Optional ProxSave restore is Custom and excludes `pve_cluster`; node-local network changes need console review. |
+| New hardware | [Migration to New Hardware](#scenario-4-migration-to-new-hardware) | Choose standalone, isolated-member or clean-join recovery before selecting scope. Validate disk identity, mounts and device assignments on the destination. |
+| Different destination hostname | [Hostname Changed](#scenario-5-hostname-changed) | Do not rename a live member. On a fresh or isolated destination, review SAFE exported-node selection and live guest ownership. |
+
+Each linked runbook contains its prerequisites, external Proxmox steps, dashboard choices and verification. Follow it as a complete procedure rather than combining commands from different scenarios. The [pre-recovery checklist](#pre-recovery-checklist) is required preparation; official membership procedures remain external Proxmox operations.
+
+### SAFE and RECOVERY are separate from scope
+
+The mandatory cluster-mode selector appears when a selected `pve_cluster` payload is present. Full and Storage can reach it; Custom reaches it only with that category selected. System base does not select it. Full includes export-only categories, while Storage and System base exclude them. Include `pve_config_export` when you need backed-up guest definitions for SAFE application.
+
+SAFE does not replace the archived `config.db` or stop the PVE cluster services. Confirmed storage, datacenter, pool, mapping and guest applies nevertheless change live state, sometimes across the cluster. Guest confirmation concerns the eligible batch from the chosen exported source node, not an individual selection for every VM. Source-node selection does not transfer ownership: cluster-wide guest inventory must be readable and unambiguous, and VMIDs owned by another node or with another guest type are skipped. A file fallback for an existing guest needs a recognized API schema refusal and verified stopped status; other API errors do not authorize it. Without `pvesh`, SAFE applies are skipped. Review [full SAFE behavior](#cluster-restore-modes-safe-vs-recovery) before accepting these changes.
+
+RECOVERY overwrites `/var/lib/pve-cluster/` while pmxcfs is stopped. Use it only on an offline or isolated destination under the chosen runbook. A quorate cluster with more than one online node is refused before services stop or files are written. Unreadable quorum or node counts allow continuation only when corosync is confirmed inactive or failed; active, starting or unreadable corosync is refused. A node without either corosync configuration path is treated as standalone. Passing a software guard does not replace verifying the scenario and peer isolation.
+
+### Service and partial-failure safeguards
+
+RECOVERY stops HA first: `pve-ha-lrm`, then `pve-ha-crm`, before cluster/API services. The LRM receives one graceful stop and up to 180 seconds; it is never signalled to force progress because that can leave its watchdog armed and fence the host. If it cannot stop, the restore aborts and cancels the queued stop. Do not kill it manually to bypass this safeguard.
+
+The workflow unmounts `/etc/pve`, extracts the database, then restarts cluster/API services before later restore stages. An unmount failure is a warning, not proof that the database is safe. Individual `/etc/pve` applies are skipped in RECOVERY because the database owns those areas; confirmed SAFE paths are separate live write paths. Restart warnings must be investigated, and HA must not be brought back while pmxcfs is unavailable.
+
+Normal extraction, fstab merge and SAFE operations can change the host before later staged apply. An incomplete sensitive stage is discarded and its consumers are skipped; this is not a whole-restore transaction. Network/firewall/HA/access-control live applies have their own 180-second COMMIT rollback decisions. The fstab countdown expires to No even when matching root/swap makes Yes the Enter-key default. Read the logs and establish the actual applied scope before retrying.
+
+### Verify and handle failures
+
+Use [Post-Recovery Verification](#post-recovery-verification) to check service health, mounted pmxcfs, actual membership and quorum, cluster communication, storage, UI/API access and workload definitions. Confirm backing mounts and VM disks before starting workloads. Mount guards can make offline storage read-only; a failed bind guard is warning-only, and a real mount only shadows an existing guard. Use **Recovery > Cleanup guards** after storage is correctly available and inspect any remaining/pending legacy flags.
+
+Keep the printed logs and persistent `/restore/TIMESTAMP/` safety artifacts until the result is verified. They do not undo every API operation. Never blindly extract a safety archive over a live database: follow [manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites), including isolation, graceful HA shutdown and correct `config.db` recovery permissions. For refused guards or incomplete recovery, use [Common Issues and Solutions](#common-issues-and-solutions), the applicable runbook's failure handling, and [Prepare a support request](TROUBLESHOOTING.md#prepare-a-support-request).
+
+
+
## Overview
This guide covers **advanced cluster database recovery** using proxsave's restore functionality. These procedures should be performed by experienced administrators familiar with Proxmox VE clustering.
@@ -43,29 +92,7 @@ This guide covers **advanced cluster database recovery** using proxsave's restor
## Starting a restore
-Every procedure in this guide is driven from ProxSave's restore workflow. There are two
-ways to open it and they run the same code:
-
-- **The dashboard, `Restore`.** Run `proxsave` with no arguments on a terminal and pick
- `Restore` from the menu. This is the normal way to use ProxSave, including for the
- recoveries below, whenever the node still gives you a usable console.
-- **`proxsave --restore`.** The flag path: a headless host, a terminal whose `TERM` is
- unset or `dumb`, a scripted or piped run, and any case where the menu cannot render.
- The dashboard opens only on a **completely bare** `proxsave`, so any flag, `--config`
- included, suppresses it; a restore that has to carry another flag is necessarily a
- flag invocation.
-
-Both open the same workflow. On an interactive terminal you get the graphical (TUI)
-screens; `--cli`, and any non-interactive invocation, gives the plain text prompts. The
-menus quoted throughout this guide are that text rendering, because it is the one that
-pastes into a document. The questions, the choices and their consequences are identical
-in the TUI, where each menu is a selector.
-
-The other ProxSave commands used below have the same shape: `Backup` in the dashboard is
-`proxsave --backup`, `Decrypt` is `proxsave --decrypt`, and `Recovery > Cleanup guards`
-is `proxsave --cleanup-guards`. See [DASHBOARD.md](DASHBOARD.md) for the menu as a whole.
-
----
+Run `proxsave` without arguments as root on an interactive console, then choose **Tools > Restore**. The prompts below are the text representation of the same restore choices shown as TUI selectors. Both interfaces require operator answers. If the dashboard cannot render or you need a different configuration file, consult [CLI reference](CLI_REFERENCE.md) for direct entry and terminal options.
## Understanding PVE Cluster Architecture
@@ -132,7 +159,7 @@ Communication Layer:
**/etc/pve**:
- **NOT** a real directory (it's a FUSE mount)
- View into config.db
-- You cannot write files into it directly (writes go to the FUSE layer). ProxSave either applies the exported files through the API (SAFE) or restores config.db while pmxcfs is stopped (RECOVERY). See [Cluster restore modes](#cluster-restore-modes-safe-vs-recovery).
+- Writes through mounted pmxcfs are persisted in config.db and replicated. ProxSave blocks blind archive extraction there and uses confirmed API/pmxcfs applies (SAFE) or database replacement with services stopped (RECOVERY). See [Cluster restore modes](#cluster-restore-modes-safe-vs-recovery).
- Repopulated from config.db when pmxcfs restarts (the RECOVERY path)
**Corosync**:
@@ -142,14 +169,14 @@ Communication Layer:
### Why /etc/pve needs special handling
-You cannot simply copy files into `/etc/pve`. It is a FUSE view of config.db, so a `cp` into it writes to the FUSE layer and is lost when pmxcfs restarts:
-
-```bash
-# This does NOT persist:
-cp backup/etc/pve/storage.cfg /etc/pve/storage.cfg
-```
+A write through mounted pmxcfs updates persistent cluster configuration. A copy into
+an underlying directory while pmxcfs is unmounted does not update that database.
+Confusing these two states can overwrite live configuration or leave files hidden
+under the mount. See the [pmxcfs documentation](https://pve.proxmox.com/pve-docs/pmxcfs-plain.html).
-ProxSave handles this in one of two ways, and it makes you choose which at restore time: it either applies the exported configuration to a running cluster through the Proxmox API (SAFE), or it restores the whole config.db while pmxcfs is stopped (RECOVERY). The next section is the one that matters most.
+ProxSave exports `/etc/pve` entries for review. SAFE offers confirmed configuration
+applies against the running cluster; RECOVERY replaces the archived database only
+after the required service shutdown. Choose the mode according to the cluster state.
---
@@ -171,17 +198,17 @@ Choice:
In the TUI it is a selector titled `Cluster restore mode` with `SAFE`, `RECOVERY`, and `Exit` items carrying the same text. `Exit` (or Esc) aborts the whole restore.
-### SAFE (the non-destructive choice)
+### SAFE (configuration apply)
-SAFE never writes config.db, never stops `pve-cluster`/`pvedaemon`/`pveproxy`/`pvestatd`, and never unmounts `/etc/pve`. It extracts the cluster files to an export directory and re-applies them to the RUNNING cluster through `pvesh`/`pveum`:
+SAFE does not replace config.db with the archived database, does not stop `pve-cluster`/`pvedaemon`/`pveproxy`/`pvestatd`, and does not unmount `/etc/pve`. It extracts the cluster files to an export directory and re-applies them to the RUNNING cluster through `pvesh`/`pveum`:
- storage definitions from storage.cfg (`pvesh create /storage`, falling back to `pvesh set /storage/` for definitions that already exist);
- datacenter options (datacenter.cfg written into pmxcfs, which replicates cluster-wide; the API has no whole-file endpoint);
- resource pools (`pveum pool add/modify` for definitions, then membership, with an optional allow-move guard when a pool lists guests);
- PCI, USB, and directory resource mappings;
-- VM and CT configs: before any guest mutation, SAFE loads the cluster-wide inventory with `pvesh get /cluster/resources --type vm --output-format=json`. An unavailable, malformed, incomplete, or ambiguous inventory fails the whole selected guest batch closed. A VMID owned by another node, or present with a different guest type, is reported and skipped; SAFE never moves it. Existing guests on the current node are updated with `pvesh set` under `/nodes//qemu|lxc//config` (minus create-only keys); if that fails, the staged conf is written into pmxcfs only after `status/current` explicitly reports `stopped`. A VMID absent cluster-wide is registered on the current node by writing the conf into pmxcfs (config only - disks are not part of a config restore).
+- VM and CT configs: before any guest mutation, SAFE loads the cluster-wide inventory with `pvesh get /cluster/resources --type vm --output-format=json`. An unavailable, malformed, incomplete, or ambiguous inventory fails the whole selected guest batch closed. A VMID owned by another node, or present with a different guest type, is reported and skipped; SAFE never moves it. Existing guests on the current node are updated with `pvesh set` under `/nodes//qemu|lxc//config` (minus create-only keys); a recognized schema refusal allows file fallback only after `status/current` explicitly reports `stopped`. Other API errors do not qualify. With a running or unverified guest after a schema refusal, ProxSave may retry the API with refused keys removed. A VMID absent cluster-wide is registered on the current node by writing the conf into pmxcfs (config only - disks are not part of a config restore).
-Use SAFE when the node or cluster is up and you want to merge the backed-up configuration back in without touching the live database. SAFE needs `pvesh` on PATH; without it, it logs a skip and applies nothing.
+Use SAFE for confirmed applies without replacing the whole database. These operations still change live state, sometimes cluster-wide. Guest confirmation covers the eligible batch from the selected source node, not individual guests. SAFE needs `pvesh` on PATH; without it, it logs a skip and applies nothing.
If the backup's VM/CT configs are stored under a node name that does not match the current host (a hostname change), SAFE handles it for you: it warns, and either auto-selects the single exported node or asks which exported node to import the guest configs from. The chosen configs are applied to the current node. You do not need to copy `/etc/pve/nodes/...` by hand.
@@ -225,12 +252,9 @@ Older versions of this guide showed the "stopping PVE services / unmounting /etc
### Offline storage: mount guards
-If a datastore or storage mountpoint is offline during a restore (its device is not mounted, so the path resolves to the root filesystem), ProxSave bind-mounts a read-only guard over it from `/guards` (`/opt/proxsave/guards` by default), so the restore cannot write onto the root disk and be shadowed later when the real storage mounts. The guard is a runtime bind mount: it disappears when the real storage mounts on top, and it is gone after a reboot. Current versions no longer set a persistent `chattr +i` flag. To clear leftover guards once storage is back online:
+If a datastore or storage mountpoint is offline during a restore (its device is not mounted, so the path resolves to the root filesystem), ProxSave bind-mounts a read-only guard over it from `/guards` (`/opt/proxsave/guards` by default), so the restore cannot write onto the root disk and be shadowed later when the real storage mounts. The guard is a runtime bind mount: it is shadowed when the real storage mounts on top, and it is gone after a reboot. Current versions no longer set a persistent `chattr +i` flag. To clear leftover guards once storage is back online:
-```bash
-proxsave --cleanup-guards # remove leftover guards
-proxsave --cleanup-guards --dry-run # preview only
-```
+Choose **Recovery > Cleanup guards** in the dashboard. See [CLI reference](CLI_REFERENCE.md) for direct entry.
In the dashboard the same operation is `Recovery > Cleanup guards`: a read-only check
first (green when there is nothing to clean, yellow with a count when guards are
@@ -242,6 +266,10 @@ present), then `Apply` for the real removal.
If your restore scope includes the network category (FULL, SYSTEM BASE, or a CUSTOM selection, not STORAGE), ProxSave remaps interface names by hardware identity and applies the config with an armed auto-rollback: it arms a 180-second timer, reloads networking, and reverts automatically unless you confirm with `COMMIT` in time. Run that step from the local console or IPMI, not over SSH, since it can change the active IP. The firewall, HA, and access-control applies use the same armed 180-second rollback.
+### Incomplete stages and apply warnings
+
+Sensitive configuration is applied only from a complete stage. If stage extraction fails, ProxSave discards it and skips staged consumers, including network installation, firewall, HA and notification repair. Normal file extraction, fstab changes and SAFE operations may already have changed the host. This guard does not make the whole restore transactional. Read the session log and verify each applied category before retrying or rolling back.
+
### The safety backup
Before overwriting anything, ProxSave writes a safety backup of the current configuration to `/restore//restore_backup_.tar.gz` (`/opt/proxsave/restore/...` by default) and keeps it, outside `/tmp` so that it survives the reboot the restore recommends. At the end it prints where it is:
@@ -251,7 +279,7 @@ Safety backup preserved at: /opt/proxsave/restore/20251120_143052/restore_backup
Safety backup - kept until removed, ProxSave never deletes it
```
-If any staged step fails, the run ends with `Restore completed with warnings.` rather than aborting, and this safety backup is your rollback.
+If any staged step fails, the run ends with `Restore completed with warnings.` rather than aborting, and the safety backup preserves selected pre-restore files. It is not a complete reversal of API operations. Follow [manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites) before using it; never extract it blindly over a live cluster database.
---
@@ -384,14 +412,14 @@ echo "3. pvecm status to verify" >> /root/ROLLBACK.txt
- Node failed, needs cluster database restored
- No other nodes to coordinate with
-### Complexity: ★☆☆☆☆ (Low)
+### Complexity: Low
### Prerequisites
-- ✅ Backup available with `pve_cluster` category
-- ✅ Root access to node
-- ✅ Network connectivity working
-- ✅ Hostname matches backup (or willing to change it)
+- Backup available with `pve_cluster` category
+- Root access to node
+- Network connectivity working
+- Hostname matches backup (or willing to change it)
### Procedure
@@ -405,25 +433,22 @@ hostname
# 2. Check PVE installed
dpkg -l | grep proxmox-ve
-# 3. Verify no cluster membership
+# 3. Inspect current cluster status
pvecm status
-# Expected: "cluster not ready - no quorum?" or similar
+# A standalone host without corosync.conf has no Corosync cluster status.
+# "No quorum" alone does not prove that the host is standalone.
```
+Confirm that the host was standalone before the failure. If `/etc/pve` is not
+mounted, a missing `corosync.conf` does not establish that it had no cluster configuration.
+
#### Step 2: Run Restore Workflow
Open the dashboard and choose `Restore`:
-```bash
-proxsave
-```
+Choose **Tools > Restore** in the dashboard. See [CLI reference](CLI_REFERENCE.md) for direct entry.
-On a headless or console-only node, or when the menu cannot render, call the workflow
-directly. Either form works from any directory:
-
-```bash
-proxsave --restore
-```
+For direct entry when the dashboard cannot render, see [CLI reference](CLI_REFERENCE.md).
#### Step 3: Interactive Selection
@@ -435,7 +460,7 @@ Select backup source:
[1] Primary backup path
Select: 1
-Available backups:
+- backups:
[1] backup-pve01-20251120-143052.bundle.tar
Select: 1
@@ -496,7 +521,7 @@ Safety backup - kept until removed, ProxSave never deletes it
ProxSave stops `pve-ha-lrm`, `pve-ha-crm`, `pve-cluster`, `pvedaemon`, `pveproxy`, `pvestatd`, unmounts `/etc/pve`, extracts `/var/lib/pve-cluster/` (config.db), then restarts `pve-cluster`, `pvedaemon`, `pveproxy`, `pvestatd`, `pve-ha-crm`, `pve-ha-lrm` before the remaining steps of the restore. It does not print a per-service checkmark line for each one. No `/etc/pve` files are written directly: config.db owns them, so `/etc/pve` is repopulated from the restored database a moment after pmxcfs remounts, not by the file-extraction phase.
-Had you chosen SAFE, this step would instead apply what the selected categories actually exported, through `pvesh` on the running cluster, with no service stop and no config.db write. Note what STORAGE mode does not carry: the VM/CT configs live in `pve_config_export`, which is export-only and is stripped from STORAGE, so none are applied. `storage.cfg` and `datacenter.cfg` belong to `storage_pve` and are still applied through `pvesh`, as are pools and resource mappings. Use FULL, or CUSTOM including `pve_config_export`, when you want the guest configs applied.
+Had you chosen SAFE, this step would instead apply what the selected categories actually exported, through `pvesh` on the running cluster, without stopping PVE services or replacing config.db. Note what STORAGE mode does not carry: the VM/CT configs live in `pve_config_export`, which is export-only and is stripped from STORAGE, so none are applied. `storage.cfg` and `datacenter.cfg` belong to `storage_pve` and are still applied through `pvesh`, as are pools and resource mappings. Use FULL, or CUSTOM including `pve_config_export`, when you want the guest configs applied.
#### Step 5: Verification
@@ -514,7 +539,8 @@ ls -la /etc/pve/
# 3. Check cluster status
pvecm status
-# Expected: Single node cluster, quorate
+# A standalone installation may have no corosync.conf and no cluster status.
+# For an actual one-member cluster, check its configured votes and quorum.
# 4. Verify storage accessible
pvesm status
@@ -551,12 +577,13 @@ cat /etc/pve/vzdump.cron
### Success Criteria
-✅ All services running
-✅ `/etc/pve` mounted and populated
-✅ `pvecm status` shows healthy single-node cluster
-✅ Storage accessible
-✅ Web interface working
-✅ VM/CT configs visible
+- All services running
+- `/etc/pve` mounted and populated
+- Standalone host: recovered configuration visible under `/etc/pve`; no Corosync status required
+- Configured one-member cluster: `pvecm status` shows the expected membership and quorum
+- Storage accessible
+- Web interface working
+- VM/CT configs visible
---
@@ -568,15 +595,15 @@ cat /etc/pve/vzdump.cron
- Need to rebuild entire cluster from backup
- Want to restore cluster configuration
-### Complexity: ★★★★☆ (High)
+### Complexity: High
### Prerequisites
-- ✅ Complete backup of one cluster node
-- ✅ Fresh PVE installed on all nodes (or clean nodes)
-- ✅ Nodes have correct hostnames
-- ✅ Network connectivity between nodes
-- ✅ Time synchronization working (NTP)
+- Complete backup of one cluster node
+- Fresh PVE installed on all nodes (or clean nodes)
+- Nodes have correct hostnames
+- Network connectivity between nodes
+- Time synchronization working (NTP)
### Procedure
@@ -592,9 +619,9 @@ hostname
# reboot
# 2. Run restore (STORAGE or FULL mode)
-# Dashboard: run bare `proxsave` and pick Restore. The flag below is the
-# headless/console equivalent.
-proxsave --restore
+# Run bare proxsave and choose Tools > Restore in the dashboard.
+# Direct entry options are in CLI_REFERENCE.md.
+# Dashboard action: Tools > Restore
# Select: [2] STORAGE only
# At the cluster prompt choose RECOVERY: the primary is offline, so this
# restores the full config.db. SAFE would apply configs via the API without
@@ -602,7 +629,7 @@ proxsave --restore
# 3. Verify primary node working
pvecm status
-# Should show single-node cluster
+# Restored membership can still list the old peers; quorum is not automatic.
# 4. Check corosync configuration
cat /etc/pve/corosync.conf
@@ -611,56 +638,18 @@ cat /etc/pve/corosync.conf
#### Phase 2: Clean Corosync Configuration
-**On PRIMARY NODE**:
+A database from a multi-node cluster retains its membership. Recovering it on one
+host does not establish quorum or turn it into a standalone installation.
-```bash
-# 1. Edit corosync.conf to remove dead nodes
-vi /etc/pve/corosync.conf
-
-# Example before:
-# nodelist {
-# node {
-# name: pve01
-# nodeid: 1
-# quorum_votes: 1
-# ring0_addr: 192.168.1.101
-# }
-# node {
-# name: pve02 ← Dead node
-# nodeid: 2
-# quorum_votes: 1
-# ring0_addr: 192.168.1.102
-# }
-# }
-
-# Example after (if rebuilding fresh):
-# nodelist {
-# node {
-# name: pve01
-# nodeid: 1
-# quorum_votes: 1
-# ring0_addr: 192.168.1.101
-# }
-# }
-
-# 2. Update expected votes for single node
-# Update quorum section:
-# quorum {
-# provider: corosync_votequorum
-# expected_votes: 1 ← Change to 1
-# }
-
-# 3. Restart corosync and cluster
-systemctl restart corosync
-systemctl restart pve-cluster pvedaemon pveproxy
-
-# 4. Set expected votes
-pvecm expected 1
-
-# 5. Verify primary healthy
-pvecm status
-# Should show: Quorate, 1 node
-```
+Keep all former members powered off or isolated from both cluster communication and
+shared workloads. Inspect `pvecm status`, the restored `corosync.conf`, node IDs and
+expected votes. If membership changes or temporary quorum recovery are necessary,
+follow the [official Proxmox node-removal and quorum procedure](https://pve.proxmox.com/pve-docs/pvecm-plain.html)
+for that version and state. Reducing expected votes is not a general fix for a
+network partition and must not allow competing members to write independently.
+
+Proceed only after one authoritative cluster state is established and verified.
+Do not delete the mounted `/etc/pve` tree to reset a node.
#### Phase 3: Add Secondary Nodes
@@ -669,7 +658,7 @@ pvecm status
```bash
# 1. Ensure fresh PVE installation
# - No existing cluster membership
-# - No data in /etc/pve or /var/lib/pve-cluster/
+# - No existing guests; preserve the fresh installation's own pmxcfs files
# 2. Set correct hostname
hostnamectl set-hostname pve02 # Or pve03, etc.
@@ -772,13 +761,13 @@ pct config 200
### Success Criteria
-✅ All nodes show in `pvecm nodes`
-✅ Cluster is quorate
-✅ Corosync communication working
-✅ Storage accessible on all nodes
-✅ `/etc/pve` syncing across nodes (test by editing file)
-✅ Web interface accessible on all nodes
-✅ VMs/CTs can be migrated between nodes
+- All nodes show in `pvecm nodes`
+- Cluster is quorate
+- Corosync communication working
+- Storage accessible on all nodes
+- `/etc/pve` syncing across nodes (test by editing file)
+- Web interface accessible on all nodes
+- VMs/CTs can be migrated between nodes
---
@@ -791,20 +780,20 @@ pct config 200
- Other nodes still operational
- Need to restore failed node
-### Complexity: ★★★☆☆ (Medium)
+### Complexity: Medium
### Prerequisites
-- ✅ Other cluster nodes still running
-- ✅ Cluster has quorum without failed node
-- ✅ Backup of failed node available
-- ✅ Fresh PVE installed on replacement hardware
+- Other cluster nodes still running
+- Cluster has quorum without failed node
+- Backup of failed node available
+- Fresh PVE installed on replacement hardware
### Procedure
#### Step 1: Remove Dead Node from Cluster
-**On ANY WORKING NODE**:
+**On a surviving, quorate node**, after the failed node is powered off and prevented from rejoining:
```bash
# 1. Check current cluster state
@@ -819,8 +808,8 @@ pvecm delnode pve02
pvecm nodes
# Dead node should not appear
-# 4. Update expected votes if needed
-pvecm expected
+# 4. Verify the surviving cluster still has its intended quorum
+pvecm status
```
#### Step 2: Prepare Replacement Node
@@ -873,23 +862,9 @@ pvesm status
**On REPLACEMENT NODE** (optional - if you need node-specific configs):
-```bash
-# Use CUSTOM mode to restore only specific categories
-# (Dashboard: Restore; the flag is the headless equivalent.)
-proxsave --restore
-
-# Select: [4] CUSTOM selection
-# Toggle:
-# - [ ] PVE Cluster Configuration ← DO NOT select (already from cluster)
-# - [X] Network Configuration ← Select if needed
-# - [X] SSH Configuration ← Select if needed
-# - [X] Custom Scripts ← Select if needed
-# - [X] ZFS Configuration ← Select if node had ZFS
+Run `proxsave` without arguments and choose **Tools > Restore**, then choose **Custom**. Leave **PVE Cluster Configuration** (`pve_cluster`) unselected. Consider only the node-local categories required for this replacement, such as network, SSL, SSH and system services, and inspect every selected path. Review and apply network changes from a local console or IPMI; they can replace the active address and disconnect SSH.
-# Type "RESTORE" to proceed
-```
-
-**Important**: Never run a RECOVERY cluster restore on a node that is still in the cluster; it overwrites config.db and can corrupt the cluster. On a member of a quorate cluster with other nodes online, ProxSave refuses RECOVERY (`Cluster RECOVERY refused - quorate cluster, N nodes online: ...`). The conservative choice is to leave `PVE Cluster Configuration` unselected here. If you do select it, ProxSave prompts SAFE vs RECOVERY, and on a live member SAFE is the only correct answer (it applies configs via the API and never writes config.db).
+**Important**: Never run a RECOVERY cluster restore on a node that is still in the cluster; it overwrites config.db and can corrupt the cluster. On a member of a quorate cluster with other nodes online, ProxSave refuses RECOVERY (`Cluster RECOVERY refused - quorate cluster, N nodes online: ...`). The conservative choice is to leave `PVE Cluster Configuration` unselected here. If you do select it, ProxSave prompts SAFE vs RECOVERY, and on a live member SAFE is the applicable mode (its confirmed API applies change live configuration without replacing config.db).
#### Step 6: Migrate VMs/CTs to Replacement Node
@@ -907,30 +882,19 @@ pct migrate pve02-new --restart
#### Step 7: Cleanup
-**On REPLACEMENT NODE** (after verification):
-
-```bash
-# If you want to rename node back to original name
-# (Only if all VMs/CTs migrated off):
-
-# 1. Leave cluster
-pvecm delnode pve02-new
-
-# 2. Change hostname
-hostnamectl set-hostname pve02
-reboot
-
-# 3. Re-join cluster
-pvecm add
-```
+Keep the replacement's chosen hostname after it has joined. Renaming a joined node
+is not a `delnode`/rename/rejoin shortcut. Choose its final name before installation
+and joining. If replacement under another name is required later, move or back up
+its workloads, power it off, and remove it from a surviving cluster member using
+the [official procedure](https://pve.proxmox.com/pve-docs/pvecm-plain.html).
### Success Criteria
-✅ Replacement node shows in `pvecm nodes`
-✅ Cluster is quorate
-✅ Storage accessible on replacement node
-✅ Can migrate VMs/CTs to/from replacement node
-✅ No errors in `journalctl -u corosync`
+- Replacement node shows in `pvecm nodes`
+- Cluster is quorate
+- Storage accessible on replacement node
+- Can migrate VMs/CTs to/from replacement node
+- No errors in `journalctl -u corosync`
---
@@ -942,14 +906,14 @@ pvecm add
- Want to preserve cluster configuration
- Clean installation on new hardware
-### Complexity: ★★★☆☆ (Medium)
+### Complexity: Medium
### Prerequisites
-- ✅ Backup from old hardware
-- ✅ New hardware with PVE installed
-- ✅ Network connectivity configured
-- ✅ Old hardware shut down (to avoid conflicts)
+- Backup from old hardware
+- New hardware with PVE installed
+- Network connectivity configured
+- Old hardware shut down (to avoid conflicts)
### Procedure
@@ -960,7 +924,7 @@ pvecm add
```bash
# 1. Create fresh backup
# Dashboard equivalent: run bare `proxsave` and pick Backup.
-proxsave --backup
+# Dashboard action: Backup
# 2. Document configuration
pvecm status > /root/old-cluster-status.txt
@@ -993,6 +957,13 @@ reboot
#### Step 2: Restore on New Hardware
+Choose the recovery route first. If a multi-node cluster survives, use
+[Scenario 3](#scenario-3-multi-node-cluster-with-failed-master): join a clean
+replacement and restore node-local settings. Shutting down the old hardware alone
+does not isolate the replacement from the other live members. The RECOVERY example
+below applies only to a standalone recovery or an explicitly isolated full-cluster
+recovery; do not use it before joining a surviving cluster.
+
```bash
# 1. Copy proxsave tool to new hardware
# scp -r /opt/proxsave root@new-hardware:/opt/
@@ -1001,13 +972,13 @@ reboot
mkdir -p /opt/proxsave/backup
mv /root/*.bundle.tar /opt/proxsave/backup/
-# 3. Run restore (dashboard: bare `proxsave` -> Restore; the flag is the
-# headless equivalent on a freshly installed node)
-proxsave --restore
+# 3. Run bare proxsave and choose Tools > Restore in the dashboard.
+# Direct entry options are in CLI_REFERENCE.md.
+# Dashboard action: Tools > Restore
# Select: [2] STORAGE only (or FULL)
-# At the cluster prompt choose RECOVERY: the old hardware is shut down, so
-# this node is offline/isolated and RECOVERY restores the full config.db.
+# Choose RECOVERY only for the isolated recovery route described above.
+# Do not restore an old cluster database before joining a surviving cluster.
# Type "RESTORE" to confirm
```
@@ -1022,8 +993,8 @@ ls -la /etc/pve/
# 3. Check cluster status
pvecm status
-# Expected: Single-node cluster (if standalone)
-# Or: Part of multi-node cluster (if rejoining)
+# A standalone host need not have Corosync cluster status.
+# A restored cluster member retains the backed-up membership; verify quorum separately.
# 4. Verify storage
pvesm status
@@ -1068,15 +1039,14 @@ systemctl enable zfs-import@.service
#### Step 5: Rejoin Cluster (if multi-node)
-**If node was part of multi-node cluster**:
-
-```bash
-# On other nodes: Remove old node first
-pvecm delnode
+A node with a restored cluster database or guest definitions is not a clean joining
+node. Joining replaces `/etc/pve` with the surviving cluster's configuration, and
+Proxmox requires no existing guests on the joining host.
-# On new hardware: Join cluster
-pvecm add
-```
+If the cluster survives, follow Scenario 3 from a fresh installation. If you are
+rebuilding the entire cluster, follow Scenario 2 and join fresh secondary nodes only
+after the authoritative recovered node is ready. Preserve any recovered guest data
+before changing routes; do not erase local configuration as a shortcut.
#### Step 6: Restore VM/CT Disk Images
@@ -1095,12 +1065,12 @@ zfs send old-pool/vm-100-disk-0 | zfs recv new-pool/vm-100-disk-0
### Success Criteria
-✅ Services running on new hardware
-✅ Cluster configuration restored
-✅ Storage accessible (with path adjustments)
-✅ Network connectivity working
-✅ Web interface accessible
-✅ Can create/manage VMs/CTs
+- Services running on new hardware
+- Cluster configuration restored
+- Storage accessible (with path adjustments)
+- Network connectivity working
+- Web interface accessible
+- Can create/manage VMs/CTs
---
@@ -1112,11 +1082,11 @@ zfs send old-pool/vm-100-disk-0 | zfs recv new-pool/vm-100-disk-0
- Backup from `pve01`, restoring to `pve02`
- May cause cluster conflicts
-### Complexity: ★★☆☆☆ (Medium)
+### Complexity: Medium
### Option A: Change Hostname to Match Backup
-**Recommended if**: You want exact restoration
+**Recommended if**: You are preparing a fresh, isolated replacement before it joins any cluster. Set its hostname and `/etc/hosts` before whole-database recovery; do not rename a live cluster member this way.
```bash
# 1. Change hostname before restore
@@ -1130,111 +1100,53 @@ vi /etc/hosts
reboot
# 4. Run restore normally (dashboard: bare `proxsave` -> Restore)
-proxsave --restore
+# Dashboard action: Tools > Restore
```
### Option B: Update Configuration After Restore
-**Recommended if**: You want to keep new hostname
+Use the new name from installation onward. Prefer SAFE with FULL, or CUSTOM including
+`pve_config_export`, to review the exported node and apply eligible guest settings
+without importing the old cluster membership.
#### Step 1: Restore with Mismatched Hostname
-```bash
-# Run restore (works despite the hostname mismatch)
-# Dashboard: bare `proxsave` -> Restore; the flag is the headless equivalent.
-proxsave --restore
-
-# Select: [2] STORAGE only
-# At the cluster prompt choose RECOVERY: this restores the backup's config.db,
-# which still references the OLD hostname. You fix those references in the
-# steps below.
-#
-# SAFE is NOT a shortcut here. In STORAGE mode the selected categories carry no
-# guest configs at all (pve_config_export is export-only and STORAGE strips
-# export-only categories), so SAFE would redirect the cluster database to the
-# export directory, apply no VM/CT config, and never run the node-name mismatch
-# handling. The API-apply path with the node-name handling needs FULL, or CUSTOM
-# with pve_config_export selected.
-```
+Open **Tools > Restore** in the dashboard, select the configuration scope and choose SAFE when the
+cluster payload is included. The workflow can ask which exported node to use when
+the current hostname differs. STORAGE alone excludes the export-only guest payload.
#### Step 2: Fix Corosync Configuration
-```bash
-# 1. Edit corosync.conf
-vi /etc/pve/corosync.conf
-
-# Find nodelist section:
-# nodelist {
-# node {
-# name: pve01 ← Change this
-# nodeid: 1
-# quorum_votes: 1
-# ring0_addr: 192.168.1.101
-# }
-# }
-
-# Update to new hostname:
-# nodelist {
-# node {
-# name: pve02 ← New hostname
-# nodeid: 1
-# quorum_votes: 1
-# ring0_addr: 192.168.1.101 ← Update IP if needed
-# }
-# }
-
-# 2. Restart services
-systemctl restart corosync
-systemctl restart pve-cluster pvedaemon pveproxy
-```
+Do not turn a database restore into a rename by editing a node's name in place.
+For a surviving cluster, join a clean replacement with its final name and use the
+cluster's membership. For isolated recovery, review the version-specific Proxmox
+membership procedure before bringing any old peers back.
#### Step 3: Update Node Directory
-```bash
-# 1. Check /etc/pve/nodes/
-ls -la /etc/pve/nodes/
-# Will show old hostname directory
-
-# 2. The cluster filesystem auto-creates the new hostname directory, but a
-# RECOVERY restore put the guest configs under the OLD node name.
-
-# 3. Copy the node-specific configs to the new node directory.
-# (Had you used SAFE instead, ProxSave would have re-created the VM/CT configs
-# on the current node automatically and this copy would not be needed.)
-cp -r /etc/pve/nodes/pve01/* /etc/pve/nodes/pve02/
-
-# 4. Verify new directory
-ls -la /etc/pve/nodes/pve02/
-```
+Inspect `/etc/pve/nodes/` and the cluster-wide guest inventory. SAFE skips VMIDs owned
+by another node; it does not move them. Do not recursively copy an old node's entire
+directory to the new name. Use the Proxmox guest migration/recovery procedure for
+existing VMIDs, and review any manual single-guest change with its disks and ownership.
#### Step 4: Update Certificates
-```bash
-# Regenerate certificates for new hostname
-pvecm updatecerts
-
-# Restart services
-systemctl restart pvedaemon pveproxy
-```
+Verify `/etc/hostname`, `/etc/hosts`, DNS and the intended management address. Apply
+the appropriate Proxmox certificate procedure after the final node identity is
+established. WebAuthn users may need re-enrollment if the UI origin changes.
#### Step 5: Remove Old Node References
-```bash
-# If single-node cluster, remove old node:
-pvecm delnode pve01
-
-# Verify
-pvecm nodes
-# Should show only new hostname
-```
+Remove an obsolete node only from a surviving cluster member after its workloads
+are accounted for and the old machine cannot reconnect. Follow the
+[official cluster procedure](https://pve.proxmox.com/pve-docs/pvecm-plain.html).
### Success Criteria
-✅ `pvecm status` shows new hostname
-✅ Corosync.conf references new hostname
-✅ Certificates match new hostname
-✅ `/etc/pve/nodes//` exists
-✅ Web interface accessible
+- The running hostname and management certificates match the intended identity
+- Guest VMIDs have the intended single owner and their storage is available
+- Cluster members agree on membership and quorum; a standalone host has no unintended cluster membership
+- The web interface works and restore logs contain no unexplained skipped applies
---
@@ -1315,11 +1227,10 @@ ls -la /etc/pve/
pvesm status
# Expected: All storage "active"
-# Check storage paths exist
-for storage in $(pvesm status | awk 'NR>1 {print $1}'); do
- echo "Checking $storage:"
- pvesm path $storage
-done
+# Inspect configured storage definitions and their paths
+pvesh get /storage --output-format json
+# For an actual volume ID, pvesm path resolves its filesystem path:
+# pvesm path 'local:iso/example.iso'
# Verify ZFS pools (if applicable)
zpool status
@@ -1451,48 +1362,48 @@ echo
# 1. Services
echo "1. Checking services..."
-systemctl is-active pve-cluster >/dev/null 2>&1 && echo " ✓ pve-cluster running" || echo " ✗ pve-cluster FAILED"
-systemctl is-active pvedaemon >/dev/null 2>&1 && echo " ✓ pvedaemon running" || echo " ✗ pvedaemon FAILED"
-systemctl is-active pveproxy >/dev/null 2>&1 && echo " ✓ pveproxy running" || echo " ✗ pveproxy FAILED"
+systemctl is-active pve-cluster >/dev/null 2>&1 && echo " Yes pve-cluster running" || echo " No pve-cluster FAILED"
+systemctl is-active pvedaemon >/dev/null 2>&1 && echo " Yes pvedaemon running" || echo " No pvedaemon FAILED"
+systemctl is-active pveproxy >/dev/null 2>&1 && echo " Yes pveproxy running" || echo " No pveproxy FAILED"
echo
# 2. Cluster Status
echo "2. Checking cluster..."
if pvecm status | grep -q "Quorate.*Yes"; then
- echo " ✓ Cluster is quorate"
+ echo " Yes Cluster is quorate"
else
- echo " ✗ Cluster NOT quorate"
+ echo " No Cluster NOT quorate"
fi
echo
# 3. Filesystem
echo "3. Checking /etc/pve..."
if mount | grep -q "/etc/pve type fuse.pmxcfs"; then
- echo " ✓ /etc/pve mounted"
+ echo " Yes /etc/pve mounted"
else
- echo " ✗ /etc/pve NOT mounted"
+ echo " No /etc/pve NOT mounted"
fi
echo
# 4. Storage
echo "4. Checking storage..."
if pvesm status >/dev/null 2>&1; then
- echo " ✓ Storage accessible"
+ echo " Yes Storage accessible"
INACTIVE=$(pvesm status | grep -c "inactive" || true)
if [ "$INACTIVE" -gt 0 ]; then
- echo " ⚠ $INACTIVE storage(s) inactive"
+ echo " Warning: $INACTIVE storage(s) inactive"
fi
else
- echo " ✗ Storage check FAILED"
+ echo " No Storage check FAILED"
fi
echo
# 5. API
echo "5. Checking API..."
if pvesh get /version >/dev/null 2>&1; then
- echo " ✓ API responding"
+ echo " Yes API responding"
else
- echo " ✗ API NOT responding"
+ echo " No API NOT responding"
fi
echo
@@ -1500,9 +1411,9 @@ echo
echo "=== Summary ==="
FAILED=$(systemctl --failed --no-legend | wc -l)
if [ "$FAILED" -eq 0 ]; then
- echo " ✓ No failed services"
+ echo " Yes No failed services"
else
- echo " ✗ $FAILED failed service(s)"
+ echo " No $FAILED failed service(s)"
systemctl --failed --no-legend
fi
@@ -1537,29 +1448,22 @@ journalctl -xe -u pve-cluster
**Common Causes & Solutions**:
**1. config.db corrupted**:
-```bash
-# Rollback to safety backup
-systemctl stop pve-cluster
-# TIMESTAMP: the directory of the restore to undo, from its "Safety backup preserved at:" line
-tar -xzf /opt/proxsave/restore/TIMESTAMP/restore_backup_*.tar.gz -C /
-systemctl start pve-cluster
-```
+
+Use the [manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites)
+for the exact restore session. Do not extract a safety archive while pmxcfs is
+running, and account for HA before stopping the cluster filesystem.
**2. /etc/pve still mounted**:
-```bash
-umount -f /etc/pve
-systemctl restart pve-cluster
-```
-**3. Permissions wrong**:
+Inspect `findmnt /etc/pve` and the service log. Confirm the HA-aware shutdown before
+unmounting; do not force-unmount a live cluster as a generic repair.
-ProxSave preserves each restored file's owner and mode from the backup archive, so it does not hardcode these. The following is manual Proxmox advice for the case where the ownership on `/var/lib/pve-cluster` is wrong for some other reason:
+**3. Permissions wrong**:
-```bash
-chown -R root:www-data /var/lib/pve-cluster
-chmod 0640 /var/lib/pve-cluster/config.db
-systemctl restart pve-cluster
-```
+ProxSave preserves backed-up ownership and modes. For a manual database recovery,
+follow the [official pmxcfs procedure](https://pve.proxmox.com/pve-docs/pmxcfs-plain.html),
+which requires `config.db` mode `0600`. Check that specific file and its expected
+owner; do not recursively assign `/var/lib/pve-cluster` to `root:www-data`.
---
@@ -1571,24 +1475,14 @@ pvecm status
# Output: "not quorate"
```
-**For Single-Node Cluster**:
-```bash
-pvecm expected 1
-pvecm status
-# Should now show "quorate"
-```
-
-**For Multi-Node Cluster**:
-```bash
-# Check how many nodes are online
-pvecm nodes
-
-# Set expected votes to number of online nodes
-pvecm expected
+Check the intended membership, online members, Corosync links and qdevice state
+before changing votes. A standalone host and a one-member Corosync cluster are
+different configurations. Loss of quorum during a partition protects shared state.
-# Example: 3-node cluster, 2 nodes online:
-pvecm expected 2
-```
+Do not set expected votes to the number of nodes you can currently see. Temporary
+quorum overrides belong only to a documented recovery with the other writers
+excluded. Follow the [official Proxmox quorum procedure](https://pve.proxmox.com/pve-docs/pvecm-plain.html)
+and verify consistent membership before reconnecting recovered nodes.
---
@@ -1609,12 +1503,14 @@ corosync-quorumtool -l
# Should show all nodes with votes
```
-**2. Restart cluster services**:
+**2. Inspect service logs**:
```bash
-systemctl restart corosync
-systemctl restart pve-cluster
+journalctl -u corosync -u pve-cluster --since "30 minutes ago"
```
+A restart is not a substitute for resolving quorum or connectivity. If stopping
+pmxcfs is necessary, follow the HA-aware shutdown prerequisites first.
+
**3. Check network connectivity**:
```bash
# Test cluster network
@@ -1627,16 +1523,11 @@ iptables -L -n | grep -E "(5404|5405)"
# Corosync ports should not be blocked
```
-**4. Force config sync**:
-```bash
-# On working node:
-systemctl restart pve-cluster
+**4. Do not force synchronization by deleting a lock**:
-# On problem node:
-systemctl stop pve-cluster
-rm -f /var/lib/pve-cluster/.pmxcfs.lockfile
-systemctl start pve-cluster
-```
+Check the service and quorum errors first. Removing `.pmxcfs.lockfile` does not
+establish which cluster state is authoritative. Use the supported Proxmox recovery
+procedure for the diagnosed failure.
---
@@ -1732,100 +1623,29 @@ curl -k https://localhost:8006
**Situation**: Everything broken, cluster services won't start, /etc/pve won't mount
-#### Nuclear Option 1: Force Restore from Safety Backup
+#### Option 1: Review the Safety Backup
-```bash
-# 1. Stop everything
-systemctl stop pve-cluster pvedaemon pveproxy pvestatd
-killall pmxcfs 2>/dev/null
+Start with the exact archive and logs from the failed restore. Follow the
+[manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites),
+including graceful HA shutdown before taking pmxcfs down. The safety archive is a
+file-level recovery aid, not a complete undo of cluster-wide API operations.
-# 2. Force unmount /etc/pve
-umount -f /etc/pve 2>/dev/null
-fusermount -uz /etc/pve 2>/dev/null
+#### Option 2: Recover config.db from a Verified Backup
-# 3. Restore from safety backup
-# TIMESTAMP: the directory of the restore to undo, from its "Safety backup preserved at:" line
-tar -xzf /opt/proxsave/restore/TIMESTAMP/restore_backup_*.tar.gz -C /
+Prefer ProxSave's RECOVERY workflow on an isolated replacement. If a manual database
+recovery is necessary, verify and decrypt the complete backup first, unwrap its
+bundle, and select the actual inner archive by name. Do this in a private working
+directory before touching the live database. Use the
+[official pmxcfs recovery procedure](https://pve.proxmox.com/pve-docs/pmxcfs-plain.html)
+with the correct hostname, stopped services, unmounted `/etc/pve` and database mode
+`0600`. Do not bypass a failed HA shutdown with `killall` or a forced unmount.
-# 4. Restart services
-systemctl start pve-cluster
-sleep 5
-systemctl start pvedaemon pveproxy pvestatd
-
-# 5. Verify
-pvecm status
-```
-
-#### Nuclear Option 2: Manual config.db Restoration
-
-```bash
-# 1. Stop and disable services
-systemctl stop pve-cluster pvedaemon pveproxy pvestatd
-systemctl disable pve-cluster
+#### Option 3: Reinstall and Apply Selected Configuration
-# 2. Force unmount
-umount -f /etc/pve 2>/dev/null
-
-# 3. Backup current (broken) config
-mv /var/lib/pve-cluster /var/lib/pve-cluster.broken
-
-# 4. Manually extract config.db from backup.
-# The bundle is an UNCOMPRESSED tar holding the inner archive and its sidecars under
-# basename-only names, so it has no ./var/... paths of its own: unwrap it first.
-mkdir -p /tmp/psrecover /var/lib/pve-cluster
-tar -xf /path/to/backup.bundle.tar -C /tmp/psrecover
-ls /tmp/psrecover # -backup-. (plus .age if encrypted), .metadata, .sha256
-
-# follows the compression actually used, not the configured one: .tar.xz (default),
-# .tar.gz (gzip/pigz, and the fallback whenever the requested tool is missing), .tar.bz2,
-# .tar.lzma, .tar.zst, or plain .tar for COMPRESSION_TYPE=none. Take the name from ls:
-ARCHIVE=$(ls /tmp/psrecover/*-backup-* | grep -Ev '\.(metadata|sha256)$' | head -1)
-
-# If the archive ends in .age, decrypt it first (dashboard: Decrypt):
-# proxsave --decrypt
-# or, with the age CLI:
-# age -d -i /path/to/key.txt -o "${ARCHIVE%.age}" "$ARCHIVE" && ARCHIVE="${ARCHIVE%.age}"
-
-# Then pull the cluster database out of the inner archive.
-# Entries are stored with a leading ./ so there are four components to strip, and
-# -xf lets tar auto-detect the compression whatever COMPRESSION_TYPE was.
-tar -xf "$ARCHIVE" --strip-components=4 \
- -C /var/lib/pve-cluster \
- ./var/lib/pve-cluster/
-
-# 5. Fix permissions
-chown -R root:www-data /var/lib/pve-cluster
-chmod 0640 /var/lib/pve-cluster/config.db
-
-# 6. Re-enable and start
-systemctl enable pve-cluster
-systemctl start pve-cluster
-sleep 5
-systemctl start pvedaemon pveproxy pvestatd
-```
-
-#### Nuclear Option 3: Fresh Start with Config Import
-
-```bash
-# 1. Backup everything
-tar -czf /root/emergency-backup-$(date +%s).tar.gz \
- /etc/pve/ /var/lib/pve-cluster/ 2>/dev/null || true
-
-# 2. Remove cluster completely
-pvecm delnode $(hostname) # If multi-node
-apt remove --purge proxmox-ve pve-cluster pvedaemon pveproxy
-
-# 3. Reinstall cluster components
-apt install proxmox-ve
-
-# 4. Restore selective configs manually
-# Use export-only /etc/pve contents from backup
-# Copy configs one by one after reviewing
-
-# 5. Recreate cluster (if multi-node)
-pvecm create # On first node
-pvecm add # On other nodes
-```
+When the installation cannot be repaired, preserve guest data and the available
+configuration evidence, then install Proxmox afresh. Select the surviving-cluster
+or full-rebuild scenario before importing configuration. Purging the Proxmox
+packages on a broken live node is not a documented substitute for that process.
---
@@ -1840,31 +1660,18 @@ pvecm add # On other nodes
**Resolution**:
-```bash
-# On ALL nodes:
-
-# 1. Stop cluster communication
-systemctl stop corosync pve-cluster
-
-# 2. Choose ONE node as "source of truth" (primary)
-
-# On PRIMARY node:
-# 3. Start services
-systemctl start corosync pve-cluster
-pvecm expected 1
-
-# On SECONDARY nodes:
-# 4. Remove old cluster data
-rm -rf /etc/pve /etc/corosync
-rm -rf /var/lib/pve-cluster/*
-
-# 5. Rejoin cluster
-pvecm add
-
-# 6. Verify all nodes synced
-pvecm status # On all nodes
-# Should show consistent state
-```
+1. Use console access to establish the workload and storage state of every partition.
+ Prevent competing nodes from running or writing the same guests.
+2. Keep conflicting members isolated and preserve their configuration evidence.
+ Choose an authoritative state based on the recovery plan, not merely the first
+ node that starts.
+3. Follow the [official Proxmox cluster recovery procedure](https://pve.proxmox.com/pve-docs/pvecm-plain.html)
+ for membership and quorum. Stopping pmxcfs also requires the HA precautions in
+ [manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites).
+4. Recover the authoritative node, then reintroduce clean replacement nodes using
+ the prerequisites in Scenario 2. Never delete a mounted `/etc/pve` tree to force
+ a join, and do not lower quorum independently on competing partitions.
+5. Verify agreed membership, guest ownership, storage and HA before restoring service.
---
@@ -1876,7 +1683,7 @@ pvecm status # On all nodes
# Cluster Status
pvecm status # Overall cluster status
pvecm nodes # List cluster nodes
-pvecm expected # Set expected votes
+# Quorum overrides require the reviewed recovery procedure above
# Corosync
corosync-cfgtool -s # Corosync status
@@ -1884,19 +1691,18 @@ corosync-quorumtool -s # Quorum status
corosync-quorumtool -l # Quorum list
# Services
-systemctl restart pve-cluster pvedaemon pveproxy
systemctl status pve-cluster
journalctl -u pve-cluster --since "1 hour ago"
# Filesystem
mount | grep pve # Check /etc/pve mount
ls -la /etc/pve/ # List cluster configs
-umount -f /etc/pve # Force unmount
+findmnt /etc/pve # Inspect the mount without changing it
# Storage
pvesm status # Storage status
pvesm scan zfs # Scan ZFS pools
-pvesm scan nfs # Scan NFS exports
+pvesm scan nfs nfs.example.com # Replace with your NFS server
# HA
ha-manager status # HA service status
@@ -1942,12 +1748,12 @@ journalctl -u corosync # Corosync logs
## Final Notes
**Remember**:
-- ✅ Always test recovery procedures on non-production systems first
-- ✅ Keep multiple backup copies in different locations
-- ✅ Document your specific cluster setup and customizations
-- ✅ Verify backups regularly (don't wait for disaster)
-- ✅ Practice recovery scenarios at least annually
-- ✅ Keep this guide accessible (print or offline copy)
+- Always test recovery procedures on non-production systems first
+- Keep multiple backup copies in different locations
+- Document your specific cluster setup and customizations
+- Verify backups regularly (don't wait for disaster)
+- Practice recovery scenarios at least annually
+- Keep this guide accessible (print or offline copy)
**When in Doubt**:
1. Stop and document current state
diff --git a/docs/COLLECTOR_ARCHITECTURE.md b/docs/COLLECTOR_ARCHITECTURE.md
index b4720120..3148a9a4 100644
--- a/docs/COLLECTOR_ARCHITECTURE.md
+++ b/docs/COLLECTOR_ARCHITECTURE.md
@@ -1,5 +1,7 @@
# Collector Architecture
+For operator-facing coverage and collection settings, use the [backup guide](BACKUP_GUIDE.md#what-proxsave-backs-up). This document describes how collectors are implemented
+
This document describes the current backup collector design after the refactor to
recipes and fine-grained bricks.
diff --git a/docs/CONFIGURATION.md b/docs/CONFIGURATION.md
index 320257ff..56d38669 100644
--- a/docs/CONFIGURATION.md
+++ b/docs/CONFIGURATION.md
@@ -1,6 +1,6 @@
# Configuration Reference
-Complete reference for all 200+ configuration variables in `configs/backup.env`.
+Reference for configuration keys, accepted values, defaults and constraints in `configs/backup.env`. Template examples and compiled fallbacks are distinguished where they differ.
Most installs never need to open this file. Run `proxsave` with no arguments on a terminal
and the dashboard's configuration form covers the settings a typical host changes; the
@@ -39,6 +39,8 @@ ask about, and for hosts with no terminal.
---
+
+
## Editing the configuration from the dashboard
`proxsave`, typed bare on a terminal, opens the dashboard. `Maintenance` -> `Install` ->
@@ -88,7 +90,7 @@ Four other dashboard rows change configuration or configuration-adjacent state:
| Dashboard row | What it does |
|---|---|
-| `Maintenance` -> `Upgrade` -> `Check config` | merges variables the shipped template has and your file lacks (`--upgrade-config`), after showing you the list |
+| `Maintenance` -> `Upgrade` -> `Check config` | reviews and applies the embedded template merge, including added and retired keys |
| `Maintenance` -> `New key` | generates the AGE recipient that `AGE_RECIPIENT_FILE` points at |
| `Daemon` -> `Install` / `Disable` | switches `SCHEDULER_MODE` between `daemon` and `cron`, and turns `HEALTHCHECK_ENABLED` on and back off with it |
| `Diagnostic Checks` -> `Telegram` / `Healthchecks` | verifies what the notification and monitoring variables above actually do, without running a backup |
@@ -105,18 +107,22 @@ plain text, not shell (see [Personal scripts](#personal-scripts-daemon) for what
## Configuration File Location
**Default**: `configs/backup.env`, resolved under the detected install directory (`BASE_DIR`), so typically `/opt/proxsave/configs/backup.env`.
-**Custom**: specify with `--config`. An absolute path is used as-is; a relative path is joined onto the install directory, not the current working directory.
+**Custom profiles**: use the configuration flag described in the [CLI reference](CLI_REFERENCE.md#run-backup). An absolute path is used as-is; a relative path resolves against the installation directory. Passing this flag bypasses the dashboard and selects the normal backup path unless another operation is explicitly selected. Interactive prompts may still occur in operations that require them.
-```bash
-# Use custom config file
-proxsave --config /path/to/my-backup.env
-```
+---
-`--config` is an automation flag: passing it, like passing any flag, skips the dashboard,
-so a run with a custom configuration file is always a non-interactive one. Use it for a
-second profile (a snapshot or fixture run, for example) rather than for everyday editing.
----
+### Verify a configuration change
+
+Save an independent copy before manual editing. The file is parsed as data, not executed as shell: do not source it to test it. Ordinary duplicate assignments use the last value; the four list/recipient keys named in the integrity reference concatenate. Environment overrides apply only to the fixed allowlist, and `BASE_DIR` is detected from the executable. See the [environment reference](CLI_REFERENCE.md#environment-variables) before relying on a per-run override.
+
+Open **Post-install > Check** to review diagnostics and optional collectors. This simulation writes logs but does not create or upload archives. Review warnings and then follow the [first backup verification](BACKUP_GUIDE.md#run-and-verify-your-first-backup) using **Backup**. A check can reveal configuration problems; it does not verify recoverability.
+
+If loading fails, the dashboard opens before configuration is loaded, so **Install > Edit install** remains available. Keep configuration in a regular file: template merges replace a symlink rather than writing through to its target. Review the [upgrade effects](INSTALL.md#what-gets-updated) before applying Check config.
+
+The remaining sections are the complete key reference. Use [storage](STORAGE.md), [cloud setup](CLOUD_STORAGE.md), [encryption](ENCRYPTION.md), [scheduling](DAEMON.md) and [notifications](NOTIFICATIONS.md) for operational procedures.
+
+
## Configuration integrity check
@@ -129,7 +135,7 @@ DEBUG Configuration integrity: file=/opt/proxsave/configs/backup.env lines=47
DEBUG Configuration integrity: template assigns 182 variables and documents 33 more as commented examples
DEBUG Configuration integrity: variables that may repeat without discarding: AGE_RECIPIENT, BACKUP_BLACKLIST, BACKUP_EXCLUDE_PATTERNS, CUSTOM_BACKUP_PATHS
DEBUG Configuration integrity: 0 duplicated, 0 absent, 0 unknown, 0 legacy (duration=3.1ms)
-INFO ✓ Configuration file ok
+INFO Configuration file ok
```
It reports four things, one line each, and their levels differ because the facts differ:
@@ -147,7 +153,7 @@ WARNING HEALTHCHECK_UPDATES_ID is absent and falls back to its default
WARNING LOCAL_BACKUP_PATH is the legacy name for BACKUP_PATH and both are set; LOCAL_BACKUP_PATH wins and BACKUP_PATH has no effect
INFO RCLONE_REMOTE is the legacy name for CLOUD_REMOTE and is still read; rename it to CLOUD_REMOTE when convenient
INFO PERSONAL_SCRIPTS_PRERUN is not a known variable and is ignored
-WARNING ⚠ Configuration file: 1 duplicated, 1 absent, 1 unknown, 2 legacy
+WARNING Configuration file: 1 duplicated, 1 absent, 1 unknown, 2 legacy
```
### Duplicated: the one that loses data
@@ -189,11 +195,11 @@ binary with an older template and never sees this finding. Seeing it means the b
Fix it from the dashboard with `Maintenance` -> `Upgrade` -> `Check config`: the check lists
the variables it would add and only offers `Apply` when there is something to add, and the
-apply takes a backup it can roll back to. The same two steps from a script are
-`--upgrade-config-dry-run` (shows what it would add) and `--upgrade-config` (adds it).
+apply takes a backup it can roll back to. For automation, use the separate
+[configuration upgrade reference](CLI_REFERENCE.md#configuration-upgrade).
-A missing variable falls back to its default, so nothing you wrote is lost and the backup itself
-is unaffected. The finding is still a `WARNING`, and like every other warning it promotes the run
+A missing variable uses the parser's fallback for that setting. Review the default and
+the proposed merge before relying on the resulting behavior. The finding is still a `WARNING`, and like every other warning it promotes the run
to exit 1: a host that upgraded the binary without merging its `backup.env` exits 1 on every run,
and the Healthchecks backup check goes down with it, until the merge is run. Merge the
file, either way, or expect that state until you do.
@@ -224,7 +230,7 @@ COLORIZE_STEP_LOGS=true # true | false (requires USE_COLOR=true)
# Debug level
DEBUG_LEVEL=standard # standard | advanced | extreme
-# Dry-run mode (test without changes)
+# Diagnostic simulation: writes logs, skips archive creation and upload
# A restore is refused while this is true: it cannot run without modifying the system
DRY_RUN=false # true | false
@@ -315,18 +321,19 @@ own environment, and a name neither defines is replaced by nothing, silently. `$
a `$` at the end of the value, or one before a character that is neither a letter, a digit, an
underscore nor one of those, survives. Rename the script rather than fighting the expansion.
-These scripts belong to you. ProxSave starts them and reports nothing about them: their output
-is discarded, their exit code is ignored, they never fail a backup or change its exit code, and
-they appear in no log, notification, ping or metric. Each is killed after 10 minutes, on every
-path but the abandoned-child unwind described in [DAEMON.md](DAEMON.md). They run
-only under the daemon, never under a manual `proxsave --backup` or a cron-mode run.
+These scripts run only under the daemon, never under a manual `proxsave --backup` or
+a cron-mode run. Their output is discarded and their exit status does not change the
+backup result. The normal wait is limited to 10 minutes; shutdown and abandoned-child
+handling have different wait and cleanup rules. See [Personal scripts](DAEMON.md#personal-scripts-around-a-run).
-The one line ProxSave will ever log about them is a refusal at daemon start: the path must not
-traverse a symlink, it and every directory above it must belong to root (or the user the
-daemon runs as), the script must not be writable by group or others, and a group- or
-other-writable directory must carry the sticky bit. A path that fails is disabled for that
-daemon with a `WARNING` naming the variable, the path and the reason (see
-[SECURITY.md](SECURITY.md)).
+At startup, each path is classified as not configured, ready, ready with warning, or
+refused. The script must be a regular executable owned by root or the daemon UID and
+must not be writable by group or others. Symlinked paths and loosely writable
+non-sticky directories are refused. A safely permissioned ancestor owned by another
+UID can be accepted with a trust warning, since that owner can replace descendants.
+The execution-time gate checks the opened script again before each launch. Startup
+advisories and refusals, and execution-time refusals, are recorded in the daemon log;
+see [DAEMON.md](DAEMON.md) for the full policy and diagnostic commands.
---
@@ -518,8 +525,8 @@ SET_BACKUP_PERMISSIONS=false # true = apply chown/chmod on ba
- Checks for suspicious open ports
- Scans for suspicious processes
- Validates file hashes to detect tampering
-- **If `CONTINUE_ON_SECURITY_ISSUES=false`**: Backup aborts on any issue
-- **If `CONTINUE_ON_SECURITY_ISSUES=true`**: Issues logged as warnings, backup continues
+- **If `CONTINUE_ON_SECURITY_ISSUES=false`**: Security errors abort the backup; warning-only results do not
+- **If `CONTINUE_ON_SECURITY_ISSUES=true`**: Findings are logged and the run continues despite security errors; later backup phases can still fail
#### Process List Merge Behavior
@@ -768,7 +775,7 @@ PREFILTER_MAX_FILE_SIZE_MB=8 # Skip prefilter for files >8MB
### What These Do
-- **Deduplication**: Detects duplicate data blocks (reduces storage)
+- **Deduplication**: Finds identical whole files within the collected tree and replaces duplicates with links before archiving; this is not block deduplication across backup runs
- **Prefilter**: Applies safe, semantic-preserving normalization to small text/JSON files to improve compression (e.g. removes CR from CRLF line endings and minifies JSON). It does **not** reorder, de-indent, or strip structured configuration files, and it avoids touching Proxmox/PBS structured config paths (e.g. `etc/pve/**`, `etc/proxmox-backup/**`).
### Prefilter (`ENABLE_PREFILTER`): details and risks
@@ -882,16 +889,16 @@ sudo mount -t cifs //192.168.0.10/backup /mnt/nas-backup -o credentials=/root/.s
**2. Then configure SECONDARY_PATH**:
```bash
-SECONDARY_PATH=/mnt/nas-backup # ✓ Correct - uses mounted path
+SECONDARY_PATH=/mnt/nas-backup # Correct - uses mounted path
SECONDARY_LOG_PATH=/mnt/nas-logs # Optional
```
### What NOT to Do
```bash
-SECONDARY_PATH=192.168.0.10/backup # ✗ WRONG - network address
-SECONDARY_PATH=//server/share # ✗ WRONG - UNC path
-SECONDARY_PATH=\\192.168.0.10\backup # ✗ WRONG - Windows path
+SECONDARY_PATH=192.168.0.10/backup # WRONG - network address
+SECONDARY_PATH=//server/share # WRONG - UNC path
+SECONDARY_PATH=\\192.168.0.10\backup # WRONG - Windows path
```
**For direct network access without mounting:** Use `CLOUD_REMOTE` with rclone instead (see [Cloud Storage](#cloud-storage-rclone) section).
@@ -985,10 +992,10 @@ CLOUD_LOG_PATH=B+K/BACKUP/marcellus/logs
### When Auto-Fallback Helps
Automatic with `false`:
-- ✅ **Cloudflare R2** with restricted API tokens (no list permissions)
-- ✅ **S3-compatible providers** with minimal token permissions
-- ✅ **Backblaze B2**, **Wasabi** write-only tokens
-- ✅ **First-time setup** with uncertain token permissions
+- **Cloudflare R2** with restricted API tokens (no list permissions)
+- **S3-compatible providers** with minimal token permissions
+- **Backblaze B2**, **Wasabi** write-only tokens
+- **First-time setup** with uncertain token permissions
### When to Set CLOUD_WRITE_HEALTHCHECK=true
@@ -1038,7 +1045,7 @@ MAX_PBS_TARGET_BACKUPS=15 # snapshots kept by retention (0 = no retention)
MIN_DISK_SPACE_PBS_GB=1 # free space required on the datastore
```
-- `proxmox-backup-client` must be installed; nothing about PBS is stored in `backup.env`.
+- `proxmox-backup-client` must be installed. Target selection and retention settings are stored in `backup.env`; connection details and credentials are reused from the selected PVE storage.
- Retention keeps the newest `MAX_PBS_TARGET_BACKUPS` snapshots of the group (with `RETENTION_POLICY=gfs`, the same GFS rules as the other destinations). A failed upload deletes nothing.
- When the storage has an encryption key, the snapshot and the log are encrypted with it. When it has none they are uploaded unencrypted, and step [7] says so (`Encryption: none, storage has no key`).
- ProxSave sets no timeout on the PBS client. Under cron nothing stops a hung upload; the daemon's `MAX_RUN_DURATION` watchdog does, so the daemon is the recommended scheduler with PBS.
@@ -1047,27 +1054,11 @@ MIN_DISK_SPACE_PBS_GB=1 # free space required on the datastore
## Storage Comparison
-Quick comparison to help you choose the right storage configuration:
-
-| Feature | SECONDARY_PATH | CLOUD_REMOTE (rclone) |
-|---------|----------------|----------------------|
-| **Path Type** | Filesystem-mounted paths only | Network addresses via rclone |
-| **Valid Examples** | `/mnt/nas-backup`
`/media/usb-drive`
`/backup/secondary` | `CLOUD_REMOTE=GoogleDrive` + `CLOUD_REMOTE_PATH=/backups`
`CLOUD_REMOTE=b2` + `CLOUD_REMOTE_PATH=/pbs-prod`
`CLOUD_REMOTE=minio` + `CLOUD_REMOTE_PATH=/pbs` |
-| **Invalid Examples** | ❌ `192.168.0.10/folder`
❌ `//server/share`
❌ `\\192.168.0.10\backup` | N/A (handles network directly) |
-| **Network Storage** | Must mount first via NFS/CIFS/SMB | Direct access via rclone config |
-| **Setup Complexity** | Simple (native Go copy) | Moderate (requires rclone config) |
-| **Dependencies** | None | Requires rclone installed |
-| **Speed** | Fast (local filesystem I/O) | Depends on network/cloud |
-| **Use Case** | - Local USB drives
- Pre-mounted NAS shares
- Additional local disks | - Cloud storage (GDrive, S3, B2)
- LAN servers (MinIO, S3)
- Remote storage without mounting |
-| **Failure Behavior** | Non-critical (warns, continues) | Non-critical (warns, continues) |
-| **Setup Example** | `sudo mount 192.168.0.10:/share /mnt/nas`
`SECONDARY_PATH=/mnt/nas` | `rclone config` (create "minio" remote)
`CLOUD_REMOTE=minio` + `CLOUD_REMOTE_PATH=/backups` |
+Destination selection and mounting procedures are maintained in the [storage guide](STORAGE.md). Secondary storage uses an existing local filesystem path; cloud storage uses an rclone remote and does not require a filesystem mount.
### Decision Guide
-- **Use SECONDARY_PATH if**: You have local storage (USB drive) OR willing to mount network shares to filesystem
-- **Use CLOUD_REMOTE if**: You want direct network access (no mounting) OR using cloud providers OR using S3-compatible storage
-
-**See** [docs/CLOUD_STORAGE.md](CLOUD_STORAGE.md) **for complete rclone setup guide.**
+Use the [destination guide](STORAGE.md) for local disks, NAS mounts and native PBS. Use the [cloud guide](CLOUD_STORAGE.md) for remote credentials and accessible archive retrieval.
---
@@ -1204,23 +1195,15 @@ Set the tiers in the same edit as the policy.
### Benefits
-- Better historical coverage than simple count
-- Automatic time distribution
-- ISO 8601 week numbering (standard)
-- Efficient storage (fewer total backups)
+Operational retention planning and verification are maintained in the [storage guide](STORAGE.md). The key definitions and GFS deletion constraints above remain authoritative here.
### Example Output
-```text
-GFS classification -> daily: 7/7, weekly: 4/4, monthly: 12/12, yearly: 2/3, to_delete: 15
-Deleting old backup: pbs-backup-20220115-120000.tar.xz (created: 2022-01-15 12:00:00)
-Cloud storage retention applied: deleted 15 backups (logs deleted: 15), 26 backups remaining
-```
+Read the retention classification and deletion messages in the saved run log, then verify the remaining archive set on every enabled destination.
### Storage Comparison
-- **Simple**: `MAX_CLOUD_BACKUPS=1095` for 3 years daily = 1095 backups
-- **GFS**: `DAILY=7, WEEKLY=4, MONTHLY=12, YEARLY=3` = ~26 backups (97% storage reduction!)
+A GFS tier selects distinct archives after higher-priority tiers; the sum of configured tier counts is not a guaranteed archive total. See [retention planning](STORAGE.md).
---
@@ -1258,7 +1241,7 @@ AGE_RECIPIENT_FILE=${BASE_DIR}/identity/age/recipient.txt
### Encryption
- Uses AGE (age-encryption.org)
-- Streaming encryption (no plaintext on disk)
+- Streaming encryption avoids a plaintext archive on disk; collected files are staged in plaintext before archiving, as described in [Plaintext staging](ENCRYPTION.md#plaintext-staging)
- Supports multiple recipients
- Passphrase or key-based
@@ -1547,6 +1530,10 @@ Exactly one collector variable is on the dashboard's configuration form:
`BACKUP_FIREWALL_RULES`, as the **Backup firewall rules** toggle. Every other variable in
this section is edited here.
+Collector toggles control specific collection paths. The same information may also
+be present in a database or another selected path. Review the exclusions below and
+inspect a real backup before relying on a toggle to exclude sensitive data.
+
### PVE-Specific
```bash
@@ -1588,9 +1575,11 @@ CEPH_CONFIG_PATH=/etc/ceph # Ceph config directory
BACKUP_VM_CONFIGS=true # VM/CT config files
```
-**Note (PVE snapshot behavior)**: ProxSave snapshots `PVE_CONFIG_PATH` for completeness. When a PVE feature is disabled, proxsave also excludes its well-known files from that snapshot to avoid "still included via full directory copy" surprises (e.g. `qemu-server/` + `lxc/` for `BACKUP_VM_CONFIGS=false`, `firewall/` + `host.fw` for `BACKUP_PVE_FIREWALL=false`, `user.cfg`/`domains.cfg` plus the credential files `priv/shadow.cfg`/`priv/token.cfg`/`priv/tfa.cfg` for `BACKUP_PVE_ACL=false` (ACLs are stored in `user.cfg` on PVE), `jobs.cfg` + `vzdump.cron` for `BACKUP_PVE_JOBS=false`, `corosync.conf` (and `config.db` capture) for `BACKUP_CLUSTER_CONFIG=false`).
+**Note (PVE snapshot behavior)**: ProxSave snapshots `PVE_CONFIG_PATH` for completeness. When a PVE feature is disabled, proxsave also excludes its well-known files from that snapshot to avoid "still included via full directory copy" surprises (e.g. `qemu-server/` + `lxc/` for `BACKUP_VM_CONFIGS=false`, `firewall/` + `host.fw` for `BACKUP_PVE_FIREWALL=false`, `user.cfg`/`domains.cfg` plus the credential files `priv/shadow.cfg`/`priv/token.cfg`/`priv/tfa.cfg` for `BACKUP_PVE_ACL=false` (ACLs are stored in `user.cfg` on PVE), `jobs.cfg` + `vzdump.cron` for `BACKUP_PVE_JOBS=false`, `corosync.conf` for `BACKUP_CLUSTER_CONFIG=false`).
-> **Security note**: `/etc/pve` is a pmxcfs mount backed by the cluster database `config.db`. Setting `BACKUP_PVE_ACL=false` removes the flat `priv/*` credential files from the snapshot, but the same secrets remain inside `config.db` (captured when `BACKUP_CLUSTER_CONFIG=true`). To exclude PVE access-control secrets from the backup entirely, set both `BACKUP_PVE_ACL=false` and `BACKUP_CLUSTER_CONFIG=false`. ProxSave logs a WARNING during backup when this combination leaves secrets in `config.db`.
+The pmxcfs database `config.db` is collected independently on every PVE host, including standalone hosts and configurations with `BACKUP_CLUSTER_CONFIG=false`. That flag controls Corosync configuration and cluster-specific data/runtime information. Missing Corosync files do not warn on a confirmed standalone host.
+
+> **Security note**: Setting `BACKUP_PVE_ACL=false` removes the flat access-control files and `priv/{shadow,token,tfa}.cfg` credentials from the `/etc/pve` snapshot, but the same secrets remain inside `config.db`. ProxSave logs a WARNING when these files are disabled and the database is not excluded. To exclude the database and its sidecars explicitly, add `config.db*` to `BACKUP_EXCLUDE_PATTERNS`. Disabling `BACKUP_CLUSTER_CONFIG` does not exclude the database. Excluding it removes the database recovery artifact; review that tradeoff and any custom paths that could collect another copy of the same data.
### PBS-Specific
@@ -1812,7 +1801,11 @@ BACKUP_BLACKLIST="
"
```
-**Format**: Bash-style heredoc, one path per line, `#` for comments.
+**Format**: A double-quoted multiline value, one path per line, with `#` comment lines. This is ProxSave configuration syntax, not a shell heredoc.
+
+Collecting a custom path does not automatically make it a restore category. FULL
+restore selects recognized categories present in the archive; additional files may
+require manual extraction and review. See [Restore Modes](RESTORE_GUIDE.md#restore-modes).
**Note (boot files)**: a custom path that brings in `/etc/default/grub`, `/etc/default/grub.d/`, `/etc/kernel/cmdline` or `/etc/kernel/proxmox-boot-uuids` is collected, but a restore never writes those files to the system: they name the backed-up host's root device, pool and ESPs, and go to the export directory with `proxsave_info`. The `boot` restore category carries the kernel parameters instead.
diff --git a/docs/DAEMON.md b/docs/DAEMON.md
index 1492416d..7cca5831 100644
--- a/docs/DAEMON.md
+++ b/docs/DAEMON.md
@@ -1,147 +1,240 @@
# Resident daemon
-The **resident daemon** is ProxSave's normal scheduler. New installs default to it; `cron` is the opt-out engine, still fully supported and still what a host reverted with `--daemon-remove` runs, but no longer the recommended one. The daemon schedules and supervises each backup, adds a hang watchdog, and reports to an external monitor so silent failures (a crash before notifying, a run that hangs, a host that is simply down) are caught by an external dead-man switch. Monitoring only transmits under the daemon: a host on cron reports nothing, whatever the `HEALTHCHECK_*` keys say.
+
+
+## Schedule and supervise backups
+
+The resident daemon schedules backups and reports to an external monitor. systemd keeps
+the service alive; the daemon chooses when backups run. It can report missed runs through
+monitoring even when the backup process cannot send a notification. Cron remains an
+alternative scheduler, but does not provide daemon monitoring or personal-script execution.
+
+### Choose the scheduler and schedule
+
+Run `proxsave` without arguments on an interactive terminal. For a new setup or an
+existing configuration, choose **Maintenance** > **Install** > **Edit install**.
+Review `Scheduler engine`, `Healthchecks`, `Notify level`, `Frequency` and `Run at`.
+Weekly schedules also have `Weekday`; monthly schedules have `Day of month`, limited
+to 1 through 28. The default schedule is daily at 02:00 in the host's local time.
+
+With the daemon selected, **Install** > **Edit install** prepares the service before
+the installation's monitoring check, installing it if missing. This path preserves
+the monitoring choice saved by the wizard.
+
+For an installed host, the **Daemon** group offers actions according to the configured
+engine:
+
+| Recorded engine | Available actions |
+| --- | --- |
+| cron | Install, Status |
+| daemon | Disable, Restart, Status |
+| Unreadable configuration | Status only |
+
+**Install** switches from cron to the daemon, enables monitoring, installs the service,
+removes owned cron entries and restarts the daemon. Do this outside a running backup:
+this installation action can stop a supervised run. It differs from **Restart**, which
+waits for a running backup rather than immediately cancelling it.
+
+**Disable** reverts to cron, records that preference and disables monitoring. It waits
+up to four minutes for the backup lock. If the run does not finish, or configuration
+cannot be read, it reports deferral and leaves the transition unapplied. Retry when
+idle or after fixing the configuration.
+
+### Prevent duplicate schedules
+
+Inspect the action's result screen. ProxSave removes cron lines whose executed command
+is named `proxsave` or `proxmox-backup`, including custom paths. A wrapper script with
+another name is outside that ownership rule. It can remain scheduled after the daemon
+is installed, and the action warns when an unowned schedule survives.
+
+Review root's crontab and any external scheduler or automation that starts backups.
+Remove an obsolete wrapper only after establishing what it does. On reversion, ProxSave
+writes its canonical cron line even if an unowned schedule remains; review the warning
+so both do not run. A backup lock can reject an overlapping run, but that is not a
+substitute for choosing one scheduler. Current upgrade migration respects an explicit
+`SCHEDULER_MODE`; legacy migration and finalize behavior are described in the
+[retrofit reference](#retrofit-existing-installs).
+
+### Check the effective schedule
+
+Choose **Daemon** > **Status**. Compare the running schedule with the configuration
+and read the synchronization verdict. Use **Re-check** to refresh the screen.
+A hand edit of schedule keys takes effect after restart, so a changed file can show
+`OUT OF SYNC` until you choose **Daemon** > **Restart**.
+
+In centralized monitoring mode a new frequency becomes effective after the monitoring
+server confirms the corresponding check period. Until confirmation, the daemon retains
+its previously confirmed frequency, or daily if none was confirmed. `PENDING` therefore
+requires checking the reason and effective schedule, not assuming the new frequency
+already runs. With self-hosted monitoring or monitoring disabled, the schedule applies
+locally; set your external backup check's period to match.
+
+Invalid hand-edited schedule values produce warnings and a daily fallback, at the valid
+configured time or 02:00 if the time is invalid. Correct the file and restart.
+There is no catch-up: a run missed while the host or service was down is skipped, and
+monitoring should alert on that absence.
+
+### Verify service and backup outcomes
+
+After switching engines or changing the schedule, check **Daemon** > **Status** for a
+running, reporting and aligned daemon. Then check the next scheduled backup's saved
+artifacts and the external monitor's event history. Status does not start a backup,
+execute personal scripts or prove that the next backup will succeed.
+
+An installation can defer restarting an existing daemon when a backup is running or
+the backup lock cannot be established safely. If the installer reports
+`configuration not applied; manual restart required`, let any backup finish and
+resolve any reported configuration error. Then choose **Daemon** > **Restart** and
+check **Daemon** > **Status** to verify that the new configuration is active.
+
+**Restart** waits up to four minutes for a supervised backup, then verifies a fresh,
+aligned daemon. An upgrade also attempts restart and verification; a deferred or failed
+restart can leave the old process running after the on-disk binary was replaced.
+Use the status screen to decide whether further action is needed. An external
+`systemctl restart` has no equivalent backup wait and can kill a run in progress.
+System service logs can be read outside the dashboard:
-Installing, disabling, restarting and inspecting the daemon are all reachable from the interactive dashboard, which is what `proxsave` with no arguments opens on a TTY. The `--daemon-*` flags do the same work without the TUI, for headless hosts, scripts and recovery. Both routes are in [Operating](#operating).
+```bash
+journalctl -u proxsave-daemon.service
+```
-This document covers the daemon itself. The monitoring side, which checks exist, what they cover, and how to configure the centralized or self-hosted monitor, is in [HEALTHCHECKS.md](HEALTHCHECKS.md).
+A dashboard **Backup** run is standalone. It can hand its outcome to a live daemon,
+but it does not exercise scheduled personal scripts or update scheduled per-channel
+notification sensors. With `BACKUP_ENABLED=false`, scheduled backups are skipped and
+no successful backup ping is invented; the liveness heartbeat continues.
-## Why
+### Set supervision and optional personal scripts
-A pure "notify only on failure" model is blind to the worst failures: the process cannot speak when it panics, is OOM-killed, hangs, or never starts. The daemon pushes to an **external** monitor that alarms on *silence*, so those cases are still caught.
+Advanced settings are hand edits of `configs/backup.env`. `MAX_RUN_DURATION` bounds a
+supervised run. A timed-out child receives SIGTERM and then SIGKILL after a 30-second
+grace. Review a timeout as a failed or hung run, not a completed backup.
-## What it does
+`PERSONAL_SCRIPT_PRE_RUN` and `PERSONAL_SCRIPT_POST_RUN` run only around daemon-supervised
+backups. Read the [personal-script policy](#personal-scripts-around-a-run) before using
+them: ownership, permissions, mount policy and startup trust decisions matter. Status
+shows the running snapshot separately from what a restart would load. A script refused
+by policy is not automatically made safe by a restart. These scripts do not run for
+cron or dashboard backups.
-- **Schedules** the backup itself (replacing the crontab entry): daily, weekly or monthly (`SCHEDULER_FREQUENCY`, on `SCHEDULER_WEEKDAY` or `SCHEDULER_MONTHDAY`) at the `SCHEDULER_TIME` ("Run at") time. See [Backup schedule](#backup-schedule). There is **no catch-up**: the next run is always computed forward from now, so a window missed because the host was off or the service was down is skipped rather than made up. That shows on the monitor as `proxsave-backup` going down, which is the intended signal.
-- **Supervises** each run as a child process (`proxsave --backup`) under a `MAX_RUN_DURATION` timeout. A run that overruns gets `SIGTERM`, then `SIGKILL` after a 30-second grace, and is reported as a **hang**.
-- **Reports** four families of monitored checks: daemon liveness, the backup outcome, release updates, and one per notification channel. See [HEALTHCHECKS.md](HEALTHCHECKS.md).
+An uninterruptible D-state child can survive termination. The daemon records persistent
+abandonment, suppresses further scheduled backups and marks liveness failed while it is
+outstanding. Restarting the daemon does not clear a living abandoned child. Fix the
+underlying mount or I/O problem; see [uninterruptible sleep](#caveat-uninterruptible-sleep-d-state)
+for cleanup and recovery limits.
-systemd (`proxsave-daemon.service`, `Restart=always`) is only the keep-alive supervisor; the daemon schedules internally.
+For a silent or failed monitor continue with
+[monitoring](HEALTHCHECKS.md#configure-and-verify-backup-monitoring).
+Automation flags and script exit codes belong in [CLI_REFERENCE.md](CLI_REFERENCE.md).
-### BACKUP_ENABLED=false
+
-When `BACKUP_ENABLED=false`, the daemon skips the scheduled run entirely: no child process, no backup-outcome ping, so `proxsave-backup` honestly goes down (no false green). The liveness heartbeat keeps signalling, so you can still tell the daemon is up.
+## Implementation appendix
-## Backup schedule
-
-The daemon reads `SCHEDULER_FREQUENCY`, `SCHEDULER_WEEKDAY`, `SCHEDULER_MONTHDAY` and `SCHEDULER_TIME` when it starts, and its journal reports the result in one block that ends with the outcome:
-
-```text
-Applying backup schedule...
- Frequency: weekly
- Weekday: Monday
- Time: 02:00
-✓ Backup schedule: applied
-daemon: next backup at 2026-10-05 02:00 (in 3d 15h5m53s)
-```
-
-- **Centralized monitor.** The frequency travels to ProxSave HC Server on the daemon's config poll, and the server moves the `proxsave-backup` check, and the periodic notify checks, to that period: 1 day, 7 days or 31 days, grace 1 hour ([HEALTHCHECKS.md](HEALTHCHECKS.md)). A new frequency applies only once the server confirms it. Until then the daemon keeps the frequency it last had confirmed (daily on a host that never had one confirmed), so the backup check never goes down for a run that was not due, and the block ends `⚠ Backup schedule: pending, no action needed` with an `In effect:` line and the reason (`ProxSave HC Server not reachable`, `not ready` or `did not confirm`). The daemon asks three times at start, then once per heartbeat (`HEALTHCHECK_HEARTBEAT_INTERVAL`, 5 minutes by default); the heartbeat that gets the confirmation prints the block again, applied, followed by the next backup. The confirmed frequency is kept in `daemon_state/.schedule_state.json`, so a restart while the server is unreachable keeps it.
-- **Self-hosted monitor, or healthchecks off.** The frequency applies at once. On your own server ProxSave does not manage the backup check's period: with a weekly or monthly schedule the block adds `Backup check: pinged weekly on your own server` (or `monthly`), and setting the check's period is up to you.
-- **An invalid value** (a frequency other than daily, weekly or monthly, a day of the month outside 1-28, a time that is not HH:MM) gets a WARNING block, `⚠ Backup schedule: not applied`, with one line per invalid value, before every backup until the value is fixed and the daemon restarted. The backup runs daily meanwhile, at `SCHEDULER_TIME`, or at 02:00 when the time itself is invalid. A variable that is missing or empty takes its default (daily, `mon`, `1`, `02:00`), and the day the frequency does not use is ignored.
-
-A change to these variables takes effect at the next daemon restart. Until then `--daemon-status` reports the schedule `OUT OF SYNC`; see [From the command line](#from-the-command-line).
-
-## Standalone backups: the SIGUSR1 handoff
-
-A backup run outside the daemon (by hand with `--backup`, from a cron line, or from the dashboard's **Backup** row) does not ping the monitor itself. The resident daemon is the sole pinger. Instead, a standalone run drops a handoff file (`.manual_backup_outcome.json`) and wakes the daemon with `SIGUSR1`; the daemon then pings the backup check with that run's outcome. A handoff older than 15 minutes is dropped without pinging (so a long-past run never flips the check), and if no live daemon is found nothing pings.
+## systemd unit
-## Binary alignment after an upgrade
+`proxsave-daemon.service` at `/etc/systemd/system/proxsave-daemon.service`:
-An in-place `--upgrade` replaces the on-disk binary without restarting the resident daemon, so the daemon can keep running the **old** code (systemd keeps the old process alive). ProxSave detects this hash-free: Linux blocks overwriting a running executable, so an upgrade unlinks it and `/proc//exe` ends in `" (deleted)"`, which alone proves the daemon is behind.
+```ini
+[Unit]
+Description=ProxSave backup daemon
+Documentation=https://github.com/tis24dev/proxsave
+After=network-online.target
+Wants=network-online.target
-`--upgrade`, the dashboard's **Upgrade**, and the dashboard's **Daemon** > **Restart** reconcile this with a restart-and-verify: they wait (bounded, up to 4 minutes) for any in-progress daemon-supervised backup to finish (deferring the restart, never killing the backup), restart the service, then poll until the daemon is back, aligned, and freshly started. `--daemon-status` and the dashboard's **Daemon** > **Status** report the same verdict: `behind - restart needed` from the flag, `BEHIND - RESTART NEEDED` on the dashboard screen, which puts every status keyword in ALL-CAPS.
+[Service]
+Type=simple
+ExecStart=/usr/local/bin/proxsave --daemon --config
+Restart=always
+RestartSec=10
-`--daemon-setup` does **not** do that. It restarts the unit immediately and then only polls until the daemon is alive with a readable alignment, accepting one that is still behind. If a daemon-supervised backup is running at that moment it is cancelled: the child gets SIGTERM, and SIGKILL if it does not stop within 30 seconds, and the run ends with no outcome ping, so the monitor sees a start that never finished. `--daemon-status` will not warn you: it reports liveness, unit state and binary alignment, never whether a backup is running. Check for the lock file under `LOCK_PATH`, or just run `--daemon-setup` outside the backup window.
+[Install]
+WantedBy=multi-user.target
+```
-## Operating
+`ExecStart` pins the same `backup.env` the install resolved (via `--config`), so the exact path in the generated unit is your install's config path.
-### From the dashboard
+## On-disk state files
-Run `proxsave` with no arguments on a TTY and the dashboard opens. Its **Daemon** group is the everyday route, and it is context-aware: it offers only the command that fits the engine currently recorded in `SCHEDULER_MODE`.
+The daemon coordinates through eight small files under `/daemon_state/` (a root-only directory, mode `0700`), all written atomically (temp file then rename, mode `0600`) and deliberately not made immutable so they can be rewritten:
-| Configured engine | Rows offered |
-|-------------------|--------------|
-| cron | **Install** (switch to the resident daemon scheduler), **Status** |
-| daemon | **Disable** (stop the daemon and revert to the cron scheduler), **Restart**, **Status** |
-| config unreadable | **Status** only |
+| File | Purpose |
+|------|---------|
+| `.daemon.pid` | the daemon's PID; the contract a standalone backup reads to send `SIGUSR1` |
+| `.daemon_info.json` | the running daemon's identity (pid, exec path, version, commit, start time), for display and the restart-verify freshness check |
+| `.daemon_runtime.json` | what the running daemon loaded at start (configuration path, personal-script verdicts), read by `--daemon-status` |
+| `.schedule_state.json` | the schedule the daemon started with, how healthchecks ran then, and the frequency ProxSave HC Server last confirmed |
+| `.healthcheck_status.json` | the last ping outcome per check, read back by the run phase to report real transmission; a corrupt file is quarantined to `.corrupt` and reset |
+| `.notify_results.json` | the backup child's per-channel notification severities, handed to the daemon to drive the `proxsave-notify-*` pings |
+| `.manual_backup_outcome.json` | a standalone run's outcome, handed off for the daemon to ping |
+| `.daemon_abandoned.json` | a backup child the kernel would not let the daemon reap: the orphan's pid and start time, the run id, and when it happened. See [the D-state caveat](#caveat-uninterruptible-sleep-d-state) |
-**Install** and **Disable** run the same operations as `--daemon-setup` and `--daemon-remove`, in-session, and report the outcome on a result screen instead of in the log. Console logging is muted while they run, so that screen is the only channel: it states what happened to the crontab (how many proxsave lines were removed, or that none were present), and it goes yellow rather than green when the host also carries a schedule ProxSave does not own.
+`.daemon.pid` and `.daemon_info.json` are written at startup and removed on shutdown.
+`.daemon_abandoned.json` is the exception that deliberately **survives** shutdown - that is its whole purpose - and is removed only once something shows backups can run again.
-**Restart** is the one action with no flag of its own. It waits (bounded, up to 4 minutes) for a daemon-supervised backup to finish before restarting, then polls until the daemon is back, aligned and freshly started. `systemctl restart proxsave-daemon.service` does none of that waiting and will kill a backup in flight.
+A ninth file in the same directory, `.daemon.lock`, is not state but the single-instance ownership lock (an advisory `flock`, mode `0600`). It stays on disk between runs; what matters is who holds the lock, not that the file exists.
-**Status** shows the same verdict `proxsave --daemon-status` prints, on a screen with a `Re-check` row that recomputes it, so you can restart the service elsewhere and watch it flip to aligned without leaving the dashboard.
+Before 0.41 these files lived in `/identity/`. The first start of a 0.41 daemon moves them, and `identity/` keeps only the server identity, the relay secret and the AGE keys. `--new-install` keeps `daemon_state/` like `identity/`.
-The scheduler engine itself is also editable from **Install** > **Edit install**, which re-runs the install wizard against the existing configuration: `Scheduler engine` is one of its fields. Monitoring lives under **Healthchecks** in the **Diagnostic Checks** group; see [HEALTHCHECKS.md](HEALTHCHECKS.md).
+## Configuration keys (`backup.env`)
-### From the command line
+```ini
+# Scheduler engine
+SCHEDULER_MODE=cron # cron | daemon. Raw template value; the wizard writes daemon by default
+SCHEDULER_FREQUENCY=daily # daily, weekly or monthly
+SCHEDULER_WEEKDAY=mon # weekly only: mon, tue, wed, thu, fri, sat or sun
+SCHEDULER_MONTHDAY=1 # monthly only: 1-28
+SCHEDULER_TIME=02:00 # HH:MM ("Run at")
+MAX_RUN_DURATION=1h # watchdog hard timeout for one backup
+BACKUP_ENABLED=true # false: daemon skips the scheduled run (backup check goes down)
-The flags are the same operations without the TUI, for headless hosts, cron jobs, scripts, and recovery when the dashboard cannot run:
+# Personal scripts: your own, started around each run (daemon only)
+PERSONAL_SCRIPT_PRE_RUN= # path to a script started before the run (works only with the daemon)
+PERSONAL_SCRIPT_POST_RUN= # path to a script started after the run, whatever the outcome (works only with the daemon)
-```bash
-proxsave --daemon-status # read-only status + exit code (see below)
-proxsave --daemon-status --log-level debug # include script-path ownership/mode evidence
-systemctl status proxsave-daemon.service # is it running?
-journalctl -u proxsave-daemon.service -f # follow its log
-proxsave --daemon-setup # switch to the daemon
-proxsave --daemon-remove # revert to cron
+# Monitoring: enabled here, configured in HEALTHCHECKS.md
+HEALTHCHECK_ENABLED=false # forced true by --daemon-setup, the dashboard's Install, auto-migration
```
-`--daemon` itself is not an operator command: it is what `proxsave-daemon.service` puts in its `ExecStart`. Running it by hand does not talk to the daemon systemd owns, and it does not become a second one either: an ownership lock (`/daemon_state/.daemon.lock`) makes it warn that another daemon already owns this install and exit `16`.
+The `HEALTHCHECK_*` keys that decide *where* and *what* the daemon reports live in [HEALTHCHECKS.md](HEALTHCHECKS.md).
-`proxsave --daemon-status` prints a combined verdict and is meant for scripts:
+See [CONFIGURATION.md](CONFIGURATION.md) for the full variable reference and [CLI_REFERENCE.md](CLI_REFERENCE.md) for the `--daemon-*` flags.
-```text
-Daemon status:
-Scheduler mode:
-Daemon service (proxsave-daemon.service): installed | not installed
-Service state (systemctl is-active):
-Running version: ()
-Binary alignment: aligned | BEHIND (restart needed) | unknown
-Running daemon configuration:
-Running daemon loaded at:
-Backup schedule:
- Daemon now: DAILY () | WEEKLY ( at ) | MONTHLY (day at ) | NOT RUNNING | UNAVAILABLE ()
- Configuration: DAILY (...) | WEEKLY (...) | MONTHLY (...) | INVALID () | UNKNOWN:
- Synchronization: IN SYNC | OUT OF SYNC () | PENDING () | NOT APPLICABLE | UNKNOWN ()
-Personal pre-run script:
- Daemon now: NOT RUNNING | NOT CONFIGURED | READY | READY WITH WARNING | REFUSED | UNAVAILABLE
- Configuration: NOT CONFIGURED () | READY | READY WITH WARNING | REFUSED | UNKNOWN
- Synchronization: NOT APPLICABLE | IN SYNC | OUT OF SYNC | PATH STATE CHANGED SINCE STARTUP | UNKNOWN
-Personal post-run script:
- Daemon now: NOT RUNNING | NOT CONFIGURED | READY | READY WITH WARNING | REFUSED | UNAVAILABLE
- Configuration: NOT CONFIGURED () | READY | READY WITH WARNING | REFUSED | UNKNOWN
- Synchronization: NOT APPLICABLE | IN SYNC | OUT OF SYNC | PATH STATE CHANGED SINCE STARTUP | UNKNOWN
-```
-`Running version:` and `Binary alignment:` appear only when their daemon evidence is available, the two `Running daemon` lines only when the live daemon published its runtime state. The backup schedule and the two personal-script sections always appear.
-`Backup schedule` compares the schedule the daemon runs (`Daemon now`, from `daemon_state/.schedule_state.json`) with the one `backup.env` configures now. `OUT OF SYNC (restart the daemon to apply current schedule configuration)` means the file changed after the daemon started. `PENDING (ProxSave switches to weekly automatically; no action needed)` means the daemon is waiting for ProxSave HC Server to confirm the frequency and runs the last confirmed one meanwhile ([Backup schedule](#backup-schedule)); it switches by itself. A file changed after the start reads `OUT OF SYNC` even while a confirmation is pending, because only a restart brings the new value. `INVALID` names the invalid values, the same reasons the daemon's `not applied` block gives. `UNAVAILABLE` on `Daemon now` means the live daemon left no usable schedule state (none, one from an earlier start, or one that cannot be read).
+## Detailed reference
-In the personal-script sections, `Daemon now` is the state captured and applied at daemon startup; `Configuration` is what a restart would load and how that path looks now. `NOT CONFIGURED` means the setting was empty, `READY` means the path passed without an advisory, `READY WITH WARNING` means it remains enabled under an explicit administrator trust decision, and `REFUSED` includes the exact refusal reason. If a live daemon has not published matching runtime state, the command says `Running daemon personal-script state: UNAVAILABLE ()` and marks each `Daemon now:` line `UNAVAILABLE ()`; it never turns missing runtime evidence into a false `NOT CONFIGURED` verdict.
+The task above is the operator procedure. The following material preserves detailed behavior, limits and implementation context.
-On the `Configuration` line only, `NOT CONFIGURED` also says what the file being read right now actually contains, because the verdict alone cannot tell three different files apart:
+## Backup schedule
+
+The daemon reads `SCHEDULER_FREQUENCY`, `SCHEDULER_WEEKDAY`, `SCHEDULER_MONTHDAY` and `SCHEDULER_TIME` when it starts, and its journal reports the result in one block that ends with the outcome:
```text
- Configuration: NOT CONFIGURED (PERSONAL_SCRIPT_PRE_RUN is not in the file)
- Configuration: NOT CONFIGURED (PERSONAL_SCRIPT_PRE_RUN is on line 456 & is empty)
- Configuration: NOT CONFIGURED (PERSONAL_SCRIPT_PRE_RUN is on lines 120 and 456 & line 456 wins and is empty)
+Applying backup schedule...
+ Frequency: weekly
+ Weekday: Monday
+ Time: 02:00
+Backup schedule: applied
+daemon: next backup at 2026-10-05 02:00 (in 3d 15h5m53s)
```
-The third is the last-wins rule described in [CONFIGURATION.md](CONFIGURATION.md#configuration-integrity-check): a value you wrote is being discarded by a later assignment. The `Daemon now` line never carries this note. That daemon read its own copy of the file when it started, so describing today's file as if it explained the daemon's verdict would be a guess.
+- **Centralized monitor.** The frequency travels to ProxSave HC Server on the daemon's config poll, and the server moves the `proxsave-backup` check, and the periodic notify checks, to that period: 1 day, 7 days or 31 days, grace 1 hour ([HEALTHCHECKS.md](HEALTHCHECKS.md)). A new frequency applies only once the server confirms it. Until then the daemon keeps the frequency it last had confirmed (daily on a host that never had one confirmed), so the backup check never goes down for a run that was not due, and the block ends `Warning Backup schedule: pending, no action needed` with an `In effect:` line and the reason (`ProxSave HC Server not reachable`, `not ready` or `did not confirm`). The daemon asks three times at start, then once per heartbeat (`HEALTHCHECK_HEARTBEAT_INTERVAL`, 5 minutes by default); the heartbeat that gets the confirmation prints the block again, applied, followed by the next backup. The confirmed frequency is kept in `daemon_state/.schedule_state.json`, so a restart while the server is unreachable keeps it.
+- **Self-hosted monitor, or healthchecks off.** The frequency applies at once. On your own server ProxSave does not manage the backup check's period: with a weekly or monthly schedule the block adds `Backup check: pinged weekly on your own server` (or `monthly`), and setting the check's period is up to you.
+- **An invalid value** (a frequency other than daily, weekly or monthly, a day of the month outside 1-28, a time that is not HH:MM) gets a WARNING block, `Warning Backup schedule: not applied`, with one line per invalid value, before every backup until the value is fixed and the daemon restarted. The backup runs daily meanwhile, at `SCHEDULER_TIME`, or at 02:00 when the time itself is invalid. A variable that is missing or empty takes its default (daily, `mon`, `1`, `02:00`), and the day the frequency does not use is ignored.
-`UNKNOWN` on `Configuration` means the configuration file itself could not be read, so there is no current verdict to state: it is not `NOT CONFIGURED`, which asserts both settings were empty. The synchronization line then reads `UNKNOWN` as well, and in particular does not ask for a daemon restart on evidence it does not have. Both carry the loader's own error, so the line names the file and the reason it could not be read. `proxsave --daemon-status` exits earlier when the config is unreadable, so this pair is what the dashboard's daemon-status screen shows.
+A change to these variables takes effect at the next daemon restart. Until then `--daemon-status` reports the schedule `OUT OF SYNC`; see [From the command line](#from-the-command-line).
-With debug logging, the block also shows the UID used for each decision and every inspected path component's owner and mode. It reads the effective UID from the live daemon's `/proc//status` when possible and explicitly reports a fallback to the status command's UID when it cannot. The synchronization verdict distinguishes a changed config source or script path (`OUT OF SYNC`, restart required) from changed ownership, mode, or policy evidence at the same path (`PATH STATE CHANGED SINCE STARTUP`).
+## Standalone backups: the SIGUSR1 handoff
-This check is read-only: it never executes a personal script, starts a backup, acquires daemon ownership, or sends a healthcheck ping. Neither the schedule nor the script status alters its exit code. It exits `0` **only** when the daemon is running, beating, and aligned; every daemon gap (not installed, not running, stale, running but not reporting, or behind) exits non-zero, so `proxsave --daemon-status` can gate a script. It cannot be combined with `--daemon`, `--daemon-setup`, or `--daemon-remove`.
+A backup run outside the daemon (by hand with `--backup`, from a cron line, or from the dashboard's **Backup** row) does not ping the monitor itself. The resident daemon is the sole pinger. Instead, a standalone run drops a handoff file (`.manual_backup_outcome.json`) and wakes the daemon with `SIGUSR1`; the daemon then pings the backup check with that run's outcome. A handoff older than 15 minutes is dropped without pinging (so a long-past run never flips the check), and if no live daemon is found nothing pings.
-## Install
+## Binary alignment after an upgrade
-New installs default to the daemon. The install wizard (TUI and `--cli`) asks for the **Scheduler engine** (daemon or cron), then **Healthchecks** and **Notify level**, then the schedule: **Frequency**, **Weekday** (weekly only), **Day of month** (monthly only, 1-28) and the **Run at** time. Choosing the daemon installs `proxsave-daemon.service` and removes the proxsave cron entry ([what that means exactly](#what-removes-the-cron-entry-means)); choosing cron tears down a daemon unit left over from a previous install, so the two engines can never both be scheduling.
+Replacing the on-disk binary alone does not restart the resident daemon, so it can keep running the **old** code. An upgrade restart that is deferred or fails leaves this same condition until the daemon is restarted. ProxSave detects this hash-free: Linux blocks overwriting a running executable, so an upgrade unlinks it and `/proc//exe` ends in `" (deleted)"`, which alone proves the daemon is behind.
-The **Healthchecks** question is asked only with the daemon engine selected, because the daemon is the only thing that pings: under cron the TUI field is inactive, the `--cli` prompt is skipped, and monitoring is written off. With the daemon it defaults to the centralized ProxSave monitoring server, and answering `Off` is what leaves a daemon host deliberately unmonitored. See [HEALTHCHECKS.md](HEALTHCHECKS.md).
+`--upgrade`, the dashboard's **Upgrade**, and the dashboard's **Daemon** > **Restart** reconcile this with a restart-and-verify: they wait (bounded, up to 4 minutes) for any in-progress daemon-supervised backup to finish (deferring the restart, never killing the backup), restart the service, then poll until the daemon is back, aligned, and freshly started. `--daemon-status` and the dashboard's **Daemon** > **Status** report the same verdict: `behind - restart needed` from the flag, `BEHIND - RESTART NEEDED` on the dashboard screen, which puts every status keyword in ALL-CAPS.
-The wizard does not need a flag: from the dashboard, **Install** > **Edit install** runs the same flow against the existing configuration, prefilled from it, so a no-op pass never flips the engine.
+`--daemon-setup` does **not** do that. It restarts the unit immediately and then only polls until the daemon is alive with a readable alignment, accepting one that is still behind. If a daemon-supervised backup is running at that moment it is cancelled: the child gets SIGTERM, and SIGKILL if it does not stop within 30 seconds, and the run ends with no outcome ping, so the monitor sees a start that never finished. `--daemon-status` will not warn you: it reports liveness, unit state and binary alignment, never whether a backup is running. Check for the lock file under `LOCK_PATH`, or choose **Daemon** > **Install** outside the backup window.
## Retrofit existing installs
@@ -167,7 +260,7 @@ Retrofitting the daemon sets `HEALTHCHECK_ENABLED=true` even though its raw conf
A host that reverted with an **older** build still carries that stale `true`, and nothing it runs rewrites the key for it, so it warns and exits `1` on every otherwise successful backup. ProxSave does not repair it: on disk that host is indistinguishable from one whose operator set the key on purpose, and rewriting a monitoring setting on evidence that cannot tell the two apart takes away a choice instead of tidying a leftover.
-Two ways out, both yours to choose: set `HEALTHCHECK_ENABLED=false` in `backup.env`, or run `--daemon-setup` followed by `--daemon-remove`, which writes the key back to `false` on the way out. Hosts reverted from this release on are unaffected, and a cron host that never enabled the daemon carries the template default `false`.
+Two ways out, both yours to choose: set `HEALTHCHECK_ENABLED=false` in `backup.env`, or use **Daemon** > **Install** followed by **Disable**, which writes the key back to `false` on the way out. Hosts reverted from this release on are unaffected, and a cron host that never enabled the daemon carries the template default `false`.
### What "removes the cron entry" means
@@ -210,7 +303,7 @@ Daemon mode enabled: proxsave-daemon.service is active. No proxsave cron entry w
Daemon mode enabled: proxsave-daemon.service is active. The crontab could not be checked, so a proxsave cron entry may still be scheduled alongside it.
```
-The third line is normal on a fresh daemon install, which never had a cron entry. On a host that **was** on cron it is the signal to look: something whose command is not named `proxsave` was scheduling the backup, and it is still scheduled. Either delete that entry and let the daemon schedule the run (moving whatever the wrapper checked elsewhere), or run `proxsave --daemon-remove`, which records `SCHEDULER_MODE=cron` so upgrades leave the host alone. Note that the revert writes its own cron line as well, so a host that keeps the wrapper ends with two: it reports both and leaves the choice to you.
+The third line is normal on a fresh daemon install, which never had a cron entry. On a host that **was** on cron it is the signal to look: something whose command is not named `proxsave` was scheduling the backup, and it is still scheduled. Either delete that entry and let the daemon schedule the run (moving whatever the wrapper checked elsewhere), or choose **Daemon** > **Disable**, which records `SCHEDULER_MODE=cron` so upgrades leave the host alone. Note that the revert writes its own cron line as well, so a host that keeps the wrapper ends with two: it reports both and leaves the choice to you.
### The schedule is inherited, not reset
@@ -221,7 +314,7 @@ Adopting backup schedule from cron entry...
Frequency: weekly
Weekday: Sunday
Time: 21:00
-✓ Backup schedule: adopted from cron entry
+Backup schedule: adopted from cron entry
```
The adoption writes the frequency, the time and the day the frequency uses; the other day variable is left as it is.
@@ -238,75 +331,6 @@ The adoption writes the frequency, the time and the day the frequency uses; the
On the first `--upgrade` to 0.41 the closing summary is printed by the binary being replaced, which lists the warnings about cron lines not adopted but not the block that reports an adoption. The adopted values are in `backup.env` all the same.
-## systemd unit
-
-`proxsave-daemon.service` at `/etc/systemd/system/proxsave-daemon.service`:
-
-```ini
-[Unit]
-Description=ProxSave backup daemon
-Documentation=https://github.com/tis24dev/proxsave
-After=network-online.target
-Wants=network-online.target
-
-[Service]
-Type=simple
-ExecStart=/usr/local/bin/proxsave --daemon --config
-Restart=always
-RestartSec=10
-
-[Install]
-WantedBy=multi-user.target
-```
-
-`ExecStart` pins the same `backup.env` the install resolved (via `--config`), so the exact path in the generated unit is your install's config path.
-
-## On-disk state files
-
-The daemon coordinates through eight small files under `/daemon_state/` (a root-only directory, mode `0700`), all written atomically (temp file then rename, mode `0600`) and deliberately not made immutable so they can be rewritten:
-
-| File | Purpose |
-|------|---------|
-| `.daemon.pid` | the daemon's PID; the contract a standalone backup reads to send `SIGUSR1` |
-| `.daemon_info.json` | the running daemon's identity (pid, exec path, version, commit, start time), for display and the restart-verify freshness check |
-| `.daemon_runtime.json` | what the running daemon loaded at start (configuration path, personal-script verdicts), read by `--daemon-status` |
-| `.schedule_state.json` | the schedule the daemon started with, how healthchecks ran then, and the frequency ProxSave HC Server last confirmed |
-| `.healthcheck_status.json` | the last ping outcome per check, read back by the run phase to report real transmission; a corrupt file is quarantined to `.corrupt` and reset |
-| `.notify_results.json` | the backup child's per-channel notification severities, handed to the daemon to drive the `proxsave-notify-*` pings |
-| `.manual_backup_outcome.json` | a standalone run's outcome, handed off for the daemon to ping |
-| `.daemon_abandoned.json` | a backup child the kernel would not let the daemon reap: the orphan's pid and start time, the run id, and when it happened. See [the D-state caveat](#caveat-uninterruptible-sleep-d-state) |
-
-`.daemon.pid` and `.daemon_info.json` are written at startup and removed on shutdown.
-`.daemon_abandoned.json` is the exception that deliberately **survives** shutdown - that is its whole purpose - and is removed only once something shows backups can run again.
-
-A ninth file in the same directory, `.daemon.lock`, is not state but the single-instance ownership lock (an advisory `flock`, mode `0600`). It stays on disk between runs; what matters is who holds the lock, not that the file exists.
-
-Before 0.41 these files lived in `/identity/`. The first start of a 0.41 daemon moves them, and `identity/` keeps only the server identity, the relay secret and the AGE keys. `--new-install` keeps `daemon_state/` like `identity/`.
-
-## Configuration keys (`backup.env`)
-
-```ini
-# Scheduler engine
-SCHEDULER_MODE=cron # cron | daemon. Raw template value; the wizard writes daemon by default
-SCHEDULER_FREQUENCY=daily # daily, weekly or monthly
-SCHEDULER_WEEKDAY=mon # weekly only: mon, tue, wed, thu, fri, sat or sun
-SCHEDULER_MONTHDAY=1 # monthly only: 1-28
-SCHEDULER_TIME=02:00 # HH:MM ("Run at")
-MAX_RUN_DURATION=1h # watchdog hard timeout for one backup
-BACKUP_ENABLED=true # false: daemon skips the scheduled run (backup check goes down)
-
-# Personal scripts: your own, started around each run (daemon only)
-PERSONAL_SCRIPT_PRE_RUN= # path to a script started before the run (works only with the daemon)
-PERSONAL_SCRIPT_POST_RUN= # path to a script started after the run, whatever the outcome (works only with the daemon)
-
-# Monitoring: enabled here, configured in HEALTHCHECKS.md
-HEALTHCHECK_ENABLED=false # forced true by --daemon-setup, the dashboard's Install, auto-migration
-```
-
-The `HEALTHCHECK_*` keys that decide *where* and *what* the daemon reports live in [HEALTHCHECKS.md](HEALTHCHECKS.md).
-
-See [CONFIGURATION.md](CONFIGURATION.md) for the full variable reference and [CLI_REFERENCE.md](CLI_REFERENCE.md) for the `--daemon-*` flags.
-
## Personal scripts around a run
`PERSONAL_SCRIPT_PRE_RUN` and `PERSONAL_SCRIPT_POST_RUN` name two scripts of your own that
@@ -315,7 +339,7 @@ after it. Both are empty by default, which is the shipped state and means nothin
They are **yours, not ProxSave's**, and the whole contract follows from that:
-- **Daemon runs only.** A manual `proxsave --backup`, a cron-mode run, and a dashboard run
+- **Daemon runs only.** A standalone backup, a cron-mode run, and a dashboard run
start neither script. Only the run the daemon schedules and supervises is bracketed.
- **Nothing is reported about their execution.** Their standard output and standard error go to
`/dev/null`. Nothing they print or fail at appears in the run log, in the log file, in the
@@ -441,7 +465,7 @@ effect at the next daemon restart; changing the contents of the script file take
the next run.
To diagnose the configured paths without executing either script, run
-`proxsave --daemon-status --log-level debug`. It reports the running daemon's startup snapshot
+the diagnostic status invocation described in [CLI_REFERENCE.md](CLI_REFERENCE.md). It reports the running daemon's startup snapshot
beside a current inspection as `NOT CONFIGURED`, `READY`, `READY WITH WARNING`, or `REFUSED`,
then reports whether the two are synchronized. Debug output includes the UID plus ownership/mode
evidence. This does not prove the script's own logic succeeds; test that separately, as root, with
@@ -463,3 +487,77 @@ The exit code only matters in one fallback, when the marker is too corrupt to na
If backups are administratively off (`BACKUP_ENABLED=false`) the marker is kept but the alive check is left alone -- with backups off nothing could ever lift the degrade, and `proxsave-backup` is already down on its own merits.
Your fastest confirmation is `ps -eo pid,stat,wchan,cmd | grep ' D'`; the monitor's server-side `/start` plus grace catches the same run from the other side, and the `FS_IO_TIMEOUT` / `safefs` defenses are the layer below this watchdog.
+
+## Daemon status reference
+
+`--daemon` itself is not an operator command: it is what `proxsave-daemon.service` puts in its `ExecStart`. Running it by hand does not talk to the daemon systemd owns, and it does not become a second one either: an ownership lock (`/daemon_state/.daemon.lock`) makes it warn that another daemon already owns this install and exit `16`.
+
+The daemon status screen exposes the following running and configured state. Command-line status semantics and exit codes are in [CLI_REFERENCE.md](CLI_REFERENCE.md):
+
+```text
+Daemon status:
+Scheduler mode:
+Daemon service (proxsave-daemon.service): installed | not installed
+Service state (systemctl is-active):
+Running version: ()
+Binary alignment: aligned | BEHIND (restart needed) | unknown
+Running daemon configuration:
+Running daemon loaded at:
+Backup schedule:
+ Daemon now: DAILY () | WEEKLY ( at ) | MONTHLY (day at ) | NOT RUNNING | UNAVAILABLE ()
+ Configuration: DAILY (...) | WEEKLY (...) | MONTHLY (...) | INVALID () | UNKNOWN:
+ Synchronization: IN SYNC | OUT OF SYNC () | PENDING () | NOT APPLICABLE | UNKNOWN ()
+Personal pre-run script:
+ Daemon now: NOT RUNNING | NOT CONFIGURED | READY | READY WITH WARNING | REFUSED | UNAVAILABLE
+ Configuration: NOT CONFIGURED () | READY | READY WITH WARNING | REFUSED | UNKNOWN
+ Synchronization: NOT APPLICABLE | IN SYNC | OUT OF SYNC | PATH STATE CHANGED SINCE STARTUP | UNKNOWN
+Personal post-run script:
+ Daemon now: NOT RUNNING | NOT CONFIGURED | READY | READY WITH WARNING | REFUSED | UNAVAILABLE
+ Configuration: NOT CONFIGURED () | READY | READY WITH WARNING | REFUSED | UNKNOWN
+ Synchronization: NOT APPLICABLE | IN SYNC | OUT OF SYNC | PATH STATE CHANGED SINCE STARTUP | UNKNOWN
+```
+
+`Running version:` and `Binary alignment:` appear only when their daemon evidence is available, the two `Running daemon` lines only when the live daemon published its runtime state. The backup schedule and the two personal-script sections always appear.
+
+`Backup schedule` compares the schedule the daemon runs (`Daemon now`, from `daemon_state/.schedule_state.json`) with the one `backup.env` configures now. `OUT OF SYNC (restart the daemon to apply current schedule configuration)` means the file changed after the daemon started. `PENDING (ProxSave switches to weekly automatically; no action needed)` means the daemon is waiting for ProxSave HC Server to confirm the frequency and runs the last confirmed one meanwhile ([Backup schedule](#backup-schedule)); it switches by itself. A file changed after the start reads `OUT OF SYNC` even while a confirmation is pending, because only a restart brings the new value. `INVALID` names the invalid values, the same reasons the daemon's `not applied` block gives. `UNAVAILABLE` on `Daemon now` means the live daemon left no usable schedule state (none, one from an earlier start, or one that cannot be read).
+
+In the personal-script sections, `Daemon now` is the state captured and applied at daemon startup; `Configuration` is what a restart would load and how that path looks now. `NOT CONFIGURED` means the setting was empty, `READY` means the path passed without an advisory, `READY WITH WARNING` means it remains enabled under an explicit administrator trust decision, and `REFUSED` includes the exact refusal reason. If a live daemon has not published matching runtime state, the command says `Running daemon personal-script state: UNAVAILABLE ()` and marks each `Daemon now:` line `UNAVAILABLE ()`; it never turns missing runtime evidence into a false `NOT CONFIGURED` verdict.
+
+On the `Configuration` line only, `NOT CONFIGURED` also says what the file being read right now actually contains, because the verdict alone cannot tell three different files apart:
+
+```text
+ Configuration: NOT CONFIGURED (PERSONAL_SCRIPT_PRE_RUN is not in the file)
+ Configuration: NOT CONFIGURED (PERSONAL_SCRIPT_PRE_RUN is on line 456 & is empty)
+ Configuration: NOT CONFIGURED (PERSONAL_SCRIPT_PRE_RUN is on lines 120 and 456 & line 456 wins and is empty)
+```
+
+The third is the last-wins rule described in [CONFIGURATION.md](CONFIGURATION.md#configuration-integrity-check): a value you wrote is being discarded by a later assignment. The `Daemon now` line never carries this note. That daemon read its own copy of the file when it started, so describing today's file as if it explained the daemon's verdict would be a guess.
+
+`UNKNOWN` on `Configuration` means the configuration file itself could not be read, so there is no current verdict to state: it is not `NOT CONFIGURED`, which asserts both settings were empty. The synchronization line then reads `UNKNOWN` as well, and in particular does not ask for a daemon restart on evidence it does not have. Both carry the loader's own error, so the line names the file and the reason it could not be read. `proxsave --daemon-status` exits earlier when the config is unreadable, so this pair is what the dashboard's daemon-status screen shows.
+
+With debug logging, the block also shows the UID used for each decision and every inspected path component's owner and mode. It reads the effective UID from the live daemon's `/proc//status` when possible and explicitly reports a fallback to the status command's UID when it cannot. The synchronization verdict distinguishes a changed config source or script path (`OUT OF SYNC`, restart required) from changed ownership, mode, or policy evidence at the same path (`PATH STATE CHANGED SINCE STARTUP`).
+
+This check is read-only: it never executes a personal script, starts a backup, acquires daemon ownership, or sends a healthcheck ping. Neither the schedule nor the script status alters its exit code. It exits `0` **only** when the daemon is running, beating, and aligned; every daemon gap (not installed, not running, stale, running but not reporting, or behind) exits non-zero, so `proxsave --daemon-status` can gate a script. It cannot be combined with `--daemon`, `--daemon-setup`, or `--daemon-remove`.
+
+
+### From the command line
+
+See [CLI_REFERENCE.md](CLI_REFERENCE.md) for scheduler flags, automation examples and status exit codes.
+
+## Earlier guide entry points
+
+## Install
+
+See the complete [operator procedure](#schedule-and-supervise-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Operating
+
+See the complete [operator procedure](#schedule-and-supervise-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## What it does
+
+See the complete [operator procedure](#schedule-and-supervise-backups). Detailed settings and implementation material remain in the reference sections above.
+
+## Why
+
+See the complete [operator procedure](#schedule-and-supervise-backups). Detailed settings and implementation material remain in the reference sections above.
diff --git a/docs/DASHBOARD.md b/docs/DASHBOARD.md
index 16f1e216..5a20f698 100644
--- a/docs/DASHBOARD.md
+++ b/docs/DASHBOARD.md
@@ -1,10 +1,12 @@
# Dashboard
-The dashboard is how you use ProxSave. Run `proxsave` with no arguments on a terminal and it opens: installing, editing the configuration, upgrading, enabling or checking the daemon, running a backup, restoring, and opening a support report are all one keypress away. It is a launcher: where a choice has a matching command-line flag, picking it runs that flag's code, so nothing you do here behaves differently from the CLI. A few rows have no flag at all and exist only here, and the table below marks them.
+Run `proxsave` without arguments on an interactive terminal to open the dashboard. It provides backup, restore, decryption, configuration, maintenance, diagnostics, scheduling and support actions. Menu choices use the same underlying operation code as explicit commands, with dashboard-specific presentation and confirmation screens.
The flags stay fully supported, and [CLI_REFERENCE.md](CLI_REFERENCE.md) documents all of them. Reach for them when there is no terminal to open the dashboard on: headless hosts, cron entries, provisioning scripts, remote automation, and recovery when the TUI cannot run.
-This guide covers when the dashboard appears, the menu, what each entry does, and which flag each entry maps to. For the architecture behind it (the Charm/bubbletea stack, the Session, the Ask bridge, testing), see [DASHBOARD_TUI.md](DASHBOARD_TUI.md).
+This guide covers invocation rules, navigation and result screens. For the architecture behind it (the Charm/bubbletea stack, the Session, the Ask bridge, testing), see [DASHBOARD_TUI.md](DASHBOARD_TUI.md).
+
+
## When the dashboard opens
@@ -13,7 +15,7 @@ The dashboard opens only when both of these are true:
- You ran `proxsave` completely bare, with no flags at all. Any flag, even `--config`, skips it.
- Standard input and standard output are both real terminals, and `TERM` is set and is not `dumb`.
-If either is false, `proxsave` runs the backup exactly as it always has. That covers cron, systemd timers, pipes, `ssh` without a TTY, and serial or dumb terminals. The gate is deliberately strict: when in doubt, ProxSave runs the backup and never surprises you with a menu.
+If either is false, the dashboard is skipped. Explicit action flags select their operation; without an action flag, the normal backup path runs. A bare invocation from cron, a systemd timer, a pipe, `ssh` without a TTY, or a terminal with an unset or `dumb` TERM therefore starts a backup. An interactive serial console can open the dashboard if it satisfies the same terminal checks.
The reverse is also a guarantee: a failed or abandoned dashboard never falls through into a backup. If you press Esc or Ctrl+C at the menu, or the screen cannot render, ProxSave exits without doing anything and says so on stderr:
@@ -21,7 +23,7 @@ The reverse is also a guarantee: a failed or abandoned dashboard never falls thr
Dashboard unavailable: exiting without action. Use proxsave --backup to run a backup non-interactively.
```
-To run a backup without the menu (from a script, or just deliberately), use `proxsave --backup`.
+For explicit headless operation, use the [CLI reference](CLI_REFERENCE.md#basic-operations).
### Idle timeout
@@ -43,38 +45,27 @@ Until the notes are acknowledged, every automated run logs one warning:
ProxSave has unseen release notes. Open proxsave to view the new features.
```
-That warning is what an unattended host uses to tell you the dashboard is worth opening. If you upgraded a host you never sit at, `proxsave --show-whatsnew` displays the same screen once and clears the warning. Development builds never show the screen and never warn.
+That warning is what an unattended host uses to tell you the dashboard is worth opening. For unattended hosts, see [release-note acknowledgement](CLI_REFERENCE.md#binary-upgrade). Development builds never show the screen and never warn.
## Menu entries and their flags
-Where an entry has a flag, picking it runs that flag's code: some entries set the flag internally and fall through to the identical flow, the rest call the same function inside the live dashboard session. The rows marked "none, dashboard only" have no flag and exist only here.
-
-| Menu path | What it does | CLI equivalent |
-|-----------|--------------|----------------|
-| Backup | Runs a backup with the current configuration, streamed on screen | `--backup` |
-| Restore | Restores a backup onto this system | `--restore` |
-| Decrypt | Converts an encrypted backup into a plaintext bundle | `--decrypt` |
-| New key | Creates a new AGE encryption key | `--newkey` (alias `--age-newkey`) |
-| Install > Edit install | Re-runs the installer against the current configuration | `--install` |
-| Install > Wipe install | Resets the install directory, then re-runs the installer | `--new-install` |
-| Upgrade > Check upgrade | Checks for a newer release and installs it | `--upgrade` |
-| Upgrade > Check config | Adds new template variables to `backup.env` | `--upgrade-config` (its read-only step is `--upgrade-config-dry-run`) |
-| Telegram | Verifies the Telegram relay pairing | none, dashboard only |
-| Healthchecks | Verifies backup monitoring and shows the portal details | none, dashboard only |
-| Post-install | Re-runs the post-install audit | none, dashboard only (it runs `proxsave --dry-run` internally) |
-| Daemon > Install | Switches the scheduler from cron to the resident daemon | `--daemon-setup` |
-| Daemon > Disable | Reverts the scheduler to cron | `--daemon-remove` |
-| Daemon > Restart | Restarts the resident daemon and verifies it came back | none, dashboard only |
-| Daemon > Status | Shows the daemon service and scheduler state | `--daemon-status` |
-| Cleanup guards | Removes leftover restore mount guards | `--cleanup-guards` (preview with `--dry-run`) |
-| Support | Runs a support backup and emails the debug log to the maintainer | `--support` |
-| What's new | Shown once per release before the menu | `--show-whatsnew` |
-
-Going the other way, `--config`, `--dry-run`, `--log-level` and `--cli` are run modifiers with no menu row, and `--daemon` is what `proxsave-daemon.service` executes rather than something you type.
-
-Compatibility rules are re-checked after the menu, so a menu choice can never reach a state the flags would reject.
-
-Backup, Support and the binary upgrade keep the menu's frame alive and stream their run inside it (see [Backup](#backup)). The diagnostic, daemon and recovery actions run in place and return you to the menu. Everything else hands off to its flow.
+The flag mapping is maintained in the [CLI reference](CLI_REFERENCE.md#all-flags). Navigate the dashboard by the task names below; diagnostic checks and Daemon Restart are dashboard-only actions.
+
+| Task | Menu route | Complete procedure |
+|---|---|---|
+| Create a backup | Backup | [First backup](BACKUP_GUIDE.md#run-and-verify-your-first-backup) |
+| Restore selected host configuration | Tools > Restore | [Restore guide](RESTORE_GUIDE.md) |
+| Produce a plaintext bundle | Tools > Decrypt | [Decryption](ENCRYPTION.md#decrypting-backups) |
+| Set up public AGE recipients | Maintenance > New key | [Encryption](ENCRYPTION.md) |
+| Edit or reinstall | Maintenance > Install > Edit install / Wipe install | [Installation](INSTALL.md#fast-install) |
+| Update executable or merge settings | Maintenance > Upgrade > Check upgrade / Check config | [Upgrade](INSTALL.md#upgrading-proxsave-binary) |
+| Check Telegram or monitoring | Diagnostic Checks > Telegram / Healthchecks | [Notifications](NOTIFICATIONS.md), [monitoring](HEALTHCHECKS.md) |
+| Review optional collectors | Diagnostic Checks > Post-install > Check | [Configuration](CONFIGURATION.md#editing-the-configuration-from-the-dashboard) |
+| Manage the scheduler | Daemon | [Scheduling](DAEMON.md) |
+| Remove restore guards | Recovery > Cleanup guards | [Guard screen](#recovery-cleanup-guards) |
+| Send a diagnostic run log | Recovery > Support | [Support consent](#support) |
+
+Backup, Support and binary upgrade stream their output inside the dashboard frame. Other choices open a check screen or hand off to their interactive workflow. Operation compatibility is checked after selection too.
## Reading the screens: the Status vocabulary
@@ -82,15 +73,15 @@ Every result screen speaks one small vocabulary, so a color and a symbol always
| Look | Meaning |
|------|---------|
-| Green `✓` | Ok. The thing succeeded or is in the expected state. |
-| Red `✗` | Error. Something failed. |
-| Yellow `⚠` | Warning. Needs attention, usually retryable or a "here is what to do next". |
+| Green success | Ok. The thing succeeded or is in the expected state. |
+| Red error | Error. Something failed. |
+| Yellow warning | Warning. Needs attention, usually retryable or a "here is what to do next". |
| Yellow, no symbol | A neutral, pre-check state. You see this before you run a check, shown as `NOT CHECKED`. |
Two keywords are worth calling out because they look similar but are not the same level:
- `NOT CHECKED` is the neutral, no-symbol state: a check that has not run yet.
-- `NOT CONFIGURED` is a yellow `⚠` warning: the feature is not enabled on this host, so there is nothing to check.
+- `NOT CONFIGURED` is a yellow warning: the feature is not enabled on this host, so there is nothing to check.
## The menu
@@ -139,69 +130,41 @@ Navigate with the arrow keys (or `j`/`k`), `/` filters the list, Enter selects,
## Backup
-Backup is the one screen that keeps the frame and streams the run inside it. Your `[timestamp] LEVEL message` log lines flow, in color, into a scrollable panel on screen instead of scrolling past in raw text. The same blank-line spacing between sections that you see on the CLI is preserved.
+Backup keeps the dashboard frame and streams the run inside it. Your `[timestamp] LEVEL message` log lines flow, in color, into a scrollable panel on screen instead of scrolling past in raw text. The same blank-line spacing between sections that you see on the CLI is preserved.
While it runs:
- Arrow keys, PgUp/PgDn, Home/End, and the mouse wheel scroll within the panel. Scrolling up stops the auto-follow so the newest line does not yank you back down; press End (or scroll back to the bottom) to follow again.
-- `c` copies the whole log to the clipboard (the original lines, not the wrapped-on-screen rows), handy for a support request.
+- `c` copies the retained original lines to the clipboard, not the wrapped-on-screen rows. The panel retains up to 5,000 lines; use the saved run log for the complete output.
- Esc requests cancellation of the run.
When the run finishes, the panel shows the outcome block and waits. Press Enter or Space to return. A non-fatal problem reads as a yellow "completed with warnings", not a red failure; the exit code is identical to a plain CLI run.
-The outcome block is the only recap a dashboard backup gets, because the engine skips its own logged recap on this path. It carries the banner, the backup statistics, the secondary and cloud destination status when they are in use, the Telegram Server ID and the healthchecks portal link or address in centralized mode, the path of the run log, and finally a warnings/errors recap (the first 10 issue lines, with a "... and N more (scroll up to review)" note when there were more). The full list stays scrollable in the panel above.
+The outcome block is the only recap a dashboard backup gets, because the engine skips its own logged recap on this path. It carries the banner, the backup statistics, the secondary and cloud destination status when they are in use, the Telegram Server ID and the healthchecks portal link or address in centralized mode, the path of the run log, and finally a warnings/errors recap (the first 10 issue lines, with a "... and N more (scroll up to review)" note when there were more). Retained lines remain scrollable in the panel; the saved log contains the complete record.
-A backup started any other way (cron, `--backup`, the daemon) runs plainly with no panel.
+Scheduled and explicit headless backups run without the dashboard panel.
## Restore and Decrypt
-Restore and Decrypt hand off to their normal flows, rendered in the TUI. They are the same workflows as `proxsave --restore` and `proxsave --decrypt`; only the interface differs. Add `--cli` on the command line if you want the plain text prompts instead.
-
-A few things you will meet in the restore flow:
+These choices open the interactive backup selector and the corresponding workflow. Read the [restore guide](RESTORE_GUIDE.md) or [decryption procedure](ENCRYPTION.md#decrypting-backups) before proceeding. Restore category selection and the final overwrite guard are separate confirmations; the overwrite guard defaults to Cancel. Esc or `q` in the plan pager aborts rather than accepting it.
-- You pick categories from a checkbox list (at least one). Esc goes back to the mode selection, it does not cancel the whole restore.
-- Confirmation is two stages. First a `RESTORE` button (which holds the default focus), then a destructive `Overwrite and restore` guard whose default is `Cancel` and which has no single-key `y`/`n` shortcut, so a reflex keypress cannot trigger it.
-- For a cluster backup you are asked to choose `SAFE` (export cluster files only, does not write the cluster database) or `RECOVERY` (restore the full cluster database, only when the cluster is offline or isolated), or exit.
-- The restore plan is shown in a scrollable pager. Esc or `q` there aborts; it never counts as acceptance.
-
-Full detail lives in [RESTORE_GUIDE.md](RESTORE_GUIDE.md), and cluster specifics in [CLUSTER_RECOVERY.md](CLUSTER_RECOVERY.md).
+For cluster archives, SAFE and RECOVERY are separate strategy choices. SAFE can offer live API changes after exporting cluster material; it does not replace the cluster database. RECOVERY requires the offline or isolated conditions in the [cluster recovery guide](CLUSTER_RECOVERY.md). Do not infer that SAFE leaves the entire live host unchanged.
## New key
-New key runs the AGE encryption setup, the same as `proxsave --newkey`. See [ENCRYPTION.md](ENCRYPTION.md).
+Opens public AGE recipient setup. Follow the [encryption guide](ENCRYPTION.md) for recipient choices and independent private-key recovery. Generating a recipient is not a verification that you can decrypt a backup.
## Install
-The single `Install` row opens a small chooser:
-
-- `Edit install` re-runs the installer against your current configuration (`--install`).
-- `Wipe install` resets the installation directory, preserving `build`, `env`, `guards`, `identity` and `restore`, then runs the installer (`--new-install`). It asks you to confirm the destructive wipe first.
-- `Back` returns to the menu.
-
-See [INSTALL.md](INSTALL.md).
+Choose **Edit install** to reopen the installer, **Wipe install** for a destructive reset, or **Back**. Wipe preserves only `build`, `daemon_state`, `env`, `guards`, `identity` and `restore`; stock local archives, logs and configuration are deleted. Copy and verify required data independently before confirming. See [installation and reinstall](INSTALL.md#reinstall-safely).
## Upgrade
-The `Upgrade` row opens a chooser showing your current version, with two entries:
-
-- `Check upgrade` looks for a newer release. It runs the check the moment you open it. If you are current it shows green `NO UPGRADE ()`. If a newer release exists it shows yellow with the version, the release URL and notes, and a `Run upgrade` button. A failed check shows yellow `CHECK FAILED`.
-- `Check config` compares your `backup.env` against the shipped template. This is the two-step check-and-apply described under [Cleanup guards](#recovery-cleanup-guards); it lists the variables it would add and only offers Apply when there is something to add. A backup of the file is saved before the merge. It is the same operation as `proxsave --upgrade-config`.
-
-When you run the binary upgrade from here, its log streams into the same contained panel that Backup uses; press Enter when it finishes. On success the daemon, if it is active, is restarted once and verified, and then the dashboard relaunches itself from the freshly installed binary, so the session you continue in is the new version. If the daemon is not active there is nothing to restart and the screen tells you the new binary is on disk.
-
-Binary upgrade details are in [CLI_REFERENCE.md](CLI_REFERENCE.md#binary-upgrade).
+Choose **Check upgrade** to check releases automatically, then review the offered version and notes before **Run upgrade**. **Check config** previews the template merge and offers Apply when changes are available. Review its added and retired keys before applying. See [upgrade and configuration effects](INSTALL.md#upgrading-proxsave-binary) for daemon restart, verification and failure handling.
### Which binary drives the upgrade
-`Run upgrade` here is `proxsave --upgrade`, and that command is executed by the binary already installed on the host. The release check, the download, the signature verification and the binary swap are all the OLD release's code. So a fix to the upgrade flow itself only helps the upgrade AFTER the one that installs it: a host coming from an older release cannot benefit from migration logic shipped in the new one. (Since 0.36.0 the post-install finalize phase is handed to the freshly installed binary, but only when the binary doing the upgrading is new enough to know how to hand it over.)
-
-The externally fetched installer avoids that entirely: it downloads and swaps the binary itself, then runs the NEW binary to finalize.
-
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" -- --upgrade
-```
-
-Use that route when an upgrade misbehaves, or when the release notes say the upgrade path itself changed. The in-place upgrade, from here or from `proxsave --upgrade`, is the convenient one for routine releases.
+Release discovery and verification use the currently installed binary. Finalization can use the new binary when the old release supports delegation. The [two upgrade paths](INSTALL.md#the-two-upgrade-paths) explain this boundary and the external installer fallback.
## Diagnostic Checks
@@ -252,13 +215,13 @@ Monitoring only transmits under the resident daemon: it is the only thing that p
### Post-install
-Re-runs the post-install audit. Unlike the other checks it waits for you to press `Check`. It runs `proxsave --dry-run` (this can take a minute), then offers a checkbox list of unused or optional collectors you can turn off, each with a detail pane. What you select is written as `KEY=false` into `backup.env`. If nothing is unused it says `NO UNUSED COMPONENTS`; if you select nothing it says `NO CHANGES` and writes nothing. Any error here is non-fatal.
+Re-runs the post-install audit. Unlike the other checks it waits for you to press `Check`. It runs a diagnostic simulation that writes logs but does not create or upload a backup archive (this can take a minute), then offers a checkbox list of unused or optional collectors you can turn off, each with a detail pane. What you select is written as `KEY=false` into `backup.env`. If nothing is unused it says `NO UNUSED COMPONENTS`; if you select nothing it says `NO CHANGES` and writes nothing. Any error here is non-fatal.
## Daemon
-The resident daemon (`proxsave-daemon.service`) is the normal scheduler and the only thing that transmits healthcheck pings. Cron is the legacy path, kept for schedules the daemon cannot express. The daemon operations here are the graphical equivalent of the `--daemon-*` flags, and the menu only shows the ones that apply to your current scheduler (see [the menu](#the-menu)).
+The resident daemon (`proxsave-daemon.service`) is the normal scheduler and the only thing that transmits healthcheck pings. Cron is the legacy path, kept for schedules the daemon cannot express. The menu only shows the ones that apply to your current scheduler (see [the menu](#the-menu)).
-- `Status` computes a combined verdict and shows it: whether the service is installed and active, the scheduler mode, the running version, whether the on-disk binary matches the running process, and the readiness of any personal pre/post scripts. It runs automatically when opened; `Re-check` re-computes it so a restart done elsewhere shows up. A fresh heartbeat reads green `RUNNING`; a replaced binary while active reads yellow `BEHIND - RESTART NEEDED`. All problem states today are yellow warnings. It is the same verdict `proxsave --daemon-status` prints, ALL-CAPS here and in lower case on the command line.
+- `Status` computes a combined verdict and shows it: whether the service is installed and active, the scheduler mode, the running version, whether the on-disk binary matches the running process, and the readiness of any personal pre/post scripts. It runs automatically when opened; `Re-check` re-computes it so a restart done elsewhere shows up. A fresh heartbeat reads green `RUNNING`; a replaced binary while active reads yellow `BEHIND - RESTART NEEDED`. All problem states today are yellow warnings.
- `Install` installs and enables the service and removes the cron entry. The result screen states what the cron removal actually did. If the crontab could not be verified it reads yellow `INSTALLED - NO CRON ENTRY REMOVED`, and if another schedule that also runs backups is still present it reads yellow `INSTALLED - DUPLICATE SCHEDULE` and tells you to clean up your crons, because the host would otherwise back up twice.
- `Disable` reverts to the cron scheduler and stops future upgrades from reinstalling the daemon. If a backup is in progress it reports yellow `DEFERRED - BACKUP RUNNING` rather than tearing the service out from under it.
- `Restart` restarts the service and verifies it came back aligned. It first waits for any in-progress backup to finish, because a restart would kill a daemon-supervised backup. If the wait times out it reports yellow `DEFERRED - BACKUP RUNNING`; if the restart happened but could not be confirmed it reports yellow `RESTARTED, NOT CONFIRMED` and points you at `Status`. There is no flag for this one: it exists only here.
@@ -272,7 +235,7 @@ During some restores ProxSave places a read-only guard over a datastore mountpoi
1. A read-only check. If there is nothing to clean it shows green `CLEAN` and offers only `Re-check` and `Back`, never Apply. If it finds guards it shows yellow `FOUND` with a count.
2. Apply runs the real cleanup. If everything is removed it shows green `DONE`. If anything is left behind (or the state cannot be re-read) it shows yellow `PENDING` with guidance to unmount the datastore and run it again once the storage is offline.
-The command-line equivalent is `proxsave --cleanup-guards`; see [CLI_REFERENCE.md](CLI_REFERENCE.md#cleanup-mount-guards-optional).
+Headless cleanup and exit-code interpretation are in the [CLI reference](CLI_REFERENCE.md#cleanup-mount-guards-optional).
## Support
@@ -280,7 +243,7 @@ Support collects a little context, then runs a backup in debug mode and emails t
The note tells you the run is in debug mode, that the full log is emailed to the maintainer at the end of the run, that anything personal or sensitive in it will be shared, and that it may contain personal data such as this server's MAC address. Below it are four rows: your GitHub nickname, the GitHub issue number (`#1234`), and two acknowledgement toggles that both have to be set to Yes before Continue is accepted, one for consent to send the log and one confirming the GitHub issue is already open. Untouched toggles read No, so nothing is armed by walking away from the form. The maintainer's email address is never shown.
-On confirm it runs like Backup, streaming the debug run in the frame. Cancel or Esc returns to the menu. The command-line equivalent is `proxsave --support`, which asks the same questions on stdin.
+On confirm it runs like Backup, streaming the debug run in the frame. Cancel or Esc returns to the menu. After initial consent, the log is sent automatically when the run ends; there is no final review screen. See [support preparation](TROUBLESHOOTING.md) to prepare a log for review before sharing.
## Keyboard and mouse
@@ -292,3 +255,5 @@ On confirm it runs like Backup, streaming the debug run in the frame. Cancel or
## Exiting and timeouts
You leave the dashboard by choosing `Exit`, pressing Esc or Ctrl+C at the menu, or letting the 10-minute idle timeout fire. All of these exit cleanly without running anything.
+
+
diff --git a/docs/DASHBOARD_TUI.md b/docs/DASHBOARD_TUI.md
index 473afc35..6bccc291 100644
--- a/docs/DASHBOARD_TUI.md
+++ b/docs/DASHBOARD_TUI.md
@@ -148,11 +148,11 @@ The raw ring is bounded at 5000 lines; older lines drop first with a `(showing l
## Theme and the Status vocabulary
-`theme.go` is a fixed dark-first Proxmox palette: orange `#E57000` for the border, titles and selection, plus green, red, yellow, blue, and a magenta that matches the Ctrl+C interrupt summary color. `Background` `#101010` is painted explicitly on every frame; there is no terminal-background detection, because serial and IPMI terminals answer background queries unreliably. Symbols are `✓ ✗ ⚠ ℹ ▸ → • ☑ ☐`.
+`theme.go` is a fixed dark-first Proxmox palette: orange `#E57000` for the border, titles and selection, plus green, red, yellow, blue, and a magenta that matches the Ctrl+C interrupt summary color. `Background` `#101010` is painted explicitly on every frame; there is no terminal-background detection, because serial and IPMI terminals answer background queries unreliably. The theme defines symbols for success, error, warning, information, selection, navigation and checkbox state.
-`StatusColor`/`StatusSymbol` map status keywords: `success`/`ok`/`done`/`completed` to green `✓`; `error`/`failed`/`fail` to red `✗`; `warning`/`warn` to yellow `⚠`; `info`/`pending`/`running` to blue `ℹ` (note `pending` and `running` share the info color); anything else to light `•`.
+`StatusColor`/`StatusSymbol` map status keywords: `success`/`ok`/`done`/`completed` to green a check mark; `error`/`failed`/`fail` to red a cross; `warning`/`warn` to yellow a warning triangle; `info`/`pending`/`running` to blue an information symbol (note `pending` and `running` share the info color); anything else to light a bullet.
-Result screens across the daemon, install, and workflow code do not use this directly; they delegate to `orchestrator.RenderStatusLevel`, which is the one renderer for a styled `Status:` line and has four levels: Ok (green `✓`), Error (red `✗`), Warn (yellow `⚠`), and Neutral (yellow, no symbol). `orchestrator.BuildStatusPrompt` composes the keyword and its explanation into the block those screens hand to `WithSelectorPromptStyled`, sanitizing both. Neutral is a front-end-only pre-check state (`NOT CHECKED`); `NOT CONFIGURED` is a Warn keyword (with the `⚠`), not a Neutral one. Keeping every result screen on one renderer is what stops the Status look from drifting.
+Result screens across the daemon, install, and workflow code do not use this directly; they delegate to `orchestrator.RenderStatusLevel`, which is the one renderer for a styled `Status:` line and has four levels: Ok (green a check mark), Error (red a cross), Warn (yellow a warning triangle), and Neutral (yellow, no symbol). `orchestrator.BuildStatusPrompt` composes the keyword and its explanation into the block those screens hand to `WithSelectorPromptStyled`, sanitizing both. Neutral is a front-end-only pre-check state (`NOT CHECKED`); `NOT CONFIGURED` is a Warn keyword (with the a warning triangle), not a Neutral one. Keeping every result screen on one renderer is what stops the Status look from drifting.
What each level means to the operator is [DASHBOARD.md](DASHBOARD.md)'s job, not this file's. Add a level here only if you are prepared to give it a meaning there.
diff --git a/docs/DEVELOPER_GUIDE.md b/docs/DEVELOPER_GUIDE.md
index b85c4f00..3543ab70 100644
--- a/docs/DEVELOPER_GUIDE.md
+++ b/docs/DEVELOPER_GUIDE.md
@@ -19,15 +19,10 @@ Guide for contributing to Proxsave, including development setup, coding guidelin
## Overview
-Proxsave is built with modern Go practices, emphasizing:
-
-- **Performance**: Compiled binary, concurrent operations
-- **Reliability**: Comprehensive error handling, safe defaults
-- **Maintainability**: Clean architecture, modular design
-- **Testability**: Unit tests, integration tests, mocking
+This guide covers the implementation and contributor workflow. For the operator view of collection, archives and destinations, read [How a backup runs](BACKUP_GUIDE.md#how-a-backup-runs). For routine operations, use the [dashboard guide](DASHBOARD.md)
**Technology stack**:
-- **Language**: Go 1.26.8 or later (the floor `go.mod` sets and `goRuntimeMinVersion` enforces at startup)
+- **Language**: Go 1.26.9 or later (the floor `go.mod` sets and `goRuntimeMinVersion` enforces at startup)
- **Dependencies**: See `go.mod` for complete list
- **Build system**: Makefile + Go modules
- **Compression**: gzip, bzip2, xz, lzma, zstd
@@ -41,7 +36,7 @@ Proxsave is built with modern Go practices, emphasizing:
### Prerequisites
```bash
-# Go 1.26.8 or later
+# Go 1.26.9 or later
go version
# Build tools
@@ -199,7 +194,7 @@ go build -ldflags="-s -w" -o build/proxsave ./cmd/proxsave
# With version info
VERSION=$(git describe --tags --always)
-go build -ldflags="-s -w -X main.version=${VERSION}" -o build/proxsave ./cmd/proxsave
+go build -ldflags="-s -w -X github.com/tis24dev/proxsave/internal/version.Version=${VERSION}" -o build/proxsave ./cmd/proxsave
```
### Run Without Building
diff --git a/docs/ENCRYPTION.md b/docs/ENCRYPTION.md
index e2930147..dc1f3425 100644
--- a/docs/ENCRYPTION.md
+++ b/docs/ENCRYPTION.md
@@ -1,52 +1,300 @@
# Encryption Guide
-Complete guide to AGE encryption for Proxsave.
-
-## Table of Contents
-
-- [Overview](#overview)
-- [Features](#features)
-- [Plaintext staging](#plaintext-staging)
-- [Quick Start](#quick-start)
-- [Configure Recipients](#configure-recipients)
- - [Static Configuration](#static-configuration)
- - [Interactive Wizard](#interactive-wizard)
-- [Running Encrypted Backups](#running-encrypted-backups)
-- [Decrypting Backups](#decrypting-backups)
-- [Restoring Encrypted Backups](#restoring-encrypted-backups)
-- [Key Rotation](#key-rotation)
-- [Emergency Scenarios](#emergency-scenarios)
-- [Security Notes](#security-notes)
-- [Related Documentation](#related-documentation)
+
+
+## Encrypt backups and preserve recovery keys
+
+AGE encryption protects the archives delivered to primary, secondary and rclone
+storage. Any private identity matching one of the configured recipients can decrypt
+the archive. Keep that identity, or the original passphrase, independently of the host.
+ProxSave does not store your private key or passphrase for you.
+
+Native PBS snapshots use the PVE storage encryption key, not AGE recipients. Enabling
+AGE archive encryption does not encrypt a PBS snapshot whose storage has no key.
+See [native PBS encryption](STORAGE.md#check-the-actual-encryption-key).
+
+### Enable archive encryption
+
+Run `proxsave` without arguments on an interactive terminal and choose
+**Maintenance** > **Install** > **Edit install**. Enable `Backup encryption (AGE)`.
+The wizard writes `ENCRYPT_ARCHIVE=true` and runs recipient setup when needed.
+To configure recipients separately, choose **Maintenance** > **New key**.
+
+Before changing an existing setup, inspect `AGE_RECIPIENT` and `AGE_RECIPIENT_FILE`
+in the active `configs/backup.env`. The recipient wizard rewrites the recipient file
+only; it does not clear inline recipients or change the configured file path.
+Inline recipients and file recipients are merged and deduplicated, so an old inline
+recipient can remain authorized after you replace the file.
+
+The normal recipient file is `${BASE_DIR}/identity/age/recipient.txt`. It contains
+public recipients, not private recovery keys. `AGE_RECIPIENTS` is a fallback alias used
+only when `AGE_RECIPIENT` is empty. See [recipient configuration](#configure-recipients)
+for supported formats, separators and permissions.
+
+### Choose recovery material you can retain
+
+The recipient setup accepts an AGE public recipient, an AGE private identity from
+which it derives the public recipient, or a passphrase from which it derives an identity.
+It supports multiple recipients. Preserve each needed private identity outside the
+host; entering a private identity during setup does not make ProxSave retain it.
+
+For passphrases, setup requires at least 12 characters and three of four character
+classes: lowercase, uppercase, digit and symbol. Known weak passphrases are rejected.
+Strength validation does not replace a safely retained recovery secret.
+
+A passphrase-derived recipient is an X25519 identity, not age's native passphrase
+format. Setup uses a random per-installation salt. Each backup manifest carries the
+salt needed for later passphrase recovery. Keep the bundle intact or retain the raw
+archive with its matching manifest. The same passphrase entered into a new setup with
+a new salt creates a different recipient.
+
+SSH public recipients are accepted for encryption, but ProxSave's built-in recovery
+prompt does not accept SSH private keys. Use X25519 recovery material for dashboard
+recovery, or explicitly plan and test the external AGE procedure in the
+[recipient reference](#configure-recipients).
+
+### Understand plaintext exposure
+
+Collection happens before encryption. Sensitive files are staged in a root-owned
+`0700` per-run directory under `/tmp/proxsave`. The compressed archive is streamed into
+AGE without creating a plaintext archive, but the staging tree remains plaintext.
+Provision enough temporary space for an uncompressed collection as well as the output.
+On tmpfs, plaintext may reach swap; on disk it reaches persistent storage.
+
+The shared `/tmp/proxsave` root may be `0755`. Its guard rejects unsafe ownership or
+write permissions but does not tighten every world-readable root. Review it and use
+private permissions if your security policy requires them. The location is compiled
+in; `TMPDIR` does not move the staging tree.
+
+Normal return and the first interrupt clean up backup staging. SIGKILL, power loss or
+a second interrupt can leave it behind. Give the first interrupt time to unwind.
+After an unclean shutdown inspect leftovers and establish that no backup, decrypt or
+restore is using them before removing a specific directory. Never delete by a broad
+glob on a working host. The next backup's sweep does not guarantee cleanup after a
+reboot or for restore staging. See [Plaintext staging](#plaintext-staging) for exact
+cleanup scope and the external inspection procedure.
+
+### Verify encryption and recovery
+
+Choose **Backup** in the dashboard. Check the encryption result and the named artifact:
+a raw encrypted archive ends in `.age`; the default bundled artifact ends in
+`.age.bundle.tar`. Keep the archive's sidecars together when bundling is disabled.
+
+Choose **Tools** > **Decrypt** and prove the saved archive opens with your independently
+retained private identity or passphrase. A successful encrypted upload does not prove
+that you retained a working recovery secret. Follow
+[Decrypting Backups](#decrypting-backups) to inspect the result safely.
+
+### Rotate keys without losing old recovery points
+
+For a gradual rotation, add the new recipient alongside the old one, create and test
+a backup with the new identity, then remove the old recipient from both file and inline
+settings. Replacing recipients changes future backups only. Existing backups still
+need an identity that matched their original recipients.
+
+Keep old private identities and passphrases until all backups that require them have
+expired. The wizard backs up an existing recipient file before overwriting it, but
+that public file cannot decrypt your old backups. Review the
+[rotation reference](#key-rotation) for replacement and multi-recipient behavior.
+
+When migrating a setup, preserve the entire `identity/age` directory, especially
+`passphrase.salt`, alongside configuration. The setup wizard reads the salt file;
+the comment inside `recipient.txt` is not its substitute. Existing backup decryption
+uses the manifest salt and remains possible even if local salt files are lost.
+See [lost-salt recovery](#rebuilding-a-lost-salt) before recreating future recipients.
+Command-line equivalents are in [CLI_REFERENCE.md](CLI_REFERENCE.md).
+
+
+
+
----
+## Decrypting Backups
-## Overview
+Decryption creates a plaintext bundle for inspection or transfer; it does not apply
+configuration to the host. This workflow accepts AGE archives from primary, secondary
+or rclone storage. Native PBS snapshots require the
+[PBS recovery procedure](STORAGE.md#recover-a-native-pbs-snapshot).
+
+### Prepare a safe destination and recovery secret
+
+Keep the original encrypted bundle, or the archive with its matching manifest and
+checksum. You need a matching `AGE-SECRET-KEY-...` private identity or the original
+passphrase. A public recipient cannot decrypt a backup.
+
+Passphrase recovery uses the salt recorded in that backup's manifest. It does not
+read `recipient.txt` or the host's `passphrase.salt`, so losing local setup files does
+not prevent recovery of a complete existing backup. A different salt in newly created
+setup does not change the identity needed by older archives.
+
+Provide enough destination and temporary space. Decryption stages plaintext under
+`/tmp/proxsave`; normal completion removes temporary staging, while an abrupt kill or
+power loss can leave plaintext behind. The saved output is deliberately plaintext.
+Choose a private destination with restrictive permissions and control access for as
+long as the output exists. Follow [staging cleanup guidance](#plaintext-staging) after
+an unclean shutdown, checking for live operations before deleting anything.
+
+### Decrypt through the dashboard
+
+1. Run `proxsave` without arguments on an interactive terminal and choose
+ **Tools** > **Decrypt**.
+2. Select the configured primary, secondary or cloud archive source and then the
+ exact encrypted backup. Confirm its hostname and date.
+3. Choose the destination directory. The suggested path is `./decrypt` or
+ `${BASE_DIR}/decrypt`, depending on the resolved installation context.
+4. Enter the matching AGE private identity or original passphrase when prompted.
+ If it does not match, check the selected backup and secret before trying again.
+5. Confirm successful completion and record the output path.
+
+The output is `*.decrypted.bundle.tar`, an outer plain tar containing the decrypted
+archive plus metadata and checksum. It is not itself the configuration archive.
+Inspect its member names before selecting the inner archive:
+
+```bash
+tar -tf /private/path/backup.decrypted.bundle.tar
+```
+
+To extract it for inspection, use a new private directory and the exact output path:
+
+```bash
+install -d -m 700 /root/proxsave-inspection
+tar -xf /private/path/backup.decrypted.bundle.tar -C /root/proxsave-inspection
+```
+
+Verify the inner archive against the matching checksum from that bundle, and inspect
+expected configuration members before relying on it. Keep the original encrypted copy.
+Remove plaintext inspection copies when finished; deletion is not guaranteed secure
+erasure from the underlying storage.
+
+### Recover with external AGE tools
+
+When ProxSave is unavailable, the official AGE client can decrypt with a suitable
+private identity. First unwrap the encrypted bundle into a private directory; feeding
+the outer `.bundle.tar` directly to age is not the same as decrypting its `.age` member.
+The complete [emergency decryption procedure](#emergency-decryption-without-configuration)
+preserves the extraction order, checksum validation and cleanup steps.
+
+A passphrase-derived ProxSave recipient is not age's native scrypt passphrase stanza.
+The stock age client cannot reproduce it from the passphrase alone. Use the dashboard
+with the original passphrase and manifest salt, or an independently retained matching
+private identity for external recovery. Do not enter an SSH private key into the
+ProxSave prompt: it is treated as a passphrase and derives the wrong identity. SSH
+recipient recovery requires the external AGE procedure.
+
+### Apply configuration only through a planned restore
+
+If the goal is host recovery, choose **Tools** > **Restore** instead. That workflow can
+verify and decrypt the original encrypted backup before category selection and plan
+review; there is no need to decrypt first merely to restore it. Follow the
+[restore guide](RESTORE_GUIDE.md#restore-modes) and target-specific cluster, storage,
+network and boot precautions. Do not copy the extracted tree over `/`.
+
+For a replacement host, restore remote credentials independently, make the complete
+backup available through a configured source and retain the original recovery secret.
+If a checksum fails, stop and retrieve another verified copy. If the key does not match,
+check the original recipients and recovery records; new recipient setup does not
+unlock an old backup. See [Emergency Scenarios](#emergency-scenarios) for missing salt
+or setup files. Automation entry points belong in [CLI_REFERENCE.md](CLI_REFERENCE.md).
+
+
+
+## Related Documentation
+
+### Configuration
+- **[Configuration Guide](CONFIGURATION.md)** - Complete variable reference including all AGE settings
+- **[Cloud Storage Guide](CLOUD_STORAGE.md)** - rclone integration with encrypted cloud backups
+
+### Restore Operations
+- **[Restore Guide](RESTORE_GUIDE.md)** - Complete restore workflows (all modes)
+- **[Restore Technical](RESTORE_TECHNICAL.md)** - Technical implementation details
+- **[Cluster Recovery](CLUSTER_RECOVERY.md)** - Disaster recovery procedures
-Proxsave uses the **[age](https://age-encryption.org/)** format (via `filippo.io/age`) for encryption. AGE is a modern, simple, and secure file encryption format designed to replace GPG for basic use cases.
+### Reference
+- **[Dashboard](DASHBOARD.md)** - The interactive menu: New key, Backup, Decrypt, Restore
+- **[Daemon](DAEMON.md)** - The resident scheduler that runs the encrypted backups
+- **[CLI Reference](CLI_REFERENCE.md)** - All command flags including `--decrypt`, `--newkey`
+- **[Troubleshooting](TROUBLESHOOTING.md)** - Common encryption/decryption issues
+- **[Examples](EXAMPLES.md)** - Real-world encrypted backup scenarios
-**Key characteristics**:
-- **Streaming encryption**: the archive is encrypted as it is written, so no plaintext archive is ever created on disk. The files gathered for the backup are staged in the clear under `/tmp/proxsave` first: see [Plaintext staging](#plaintext-staging)
-- **Multiple recipients**: Support for both passphrase and key-based encryption
-- **Memory safety**: Sensitive data zeroed immediately after use
-- **Standard format**: Compatible with standard AGE tools
+### Main Documentation
+- **[README](../README.md)** - Project overview and quick start
---
-## Features
+## Quick Reference
+
+### Environment Variables
-| Feature | Description |
-|---------|-------------|
-| **Encryption algorithm** | ChaCha20-Poly1305 (AEAD) with X25519 key exchange |
-| **Key types** | Passphrase or X25519 key pair. SSH public keys (`ssh-ed25519` / `ssh-rsa`) are accepted as recipients but ProxSave cannot decrypt with the matching SSH private key: see the warning below |
-| **Multiple recipients** | Single backup can be decrypted with any configured recipient |
-| **Interactive setup** | Dashboard **Maintenance** > **New key**, the same flow as `--newkey`; the install wizard runs it too when you turn `Backup encryption (AGE)` on, and so does the first encrypted run with no recipients configured |
-| **Streaming mode** | Encrypts during backup creation, so there is no temporary plaintext **archive**. The staging tree under `/tmp/proxsave` is plaintext |
-| **Security** | Passphrases read with `term.ReadPassword`, buffers zeroed after use |
-| **File permissions** | Recipient files are created 0700/0600; the security check verifies them and auto-fixes only when `AUTO_FIX_PERMISSIONS` is enabled (otherwise it warns) |
+```bash
+# Enable encryption
+ENCRYPT_ARCHIVE=true # Master switch
+
+# Recipient configuration
+# The shipped template sets this; the compiled-in default is empty and resolves to the same path.
+# --newkey rewrites whatever this points at, so check it before assuming the default.
+AGE_RECIPIENT_FILE=${BASE_DIR}/identity/age/recipient.txt # Public recipients (recommended)
+
+# Optional: inline recipients (merged with file; supports comma/semicolon/pipe/newline)
+# AGE_RECIPIENTS (plural) is accepted as a fallback alias, used only when AGE_RECIPIENT is empty
+AGE_RECIPIENT=age1abc123...,age1def456...
+```
+
+### Common Commands
+
+See [CLI_REFERENCE.md](CLI_REFERENCE.md) for encryption, decryption and restore command equivalents.
+
+### File paths in these examples
+
+`BASE_DIR` is auto-detected from the installed executable and is **not** a shell variable:
+substitute your install root (typically `/opt/proxsave`) when pasting any path that uses it.
+
+### File Locations
+
+```text
+configs/
+└── backup.env # Environment variables
+
+identity/
+└── age/
+ ├── recipient.txt # Public recipients, plus the "# passphrase-salt:" line (0600)
+ ├── passphrase.salt # Per-installation passphrase salt (0600, passphrase setups only)
+ └── recipient.txt.bak-* # Written by --newkey when it overwrites an existing file
+
+backup/
+└── -backup-*.tar.[.age][.bundle.tar]
+```
+
+### Key Formats
+
+**Public key (X25519)**:
+```text
+age1abc123def456ghi789jkl012mno345pqr678stu901vwx234yz567abc
+```
+
+**Private key (X25519)**:
+```text
+AGE-SECRET-KEY-1ABC123DEF456GHI789JKL012MNO345PQR678STU901VWX234YZ567ABC
+```
---
+**For complete AGE specification**, see: https://age-encryption.org/v1
+
+
+## Implementation appendix
+
+### Encryption Implementation
+
+- **Algorithm**: ChaCha20-Poly1305 (AEAD) with X25519 ECDH
+- **Key derivation**: scrypt (N=2^15, r=8, p=1) for passphrases. The current scheme uses a **per-installation random salt** (v2), generated once, stored `0600` at `identity/age/passphrase.salt`, mirrored as the `# passphrase-salt:` line inside the recipient file (every backup rewrites that comment from the sibling before reading it back, so the sibling wins whenever the two differ; once the sibling is gone the comment still supplies the salt stamped into new manifests, but it can **not** re-derive the recipient, because the setup wizard reads the sibling alone and mints a fresh random salt when it is missing, yielding a different recipient), and embedded in each manifest as `passphrase_salt` so the passphrase alone can re-derive the recipient on any host. At decrypt ProxSave tries salts in order: the manifest's per-install salt first, then two fixed legacy namespaces (`proxsave/age-passphrase/v1`, then the pre-rebrand `proxmox-backup-go/age-passphrase/v1`), so archives from older versions and from before the rename stay decryptable.
+- **Random nonces**: Unique per encryption operation
+- **Authentication**: Poly1305 MAC prevents tampering
+
+
+
+## Encryption settings and security reference
+
+The task above is the operator procedure. The following material preserves detailed behavior, limits and implementation context.
+
## Plaintext staging
Encryption applies to the **archive**, not to the collection step. Each run creates a
@@ -132,92 +380,12 @@ than land it on a shared filesystem.
---
-## Quick Start
-
-Encryption is set up from the dashboard: run `proxsave` with no arguments on a TTY and it
-opens. Two of its rows cover everything below.
-
-- **Install** > **Edit install** re-runs the install wizard against the existing
- configuration. Its `Backup encryption (AGE)` toggle is what writes `ENCRYPT_ARCHIVE`,
- and when you turn it on the AGE recipient setup runs straight after the wizard.
-- **Maintenance** > **New key** opens that same recipient setup on its own.
-
-The flags in this guide reach the same flows without going through the dashboard, for
-headless hosts, scripts, and recovery. They still draw the TUI; add `--cli` for text-mode
-prompts when the terminal cannot render it. See [DASHBOARD.md](DASHBOARD.md).
-
-### 1. Generate Recipients
-
-**Option A: Interactive wizard** (recommended for beginners). In the dashboard,
-**Maintenance** > **New key**; headless, the same flow is:
-
-```bash
-proxsave --newkey
-```
-
-**Option B: Manual generation** with standard AGE tools:
-
-```bash
-# Generate key pair (keep the private key offline if possible)
-age-keygen -o age-keys.txt
-
-# Extract the public recipient (starts with "age1...")
-grep "# public key:" age-keys.txt | cut -d: -f2 | tr -d ' '
-
-# Then paste the recipient into:
-# proxsave --newkey
-# or configure it via AGE_RECIPIENT / AGE_RECIPIENT_FILE in configs/backup.env
-```
-
-### 2. Configure Environment
-
-`ENCRYPT_ARCHIVE` is the one key the wizard writes for you (dashboard **Install** >
-**Edit install**, field `Backup encryption (AGE)`). The recipient keys are not wizard
-fields: `--newkey` writes the recipient **file** and never edits `configs/backup.env`, so
-an inline recipient or a non-default file path is a hand edit.
-
-In `configs/backup.env`:
-
-```bash
-# Enable encryption
-ENCRYPT_ARCHIVE=true
-
-# Recipients (public keys). You can use the inline list, the file, or both.
-# Inline list supports separators: comma, semicolon, pipe, newline
-AGE_RECIPIENT=
-
-# Default recipient file (created by the wizard on first run)
-AGE_RECIPIENT_FILE=${BASE_DIR}/identity/age/recipient.txt
-```
-
-### 3. Run Encrypted Backup
-
-From the dashboard, the **Backup** row. From a script or a headless host:
-
-```bash
-proxsave --backup
-# Archive will be encrypted (archive ends with .age; if bundling is enabled, output ends with .age.bundle.tar)
-```
-
-A bare `proxsave` opens the dashboard on a terminal and runs the backup only when it is
-not on one (cron, a systemd unit, a pipe), so scripts should say `--backup` explicitly.
-On a host scheduled by the resident daemon you do not start runs by hand at all: the
-daemon does it. See [DAEMON.md](DAEMON.md).
-
-### 4. Decrypt When Needed
-
-From the dashboard, **Tools** > **Decrypt**. Without the dashboard:
-
-```bash
-# Interactive decryption
-proxsave --decrypt
-```
-
----
-
## Configure Recipients
-Recipients are public keys or passphrases that can decrypt backups. A backup encrypted for **N recipients** can be decrypted by **any of the N private keys/passphrases**.
+Recipients identify the public keys used to encrypt an archive. Any matching private
+identity can decrypt an archive encrypted for multiple recipients. ProxSave's
+passphrase setup derives an X25519 identity and recipient using the installation's
+salt; a public recipient alone cannot decrypt a backup.
### Static Configuration
@@ -284,18 +452,7 @@ SSH recipients carry their own asymmetry, in the opposite direction:
### Interactive Wizard
-The everyday route is the dashboard: **Maintenance** > **New key**. It runs the same
-recipient setup as the flags below, in the same session.
-
-The flags reach it without the dashboard, on a headless host or from a script:
-
-```bash
-# Dedicated wizard (TUI by default)
-proxsave --newkey
-
-# Use CLI prompts instead of TUI (useful for debugging or when TUI rendering is unavailable)
-proxsave --newkey --cli
-```
+Setup requirements and supported input forms follow. Use the [encryption task](#encrypt-backups-and-preserve-recovery-keys) for the dashboard procedure and [CLI_REFERENCE.md](CLI_REFERENCE.md) for text-mode entry points.
If `ENCRYPT_ARCHIVE=true` and no recipients are configured, proxsave will start an interactive setup automatically during the backup (only when running in a real terminal).
@@ -317,190 +474,6 @@ is also rejected outright.
---
-## Running Encrypted Backups
-
-### Prerequisites
-
-1. `ENCRYPT_ARCHIVE=true` in `configs/backup.env`
-2. At least one recipient configured via `AGE_RECIPIENT` and/or `AGE_RECIPIENT_FILE`
-3. File permissions and ownership checked automatically (0700 directory, 0600 recipient file, owned root:root; auto-fixed when `AUTO_FIX_PERMISSIONS=true`, otherwise a warning)
-
-### Backup Execution
-
-Nothing about the run changes when encryption is on, so it is the ordinary backup: the
-resident daemon on schedule, the dashboard **Backup** row when you want one now, or
-`proxsave --backup` from a script or a headless host.
-
-```bash
-proxsave --backup
-```
-
-**Encryption flow**:
-
-```text
-┌─────────────────────────────────────────────┐
-│ Phase 1: Backup Collection │
-│ - Gather PVE/PBS/System files │
-│ - Stage them IN THE CLEAR under │
-│ /tmp/proxsave/proxsave--- │
-│ (mode 0700, root only) │
-└─────────────┬───────────────────────────────┘
- │
- ▼
-┌─────────────────────────────────────────────┐
-│ Phase 2: Streaming Encryption │
-│ - Stream the staging tree as a tar through │
-│ the compressor into AGE (ChaCha20-Poly1305)│
-│ - Write to -backup-YYYYMMDD-HHMMSS.tar..age │
-│ - NO plaintext ARCHIVE on disk │
-└─────────────┬───────────────────────────────┘
- │
- ▼
-┌─────────────────────────────────────────────┐
-│ Phase 3: Storage Distribution │
-│ - Local: BACKUP_PATH/ │
-│ - Secondary: SECONDARY_PATH/ (optional) │
-│ - Cloud: rclone (optional) │
-└─────────────────────────────────────────────┘
-```
-
-**Output file format**:
-
-```text
-backup/
-└── pve-node1-backup-20240115-023000.tar.xz.age.bundle.tar # Typical (bundling enabled)
-```
-
-**If bundling is disabled** (`BUNDLE_ASSOCIATED_FILES=false`), proxsave keeps the raw artifacts:
-
-```text
-backup/
-├── pve-node1-backup-20240115-023000.tar.xz.age
-├── pve-node1-backup-20240115-023000.tar.xz.age.sha256
-├── pve-node1-backup-20240115-023000.tar.xz.age.metadata
-└── pve-node1-backup-20240115-023000.tar.xz.age.manifest.json
-```
-
-**Manifest structure** (used during restore):
-
-```json
-{
- "archive_path": "/opt/proxsave/backup/pve-node1-backup-20240115-023000.tar.xz.age",
- "archive_size": 1234567890,
- "sha256": "...",
- "created_at": "2024-01-15T02:30:00Z",
- "compression_type": "xz",
- "hostname": "pve-node1",
- "encryption_mode": "age",
- "passphrase_salt": "proxsave/age-passphrase/v2:1a2b3c..."
-}
-```
-
-`passphrase_salt` is omitted entirely for X25519 or SSH-only setups, and for legacy
-fixed-salt archives.
-
----
-
-## Decrypting Backups
-
-The decrypt workflow converts an encrypted backup into a decrypted bundle for inspection or
-transfer. In the dashboard it is **Tools** > **Decrypt**; the flag reaches the same flow on
-a headless host (add `--cli` for text-mode prompts):
-
-```bash
-proxsave --decrypt
-```
-
-**High-level flow**:
-1. Select backup source (primary/secondary/cloud)
-2. Select an encrypted backup
-3. Select destination folder (default: `./decrypt` or `${BASE_DIR}/decrypt`)
-4. When prompted, enter:
- - an AGE private key (`AGE-SECRET-KEY-...`), or
- - the passphrase you used (proxsave derives the matching identity; the passphrase is not stored)
-
-**Output**:
-- A decrypted bundle saved as `*.decrypted.bundle.tar`. That is itself a plain tar holding
- the decrypted archive plus its `.metadata` and `.sha256`, so `tar -xf` it to get the
- archive out.
-
-If you need fully scripted/non-interactive decryption with a **private key**, use the
-official `age` CLI. With bundling left at its default the raw `.age` is not on disk, so
-unwrap the bundle first (see [Emergency Decryption Without
-Configuration](#emergency-decryption-without-configuration)):
-
-```bash
-# 0700 workspace: the decrypted archive below is plaintext and /tmp is shared.
-install -d -m 700 /tmp/emergency
-tar -xf -backup-YYYYMMDD-HHMMSS.tar.xz.age.bundle.tar -C /tmp/emergency
-age --decrypt -i /path/to/age-keys.txt \
- /tmp/emergency/-backup-YYYYMMDD-HHMMSS.tar.xz.age \
- > /tmp/emergency/-backup-YYYYMMDD-HHMMSS.tar.xz
-rm -rf /tmp/emergency # once you have what you needed
-```
-
-> **Passphrase recipients are not native age passphrases.** A passphrase recipient
-> is an X25519 key *derived* from the passphrase, so the raw `age --decrypt` (which
-> only understands age's own scrypt passphrase stanza) cannot decrypt it from the
-> passphrase alone, use `proxsave --decrypt`. proxsave re-derives the identity from
-> the passphrase plus the **per-installation random salt** generated at setup, which
-> is stored next to the recipient (`identity/age/passphrase.salt`, mirrored as the
-> `# passphrase-salt:` line in the recipient file) and embedded in every backup manifest
-> (`passphrase_salt`) so recovery works on any host. The emergency `age` CLI path above
-> therefore needs an `AGE-SECRET-KEY-...` identity file; a passphrase-only holder must use
-> `proxsave --decrypt`, which reads the bundle directly.
->
-> **Decryption never reads `recipient.txt` or `passphrase.salt`.** The salt travels inside
-> each archive's manifest, so an existing backup stays openable with its passphrase even if
-> both local copies are gone. See [Emergency
-> Scenarios](#emergency-scenarios) for how to rebuild them from an archive.
-
----
-
-## Restoring Encrypted Backups
-
-Encrypted backups are restored through the standard restore workflow, which handles the
-decryption automatically. In the dashboard it is **Tools** > **Restore**; the flag reaches
-the same flow on a headless host (add `--cli` for text-mode prompts).
-
-### Quick Restore Summary
-
-```bash
-# Interactive restore (decrypts automatically)
-proxsave --restore
-```
-
-**Restore workflow with encryption**:
-
-1. **Select backup** → Choose encrypted `.age` file
-2. **Decrypt** → Provide key or passphrase when prompted
-3. **Choose restore mode** → Full/Storage/Base/Custom
-4. **Select categories** → PVE configs, PBS datastores, etc.
-5. **Review and confirm** → Safety checks before applying
-6. **Extract files** → Categories restored to system
-
-**Decryption options during restore**:
-- **Key or passphrase**: Prompted interactively when needed
-- **Multiple recipients**: Any X25519 recipient that matches the archive can decrypt it. An SSH recipient cannot be used here; see the warning in the recipients section
-
-### Detailed Restore Documentation
-
-For complete restore workflows, category details, safety features, and cluster recovery procedures, see:
-
-- **[Restore Guide](RESTORE_GUIDE.md)** - Complete user guide with all restore modes
-- **[Restore Technical](RESTORE_TECHNICAL.md)** - Technical architecture and internals
-- **[Cluster Recovery](CLUSTER_RECOVERY.md)** - Advanced cluster disaster recovery
-
-**Key topics covered in restore docs**:
-- 4 restore modes (Full/Storage/Base/Custom)
-- 15+ category reference
-- Service management for cluster databases
-- Safety features and rollback procedures
-- Post-restore verification
-- Troubleshooting
-
----
-
## Key Rotation
Rotating encryption keys periodically improves security (recommended annually or after key compromise).
@@ -553,9 +526,7 @@ To really drop a compromised recipient, clear all of these:
Then run the recipient setup, from the dashboard (**Maintenance** > **New key**) or the
flag:
-```bash
-proxsave --newkey
-```
+Choose **Maintenance** > **New key** in the dashboard.
If the target recipient file already exists, `--newkey` asks for confirmation and copies the
old file to `.bak-` itself before overwriting. If it does not exist, for
@@ -568,12 +539,95 @@ variable, `--newkey` does replace the effective recipient set.
---
+## Security Notes
+
+### Security Best Practices
+
+| Practice | Implementation |
+|----------|----------------|
+| **Passphrase handling** | CLI entry uses `term.ReadPassword` (no echo); the TUI uses its password input |
+| **Memory security** | Explicit buffers are cleared where implemented, but immutable Go strings and other copies cannot be guaranteed to be overwritten |
+| **Streaming encryption** | No plaintext **archive** on disk during backup. Backup and restore staging are removed on normal completion; abrupt termination can leave plaintext behind. Restore safety archives are retained separately: see [Plaintext staging](#plaintext-staging) |
+| **File permissions & ownership** | Enforced 0700/0600 and root:root on recipient/identity files (auto-fixed with `AUTO_FIX_PERMISSIONS`, otherwise warned) |
+| **Private key storage** | **Keep offline** (password manager, hardware token, printed backup) |
+| **Backup separation** | Store keys separately from backup media |
+| **Access control** | Limit who has decryption keys |
+
+### Private Key Protection
+
+A private identity unlocks every backup encrypted to its matching recipient. Protect it as carefully as the data it can reveal.
+
+**Storage recommendations** (choose 2+ for redundancy):
+
+1. **Password manager** (1Password, Bitwarden, KeePassXC)
+ - Encrypted vault with strong master password
+ - Accessible from multiple devices
+ - Regular backups
+
+2. **Hardware token** (YubiKey, Nitrokey)
+ - Physical device required for decryption
+ - Resistant to remote attacks
+ - Risk: device loss
+
+3. **Printed paper backup**
+ - QR code + text format
+ - Store in safe or safety deposit box
+ - Immune to digital attacks
+
+4. **Offline encrypted USB**
+ - LUKS/VeraCrypt encrypted volume
+ - Store in secure physical location
+ - Air-gapped from network
+
+**Never**:
+- Store private keys on the same server as backups
+- Commit private keys to git repositories
+- Email private keys (even encrypted)
+- Store in cloud drives without additional encryption
+
+### Threat Model
+
+**Protected against**:
+- Backup media theft (encrypted at rest)
+- Unauthorized access to backup storage
+- Archive tampering (authenticated encryption)
+- Network interception (if using rclone with encryption)
+
+**Not protected against**:
+- Compromise of the server during a backup. While a backup runs, the collected files sit unencrypted under `/tmp/proxsave` (see [Plaintext staging](#plaintext-staging)); a root-level compromise in that window sees everything in the clear
+- Private key theft from offline storage
+- Weak passphrase brute-force
+- Advanced persistent threats on backup server
+
+**Mitigation strategies**:
+- Run backups on isolated systems
+- Use hardware security modules (HSM) for production
+- Implement key splitting (Shamir's Secret Sharing)
+- Regular security audits
+
+### Compliance Considerations
+
+Archive encryption is one technical control. ProxSave does not establish or certify
+compliance with GDPR, HIPAA, PCI DSS or SOC 2. Any assessment must also cover the
+deployment, access controls, key management, plaintext staging and operational procedures.
+
+**Diagnostics**: `DEBUG_LEVEL=advanced`, `DEBUG_LEVEL=extreme` or `--log-level debug`
+records additional operational details. Review diagnostic output before sharing it;
+it is not a compliance audit trail.
+
+---
+
+
+## Recovery reference
+
+The task above is the operator procedure. The following material preserves detailed behavior, limits and implementation context.
+
## Emergency Scenarios
| Scenario | Solution |
|----------|----------|
| **Lost passphrase/private key** | **No recovery possible**. Keep 2+ offline copies (password manager, printed paper). |
-| **Migrating to new server** | Copy the whole `identity/age/` directory byte for byte, **`passphrase.salt` included**, plus your `configs/backup.env`. `passphrase.salt` is the file that matters: the setup wizard reads only that one, and if it is missing it mints a new random salt and derives a **different** recipient without warning. The `# passphrase-salt:` copy inside `recipient.txt` only feeds the manifest, so do not rely on it alone and do not retype the recipient file. Alternatively run `proxsave --newkey` on the new host and accept a new recipient. Keep private keys offline. |
+| **Migrating to new server** | Copy the whole `identity/age/` directory byte for byte, **`passphrase.salt` included**, plus your `configs/backup.env`. `passphrase.salt` is the file that matters: the setup wizard reads only that one, and if it is missing it mints a new random salt and derives a **different** recipient without warning. The `# passphrase-salt:` copy inside `recipient.txt` only feeds the manifest, so do not rely on it alone and do not retype the recipient file. Alternatively choose **Maintenance** > **New key** on the new host and accept a new recipient. Keep private keys offline. |
| **Verifying integrity** | Periodically decrypt a backup (or run a restore in a test VM) to ensure keys and archives are valid. |
| **Automation** | Headless runs require recipients pre-configured (`AGE_RECIPIENT` and/or `AGE_RECIPIENT_FILE`). |
| **Recipient file overwritten** | Restore from `recipient.txt.bak-*`. ProxSave writes that copy itself whenever `--newkey` overwrites an existing recipient file. |
@@ -634,7 +688,7 @@ Notes on this recipe:
`passphrase_salt` without touching the archive.
- This path needs an `AGE-SECRET-KEY-...` identity. A passphrase cannot be fed to the `age`
CLI (see the note under [Decrypting Backups](#decrypting-backups)); use
- `proxsave --decrypt`, which reads the bundle directly. It only lists backups found under
+ the dashboard **Tools** > **Decrypt** workflow, which reads the bundle directly. It only lists backups found under
the configured primary, secondary or cloud path, so a bundle carried in on removable media
has to be placed on one of those paths first.
@@ -688,192 +742,60 @@ rm -f /tmp/emergency/archive.inner
---
-## Security Notes
-
-### Encryption Implementation
-
-- **Algorithm**: ChaCha20-Poly1305 (AEAD) with X25519 ECDH
-- **Key derivation**: scrypt (N=2^15, r=8, p=1) for passphrases. The current scheme uses a **per-installation random salt** (v2), generated once, stored `0600` at `identity/age/passphrase.salt`, mirrored as the `# passphrase-salt:` line inside the recipient file (every backup rewrites that comment from the sibling before reading it back, so the sibling wins whenever the two differ; once the sibling is gone the comment still supplies the salt stamped into new manifests, but it can **not** re-derive the recipient, because the setup wizard reads the sibling alone and mints a fresh random salt when it is missing, yielding a different recipient), and embedded in each manifest as `passphrase_salt` so the passphrase alone can re-derive the recipient on any host. At decrypt ProxSave tries salts in order: the manifest's per-install salt first, then two fixed legacy namespaces (`proxsave/age-passphrase/v1`, then the pre-rebrand `proxmox-backup-go/age-passphrase/v1`), so archives from older versions and from before the rename stay decryptable.
-- **Random nonces**: Unique per encryption operation
-- **Authentication**: Poly1305 MAC prevents tampering
-
-### Security Best Practices
-
-| Practice | Implementation |
-|----------|----------------|
-| **Passphrase handling** | Read with `term.ReadPassword` (no echo) |
-| **Memory security** | Buffers zeroed immediately after use |
-| **Streaming encryption** | No plaintext **archive** on disk. The backup staging tree is removed when the run ends, but not on `SIGKILL`, power loss or a double Ctrl-C, and a restore leaves its own staging tree and safety tarballs behind: see [Plaintext staging](#plaintext-staging) |
-| **File permissions & ownership** | Enforced 0700/0600 and root:root on recipient/identity files (auto-fixed with `AUTO_FIX_PERMISSIONS`, otherwise warned) |
-| **Private key storage** | **Keep offline** (password manager, hardware token, printed backup) |
-| **Backup separation** | Store keys separately from backup media |
-| **Access control** | Limit who has decryption keys |
-
-### Private Key Protection
-
-**CRITICAL**: Private keys allow decryption of ALL backups. Protect them as you would the data itself.
-
-**Storage recommendations** (choose 2+ for redundancy):
-
-1. **Password manager** (1Password, Bitwarden, KeePassXC)
- - Encrypted vault with strong master password
- - Accessible from multiple devices
- - Regular backups
-
-2. **Hardware token** (YubiKey, Nitrokey)
- - Physical device required for decryption
- - Resistant to remote attacks
- - Risk: device loss
-
-3. **Printed paper backup**
- - QR code + text format
- - Store in safe or safety deposit box
- - Immune to digital attacks
-
-4. **Offline encrypted USB**
- - LUKS/VeraCrypt encrypted volume
- - Store in secure physical location
- - Air-gapped from network
-
-**Never**:
-- ❌ Store private keys on the same server as backups
-- ❌ Commit private keys to git repositories
-- ❌ Email private keys (even encrypted)
-- ❌ Store in cloud drives without additional encryption
-
-### Threat Model
-
-**Protected against**:
-- ✅ Backup media theft (encrypted at rest)
-- ✅ Unauthorized access to backup storage
-- ✅ Archive tampering (authenticated encryption)
-- ✅ Network interception (if using rclone with encryption)
-
-**Not protected against**:
-- ❌ Compromise of the server during a backup. While a backup runs, the collected files sit unencrypted under `/tmp/proxsave` (see [Plaintext staging](#plaintext-staging)); a root-level compromise in that window sees everything in the clear
-- ❌ Private key theft from offline storage
-- ❌ Weak passphrase brute-force
-- ❌ Advanced persistent threats on backup server
-
-**Mitigation strategies**:
-- Run backups on isolated systems
-- Use hardware security modules (HSM) for production
-- Implement key splitting (Shamir's Secret Sharing)
-- Regular security audits
-
-### Compliance Considerations
-
-AGE encryption meets requirements for:
-
-- **GDPR**: Personal data encrypted at rest and in transit
-- **HIPAA**: PHI encrypted with industry-standard algorithms
-- **PCI DSS**: Cardholder data encrypted per Requirement 3.4
-- **SOC 2**: Encryption controls for confidentiality
-
-**Audit trail**: Use `DEBUG_LEVEL=advanced` (or `DEBUG_LEVEL=extreme`) and/or run with `--log-level debug` to log encryption-related operations (never keys/passphrases).
-
----
-
-## Related Documentation
+## External AGE extraction reference
-### Configuration
-- **[Configuration Guide](CONFIGURATION.md)** - Complete variable reference including all AGE settings
-- **[Cloud Storage Guide](CLOUD_STORAGE.md)** - rclone integration with encrypted cloud backups
-
-### Restore Operations
-- **[Restore Guide](RESTORE_GUIDE.md)** - Complete restore workflows (all modes)
-- **[Restore Technical](RESTORE_TECHNICAL.md)** - Technical implementation details
-- **[Cluster Recovery](CLUSTER_RECOVERY.md)** - Disaster recovery procedures
-
-### Reference
-- **[Dashboard](DASHBOARD.md)** - The interactive menu: New key, Backup, Decrypt, Restore
-- **[Daemon](DAEMON.md)** - The resident scheduler that runs the encrypted backups
-- **[CLI Reference](CLI_REFERENCE.md)** - All command flags including `--decrypt`, `--newkey`
-- **[Troubleshooting](TROUBLESHOOTING.md)** - Common encryption/decryption issues
-- **[Examples](EXAMPLES.md)** - Real-world encrypted backup scenarios
-
-### Main Documentation
-- **[README](../README.md)** - Project overview and quick start
-
----
-
-## Quick Reference
-
-### Environment Variables
+If you need fully scripted/non-interactive decryption with a **private key**, use the
+official `age` CLI. With bundling left at its default the raw `.age` is not on disk, so
+unwrap the bundle first (see [Emergency Decryption Without
+Configuration](#emergency-decryption-without-configuration)):
```bash
-# Enable encryption
-ENCRYPT_ARCHIVE=true # Master switch
-
-# Recipient configuration
-# The shipped template sets this; the compiled-in default is empty and resolves to the same path.
-# --newkey rewrites whatever this points at, so check it before assuming the default.
-AGE_RECIPIENT_FILE=${BASE_DIR}/identity/age/recipient.txt # Public recipients (recommended)
-
-# Optional: inline recipients (merged with file; supports comma/semicolon/pipe/newline)
-# AGE_RECIPIENTS (plural) is accepted as a fallback alias, used only when AGE_RECIPIENT is empty
-AGE_RECIPIENT=age1abc123...,age1def456...
+# 0700 workspace: the decrypted archive below is plaintext and /tmp is shared.
+install -d -m 700 /tmp/emergency
+tar -xf -backup-YYYYMMDD-HHMMSS.tar.xz.age.bundle.tar -C /tmp/emergency
+age --decrypt -i /path/to/age-keys.txt \
+ /tmp/emergency/-backup-YYYYMMDD-HHMMSS.tar.xz.age \
+ > /tmp/emergency/-backup-YYYYMMDD-HHMMSS.tar.xz
+rm -rf /tmp/emergency # once you have what you needed
```
-### Common Commands
-
-On a terminal, `proxsave` with no arguments opens the dashboard, where these are
-**Maintenance** > **New key**, **Backup**, **Tools** > **Decrypt** and **Tools** >
-**Restore**. The flags below reach the same flows without the dashboard, on a headless host
-or from a script; add `--cli` when the terminal cannot draw the TUI.
-
-```bash
-# Generate new keys
-proxsave --newkey
-
-# Run encrypted backup
-proxsave --backup
-
-# Decrypt backup (interactive)
-proxsave --decrypt
+> **Passphrase recipients are not native age passphrases.** A passphrase recipient
+> is an X25519 key *derived* from the passphrase, so the raw `age --decrypt` (which
+> only understands age's own scrypt passphrase stanza) cannot decrypt it from the
+> passphrase alone, use **Tools** > **Decrypt**. ProxSave re-derives the identity from
+> the passphrase plus the **per-installation random salt** generated at setup, which
+> is stored next to the recipient (`identity/age/passphrase.salt`, mirrored as the
+> `# passphrase-salt:` line in the recipient file) and embedded in every backup manifest
+> (`passphrase_salt`) so recovery works on any host. The emergency `age` CLI path above
+> therefore needs an `AGE-SECRET-KEY-...` identity file; a passphrase-only holder must use
+> the dashboard **Tools** > **Decrypt** workflow, which reads the bundle directly.
+>
+> **Decryption never reads `recipient.txt` or `passphrase.salt`.** The salt travels inside
+> each archive's manifest, so an existing backup stays openable with its passphrase even if
+> both local copies are gone. See [Emergency
+> Scenarios](#emergency-scenarios) for how to rebuild them from an archive.
-# Restore from encrypted backup
-proxsave --restore
+---
-# Manual decryption (scriptable) with age CLI, straight out of the bundle
-tar -xOf -backup-YYYYMMDD-HHMMSS.tar.xz.age.bundle.tar \
- -backup-YYYYMMDD-HHMMSS.tar.xz.age \
- | age --decrypt -i /path/to/age-keys.txt > -backup-YYYYMMDD-HHMMSS.tar.xz
-```
-### File paths in these examples
+## Earlier guide entry points
-`BASE_DIR` is auto-detected from the installed executable and is **not** a shell variable:
-substitute your install root (typically `/opt/proxsave`) when pasting any path that uses it.
+## Features
-### File Locations
+See the complete [operator procedure](#encrypt-backups-and-preserve-recovery-keys). Detailed settings and implementation material remain in the reference sections above.
-```text
-configs/
-└── backup.env # Environment variables
+## Overview
-identity/
-└── age/
- ├── recipient.txt # Public recipients, plus the "# passphrase-salt:" line (0600)
- ├── passphrase.salt # Per-installation passphrase salt (0600, passphrase setups only)
- └── recipient.txt.bak-* # Written by --newkey when it overwrites an existing file
+See the complete [operator procedure](#encrypt-backups-and-preserve-recovery-keys). Detailed settings and implementation material remain in the reference sections above.
-backup/
-└── -backup-*.tar.[.age][.bundle.tar]
-```
+## Quick Start
-### Key Formats
+See the complete [operator procedure](#encrypt-backups-and-preserve-recovery-keys). Detailed settings and implementation material remain in the reference sections above.
-**Public key (X25519)**:
-```text
-age1abc123def456ghi789jkl012mno345pqr678stu901vwx234yz567abc
-```
+## Restoring Encrypted Backups
-**Private key (X25519)**:
-```text
-AGE-SECRET-KEY-1ABC123DEF456GHI789JKL012MNO345PQR678STU901VWX234YZ567ABC
-```
+See the complete [operator procedure](#decrypting-backups). Detailed settings and implementation material remain in the reference sections above.
----
+## Running Encrypted Backups
-**For complete AGE specification**, see: https://age-encryption.org/v1
+See the complete [operator procedure](#encrypt-backups-and-preserve-recovery-keys). Detailed settings and implementation material remain in the reference sections above.
diff --git a/docs/EXAMPLES.md b/docs/EXAMPLES.md
index 95fc5c0e..77aa97cb 100644
--- a/docs/EXAMPLES.md
+++ b/docs/EXAMPLES.md
@@ -1,1311 +1,225 @@
-# Practical Examples
-
-Real-world configuration examples for ProxSave covering common deployment scenarios.
-
-Everything below is reached the same way: run `proxsave` with no arguments on a terminal
-and the interactive dashboard opens. That is where you install, edit the configuration,
-run a backup, restore, upgrade, and manage the scheduler. The command-line flags shown
-next to each example are the automation and recovery route, for cron jobs, scripts and
-hosts where the dashboard cannot run.
-
-## Table of Contents
-
-- [Start with the dashboard](#start-with-the-dashboard)
-- [Overview](#overview)
-- [Example 1: Basic Local Backup](#example-1-basic-local-backup)
-- [Example 2: Local + Secondary Storage](#example-2-local--secondary-storage)
-- [Example 3: Cloud Backup with Google Drive](#example-3-cloud-backup-with-google-drive)
-- [Example 4: Encrypted Backup with AGE](#example-4-encrypted-backup-with-age)
-- [Example 5: Backblaze B2 with Bandwidth Limiting](#example-5-backblaze-b2-with-bandwidth-limiting)
-- [Example 6: MinIO Self-Hosted with High Performance](#example-6-minio-self-hosted-with-high-performance)
-- [Example 7: Multi-Notification Setup](#example-7-multi-notification-setup)
-- [Example 8: Complete Production Setup](#example-8-complete-production-setup)
-- [Example 9: Test in a Chroot/Fixture](#example-9-test-in-a-chrootfixture)
-- [HA-LXC Backup Appliance (HOST_BACKUP_MODE)](#ha-lxc-backup-appliance-host_backup_mode)
-- [Example 10: Dual PVE+PBS Host](#example-10-dual-pvepbs-host)
-- [Example 11: Resident daemon and healthchecks monitoring](#example-11-resident-daemon-and-healthchecks-monitoring)
-- [Quick Comparison Matrix](#quick-comparison-matrix)
-- [Customization Tips](#customization-tips)
-- [Related Documentation](#related-documentation)
-
----
+# Practical examples
-## Start with the dashboard
-
-`proxsave`, typed bare on a terminal, opens the dashboard. It is a launcher: every row that
-has a matching flag runs the same code as that flag, so nothing you do there behaves
-differently from the command line. The rows marked `(dashboard only)` below have no flag.
-The full walkthrough is in [DASHBOARD.md](DASHBOARD.md); this is the map from the tasks in
-this guide to the rows that perform them.
-
-| You want to | Dashboard route | Same thing from a script |
-|---|---|---|
-| Install or re-install | `Maintenance` -> `Install` -> `Edit install` | `proxsave --install` |
-| Start over on a dirty install | `Maintenance` -> `Install` -> `Wipe install` | `proxsave --new-install` |
-| Change the configuration | `Maintenance` -> `Install` -> `Edit install`, then `Edit existing` | edit `configs/backup.env` by hand |
-| Run a backup now | `Backup` -> `Backup` | `proxsave --backup` |
-| Restore a backup | `Tools` -> `Restore` | `proxsave --restore` |
-| Decrypt an encrypted bundle | `Tools` -> `Decrypt` | `proxsave --decrypt` |
-| Create the AGE encryption key | `Maintenance` -> `New key` | `proxsave --newkey` |
-| Update the binary | `Maintenance` -> `Upgrade` -> `Check upgrade` | `proxsave --upgrade` |
-| Add new template keys to `backup.env` | `Maintenance` -> `Upgrade` -> `Check config` | `proxsave --upgrade-config` |
-| Switch the scheduler to the daemon | `Daemon` -> `Install` | `proxsave --daemon-setup` |
-| Go back to cron | `Daemon` -> `Disable` | `proxsave --daemon-remove` |
-| Check the scheduler state | `Daemon` -> `Status` | `proxsave --daemon-status` |
-| Verify Telegram pairing | `Diagnostic Checks` -> `Telegram` | (dashboard only) |
-| Verify backup monitoring | `Diagnostic Checks` -> `Healthchecks` | (dashboard only) |
-| Re-run the post-install audit | `Diagnostic Checks` -> `Post-install` | (dashboard only) |
-| Send a support report | `Recovery` -> `Support` | `proxsave --support` |
-| Clear leftover restore mount guards | `Recovery` -> `Cleanup guards` | `proxsave --cleanup-guards` |
-
-Two things to know before you rely on it:
-
-- The dashboard opens only when `proxsave` is invoked completely bare and both stdin and
- stdout are real terminals. Any flag at all, `--config` included, skips it. Everything
- else, cron and the daemon included, runs the backup directly.
-- It opens before the configuration is loaded, so it works on a host whose `backup.env`
- is missing or broken. That is the intended way to repair one.
-
-### The configuration form
-
-`Install` -> `Edit install` is the graphical editor for the settings most installs need.
-Choose `Edit existing` when asked about the current file and the form is pre-filled from
-it; `Overwrite` starts from the shipped template instead. The form covers secondary
-storage, cloud storage, firewall-rule collection, Telegram, email and its delivery mode,
-encryption, the scheduler engine, healthchecks monitoring, and the daily run time.
-Everything else in `backup.env` is edited by hand; which block lives where is listed in
-[CONFIGURATION.md](CONFIGURATION.md).
-
-### Upgrading: which binary runs the upgrade
-
-There are two upgrade routes and they are not equivalent.
-
-**In place**, from the dashboard (`Maintenance` -> `Upgrade` -> `Check upgrade`) or with
-`proxsave --upgrade`. Both run the same code in the binary already installed. That binary
-owns the release check, the download, the signature and checksum verification, and the
-replacement itself; the downloaded binary is untrusted until this one has verified it, so
-it cannot be the party that verifies itself. The `backup.env` merge is then always run by
-the freshly installed binary, and from release 0.36.0 onward the rest of the post-install
-work (documentation refresh, symlinks, legacy cron repointing, daemon migration and
-restart) is handed to it as well. On a host whose installed binary predates 0.36.0 there is
-no such handover: the old release's finalize runs, so anything a newer release changed
-there does not take effect on that upgrade.
-
-**Externally fetched**, which downloads and swaps in the new binary first and only then
-asks it to finish the job:
-
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" -- --upgrade
-```
+These scenarios combine the task guides into a host configuration backup policy. Start with [your first backup](BACKUP_GUIDE.md#run-and-verify-your-first-backup) if you have not yet verified a run
-Every step, the finalize included, is the new release's code. Use this route when the
-installed binary is old, and when an in-place upgrade has misbehaved.
+Open the dashboard with `proxsave` on an interactive terminal. Use **Maintenance > Install > Edit install** for settings exposed by its form; edit other settings in the active configuration file according to the [configuration reference](CONFIGURATION.md). The values below are examples, not installation defaults
-### When to reach for the flags instead
-
-The flags stay fully supported, and they are the right tool in four cases: a headless or
-serial-console host where no TTY is available, a cron job or a script, a run driven by
-configuration management, and recovery on a host where the TUI will not start. Each
-example below shows the flag form for exactly that reason.
+## Start with the dashboard
----
+Choose **Backup** to run the configured backup, **Tools > Restore** to recover settings, and **Daemon > Status** to inspect scheduling. Review [the dashboard guide](DASHBOARD.md) for the actual menu and terminal requirements. Automation and alternate configuration files are covered separately in the [CLI reference](CLI_REFERENCE.md)
## Overview
-This guide provides complete, copy-paste ready configuration examples for common deployment scenarios. Each example includes:
-
-- **Scenario description**: What problem it solves
-- **Complete configuration**: Ready-to-use `backup.env` settings
-- **Step-by-step setup**: The dashboard route, and the equivalent commands
-- **Scheduling**: The daemon, or a cron entry where cron is the chosen engine
-- **Expected results**: What to expect after setup
-
-**How to use these examples**:
-1. Choose the example closest to your use case
-2. Open the dashboard (`proxsave`) and set what the form covers under `Install` -> `Edit install`
-3. Put the remaining variables in `configs/backup.env`
-4. Adjust paths, credentials, and parameters for your environment
-5. Test with `DRY_RUN=true` or `proxsave --dry-run` before production use
-6. Let the resident daemon schedule the run; it is already the engine on a fresh install,
- and `Daemon` -> `Install` switches a host that is still on cron
-
----
-
-## Example 1: Basic Local Backup
-
-**Scenario**: Single server, local backup only, simple retention.
-
-**Use case**:
-- Standalone Proxmox VE or PBS server
-- No cloud storage requirements
-- Simple daily backups
-- Fast local SSD/NVMe storage
-
-### Configuration
-
-```bash
-# configs/backup.env
-BACKUP_ENABLED=true
-BACKUP_PATH=/opt/proxsave/backup
-LOG_PATH=/opt/proxsave/log
-
-# Compression
-COMPRESSION_TYPE=xz
-COMPRESSION_LEVEL=6
-COMPRESSION_MODE=standard
-
-# Retention: Keep 15 backups
-MAX_LOCAL_BACKUPS=15
-```
-
-### Setup Steps
-
-From the dashboard:
-
-1. Run `proxsave` to open it.
-2. `Maintenance` -> `Install` -> `Edit install`, and walk the configuration form.
-3. Put `BACKUP_PATH`, `LOG_PATH`, the compression variables and `MAX_LOCAL_BACKUPS` in
- `configs/backup.env` by hand; the form does not cover them.
-4. `Daemon` -> `Status` to confirm the resident service is the scheduler. A fresh install
- already selects it, so the group offers `Disable` and `Restart`; a host still on cron
- offers `Install` instead, and that is the row that switches it.
-5. `Backup` -> `Backup` to run the first one now and watch the log stream on screen.
-
-The same steps without a TTY:
-
-```bash
-# 1. Install
-proxsave --install
-# (use --new-install to wipe everything except build/, daemon_state/, env/, guards/, identity/, and restore/ before installing)
-
-# 2. Edit configuration
-nano /opt/proxsave/configs/backup.env
-# (paste configuration above)
-
-# 3. Test
-proxsave --dry-run
-
-# 4. Run first backup
-proxsave --backup
-```
-
-### Scheduling
-
-A fresh install schedules the backup through the resident daemon
-(`proxsave-daemon.service`), daily at `SCHEDULER_TIME` unless `SCHEDULER_FREQUENCY` says
-weekly or monthly. Nothing more is needed. See
-[Example 11](#example-11-resident-daemon-and-healthchecks-monitoring) and
-[DAEMON.md](DAEMON.md).
-
-Only if you have deliberately opted out of the daemon (`SCHEDULER_MODE=cron`) does a cron
-entry apply. ProxSave writes that entry itself; hand-editing the crontab is the legacy
-path:
-
-```bash
-# Daily backup at 2 AM, the canonical entry ProxSave writes
-crontab -e
-
-0 2 * * * /usr/local/bin/proxsave --backup >> /var/log/pbs-backup.log 2>&1
-```
-
-### Expected Results
-
-```text
-Backup directory: /opt/proxsave/backup/
-- -backup-20240115-020000.tar.xz.bundle.tar
-```
+| Scenario | Purpose |
+| --- | --- |
+| [Multiple destinations](#example-8-complete-production-setup) | Combine local/NAS/cloud copies, encryption and result monitoring |
+| [Alternate system root](#example-9-test-in-a-chrootfixture) | Collect a mounted test tree on an isolated disposable host |
+| [Host backup appliance](#ha-lxc-backup-appliance-host_backup_mode) | Collect a host filesystem mounted into an LXC |
+| [Dual-role host](#example-10-dual-pvepbs-host) | Protect a host with PVE and PBS installed together |
+| [Scheduled monitoring](#example-11-resident-daemon-and-healthchecks-monitoring) | Combine recurring backups with missing-run detection |
-If you disable bundling (`BUNDLE_ASSOCIATED_FILES=false`), proxsave keeps the raw archive plus sidecar files (`.sha256`, `.metadata`, `.manifest.json`).
-
-**Retention**: Automatically keeps latest 15 backups, deletes older ones.
+## Example 8: Complete Production Setup
-**Backup size**: Typically 500MB-2GB depending on system configuration.
+This example combines multiple destinations, AGE encryption and retention. Adapt it to the host and test every destination; enabling more features does not by itself prove that a backup is recoverable
----
+### Prerequisites for the combined policy
-## Example 2: Local + Secondary Storage
+- A working ProxSave installation and a verified initial backup
+- A secondary filesystem mounted at the intended NAS path before the run
+- An rclone remote configured for the account that runs ProxSave
+- AGE recovery material stored independently of this host
+- Enough destination capacity for the proposed retention policy
-**Scenario**: Local SSD + secondary NAS, different retention.
+Configure the basic destination and encryption choices in **Maintenance > Install > Edit install**. Create or configure recipients through **Maintenance > New key**, following the [encryption guide](ENCRYPTION.md). Do not rotate keys without retaining the identities needed for existing archives
-**Use case**:
-- Local SSD for fast backup creation
-- NAS/network storage for longer retention
-- Different retention policies per tier
-- Cost optimization (expensive SSD, cheap NAS)
+The following configuration illustrates the additional policy values. Replace existing assignments in the active configuration; do not append a second set of competing keys or aliases
-### Configuration
-
-```bash
-# configs/backup.env
+```ini
BACKUP_ENABLED=true
BACKUP_PATH=/opt/proxsave/backup
LOG_PATH=/opt/proxsave/log
-# Secondary storage (NAS)
SECONDARY_ENABLED=true
-SECONDARY_PATH=/mnt/nas/pbs-backup
-SECONDARY_LOG_PATH=/mnt/nas/pbs-log
-
-# Retention
-MAX_LOCAL_BACKUPS=7 # 1 week local (SSD expensive)
-MAX_SECONDARY_BACKUPS=30 # 1 month secondary (NAS cheap)
-```
-
-### Setup Steps
-
-Mount the share first; ProxSave copies to a filesystem path and never speaks NFS or SMB
-itself:
-
-```bash
-# 1. Mount NAS (example with NFS)
-sudo mkdir -p /mnt/nas
-sudo mount -t nfs 192.168.1.100:/backup /mnt/nas
-
-# Make mount persistent
-echo "192.168.1.100:/backup /mnt/nas nfs defaults 0 0" | sudo tee -a /etc/fstab
-
-# 2. Create backup directories
-mkdir -p /mnt/nas/pbs-backup /mnt/nas/pbs-log
-chmod 700 /mnt/nas/pbs-backup /mnt/nas/pbs-log
-
-# 3. Test write access
-touch /mnt/nas/pbs-backup/test.txt && rm /mnt/nas/pbs-backup/test.txt
-```
-
-Then, in the dashboard: `Maintenance` -> `Install` -> `Edit install`, turn
-**Secondary storage** on and fill in **Secondary backup path** and **Secondary log path**.
-The form validates both before writing them. `MAX_LOCAL_BACKUPS` and
-`MAX_SECONDARY_BACKUPS` are not on the form; set them in `configs/backup.env`. Finish with
-`Backup` -> `Backup`.
-
-The same without a TTY:
-
-```bash
-proxsave --install
-# (use --new-install if you want to reset the install dir first, keeping build/, daemon_state/, env/, guards/, identity/, and restore/)
-# (paste configuration above)
-proxsave --dry-run
-proxsave --backup
-```
-
-### Expected Results
-
-```text
-Local (SSD):
-/opt/proxsave/backup/
-- 7 backups retained (latest week)
-
-Secondary (NAS):
-/mnt/nas/pbs-backup/
-- 30 backups retained (latest month)
-```
-
-**Cost benefit**: Keep only 1 week locally (saves SSD space), 1 month on cheap NAS storage.
-
----
-
-## Example 3: Cloud Backup with Google Drive
-
-**Scenario**: Small business, daily backups, GFS retention, Google Drive.
-
-**Use case**:
-- Small/medium business
-- 15GB free Google Drive tier
-- GFS retention for compliance
-- Daily automated backups
-
-### Setup Steps
-
-#### Step 1: Configure rclone
-
-```bash
-rclone config
-# n > gdrive > drive > [OAuth] > y > q
-rclone mkdir gdrive:pbs-backups
-rclone mkdir gdrive:pbs-logs
-```
-
-#### Step 2: Configure the cloud target
-
-In the dashboard, `Maintenance` -> `Install` -> `Edit install`, turn
-**Cloud backups (rclone)** on and fill in **Rclone backup remote** and
-**Rclone log remote**. Those three fields are all the form writes for cloud storage
-(`CLOUD_ENABLED`, `CLOUD_REMOTE`, `CLOUD_LOG_PATH`). `CLOUD_REMOTE_PATH`, the upload mode,
-the rclone tuning and the retention policy go in `configs/backup.env`:
+SECONDARY_PATH=/mnt/nas/proxsave/backup
+SECONDARY_LOG_PATH=/mnt/nas/proxsave/log
-```bash
-# configs/backup.env
-
-# Cloud storage
CLOUD_ENABLED=true
-CLOUD_REMOTE=gdrive
-CLOUD_REMOTE_PATH=/pbs-backups
-CLOUD_LOG_PATH=/pbs-logs
-CLOUD_UPLOAD_MODE=parallel
-CLOUD_PARALLEL_MAX_JOBS=3
-CLOUD_PARALLEL_VERIFICATION=true
-
-# Google Drive tuning
-RCLONE_TIMEOUT_CONNECTION=60
-RCLONE_TIMEOUT_OPERATION=600
-RCLONE_TRANSFERS=4
-RCLONE_RETRIES=3
-CLOUD_BATCH_SIZE=10
-CLOUD_BATCH_PAUSE=2
-
-# GFS retention (3-year coverage)
-RETENTION_POLICY=gfs
-RETENTION_DAILY=7
-RETENTION_WEEKLY=4
-RETENTION_MONTHLY=12
-RETENTION_YEARLY=3
-```
-
-#### Step 3: Test and Run
-
-Run the backup from the dashboard with `Backup` -> `Backup`; the log streams inside the
-screen and `c` copies it. The scripted equivalent:
-
-```bash
-# Dry-run
-proxsave --dry-run
-
-# Real backup
-proxsave --backup
-
-# Verify
-rclone ls gdrive:pbs-backups/
-rclone ls gdrive:/pbs-logs/
-```
-
-### Expected Results
-
-**GFS retention distribution**:
-- 7 daily backups (last week)
-- 4 weekly backups (last month)
-- 12 monthly backups (last year)
-- 3 yearly backups
-
-**Total**: ~26 backups across 3 years
-
-**Storage calculation** (example):
-- Backup size: 500 MB
-- Total: 26 × 500 MB = 13 GB (fits in 15GB free tier)
-
----
-
-## Example 4: Encrypted Backup with AGE
-
-**Scenario**: Sensitive data, encryption required, cloud storage.
-
-**Use case**:
-- Sensitive personal/business data
-- Compliance requirements (GDPR, HIPAA)
-- Cloud storage with zero-trust model
-- Secure key management
-
-### Setup Steps
-
-#### Step 1: Generate Encryption Key
-
-In the dashboard: `Maintenance` -> `New key`. The wizard offers three sources for the AGE
-recipient (an existing public key, a passphrase, or an existing private key). For the
-passphrase route, enter a strong passphrase (minimum 12 characters, at least 3 character
-classes) and confirm it; the recipient is generated and saved, and the passphrase itself is
-not stored.
-
-The same wizard from a script (a Charm TUI by default; add `--cli` for text prompts):
-
-```bash
-proxsave --newkey
-```
-
-#### Step 2: Configure backup.env
-
-Turn **Backup encryption (AGE)** on in `Maintenance` -> `Install` -> `Edit install`; that
-writes `ENCRYPT_ARCHIVE`. The recipient file path, bundling and the cloud target are
-hand-edited:
-
-```bash
-# configs/backup.env
-
-# Encryption
-ENCRYPT_ARCHIVE=true
-AGE_RECIPIENT_FILE=/opt/proxsave/identity/age/recipient.txt
-
-# Bundle (recommended with encryption)
-BUNDLE_ASSOCIATED_FILES=true
-
-# Cloud storage
-CLOUD_ENABLED=true
-CLOUD_REMOTE=gdrive
-CLOUD_REMOTE_PATH=/pbs-encrypted
-MAX_CLOUD_BACKUPS=30
-```
-
-#### Step 3: Run Backup
-
-`Backup` -> `Backup` in the dashboard, or `proxsave --backup` from a script.
-
-```text
-Result (with bundling enabled): pve01-backup-20240115-020000.tar.xz.age.bundle.tar
-```
-
-#### Step 4: Decrypt (when needed)
-
-In the dashboard: `Tools` -> `Decrypt`. The flow asks for the backup to decrypt, then for
-the AGE key or passphrase in a single secret field, then for the destination directory
-(which defaults to the `decrypt/` folder under `BASE_DIR`). The decrypted archive is
-written there as `.decrypted.bundle.tar`.
-
-The same flow from a script (a Charm TUI by default; add `--cli` for text prompts):
-
-```bash
-proxsave --decrypt
-```
-
-### Expected Results
-
-**Encrypted backup**:
-```text
-pve01-backup-20240115-020000.tar.xz.age.bundle.tar # Encrypted bundle (archive + metadata + checksum)
-```
-
-**Security features**:
-- ✅ Streaming encryption (no plaintext on disk)
-- ✅ ChaCha20-Poly1305 AEAD
-- ✅ Passphrase-based or key-based
-- ✅ Compatible with standard AGE tools
-
----
-
-## Example 5: Backblaze B2 with Bandwidth Limiting
-
-**Scenario**: Remote archival, slow network, cost optimization.
-
-**Use case**:
-- Long-term archival (7-year retention)
-- Slow office network (don't saturate during work hours)
-- Cost-effective cloud storage
-- Nighttime backup window
-
-### Setup Steps
-
-#### Step 1: Configure Backblaze B2
-
-```bash
-# Create B2 account (10GB free)
-# Create bucket: pbs-backups (Private)
-# Create Application Key (copy Key ID and Application Key)
-
-rclone config
-# n > b2 > b2 > > > n > n > y > q
-```
-
-#### Step 2: Configure backup.env
-
-```bash
-# configs/backup.env
-
-# Cloud storage
-CLOUD_ENABLED=true
-CLOUD_REMOTE=b2
-CLOUD_REMOTE_PATH=/pbs-backups
-CLOUD_LOG_PATH=/pbs-backups/logs
-CLOUD_UPLOAD_MODE=sequential
-
-# Slow network tuning
-RCLONE_TIMEOUT_CONNECTION=45
-RCLONE_TIMEOUT_OPERATION=1800 # 30 minutes
-RCLONE_BANDWIDTH_LIMIT=5M # 5 MB/s (don't saturate office network)
-RCLONE_TRANSFERS=2
-RCLONE_RETRIES=5
-
-# Batch deletion (B2 rate limiting)
-CLOUD_BATCH_SIZE=20
-CLOUD_BATCH_PAUSE=2
-
-# GFS retention (long-term archival)
-RETENTION_POLICY=gfs
-RETENTION_DAILY=14
-RETENTION_WEEKLY=8
-RETENTION_MONTHLY=24
-RETENTION_YEARLY=5
-
-# Result: ~51 backups distributed over 5 years
-# Cost: 51 × 0.5GB = 25.5GB × $0.005 = $0.13/month
-```
-
-#### Step 3: Schedule Nightly Backup
-
-Set the schedule in the dashboard (`Maintenance` -> `Install` -> `Edit install`, the
-**Frequency** and **Run at (HH:MM)** fields) and let the resident daemon own the schedule
-(already the engine on a fresh install; `Daemon` -> `Install` switches a cron host). Both
-write to `configs/backup.env`: `SCHEDULER_FREQUENCY=daily`, `SCHEDULER_TIME=02:00` and
-`SCHEDULER_MODE=daemon`.
-
-Only on a host kept on cron does the crontab matter:
-
-```bash
-# Cron: 2 AM daily (SCHEDULER_MODE=cron only)
-crontab -e
-0 2 * * * /usr/local/bin/proxsave --backup
-```
-
-**Why nightly?**: Slow upload doesn't impact office hours, B2 free egress 1GB/day.
-
-### Expected Results
-
-**Cost calculation** (example):
-- Backup size: 500 MB
-- GFS retention: 51 backups
-- Total storage: 25.5 GB
-- B2 cost: $0.005/GB/month = **$0.13/month**
-
-**Upload time** (example):
-- Backup size: 500 MB
-- Bandwidth: 5 MB/s
-- Upload time: ~100 seconds (1.5 minutes)
-
----
-
-## Example 6: MinIO Self-Hosted with High Performance
-
-**Scenario**: LAN-based MinIO server, fast storage, hourly backups.
-
-**Use case**:
-- Self-hosted S3-compatible storage (MinIO)
-- Local network (gigabit LAN)
-- Hourly backup frequency
-- High-performance requirements
-
-### Setup Steps
-
-#### Step 1: Configure MinIO
-
-```bash
-# Assuming MinIO running at https://minio.local:9000
-# Create bucket via MinIO Console or mc client
-mc mb minio-local/pbs-backups
-mc mb minio-local/pbs-logs
-
-rclone config
-# n > minio > s3 > Minio > minioadmin > minioadmin > (empty region) > https://minio.local:9000 > y > q
-```
-
-#### Step 2: Configure backup.env
-
-```bash
-# configs/backup.env
-
-# Cloud storage (MinIO LAN)
-CLOUD_ENABLED=true
-CLOUD_REMOTE=minio
-CLOUD_REMOTE_PATH=/pbs-backups/server1 # Organize by server
-CLOUD_LOG_PATH=/pbs-logs
-CLOUD_UPLOAD_MODE=parallel
-CLOUD_PARALLEL_MAX_JOBS=4
-CLOUD_WRITE_HEALTHCHECK=true # Test write access
-
-# LAN performance tuning
-RCLONE_TIMEOUT_CONNECTION=10
-RCLONE_TIMEOUT_OPERATION=300
-RCLONE_BANDWIDTH_LIMIT= # Unlimited (LAN)
-RCLONE_TRANSFERS=8 # Highly parallel
-RCLONE_RETRIES=2
-
-# Batch deletion (no API limits)
-CLOUD_BATCH_SIZE=100
-CLOUD_BATCH_PAUSE=0
-
-# Simple retention (168 hours = 1 week)
-MAX_CLOUD_BACKUPS=168
-```
-
-#### Step 3: Hourly Backup
-
-This is the one scenario in this guide that cron does better. The resident daemon runs the
-backup daily, weekly or monthly, at `SCHEDULER_TIME`; it has no sub-daily schedule. An hourly cadence
-therefore means staying on cron: keep `SCHEDULER_MODE=cron` (or revert with
-`Daemon` -> `Disable`) and write the entry yourself.
-
-```bash
-# Cron: every hour
-crontab -e
-0 * * * * /usr/local/bin/proxsave --backup
-```
-
-Note what that costs: the healthchecks monitoring described in
-[Example 11](#example-11-resident-daemon-and-healthchecks-monitoring) only transmits under
-the daemon, so an hourly cron host has no dead-man switch and no hang watchdog.
-
-### Expected Results
-
-**Performance**:
-- Backup creation: 2-3 minutes
-- Upload to MinIO (LAN): 10-30 seconds
-- Total time: ~3-4 minutes
-
-**Retention**:
-- 168 hourly backups (1 week)
-- Automatic hourly rotation
-
-**Advantages**:
-- ✅ Full control over data
-- ✅ No cloud costs
-- ✅ LAN speed (gigabit)
-- ✅ S3-compatible API
-
----
-
-## Example 7: Multi-Notification Setup
-
-**Scenario**: Telegram + Email + Webhook (Discord + Pushover) notifications.
-
-**Use case**:
-- Multiple notification channels
-- Team awareness
-- Critical alerts via multiple paths
-- Redundant notification delivery
-
-### Configuration
-
-The dashboard covers the two channels most hosts use: `Maintenance` -> `Install` ->
-`Edit install` has a **Telegram notifications** toggle, an **Email notifications** toggle
-and an **Email delivery mode** selector (relay, sendmail, pmf). Enabling Telegram there
-also selects the centralized bot on a config that has no `BOT_TELEGRAM_TYPE` yet. Gotify
-and webhooks have no form fields; they are configured in `backup.env` only. Once Telegram
-is on, `Diagnostic Checks` -> `Telegram` verifies the pairing without running a backup.
-
-```bash
-# configs/backup.env
-
-# Telegram
-TELEGRAM_ENABLED=true
-BOT_TELEGRAM_TYPE=personal
-TELEGRAM_BOT_TOKEN=123456789:ABCdefGHIjklMNOpqrsTUVwxyz
-TELEGRAM_CHAT_ID=987654321
-
-# Email
-EMAIL_ENABLED=true
-EMAIL_DELIVERY_METHOD=relay
-EMAIL_RECIPIENT=admin@example.com
-EMAIL_FROM=noreply@proxmox.example.com
-
-# Webhook (Discord + Pushover)
-WEBHOOK_ENABLED=true
-WEBHOOK_ENDPOINTS=discord_alerts,pushover
-WEBHOOK_DISCORD_ALERTS_URL=https://discord.com/api/webhooks/XXXX/YYYY
-WEBHOOK_DISCORD_ALERTS_FORMAT=discord
-WEBHOOK_DISCORD_ALERTS_METHOD=POST
-
-# Pushover (push notifications to phone/desktop). Token + user key go in the
-# JSON body, so AUTH_TYPE stays "none". PRIORITY accepts -2..1 (default 0).
-WEBHOOK_PUSHOVER_URL=https://api.pushover.net/1/messages.json
-WEBHOOK_PUSHOVER_FORMAT=pushover
-WEBHOOK_PUSHOVER_METHOD=POST
-WEBHOOK_PUSHOVER_AUTH_TYPE=none
-WEBHOOK_PUSHOVER_AUTH_TOKEN=
-WEBHOOK_PUSHOVER_AUTH_USER=
-WEBHOOK_PUSHOVER_PRIORITY=0
-```
-
-Run the backup (`Backup` -> `Backup`, or `proxsave --backup`) and the report goes to
-Telegram, Email, Discord and Pushover.
-
-### Setup Steps
-
-#### 1. Telegram Bot Setup
-
-```bash
-# Create bot via @BotFather on Telegram
-# Send message: /newbot
-# Get token: 123456789:ABC...
-
-# Get chat ID:
-# Send message to bot
-# Visit: https://api.telegram.org/bot/getUpdates
-# Copy chat.id value
-```
-
-#### 2. Email Configuration
-
-```bash
-# Option A: Cloud relay (default, outbound HTTPS)
-# - Set EMAIL_DELIVERY_METHOD=relay and configure EMAIL_RECIPIENT (or leave empty for root@pam auto-detect)
-# - Relay blocks root@... recipients; use a real non-root mailbox for EMAIL_RECIPIENT
-# - No local SMTP/MTA setup required on the node
-# - Optional/default: set EMAIL_FALLBACK_SENDMAIL=true to fall back to local sendmail when the relay fails
-
-# Option B: Local sendmail (/usr/sbin/sendmail)
-# - Set EMAIL_DELIVERY_METHOD=sendmail
-# - Requires a working local MTA (e.g. postfix) on the node
-# - EMAIL_RECIPIENT is required (or auto-detected from Proxmox root@pam if configured)
-
-# Option C: Proxmox Notifications (manual)
-# - Set EMAIL_DELIVERY_METHOD=pmf
-# - Configure SMTP/Sendmail targets and matchers in Proxmox Notifications
-# - ProxSave does not need SMTP host/port/user/password
-# - EMAIL_RECIPIENT is optional (only used for the To: header)
-# - If PMF fails the relay is tried next regardless of EMAIL_FALLBACK_SENDMAIL, which only gates the final local-sendmail leg. Use EMAIL_DELIVERY_METHOD=sendmail to stay off the relay entirely
-# - Optional quick check (runs the forwarder directly; run as root):
-printf "To: root\nSubject: proxsave test\n\nHello from proxsave\n" | sudo /usr/libexec/proxmox-mail-forward
-```
-
-#### 3. Discord Webhook
-
-```bash
-# In Discord:
-# Server Settings > Integrations > Webhooks > New Webhook
-# Copy webhook URL
-```
-
-### Expected Results
-
-**On successful backup**:
-- ✅ Telegram message with summary
-- ✅ Email with detailed report
-- ✅ Discord embed with stats
-- ✅ Pushover push notification
-
-**On failure**:
-- ❌ Telegram alert with error
-- ❌ Email with failure details
-- ❌ Discord mention with logs
-- ❌ Pushover push notification
-
----
-
-## Example 8: Complete Production Setup
-
-**Scenario**: Enterprise setup with all features enabled.
-
-**Use case**:
-- Production environment
-- Maximum reliability
-- All collectors enabled
-- Multi-tier storage
-- Encryption
-- Notifications
-- Metrics export
-
-### Configuration
-
-```bash
-# configs/backup.env
-
-# General
-BACKUP_ENABLED=true
-USE_COLOR=true
-DEBUG_LEVEL=standard
-
-# Security
-SECURITY_CHECK_ENABLED=true
-AUTO_UPDATE_HASHES=true
-AUTO_FIX_PERMISSIONS=true
-CONTINUE_ON_SECURITY_ISSUES=false
+CLOUD_REMOTE=s3
+CLOUD_REMOTE_PATH=/company-backups/host1
+CLOUD_LOG_PATH=/company-backups/logs/host1
-# Compression (balanced)
COMPRESSION_TYPE=xz
COMPRESSION_LEVEL=6
COMPRESSION_MODE=standard
-COMPRESSION_THREADS=0
-
-# Primary storage
-BACKUP_PATH=/opt/proxsave/backup
-LOG_PATH=/opt/proxsave/log
-
-# Secondary storage (NAS)
-SECONDARY_ENABLED=true
-SECONDARY_PATH=/mnt/nas/pbs-backup
-SECONDARY_LOG_PATH=/mnt/nas/pbs-log
-# Cloud storage (S3)
-CLOUD_ENABLED=true
-CLOUD_REMOTE=s3
-CLOUD_REMOTE_PATH=/company-backups/datacenter1/pbs1
-CLOUD_LOG_PATH=/company-backups/logs
-CLOUD_UPLOAD_MODE=parallel
-CLOUD_PARALLEL_MAX_JOBS=4
-RCLONE_TRANSFERS=8
-RCLONE_RETRIES=3
-
-# GFS retention (7-year compliance)
RETENTION_POLICY=gfs
RETENTION_DAILY=7
RETENTION_WEEKLY=8
-RETENTION_MONTHLY=24
-RETENTION_YEARLY=7
+RETENTION_MONTHLY=12
+RETENTION_YEARLY=3
-# Encryption
ENCRYPT_ARCHIVE=true
BUNDLE_ASSOCIATED_FILES=true
AGE_RECIPIENT_FILE=/opt/proxsave/identity/age/recipient.txt
-
-# Notifications
-TELEGRAM_ENABLED=true
-TELEGRAM_BOT_TOKEN=...
-TELEGRAM_CHAT_ID=...
-EMAIL_ENABLED=true
-EMAIL_RECIPIENT=ops@example.com
-GOTIFY_ENABLED=true
-GOTIFY_SERVER_URL=https://gotify.example.com
-GOTIFY_TOKEN=...
-
-# Metrics
-METRICS_ENABLED=true
-METRICS_PATH=/var/lib/prometheus/node-exporter
-
-# Collectors (all enabled)
-BACKUP_CLUSTER_CONFIG=true
-BACKUP_PVE_FIREWALL=true
-BACKUP_DATASTORE_CONFIGS=true
-BACKUP_USER_CONFIGS=true
-BACKUP_NETWORK_CONFIGS=true
-BACKUP_APT_SOURCES=true
-BACKUP_CRON_JOBS=true
-BACKUP_SYSTEMD_SERVICES=true
-BACKUP_SSL_CERTS=true
-BACKUP_CRITICAL_FILES=true
-BACKUP_SSH_KEYS=true
-BACKUP_ZFS_CONFIG=true
-BACKUP_ROOT_HOME=true
-
-# Custom paths
-CUSTOM_BACKUP_PATHS="
-/root/.config/rclone/rclone.conf
-/opt/proxsave/configs/backup.env
-/etc/custom/app.conf
-"
```
-### Building it from the dashboard
-
-Six of the blocks above are on the configuration form
-(`Maintenance` -> `Install` -> `Edit install`): secondary storage, cloud storage, Telegram,
-email and its delivery mode, encryption, and the scheduler engine plus the daily run time.
-The rest (compression, retention, security, metrics, collectors, custom paths) is
-hand-edited in `configs/backup.env`.
-
-Then, still in the dashboard:
-
-1. `Maintenance` -> `New key` for the AGE recipient.
-2. `Daemon` -> `Status` to confirm the resident service owns the schedule, or
- `Daemon` -> `Install` if the host is still on cron.
-3. `Diagnostic Checks` -> `Telegram`, then `Healthchecks`, then `Post-install`, to confirm
- the install before you trust it.
-4. `Backup` -> `Backup` for the first run.
+The NAS path must be the intended mounted filesystem, not an empty directory left behind by a missing mount. The `s3` name is an already configured rclone remote. Follow [cloud setup](CLOUD_STORAGE.md) rather than treating the name as credentials
-### Scheduling
+The retention values describe a proposed policy, not a compliance guarantee. They cannot retain historical generations that have never been created. Review the [retention behavior](STORAGE.md#set-backup-retention), destination overrides and available capacity before reducing or replacing an existing policy
-The resident daemon runs the backup at the configured schedule (`SCHEDULER_FREQUENCY`,
-daily by default, at `SCHEDULER_TIME`), under a `MAX_RUN_DURATION` watchdog, and reports to an
-external monitor. That is the recommended engine for a
-production host. A cron entry applies only where the daemon was deliberately declined:
+If you use a personal Telegram bot, explicitly select `BOT_TELEGRAM_TYPE=personal` together with its token and chat ID. Use the [notification guide](NOTIFICATIONS.md) to configure and test each chosen channel. Keep secrets out of shared configuration examples
-```bash
-# Daily backup at 2 AM (SCHEDULER_MODE=cron only)
-crontab -e
-0 2 * * * /usr/local/bin/proxsave --backup >> /var/log/pbs-backup-cron.log 2>&1
-```
-
-### Expected Results
-
-**Storage distribution**:
-- ✅ Encrypted backup on local SSD
-- ✅ Copy to secondary NAS
-- ✅ Upload to S3 cloud
-- ✅ GFS retention (7-year compliance)
+For metrics, set `METRICS_ENABLED` and `METRICS_PATH` according to the [metrics reference](CONFIGURATION.md#metrics---prometheus). Writing metrics files does not configure a Prometheus scrape job or create a Grafana dashboard
-**Notifications**:
-- ✅ Telegram alert
-- ✅ Email report
-- ✅ Gotify push notification
+### Check the combined result
-**Metrics**:
-- ✅ Prometheus metrics exported
-- ✅ Grafana dashboard integration
+1. Open **Daemon > Status** and confirm which scheduler owns the installation
+2. Review **Diagnostic Checks > Post-install**, then the Telegram or Healthchecks checks for services you have configured
+3. Run **Backup** and examine the collection summary and the result of every enabled destination
+4. Confirm that copied archive sets can be accessed independently of this host, including any credentials needed to retrieve them
+5. Test decryption and a compatible recovery procedure on a disposable host before relying on this policy
-**Backup includes**:
-- PVE cluster config
-- PBS datastores
-- Network configs
-- SSL certificates
-- SSH keys
-- ZFS configuration
-- Custom application configs
-
----
+Native PBS can be added using [its dedicated procedure](STORAGE.md#create-native-pbs-backups). It stores a different format and has separate key and recovery requirements
## Example 9: Test in a Chroot/Fixture
-**Scenario**: Run collection against an alternate system root (chroot, mounted snapshot, test fixture) without touching the live filesystem.
-
-**Use case**:
-- CI/test backups in an isolated environment
-- Offline analysis of a mounted image/snapshot
-- Running inside a container that mounts a different root
+`SYSTEM_ROOT_PREFIX` redirects collection to another root. It does not sandbox ProxSave or redirect logs, runtime state, output paths or retention. Use a separate disposable test host or isolated test installation, not a production host with a different input path
-### Configuration
+Prepare the alternate filesystem using the host's storage tools, then create a dedicated configuration from the installation's current configuration. Set the prefix in that file; it is not an environment override
-```bash
-# configs/backup.env
-SYSTEM_ROOT_PREFIX=/mnt/snapshot-root # points to the alternate root
+```ini
+SYSTEM_ROOT_PREFIX=/mnt/snapshot-root
BACKUP_ENABLED=true
-# /etc, /var, /root, /home are resolved under the prefix
-```
-
-### Setup Steps
-
-This is a flags-only scenario. The run needs a second configuration file selected with
-`--config`, and any flag at all skips the dashboard, so there is no dashboard route for it.
-
-`SYSTEM_ROOT_PREFIX` is **not** one of the keys ProxSave reads from the environment, so it has to go in a config file. Setting it on the command line is silently ignored and the run collects the live root instead, which is the one mistake here that produces a plausible-looking archive of the wrong system.
-
-```bash
-# 1) Mount or prepare the alternate root
-mount /dev/vg0/snap /mnt/snapshot-root # example
-
-# 2) Put the prefix in a dedicated config file
-cp /opt/proxsave/configs/backup.env /opt/proxsave/configs/snapshot.env
-sed -i 's|^SYSTEM_ROOT_PREFIX=.*|SYSTEM_ROOT_PREFIX=/mnt/snapshot-root|' /opt/proxsave/configs/snapshot.env
-
-# 3) Run a dry-run against it
-proxsave -c /opt/proxsave/configs/snapshot.env --dry-run
-
-# 4) Run the actual backup (optional)
-proxsave -c /opt/proxsave/configs/snapshot.env --backup
-```
-
-Confirm the prefix took effect before running for real. On a Proxmox snapshot the run header names it (`Proxmox Type (prefix /mnt/snapshot-root): ...`); on a plain chroot or fixture that line is debug-only, so run the dry-run with `--log-level debug` and check the collected paths resolve under `/mnt/snapshot-root`. Collection lines at the default level name the category, not the path, so they cannot tell you which root was used.
-
-### Expected Results
-- Collected files reflect the contents of `/mnt/snapshot-root/etc`, `/var`, `/root`, `/home`, etc.
-- No writes to the node's live filesystem.
-
----
+BACKUP_PATH=/var/lib/proxsave-fixture/backup
+LOG_PATH=/var/lib/proxsave-fixture/log
+SECONDARY_ENABLED=false
+SECONDARY_PATH=
+SECONDARY_LOG_PATH=
+CLOUD_ENABLED=false
+PBS_TARGET_ENABLED=false
+TELEGRAM_ENABLED=false
+EMAIL_ENABLED=false
+GOTIFY_ENABLED=false
+WEBHOOK_ENABLED=false
+METRICS_ENABLED=false
+HEALTHCHECK_ENABLED=false
+AUTO_UPDATE_HASHES=false
+AUTO_FIX_PERMISSIONS=false
+SET_BACKUP_PERMISSIONS=false
+```
+
+Keep outputs outside the mounted input tree. Check aliases and supported environment overrides against the [configuration reference](CONFIGURATION.md), and remove custom scripts or other test settings that could affect live services
+
+Selecting this separate configuration is an advanced command-line task. Use the [alternate-configuration instructions](CLI_REFERENCE.md#separate-collection-profile-on-a-disposable-host) and inspect debug output to confirm that collection reads the intended root before executing a real backup. The dry run still writes diagnostic logs
+
+Expected results are files from the mounted input and archives/logs under the test output paths. Temporary files and runtime state still belong to the executing installation. Restoring from such an archive is a separate operation with its own target and safety requirements
## HA-LXC Backup Appliance (`HOST_BACKUP_MODE`)
-**Scenario**: Run ProxSave inside a privileged LXC that backs up the Proxmox host, with the host filesystem bind-mounted read-only into the container (issue #255).
-
-**Use case**:
-- A dedicated, restartable backup appliance for a Proxmox VE or PBS host
-- Keeping ProxSave and its dependencies out of the host root
+This scenario runs ProxSave in a privileged LXC with the host filesystem exposed beneath `/host`. Configure the container mounts in Proxmox first: the intended host root and the PVE configuration mount must be visible at the correct prefixed paths and mounted read-only. This is external container administration, not a ProxSave dashboard operation
-### Setup Steps
+Use these settings inside the container's ProxSave installation:
-```bash
-# 1) On the Proxmox host, bind-mount the host root and pmxcfs read-only into the CT
-pct set -mp0 /,mp=/host,ro=1
-pct set -mp1 /etc/pve,mp=/host/etc/pve,ro=1
-
-# 2) In the container's configs/backup.env
+```ini
SYSTEM_ROOT_PREFIX=/host
HOST_BACKUP_MODE=true
BACKUP_ENABLED=true
-
-# 3) Dry-run, then run
-proxsave --dry-run
-proxsave --backup
```
-Once the container is configured, running `proxsave` bare inside it opens the dashboard as
-usual, so the appliance is managed the same way as a host install.
+Then open `proxsave` in the container's interactive terminal and choose **Backup**. Review the detected role and collection results before relying on the appliance
-### Expected Results
-- Proxmox type is detected from the mounted host (`/host/etc/pve`, `/host/etc/proxmox-backup`), not the container.
-- Absolute symlinks such as `/etc/ceph/ceph.conf -> /etc/pve/ceph.conf` resolve under the prefix, so Ceph configuration is collected.
-- ZFS pool state is collected (shared kernel); namespace-scoped and cluster-daemon commands (udevadm, ethtool, the PVE CLI, crontab, systemctl, ceph) are skipped and their data comes from the host files, so the container needs no PVE packages.
-- Storages are scanned under `/host`; a network storage whose mount is not carried into the container is logged as not visible.
-- Symlink targets are stored verbatim, so the archive restores onto a real host unchanged.
-- No writes to the host filesystem.
+With a prefix and host-backup mode, detection uses the mounted host filesystem. Commands whose namespace or daemon context would describe the container instead of the host are skipped, and some information comes from files. Not all host mounts or runtime information are necessarily visible in the container
----
+Keep archive destinations, logs and runtime files in deliberate container-accessible locations. Read-only input mounts protect those input paths; the prefix itself is not a general isolation boundary. Do not run Restore in the container expecting it to restore the mounted host automatically
## Example 10: Dual PVE+PBS Host
-**Scenario**: A single node runs both Proxmox VE and Proxmox Backup Server.
-
-**Use case**:
-- Lab or edge node with co-installed PVE + PBS
-- Single backup run should include both product roles
-- Restore must remain compatible with `dual`, `pve`, or `pbs` targets
-
-### Configuration
-
-```bash
-# configs/backup.env
-BACKUP_ENABLED=true
-BACKUP_PATH=/opt/proxsave/backup
-LOG_PATH=/opt/proxsave/log
+ProxSave detects hosts where both products are installed and can collect their configurations together. The backup has one shared Linux payload and role-specific PVE/PBS content. Existing configuration directories alone are not a reliable substitute for installed-role detection
-# Common/system collection
-BACKUP_NETWORK_CONFIGS=true
-BACKUP_CRON_JOBS=true
-BACKUP_SYSTEMD_SERVICES=true
-BACKUP_ZFS_CONFIG=true
+Use **Maintenance > Install > Edit install** for the exposed settings and review the collector keys in the configuration reference. This example enables representative role-specific collectors:
-# PVE collection
+```ini
BACKUP_VM_CONFIGS=true
BACKUP_CLUSTER_CONFIG=true
BACKUP_PVE_JOBS=true
BACKUP_PVE_REPLICATION=true
BACKUP_PVE_FIREWALL=true
-
-# PBS collection
BACKUP_DATASTORE_CONFIGS=true
BACKUP_REMOTE_CONFIGS=true
BACKUP_SYNC_JOBS=true
BACKUP_VERIFICATION_JOBS=true
BACKUP_PBS_NOTIFICATIONS=true
BACKUP_PBS_NODE_CONFIG=true
-
-# Recommended for dual labs: opt in to the PBS datastore inventories (off by default;
-# metadata only, never datastore contents, and it walks every configured or discovered PBS datastore)
-PXAR_SCAN_ENABLE=true
+BACKUP_NETWORK_CONFIGS=true
+BACKUP_CRON_JOBS=true
+BACKUP_SYSTEMD_SERVICES=true
+BACKUP_ZFS_CONFIG=true
```
-### Expected Behavior
-
-- ProxSave auto-detects the host as `dual`
-- One archive is produced for the run
-- Metadata persists:
- - `BACKUP_TYPE=dual`
- - `BACKUP_TARGETS=pve,pbs`
-- The backup contains:
- - PVE categories
- - PBS categories
- - one shared `common/system` payload
-
-### Restore Notes
+Run **Backup** and inspect both role summaries. If one role fails collection, the other may still be saved with the incomplete target recorded. Both role collectors failing is an error. Do not treat the presence of one archive as proof that both roles completed
-- Restore on a `dual` host: full `PVE + PBS + Common`
-- Restore on a `pve` host: `PVE + Common`
-- Restore on a `pbs` host: `PBS + Common`
+Metadata identifies a combined backup as `dual` with PVE and PBS targets. During restore, available categories depend on payload and target capabilities: a PVE-only target cannot apply PBS-only settings just because both roles were in the source archive
-The restore workflow filters categories automatically when the current host does
-not support all backup targets.
-
----
+Optional datastore inventories remain metadata. Enabling `PXAR_SCAN_ENABLE` does not include PBS datastore contents in the configuration backup
## Example 11: Resident daemon and healthchecks monitoring
-**Scenario**: You want the backup scheduled and supervised by a resident service with a
-hang watchdog and an external dead-man switch, instead of a bare cron entry. This is the
-normal engine and fresh installs default to it; cron is the opt-out. Use this to switch an
-existing install or to inspect one.
-
-### Switch to the daemon
+Use this combination when you need scheduled execution and an alert if backups fail or stop arriving
-In the dashboard, the `Daemon` group shows only the command that fits the current state.
-On a host still on cron it offers `Install`; pick it and the switch runs in the screen,
-with the result reported there. `Status` is always offered and is read-only.
+1. Open **Daemon > Status** and inspect the configured scheduler and running binary
+2. If the host uses cron and you intend to switch, choose **Daemon > Install** and review the result. Follow the [daemon migration guidance](DAEMON.md) for existing wrapper scripts or other schedulers
+3. Configure the schedule through the installation form and the documented settings. Use **Daemon > Restart** when configuration or binary changes require it
+4. Configure monitoring using the [healthchecks guide](HEALTHCHECKS.md), then open **Diagnostic Checks > Healthchecks** to inspect it
+5. Run **Backup**, confirm the result reaches the monitor, and verify the intended alert delivery
-The same operations from a script or a headless host:
+A received backup message and a working missing-run monitor are different checks. Avoid leaving an independent cron wrapper or external timer running alongside the daemon schedule
-```bash
-# Install the systemd service, remove the proxsave cron entry, turn on centralized healthchecks
-proxsave --daemon-setup
-
-# Check status (exit 0 only when running, beating, and binary-aligned)
-proxsave --daemon-status
-```
-
-Both routes run the same code. `--daemon-setup` writes `SCHEDULER_MODE=daemon` and `HEALTHCHECK_ENABLED=true` and starts
-`proxsave-daemon.service`. The daemon runs the backup at the configured schedule (daily at `SCHEDULER_TIME` by default), under a
-`MAX_RUN_DURATION` watchdog, and reports three fixed checks (alive, backup, updates) plus one
-per notification channel to an external healthchecks monitor.
-
-It also deletes every cron line whose command is named `proxsave` or `proxmox-backup`, and
-tells you how many it removed, or that it found none. "None" on a host that was running on
-cron means something else was scheduling the backup, typically a wrapper script whose command
-has a different name: that entry survives and now runs alongside the daemon, and `--daemon-setup`
-warns about it by name. The unattended `--upgrade` migration refuses outright in that case.
-Read [DAEMON.md](DAEMON.md) before switching such a host.
+## Example 1: Basic Local Backup
-### Inspect and revert
+The complete procedure now lives in [Run and verify your first backup](BACKUP_GUIDE.md#run-and-verify-your-first-backup)
-From the dashboard, on a host where the daemon is the active scheduler, the `Daemon` group
-offers `Disable` (revert to cron), `Restart` (reload a rebuilt binary) and `Status`.
-`Status` is the screen to read first: it reports the scheduler mode, the service state, the
-running version and whether that version matches the binary on disk.
+## Example 2: Local + Secondary Storage
-The equivalents, plus the systemd views the dashboard does not wrap:
+Use [backup destinations](STORAGE.md#choose-and-verify-backup-destinations) for local and pre-mounted secondary storage, including the checks needed before relying on a NAS copy
-```bash
-systemctl status proxsave-daemon.service # is it running?
-journalctl -u proxsave-daemon.service -f # follow its log
-proxsave --daemon-remove # revert to a cron entry
-```
+## Example 3: Cloud Backup with Google Drive
-`--daemon-remove` always writes a cron line at the configured schedule and records `SCHEDULER_MODE=cron`,
-which is what stops upgrades reinstalling the daemon: the key is present, so it is honoured. If the
-host also schedules ProxSave through an entry ProxSave does not own, that entry is reported and left
-alone, so such a host ends with two backups at each scheduled time and the run that loses the per-run lock exits
-`16`. Withholding the line instead would leave a misidentified host with nothing scheduled at all,
-silently, which is the worse of the two. The daemon-only healthchecks are switched back off
-with the daemon, so a reverted host does not warn about a service that is no longer installed.
+Use [cloud storage](CLOUD_STORAGE.md) to configure an rclone remote for the executing account, select its path and verify a copied archive set
-### Run your own script around each backup
+## Example 4: Encrypted Backup with AGE
-The daemon can start a script of yours before the run and another after it, for example to
-stop a service that must not be running while its data is copied and to start it again
-afterwards:
+Use the [encryption guide](ENCRYPTION.md) to configure recipients, retain recovery material and test decryption
-```bash
-PERSONAL_SCRIPT_PRE_RUN=/usr/local/bin/proxsave-pre.sh
-PERSONAL_SCRIPT_POST_RUN=/usr/local/bin/proxsave-post.sh
-```
+## Example 5: Backblaze B2 with Bandwidth Limiting
-```bash
-#!/bin/sh
-# /usr/local/bin/proxsave-pre.sh, chmod 700, owned by root
-systemctl stop my-noisy-service
-```
+Provider setup and rclone tuning belong in [cloud storage](CLOUD_STORAGE.md). Review the provider's current limits separately; a concurrency setting does not imply multiple workers within one uploaded file
-```bash
-#!/bin/sh
-# /usr/local/bin/proxsave-post.sh, chmod 700, owned by root
-# Started after every outcome, so the service comes back even when the backup failed.
-systemctl start my-noisy-service
-```
+## Example 6: MinIO Self-Hosted with High Performance
-These are your scripts: ProxSave starts them and says nothing about them. Their output is
-discarded, their exit code is ignored, a failure never blocks or fails the backup, and each is
-killed after 10 minutes (except on the abandoned-child unwind, see [DAEMON.md](DAEMON.md)). They run only under the daemon, and only around the run it schedules.
-Write your own log line if you need a record. See [DAEMON.md](DAEMON.md) for the full contract.
+Use [cloud storage](CLOUD_STORAGE.md) for an S3-compatible remote and tune it against observed transfer behavior. A self-hosted endpoint is not automatically faster, and one copy operation is not replication to several independent destinations
-See [DAEMON.md](DAEMON.md) for the daemon itself and [HEALTHCHECKS.md](HEALTHCHECKS.md)
-for the monitoring modes (centralized vs self), the monitoring portal, and the full
-configuration keys.
+## Example 7: Multi-Notification Setup
----
+Use the [notification guide](NOTIFICATIONS.md) for channels and delivery checks, and [healthchecks](HEALTHCHECKS.md) for missing-run monitoring
## Quick Comparison Matrix
-| Example | Local | NAS | Cloud | Encryption | GFS | Complexity |
-|---------|-------|-----|-------|------------|-----|------------|
-| **1. Basic Local** | ✅ | ❌ | ❌ | ❌ | ❌ | ⭐ Simple |
-| **2. Local + NAS** | ✅ | ✅ | ❌ | ❌ | ❌ | ⭐⭐ Easy |
-| **3. Google Drive** | ✅ | ❌ | ✅ | ❌ | ✅ | ⭐⭐ Easy |
-| **4. Encrypted** | ✅ | ❌ | ✅ | ✅ | ❌ | ⭐⭐⭐ Moderate |
-| **5. Backblaze B2** | ✅ | ❌ | ✅ | ❌ | ✅ | ⭐⭐⭐ Moderate |
-| **6. MinIO** | ✅ | ❌ | ✅ | ❌ | ❌ | ⭐⭐⭐ Moderate |
-| **7. Multi-Notify** | ✅ | ❌ | ❌ | ❌ | ❌ | ⭐⭐ Easy |
-| **8. Production** | ✅ | ✅ | ✅ | ✅ | ✅ | ⭐⭐⭐⭐ Advanced |
-
----
+| Choice | Read first |
+| --- | --- |
+| Local/NAS/cloud/PBS | [Storage](STORAGE.md#choose-and-verify-backup-destinations) |
+| Simple or GFS retention | [Retention](STORAGE.md#set-backup-retention) |
+| Archive encryption and recovery keys | [Encryption](ENCRYPTION.md) |
+| Scheduler and monitoring | [Daemon](DAEMON.md) and [healthchecks](HEALTHCHECKS.md) |
+| Recovery planning | [Restore](RESTORE_GUIDE.md#quick-start) |
## Customization Tips
-### Mix and Match
-
-All examples can be combined. For instance:
-
-**Example: Local + NAS + Encrypted + Google Drive + GFS**:
-```bash
-# From Example 2: Local + NAS
-SECONDARY_ENABLED=true
-SECONDARY_PATH=/mnt/nas/pbs-backup
-
-# From Example 4: Encryption
-ENCRYPT_ARCHIVE=true
-AGE_RECIPIENT_FILE=${BASE_DIR}/identity/age/recipient.txt
-
-# From Example 3: Google Drive + GFS
-CLOUD_ENABLED=true
-CLOUD_REMOTE=gdrive
-CLOUD_REMOTE_PATH=/pbs-backups
-RETENTION_POLICY=gfs
-RETENTION_DAILY=7
-RETENTION_WEEKLY=4
-RETENTION_MONTHLY=12
-RETENTION_YEARLY=3
-```
-
-### Performance Tuning
-
-Adjust compression for your use case:
-
-**Fast (low CPU)**:
-```bash
-COMPRESSION_TYPE=zstd
-COMPRESSION_LEVEL=3
-COMPRESSION_MODE=fast
-```
-
-**Balanced** (default):
-```bash
-COMPRESSION_TYPE=xz
-COMPRESSION_LEVEL=6
-COMPRESSION_MODE=standard
-```
-
-**Maximum compression** (high CPU):
-```bash
-COMPRESSION_TYPE=xz
-COMPRESSION_LEVEL=9
-COMPRESSION_MODE=slow
-```
-
-### Cost Optimization
-
-**Minimize cloud costs**:
-```bash
-# Use GFS for efficient long-term retention
-RETENTION_POLICY=gfs
-RETENTION_DAILY=7
-RETENTION_WEEKLY=4
-RETENTION_MONTHLY=6
-RETENTION_YEARLY=2
-
-# Aggressive compression
-COMPRESSION_TYPE=xz
-COMPRESSION_LEVEL=9
-
-# Disable log uploads
-CLOUD_LOG_PATH=
-
-# Result: ~19 backups instead of 365 (5% storage cost)
-```
-
----
+Change one part of a working policy at a time, run a backup from the dashboard and inspect the result. Keep a known usable backup while testing. Performance and archive size depend on the files actually collected, compression, destination and host resources
## Related Documentation
-### Using ProxSave
-- **[Dashboard](DASHBOARD.md)** - The interactive menu, screen by screen
-- **[Daemon](DAEMON.md)** - The resident scheduler, its watchdog and its reporting
-- **[Healthchecks](HEALTHCHECKS.md)** - Monitoring modes, the portal, and the checks the daemon reports
-
-### Configuration
-- **[Configuration Guide](CONFIGURATION.md)** - Complete variable reference
-- **[Cloud Storage Guide](CLOUD_STORAGE.md)** - rclone setup for all examples
-- **[Encryption Guide](ENCRYPTION.md)** - AGE encryption details
-
-### Operations
-- **[CLI Reference](CLI_REFERENCE.md)** - All command-line flags
-- **[Troubleshooting](TROUBLESHOOTING.md)** - Common issues and solutions
-
-### Reference
-- **[Restore Guide](RESTORE_GUIDE.md)** - Restore from any example backup
-
-### Main Documentation
-- **[README](../README.md)** - Project overview and quick start
-
----
+Use the [documentation index](README.md) to find the canonical task guide or the [configuration reference](CONFIGURATION.md) for individual keys
## Next Steps
-1. **Choose an example** closest to your use case
-2. **Open the dashboard** with `proxsave` and set what the configuration form covers
-3. **Copy the rest** into `configs/backup.env`
-4. **Customize** paths, credentials, retention
-5. **Test** with `proxsave --dry-run`
-6. **Run** the first backup from `Backup` -> `Backup`
-7. **Verify** results in storage locations
-8. **Schedule** with the resident daemon (`Daemon` -> `Install` on a cron host), or keep cron if you opted out
-9. **Monitor** with `Diagnostic Checks` -> `Healthchecks`, plus logs and notifications
-
-**For detailed configuration options**, see: **[Configuration Guide](CONFIGURATION.md)**
+Verify a recovery on a disposable compatible system and keep the access credentials and recovery material available independently of the original host
diff --git a/docs/HEALTHCHECKS.md b/docs/HEALTHCHECKS.md
index ad2c39c2..5a28af3d 100644
--- a/docs/HEALTHCHECKS.md
+++ b/docs/HEALTHCHECKS.md
@@ -1,55 +1,129 @@
# Backup monitoring (healthchecks)
-ProxSave reports every backup outcome, plus a liveness heartbeat, to an external
-[healthchecks](https://healthchecks.io/) monitor. The monitor alarms on **silence**, so
-the failures ProxSave cannot report itself are still caught: a crash before the
-notification phase, an OOM kill, a run wedged on a dead mount, a host that never came
-back from a reboot.
-
-Monitoring is driven by the resident daemon, which is the only thing that pings and is
-also the default scheduler. A host still on the cron scheduler reports nothing, no matter
-how the keys below are set. See [DAEMON.md](DAEMON.md) for the scheduler engines, and for
-switching between them from the dashboard or with the `--daemon-*` flags.
-
-There is exactly one off switch, `HEALTHCHECK_ENABLED`. Set it to `false` and this host
-sends nothing anywhere; everything else on this page decides **where** the pings go, never
-whether they are sent. See [Turning monitoring off](#turning-monitoring-off).
-
-## Why silence is the signal
-
-A "notify me when a backup fails" setup is blind to the worst failures, because a
-process that panics, hangs, or never starts cannot send you anything. Every channel in
-[NOTIFICATIONS.md](NOTIFICATIONS.md) has that blind spot by construction.
-
-The daemon closes it by pushing to something outside this host. Each check has an
-expected cadence on the monitor side. Miss it and the check goes down and your alerts
-fire, whether ProxSave was able to say anything or not.
-
-This is also what makes [`NOTIFY_ON`](CONFIGURATION.md#which-runs-get-notified-notify_on)
-safe to use. Silencing the message for clean runs drops a *report you were already getting
-another way*; it drops no check, because the per-run message was never what caught a run
-that did not happen. The **Healthchecks** section is not a notification channel and
-`NOTIFY_ON` never filters it, so a run nobody was told about still pings. And a run applies
-`NOTIFY_ON` below `always` only when this monitor is confirmed to alert you: see
-[Alert delivery and NOTIFY_ON](#alert-delivery-and-notify_on).
-
-## What gets monitored
-
-The daemon reports four families of checks. In centralized mode the server creates them
-and they appear on the monitor as the `proxsave-*` checks below. In self mode you create
-them on your own instance, under any name you like, and give the daemon their ping URLs:
-see [Self mode](#self-mode-your-own-healthchecks).
-
-| Check | When it pings | What it covers |
-|-------|---------------|----------------|
-| `proxsave-alive` | immediately at daemon start, then every `HEALTHCHECK_HEARTBEAT_INTERVAL` | the daemon and the host are up. Stops when either dies, and the monitor alarms on the silence. It is also pinged `/fail` on purpose, with the reason in the body, while a backup child abandoned in uninterruptible sleep is outstanding -- see [DAEMON.md](DAEMON.md#caveat-uninterruptible-sleep-d-state) |
-| `proxsave-backup` | per run: `/start` at launch, then the run's exit code, or `/fail` on a hang | whether the backup ran and how it ended |
-| `proxsave-updates` | immediately at daemon start, then every `HEALTHCHECK_UPDATE_INTERVAL` | `/0` when up to date, `/1` when a newer release exists, so the check goes down and tells you to upgrade |
-| `proxsave-notify-` | after each daemon-supervised run, one per channel the backup attempted | whether that notification channel actually delivered |
-
-A run you start yourself, from the dashboard's **Backup** row or by hand, leaves the
-per-channel checks untouched. Only `proxsave-backup` picks up a standalone run, through
-the handoff described below.
+
+
+## Configure and verify backup monitoring
+
+Monitoring detects missing runs as well as reported failures. The resident daemon sends
+liveness, backup outcome, update and notification-delivery signals to an external
+Healthchecks service. The service alerts on silence, which can reveal a dead host,
+a crashed backup or a job that never started. Backup notifications alone cannot do that.
+
+### Enable a monitored daemon
+
+Run `proxsave` without arguments on an interactive terminal, then choose
+**Maintenance** > **Install** > **Edit install**. Select the daemon under
+`Scheduler engine`, then choose `Healthchecks`: centralized monitoring, your own server
+or Off. The field is inactive for cron because only the resident daemon transmits.
+
+During installation, ProxSave prepares the selected daemon before checking monitoring,
+installing its service if missing. The separate **Diagnostic Checks** > **Healthchecks**
+screen does not install or restart services.
+
+For an existing cron installation, **Daemon** > **Install** switches engines and
+enables monitoring. Review its cron warnings to avoid duplicate schedules; see
+[scheduling](DAEMON.md#schedule-and-supervise-backups). This action enables monitoring
+even if it was previously disabled. **Install** > **Edit install** preserves the
+wizard's monitoring choice. Later upgrades preserve an explicitly disabled value.
+
+The actual transmission switch is `HEALTHCHECK_ENABLED`. Setting it to `false` in the
+active `configs/backup.env` silences monitoring while allowing daemon scheduling.
+`HEALTHCHECK_MODE=off` alone does not silence anything: runtime treats every mode value
+except `self` as centralized. Disabling the daemon through **Daemon** > **Disable**
+also disables monitoring and restores cron.
+
+### Choose centralized monitoring
+
+Centralized mode provisions the host's checks using its Server ID and relay credential.
+You do not need to paste an API key. After setup choose **Diagnostic Checks** >
+**Healthchecks** and read the monitor's state and portal details.
+
+Before you have a portal password the screen provides a single-use login link, valid
+for about an hour. Open it and set a password. Configure alert channels in the portal,
+then trigger a test alert through the monitoring service and confirm it arrives.
+Opening the link without setting a password does not complete onboarding. If it expires,
+reopen the dashboard check for a fresh link. Once a password exists, the screen shows
+the portal address and email login identity instead of issuing another magic link.
+
+A local successful check only proves communication with the monitor. Until alert delivery
+is configured and confirmed, a check going down may not reach you. Missing Server ID
+or unresolved monitoring URLs means reporting is incomplete. Provisioning outages can
+prevent a newly started daemon from resolving its URLs; an already running daemon can
+continue using resolved URLs. See [centralized provisioning](#centralized-the-proxsave-monitoring-server)
+for retry and fallback behavior.
+
+### Use your own Healthchecks service
+
+Create checks and attach alert channels on your instance before configuring ProxSave.
+Use a full ping URL such as `https://hc-ping.com/` for each check. The setup form
+requires alive and backup URLs; updates and per-channel delivery checks are optional.
+
+| Check | Expected activity | Suggested period |
+| --- | --- | --- |
+| Service alive | At daemon startup, then every heartbeat | Heartbeat interval, default 5 minutes |
+| Backup outcome | Start and completion, or timeout failure | Backup frequency, with grace covering maximum run duration |
+| Updates | Periodic release check | Update interval, default 5 minutes |
+| Channel delivery | After supervised runs that attempted that channel | Backup frequency, subject to your notification filter |
+
+For weekly or monthly backups, set the external backup check period accordingly.
+Unlike centralized mode, ProxSave does not change your service's periods or alert rules.
+Give long backups enough grace, normally at least `MAX_RUN_DURATION`, so a run still
+working is not reported overdue prematurely.
+
+Advanced self-mode settings are hand edits. Set `HEALTHCHECK_ENABLED=true` and
+`HEALTHCHECK_MODE=self`, then supply full `HEALTHCHECK_*_URL` values or IDs with the
+shared ping endpoint. See the [complete key list](#configuration-keys) for endpoint,
+interval, optional log-tail and notification-check settings. Ping URLs are credentials;
+keep them private.
+
+An alive check is mandatory when self monitoring is enabled. Leaving both its URL and
+ID empty warns, disables reporting and makes an otherwise clean run exit with a warning.
+Blanking URLs does not switch monitoring off. Either configure a real alive check or
+set `HEALTHCHECK_ENABLED=false`.
+
+### Verify real coverage
+
+1. Choose **Diagnostic Checks** > **Healthchecks**. Review transmission, daemon and
+ alert-delivery status; resolve missing service, identity, URL or credential errors.
+2. Confirm the alive check receives recurring events on the external service.
+3. Confirm the next scheduled backup has a start and outcome event. Verify its actual
+ saved backup independently; a green monitoring check is not archive validation.
+4. Confirm your external alert channel receives a deliberate test alert. Keep
+ `NOTIFY_ON=always` until this route is working.
+5. If you use channel delivery checks, inspect them after a scheduled run. Their URLs
+ watch channel delivery; they are not Telegram, email, Gotify or webhook settings.
+
+`NOTIFY_ON` filters backup messages, not monitoring. Restricting messages below `always`
+is applied only when monitoring is confirmed to alert you. Missing alert confirmation
+can therefore leave every run notified despite a lower configured threshold.
+
+### Interpret silence and failure
+
+Only the daemon sends pings. A standalone dashboard backup can hand off its result to a
+live daemon, but does not update per-channel scheduled delivery checks. A stale handoff
+is discarded; without a live daemon no ping is sent. A skipped scheduled child can leave
+a start with no finish. Disabling backups leaves the backup check silent while the
+alive check continues.
+
+A timeout is reported as failure; nonzero exit outcomes are not green. Optional failed-run
+log tails may disclose sensitive context to the monitoring service, so choose
+`HEALTHCHECK_SEND_LOG` deliberately. Standalone handoffs carry only the exit result.
+
+For a missing portal link, first resolve the monitoring error and identity state, then
+reopen **Healthchecks**. For a missing daemon unit while configuration still says daemon,
+use **Maintenance** > **Install** > **Edit install** and continue with the daemon
+selected. Review the installation result, then reopen **Diagnostic Checks** >
+**Healthchecks**. The separate **Daemon** > **Install** action is available only when
+the recorded engine is cron; command-line repair is described in
+[CLI_REFERENCE.md](CLI_REFERENCE.md). Do not invent a green state by manually pinging
+a check whose real backup did not run.
+
+Read [check-screen troubleshooting](#what-the-check-screen-tells-you) for every displayed
+verdict and [ping details](#ping-details) for event protocol semantics.
+
+
+
+## Implementation appendix
### Ping details
@@ -90,6 +164,30 @@ The exact wire behavior, in case you are reading the monitor's event log:
registers them with the log masker and strips them out of transport errors, so a
failed ping logs the reason and never the URL.
+
+
+## Detailed reference
+
+The task above is the operator procedure. The following material preserves detailed behavior, limits and implementation context.
+
+## What gets monitored
+
+The daemon reports four families of checks. In centralized mode the server creates them
+and they appear on the monitor as the `proxsave-*` checks below. In self mode you create
+them on your own instance, under any name you like, and give the daemon their ping URLs:
+see [Self mode](#self-mode-your-own-healthchecks).
+
+| Check | When it pings | What it covers |
+|-------|---------------|----------------|
+| `proxsave-alive` | immediately at daemon start, then every `HEALTHCHECK_HEARTBEAT_INTERVAL` | the daemon and the host are up. Stops when either dies, and the monitor alarms on the silence. It is also pinged `/fail` on purpose, with the reason in the body, while a backup child abandoned in uninterruptible sleep is outstanding -- see [DAEMON.md](DAEMON.md#caveat-uninterruptible-sleep-d-state) |
+| `proxsave-backup` | per run: `/start` at launch, then the run's exit code, or `/fail` on a hang | whether the backup ran and how it ended |
+| `proxsave-updates` | immediately at daemon start, then every `HEALTHCHECK_UPDATE_INTERVAL` | `/0` when up to date, `/1` when a newer release exists, so the check goes down and tells you to upgrade |
+| `proxsave-notify-` | after each daemon-supervised run, one per channel the backup attempted | whether that notification channel actually delivered |
+
+A run you start yourself, from the dashboard's **Backup** row or by hand, leaves the
+per-channel checks untouched. Only `proxsave-backup` picks up a standalone run, through
+the handoff described below.
+
### When the daemon has no backup to report
With `BACKUP_ENABLED=false` the daemon skips the scheduled run entirely: no child
@@ -163,7 +261,7 @@ server-side change to them is picked up at the next restart.
The same request carries the backup schedule's frequency and `NOTIFY_ON`, and at startup the
daemon journal reports each answer in its own block: `Applying backup schedule...`, then
`Applying notify level...`, and, only when the request failed, `Applying healthchecks ping
-URLs...`, which ends in `WARNING ⚠ Healthchecks ping URLs: not available` when no URL is
+URLs...`, which ends in `WARNING Warning Healthchecks ping URLs: not available` when no URL is
available at all. The heartbeat that later gets an answer prints those blocks again, applied,
and the daemon keeps retrying quietly until then.
@@ -271,34 +369,7 @@ because there nothing would have transmitted even with the key filled in.
### Setting it up
-1. On your healthchecks instance, create one check for each row of the table below that
- you want. Each check has its own ping URL.
-2. Give each check the period of its row, and attach your alert channels to it on your
- instance: that is what tells you when a check goes down.
-3. Give the daemon each ping URL, in the install form or in `backup.env` (both below).
-4. Run `Diagnostic Checks` > `Healthchecks` from the dashboard. It pings your alive check
- to confirm this host reaches your instance.
-
-| Check | Needed | Variable | When the daemon pings it | Period on your instance |
-|-------|--------|----------|--------------------------|-------------------------|
-| service alive | always: the run warns without it | `HEALTHCHECK_ALIVE_URL` or `_ID` | at daemon start, then every `HEALTHCHECK_HEARTBEAT_INTERVAL` (5 minutes by default) | `HEALTHCHECK_HEARTBEAT_INTERVAL` |
-| backup outcome | required by the install form | `HEALTHCHECK_BACKUP_URL` or `_ID` | each scheduled run: `/start` at launch, then the exit code, or `/fail` on a hang | the time between scheduled runs: 1 day for daily, 7 days for weekly, 31 days for monthly, with a grace of at least `MAX_RUN_DURATION` (1 hour by default), so a long run is not reported down while it is still running |
-| updates | optional | `HEALTHCHECK_UPDATES_URL` or `_ID` | at daemon start, then every `HEALTHCHECK_UPDATE_INTERVAL` (5 minutes by default): `/0` when up to date, `/1` when a newer release exists | `HEALTHCHECK_UPDATE_INTERVAL` |
-| one per notification channel | optional | `HEALTHCHECK_NOTIFY__URL` or `_ID` | after each scheduled run in which that channel sent: see [Notification delivery checks](#notification-delivery-checks) | the time between scheduled runs, as for the backup check |
-
-The alive and backup pair alone is a perfectly reasonable setup.
-
-### During install
-
-Choosing `Your own server` on the monitoring step opens a form that collects the full
-ping URL of each check, for example `https://hc-ping.com/`. The alive and backup
-URLs are required; the updates URL and the four notification delivery check URLs are
-optional. Those four are the ping URLs of checks on your instance that watch each
-channel's delivery, not the channels' own addresses: see
-[Notification delivery checks](#notification-delivery-checks). Whatever you leave empty
-simply is not reported. A verification screen then pings your alive URL to confirm it is
-reachable from this host, using a state-neutral ping that does not leave a spurious
-success or failure on your check.
+The operator setup and verification sequence is in [Configure and verify backup monitoring](#configure-and-verify-backup-monitoring). Full URL and ID forms are documented below.
### In backup.env
@@ -361,41 +432,6 @@ or `failure` apply in self mode, leave all eight empty. See
In centralized mode these variables have no effect: the server creates the
`proxsave-notify-` checks itself.
-## Where monitoring shows up
-
-**Install wizard.** The configuration form's `Healthchecks` field asks for the monitoring
-mode, immediately after `Scheduler engine`, followed by `Notify level` (see
-[Alert delivery and NOTIFY_ON](#alert-delivery-and-notify_on)) and the schedule: `Frequency`,
-`Weekday`, `Day of month (1-28)` and `Run at (HH:MM)`. Its three answers
-are `Off`, `ProxSave HC Server` (centralized) and `Your own server` (self), and it is
-active only with the daemon engine selected: under cron it is inactive and monitoring is
-written off. A screen then verifies the connection. In centralized mode it also boxes
-the portal: a fresh login link, or the portal address plus your sign-in identity once you
-have a password. `--cli` installs ask the same question, again only on the daemon engine,
-and show the same information as plain text.
-
-**Dashboard.** This is the everyday route to both halves of monitoring. **Install** >
-**Edit install** re-runs the wizard above against the existing configuration, which is
-where the monitoring mode is changed; the **Daemon** group is where the engine that
-transmits it is installed or disabled ([DAEMON.md](DAEMON.md#operating)).
-
-`Healthchecks`, under **Diagnostic Checks**, runs on entry and reports the
-real operational state, not just one-shot reachability. In centralized mode it boxes
-the portal, in whichever of the two states applies. Under the verdict, a `Sensors:`
-list gives one colored line per monitored check with its state and the age of its last
-ping. That list is centralized only: the self-mode check is a plain reachability probe
-and reads no daemon state, so it has no rows to show.
-
-**End of a backup run.** The run prints a `Healthchecks` line reporting whether the
-daemon is actually transmitting. This section sends nothing itself: the daemon is the
-only pinger, and it records every ping outcome to disk, so the run reads that record
-and reports what was really sent. A missing record reads as "nothing transmitted yet",
-which is honest for a first run or a stopped daemon, and never as a false success.
-
-**`proxsave --daemon-status`.** A scriptable verdict on the daemon itself, covered in
-[DAEMON.md](DAEMON.md). The dashboard's **Daemon** > **Status** shows the same verdict
-without the exit code.
-
## Alert delivery and NOTIFY_ON
A monitor that alerts nobody is not a monitor. Before a run lets `NOTIFY_ON=warning` or
@@ -428,8 +464,8 @@ DOWN on every run the filter kept quiet. See
[Notification delivery checks](#notification-delivery-checks).
**Where you see it.** The run log's `Applying notification filter...` block (`Setting`,
-`Healthchecks status`, `Filter in effect`, then `✓ Notification filter: applied`, or
-`⚠ Notification filter: not applied` after the reason), the daemon journal's
+`Healthchecks status`, `Filter in effect`, then `Notification filter: applied`, or
+`Warning Notification filter: not applied` after the reason), the daemon journal's
`Applying notify level...` block, at start and before a run that sends a changed level, and
the `Notifications:` block of the Healthchecks check screen and of the install check:
@@ -456,7 +492,7 @@ fully healthy centralized state; in self mode it is `REACHABLE`.
| `PROVISIONING` | the credential or the server-side setup is not ready yet | check again shortly; if it persists, this host cannot reach the monitoring server |
| `UNREACHABLE` | the monitor did not answer from this host | check outbound connectivity and DNS |
| `UNCONFIRMED` | provisioned, but reachability could not be confirmed | run the check again |
-| `NOT INSTALLED` | the monitor is reachable but the daemon service is not installed | `proxsave --daemon-setup`. The dashboard's **Daemon > Install** row does the same thing, but it is offered only while `SCHEDULER_MODE` still reads `cron`: a host recorded as `daemon` whose unit went missing is shown Disable, Restart and Status instead, so use the flag there |
+| `NOT INSTALLED` | the monitor is reachable but the daemon service is not installed | For cron, use **Daemon** > **Install**. If already configured for daemon, use **Install** > **Edit install**. Review installation errors before checking again. |
| `NOT RUNNING` | the service is installed and stopped, or never wrote a heartbeat | `systemctl start proxsave-daemon.service` |
| `RUNNING, NOT REPORTING` | the process is up but has written no heartbeat yet | usually a stale build; restart the service |
| `STALE` | the last heartbeat is older than twice the heartbeat interval, and the interval is floored at one minute first, so the smallest stale window is two minutes | the daemon is stopped or wedged; check `journalctl -u proxsave-daemon.service`. On a systemd host you will normally see `RUNNING, NOT REPORTING` instead: an active unit with a stale heartbeat is reclassified, so `STALE` surfaces only when systemd could not be asked |
@@ -594,3 +630,13 @@ See [DAEMON.md](DAEMON.md) for the daemon itself, [CONFIGURATION.md](CONFIGURATI
for the full `backup.env` reference, and [NOTIFICATIONS.md](NOTIFICATIONS.md) for how
the per-channel checks relate to the delivery channels. In self mode, the per-channel
checks are the [notification delivery checks](#notification-delivery-checks).
+
+## Earlier guide entry points
+
+## Where monitoring shows up
+
+See the complete [operator procedure](#configure-and-verify-backup-monitoring). Detailed settings and implementation material remain in the reference sections above.
+
+## Why silence is the signal
+
+See the complete [operator procedure](#configure-and-verify-backup-monitoring). Detailed settings and implementation material remain in the reference sections above.
diff --git a/docs/INSTALL.md b/docs/INSTALL.md
index 2c52917b..532a9c5b 100644
--- a/docs/INSTALL.md
+++ b/docs/INSTALL.md
@@ -1,326 +1,146 @@
# ProxSave Installation Guide
-## Table of Contents
-
-- [Fast Install](#fast-install)
- - [Direct Install](#direct-install)
- - [Open the dashboard](#open-the-dashboard)
- - [First Backup Workflow](#first-backup-workflow)
-- [Upgrading ProxSave Binary](#upgrading-proxsave-binary)
- - [Upgrade from the dashboard](#upgrade-from-the-dashboard)
- - [The two upgrade paths](#the-two-upgrade-paths)
- - [Quick Upgrade](#quick-upgrade)
- - [What Gets Updated](#what-gets-updated)
- - [Full Upgrade Workflow](#full-upgrade-workflow)
- - [Requirements](#requirements)
- - [Troubleshooting](#troubleshooting)
-- [Manual Installation](#manual-installation)
- - [Prerequisites](#prerequisites)
- - [Building from Source](#building-from-source)
- - [Interactive Installation Wizard](#interactive-installation-wizard)
- - [Scheduling and the daemon](#scheduling-and-the-daemon)
+Install ProxSave, build it from source, maintain an existing installation, or replace a historical installation. After setup, use the [dashboard](DASHBOARD.md#when-the-dashboard-opens) for normal operations.
-## Fast Install
-
-ProxSave is driven from its interactive dashboard: run `proxsave` with no arguments on a terminal and
-you get a menu with `Backup`, `Restore`, `Decrypt`, `New key`, `Install`, `Upgrade`, the diagnostic
-checks, the daemon commands and `Support`. Installing the binary is the one step that has to happen on
-the command line, because there is no binary yet to open a menu with. Everything after it, this guide
-included, starts from the dashboard. See [DASHBOARD.md](DASHBOARD.md).
+
-The CLI flags described here stay fully supported and are the right tool for a headless host, a script,
-a cron job, or a recovery where the TUI cannot render. They are not the everyday route.
+## Fast Install
### Direct Install
-1. Download & start Install
-
- ```bash
- bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)"
- ```
-
- or, if you need a fully clean reinstall. This keeps `build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/` and **deletes everything else under the base directory**, which with stock paths means your local backup archives in `backup/`, the logs in `log/`, and `configs/backup.env`. Both installers ask for confirmation first, defaulting to no. Do not run it as a way to reset the configuration unless your backups also live on secondary or cloud storage:
+Run the installer as root on a Linux amd64 Proxmox host. The release installer requires outbound access to GitHub and OpenSSL for signature verification. Other architectures require a [source build](#manual-installation).
- ```bash
- bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" _ --new-install
- ```
-
- Append `--cli` to run the text-mode installer instead of the TUI (for example `... install.sh)" _ --cli`).
-
- The installer walks you through the configuration, then finishes by installing the scheduler
- (the resident daemon by default) and the `/usr/local/bin/proxsave` entrypoint.
-
-2. Open the dashboard
+```bash
+bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)"
+```
- ```bash
- proxsave
- ```
+The script downloads the latest stable release into `/opt/proxsave`. Before installing it, it verifies the pinned ECDSA P-256 signature on `SHA256SUMS`, then checks the archive checksum. Missing or invalid signatures stop installation; there is no checksum-only fallback. See [release verification](PROVENANCE_VERIFICATION.md#release-signature-sha256sumssig) for independent checks.
- From here on this is how you use ProxSave: run it with no arguments on a terminal and the
- interactive dashboard opens, with `Backup` as the first entry.
+The installer opens the configuration wizard, installs `/usr/local/bin/proxsave`, and finalizes the selected scheduler. Fresh installations default to the resident daemon. Cloud copies require a separately configured rclone remote; see [cloud storage](CLOUD_STORAGE.md).
- `proxsave` runs the backup directly only when there is no terminal attached, which is what cron and
- the daemon do. Any flag, even `--config`, also skips the dashboard.
+For a terminal that cannot render the TUI, use the text prompts:
-> **Release integrity & authenticity.** `install.sh` and `proxsave --upgrade`
-> verify every release before installing it: `SHA256SUMS` is checked against the
-> project's pinned **ECDSA P-256** signature (`SHA256SUMS.sig`), then the archive
-> is checked against `SHA256SUMS`. A missing or invalid signature aborts the
-> install/upgrade, with no fallback to checksum-only. `install.sh` requires
-> `openssl` for this (preinstalled on Proxmox); the Go upgrade verifies it
-> natively. To verify a download yourself, see
-> [PROVENANCE_VERIFICATION.md](PROVENANCE_VERIFICATION.md#release-signature-sha256sumssig).
+```bash
+bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" _ --cli
+```
### Open the dashboard
-`proxsave` with no arguments, on a terminal, is the normal way to reach everything this guide covers.
-The dashboard is a launcher, not a second implementation: each entry that has a matching flag runs exactly
-that flag's code, so nothing behaves differently from the command line. The `Diagnostic Checks` entries and
-`Daemon` > `Restart` have no flag and exist only in the dashboard.
-
-| What you want to do | Dashboard route | Equivalent flag |
-|---------------------|-----------------|-----------------|
-| Run a backup now | `Backup` | `--backup` |
-| Re-run the installer against your current configuration | `Install` > `Edit install` | `--install` |
-| Wipe the install directory and start the wizard again | `Install` > `Wipe install` | `--new-install` |
-| Check for a newer release and install it | `Upgrade` > `Check upgrade` | `--upgrade` |
-| Add new template variables to `backup.env` | `Upgrade` > `Check config` | `--upgrade-config` |
-| Install, disable or inspect the daemon | the `Daemon` group | `--daemon-setup`, `--daemon-remove`, `--daemon-status` |
-| Restore a backup onto this system | `Restore` | `--restore` |
-| Send a support report to the maintainer | `Support` | `--support` |
-
-The dashboard opens only when standard input and standard output are both real terminals and `TERM` is
-set and is not `dumb`. Anywhere else (cron, a pipe, `ssh` without a TTY, a serial console) `proxsave`
-runs the backup, and the flags in this guide are how you drive it. Full screen-by-screen detail is in
-[DASHBOARD.md](DASHBOARD.md).
-
-### First Backup Workflow
-
-From the dashboard, pick `Backup`: the run streams into the screen, in color, and ends with an outcome
-banner. That is the recommended first run.
-
-The command-line equivalents, for a headless host or a script:
+After installation, run:
```bash
-# Dry-run test (no actual changes)
-proxsave --dry-run
-
-# Real backup, without the dashboard
-proxsave --backup
-
-# View logs. The filename carries the FQDN, not the short hostname, and LOG_PATH
-# defaults to /opt/proxsave/log, so glob the directory rather than guessing the name.
-ls -t /opt/proxsave/log/backup-*.log | head -1 | xargs tail -f
-
-# Check backup files
-ls -lh /opt/proxsave/backup/
+proxsave
```
----
+Use an interactive terminal with both stdin and stdout attached and a nonempty `TERM` other than `dumb`. Bare invocation without these conditions runs a backup directly. Adding any argument also bypasses the dashboard. See [invocation rules](DASHBOARD.md#when-the-dashboard-opens).
-## Upgrading ProxSave Binary
+To change the wizard settings later, choose **Install > Edit install**, then **Edit existing**. The form covers destinations, notifications, encryption and scheduling. Advanced settings require editing `backup.env`; the [configuration entry guide](CONFIGURATION.md#editing-the-configuration-from-the-dashboard) identifies the exact fields.
-ProxSave updates itself from the latest GitHub release. The dashboard is the route; the flags below are
-the same upgrade for a headless host, a script, or a host whose TUI cannot render.
+### First Backup Workflow
-### Upgrade from the dashboard
+Choose **Backup** in the dashboard. Review the outcome, saved log path and destination results before relying on the installation. Follow the [first backup guide](BACKUP_GUIDE.md#run-and-verify-your-first-backup) for scope, archive verification and a recovery test. An installation or diagnostic check alone does not prove that a restorable backup exists.
-Run `proxsave`, pick `Upgrade`, and choose:
+### Reinstall safely
-- `Check upgrade` looks for a newer release the moment you open it. If you are current it reads green
- `NO UPGRADE ()`. If a newer release exists it shows the version, the release URL and the
- notes, plus a `Run upgrade` button. The upgrade log streams into the screen; press Enter when it
- finishes. On success the resident daemon, if present, is restarted once and verified.
-- `Check config` compares your `backup.env` against the shipped template, lists the variables it would
- add, and only offers `Apply` when there is something to add. This is `--upgrade-config` in graphical
- form.
+**Install > Edit install** keeps the existing installation and lets you edit, overwrite or retain the configuration. **Install > Wipe install** is destructive: it preserves only `build`, `daemon_state`, `env`, `guards`, `identity` and `restore` under the installation directory. With stock paths it deletes local archives in `backup`, run logs in `log`, and `configs/backup.env`.
-### The two upgrade paths
+Copy required archives, logs and configuration to an independent destination before choosing Wipe install. The wipe requires confirmation and defaults to No. Verify the retained copies before proceeding. Wiping is not a configuration reset or a migration tool. For automation flags, use the [CLI installation reference](CLI_REFERENCE.md#installation--setup).
-There are two ways to install a new release, and they differ in which binary executes the upgrade.
+
-**Built-in, `proxsave --upgrade` (what the dashboard runs).** The binary you have installed today is the
-one that fetches the release list, downloads the archive, verifies the `SHA256SUMS.sig` signature and the
-checksum, and replaces itself. Those steps cannot move: a freshly downloaded binary is untrusted until
-the installed one has verified it, so it can never be the party that verifies itself. The consequence is
-that a change to the download-and-verify half of the upgrade only takes effect on the upgrade *after* the
-one that ships it.
+
-Since 0.36.0 the rest of the upgrade (merging new template variables into `backup.env`, refreshing docs
-and symlinks, reconciling the scheduler, normalizing permissions, printing the footer) is handed to the
-binary that was just installed, so that half is already the new release's code. The decision to hand it
-over lives in the old binary too, so a host coming from a release older than 0.36.0 still finalizes with
-the old code.
+## Upgrading ProxSave Binary
-**External, `install.sh --upgrade`.** The script downloads the latest release, verifies its signature and
-checksum itself, swaps the new binary into `/opt/proxsave/build/proxsave`, and only then runs it with
-`--upgrade --localfile`, which skips the release check and download the script has already done. The
-whole upgrade after the download is therefore executed by the new release's code.
+### Requirements
-```bash
-bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" -- --upgrade
-```
+An upgrade needs an existing readable configuration, access to GitHub releases, enough disk space, and permissions to replace the binary, normalize ownership and manage the scheduler. Run maintenance as root. Published releases are Linux amd64; upgrading a source build does not rebuild it for another architecture.
-Two things this route does unconditionally: it installs into `/opt/proxsave` (the path is fixed in the
-script), and it installs the latest **stable** release, so it pulls a host running a beta back onto the
-stable line.
+Keep an independent copy of your configuration and required backup archives before maintenance. Binary replacement and configuration merging are separate operations, and neither converts historical backup formats.
-**Which to use.** Prefer the built-in upgrade, from the dashboard or with `proxsave --upgrade`; it is the
-everyday path and it keeps working on a host with a non-standard install directory. Reach for the external
-one-liner when the built-in one cannot help itself: the release notes say the upgrade or migration logic
-changed, you are coming from a release older than 0.36.0, or a built-in upgrade failed part-way and you
-want the new code to do the finalize.
+For an installation from the historical Bash version, follow [legacy migration](#legacy-migration) before choosing an upgrade route. Updating the current configuration template does not translate old Bash settings automatically.
-### Quick Upgrade
+A wipe reinstall is a separate operation that deletes files under the installation directory, including default backup and log paths. Keep independent recovery copies and review the [installation choices](#fast-install) before using it.
-```bash
-# Upgrade to latest version
-proxsave --upgrade
+### Upgrade from the dashboard
-# Non-interactive upgrade (auto-confirm)
-proxsave --upgrade y
+1. Run `proxsave` on an interactive terminal and choose **Upgrade > Check upgrade**.
+2. The check runs automatically. `NO UPGRADE ()` means you are current. If a release is available, read the version, release URL and notes before choosing **Run upgrade**. `CHECK FAILED` means the release check failed, not that no upgrade exists.
+3. Read the streamed outcome. A successful dashboard upgrade restarts an active daemon once, verifies it, and relaunches the dashboard using the newly installed binary. If restart is deferred because a backup is active or configuration cannot be read, the existing daemon keeps its old binary. Check **Daemon > Status** before considering maintenance complete.
+4. Choose **Upgrade > Check config** to review the installed template against `backup.env`. Apply the merge when offered. This is useful separately from a binary upgrade, which also merges configuration during finalization.
+5. Use **Post-install > Check** to inspect diagnostics, then follow the [first backup verification](BACKUP_GUIDE.md#run-and-verify-your-first-backup) with **Backup**.
-# Optionally update configuration template
-proxsave --upgrade-config
+### What Gets Updated
-# Verify everything works
-proxsave --dry-run
-```
+The upgrade verifies the release signature and archive checksum, atomically replaces the executable, refreshes the entrypoint and support documents, normalizes permissions, merges the embedded configuration template and reconciles the scheduler.
-At the end of a successful interactive upgrade, the freshly installed binary opens the what's-new screen
-for the release you just got. `proxsave --upgrade y` suppresses it, on the reading that auto-confirm means
-nobody is watching to close it.
+Supported and custom configuration values are preserved. Missing keys are added, while retired keys are pruned with a warning: `BASE_DIR`, `CRON_SCHEDULE`, `CRON_HOUR`, `CRON_MINUTE`, `ENABLE_SMART_CHUNKING`, `CHUNK_SIZE_MB`, `CHUNK_THRESHOLD_MB`, `BACKUP_USER_HOMES` and `DAEMON_OPT_OUT`. Matching is by the complete key, case-insensitively. A copy is saved as `backup.env.backup.` before writing; failed merged-config validation restores that copy.
-### What Gets Updated
+Keep `backup.env` a regular file. Atomic replacement replaces a configuration symlink itself and leaves its target unchanged. For central configuration management, deploy a regular file rather than a symlink.
-The `--upgrade` command:
+The scheduler already recorded by `SCHEDULER_MODE` is retained. A daemon is installed automatically only when the upgrade had to introduce that key. To change the engine or time, use **Install > Edit install** and review the [scheduler guide](DAEMON.md).
-- Downloads the latest binary from GitHub releases and verifies its signature and checksum before installing.
-- Atomically replaces the current binary and updates the `/usr/local/bin/proxsave` symlink (removing the legacy `proxmox-backup` symlink if present).
-- Fixes file permissions.
-- Merges any new template variables into your `backup.env` (your existing and custom values are preserved, deprecated variables are dropped with a warning naming them, and the previous file is copied to `backup.env.backup.` first).
-- Reconciles the scheduler: the resident daemon is installed only on a host that has never recorded a scheduler engine; a host whose `backup.env` already carries `SCHEDULER_MODE` keeps the engine it records. Re-run `--install`, or `Install` > `Edit install` in the dashboard, to change the run time or engine.
-- Restarts the resident daemon, when one is active, and verifies it came back on the new binary. It waits out an in-progress backup rather than killing it; if the wait times out, or the configuration cannot be read, the restart is deferred and reported, and the daemon keeps running the old binary until you restart it.
+### The two upgrade paths
-### Full Upgrade Workflow
+The built-in dashboard upgrade performs release discovery, download, verification and binary replacement using the currently installed binary. Fixes to those steps cannot help the same upgrade that first installs them. Since 0.36.0, that binary delegates finalization to the freshly installed binary; older upgrading binaries finalize with their own code.
-Each step here has a dashboard equivalent: `Upgrade` > `Check upgrade`, `Upgrade` > `Check config`,
-`Daemon` > `Status`, and `Backup`. The commands are the headless form.
+The external installer verifies and replaces the binary itself, then invokes the new binary to finalize:
```bash
-# 1. Upgrade binary
-proxsave --upgrade
-
-# 2. (Optional) Update configuration with new template variables
-proxsave --upgrade-config
+bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)" -- --upgrade
+```
-# 3. Test configuration
-proxsave --dry-run
+Use this fallback when the built-in upgrade cannot complete or release notes require newer installation logic. The script always targets `/opt/proxsave` and the latest stable release; it can replace a beta with stable and is unsuitable for maintaining a different installation directory without first reviewing that boundary.
-# 4. Check the scheduler
-proxsave --daemon-status # daemon installs; use crontab -l on cron installs
+### Quick Upgrade
-# 5. Run a real backup to confirm
-proxsave --backup
-```
+For unattended invocation and auto-confirmation semantics, use the [binary upgrade flags](CLI_REFERENCE.md#binary-upgrade). The dashboard is the normal interactive route.
-### Requirements
+### Full Upgrade Workflow
-- **Internet connection**: Must reach GitHub releases
-- **Platform**: Linux (amd64)
-- **An existing configuration**: `--upgrade` refuses to run when the configuration file is missing or
- unreadable, and tells you to run `proxsave --install` first
-- **Permissions**: `install.sh` refuses to run as anything but root. `proxsave --upgrade` does not check
- the user, but replacing the binary, writing the systemd unit and normalizing ownership all need root
+The complete operator sequence is Check upgrade, review and Run upgrade, Check config, Daemon Status, Post-install Check, and a verified Backup. Keep configuration merge and daemon alignment visible in the outcome rather than treating binary replacement as completion.
### Troubleshooting
-If upgrade fails:
-
-1. Check internet connectivity: `curl -I https://github.com`
-2. Verify GitHub is reachable: `curl -I https://api.github.com`
-3. Check disk space: `df -h /opt/proxsave`
-4. Review logs for specific errors
+If the check or download fails, inspect the reported URL, connectivity, disk space and saved log. If the binary is updated but daemon status reports a version mismatch, use **Daemon > Restart** after the running backup has finished. If configuration is missing or unreadable, repair it through **Install > Edit install** before retrying. Use the [failure guide](TROUBLESHOOTING.md) for debug-log preparation.
-For more details, see [CLI Reference - Binary Upgrade](CLI_REFERENCE.md#binary-upgrade).
+
----
+
## Manual Installation
-> Allows you to compile your binary file from individual project files.
-
-This is the path for an architecture other than linux/amd64, for which no release is published,
-and for development work on the code itself. On a normal host use [Direct Install](#direct-install)
-instead. Note that `--upgrade` never rebuilds from source: it downloads the published linux/amd64
-release and installs it over whatever you built.
-
-The recipe below still needs outbound access to GitHub and to go.dev: it clones the repository and
-runs `go mod tidy`. It is not an offline install, and it is not a substitute for one. On a
-different architecture, fetch the Go toolchain for that architecture rather than the
-`linux-amd64` tarball named below; everything after that step is architecture-independent.
+Build from source for development or an architecture without a published release. This requires network access for the repository, Go toolchain and dependencies; it is not an offline installation.
### Prerequisites
-```bash
-# Install Go (if building from source)
-wget https://go.dev/dl/go1.26.8.linux-amd64.tar.gz
-tar -C /usr/local -xzf go1.26.8.linux-amd64.tar.gz
-export PATH=$PATH:/usr/local/go/bin
-
-# Install rclone (for cloud storage)
-curl https://rclone.org/install.sh | bash
-
-# Install git
-apt update && apt install -y git
-
-# Install make
-apt update && apt install -y make
-
-# Verify installations
-go version # Should show go1.26.8+
-rclone version # Should show rclone v1.60+
-git --version # Should show git 2.47.3+
-make --version # Should show make 4.4.1+
-```
+Install Git, make, and a Go toolchain satisfying `go.mod` (currently Go 1.26.9). Choose the Go download for your host architecture and verify it according to the Go project's instructions. Install rclone only if you plan to use cloud storage. Do not extract a new Go toolchain over an existing `/usr/local/go` tree.
### Building from Source
+Use an empty installation directory. Do not clone over an existing ProxSave installation or its archives.
+
```bash
-# Create folder
mkdir /opt/proxsave
-
-# Navigate to project directory
cd /opt/proxsave
-
-# Copy from github
git clone --branch main https://github.com/tis24dev/proxsave.git .
-
-# Download dependencies
-go mod tidy
-
-# Build binary
+go mod download
make build
-
-# Verify build
./build/proxsave --version
```
+`make build` sets version metadata through `internal/version.Version`, `Commit` and `Date`. A local build without the compiled support recipient cannot send maintainer support email. Build output is `build/proxsave`.
+
### Interactive Installation Wizard
-The installation wizard creates your configuration file interactively. This is the same wizard the
-dashboard opens under `Install` (`Edit install` runs `--install`, `Wipe install` runs `--new-install`),
-so on an already installed host you do not need these commands; they are here for the first run on a
-freshly built binary, and for hosts where the dashboard cannot be reached.
+For this first invocation, run the newly built binary as root:
```bash
./build/proxsave --install
-
-# Or perform a clean reinstall. Keeps build/, daemon_state/, env/, guards/, identity/ and restore/; deletes everything
-# else under the base directory, local backup archives and configs/backup.env included.
-./build/proxsave --new-install
```
+Use `./build/proxsave --install --cli` if the TUI cannot render. After finalization, use bare `proxsave` to open the dashboard. Review the saved configuration and scheduler outcome before running your [first backup](BACKUP_GUIDE.md#run-and-verify-your-first-backup).
+
If the configuration file already exists, **both TUI and CLI** ask whether to:
- **Overwrite** (start from the embedded template)
- **Edit existing** (use the current file as base and pre-fill the wizard fields)
@@ -335,7 +155,7 @@ In **Keep existing & continue** mode, config-dependent post-steps are skipped:
Final install steps still run:
- Support docs installation
-- Symlink and scheduler finalization (installs the daemon service or the cron entry for the chosen engine)
+- Symlink and scheduler finalization (completes setup for the chosen engine)
- Permission normalization
**Wizard prompts:**
@@ -353,92 +173,44 @@ Final install steps still run:
11. **Weekday** (weekly only): the day of the weekly backup, default Monday (`SCHEDULER_WEEKDAY`).
12. **Day of month (1-28)** (monthly only): the day of the monthly backup, default 1 (`SCHEDULER_MONTHDAY`). Days 29-31 are not accepted, so no month is skipped.
13. **Run at (HH:MM)**: the backup time (default `02:00`, `SCHEDULER_TIME`). Frequency, day and time are used by whichever engine you chose: the daemon's schedule, or the cron entry the install writes. When `backup.env` records no schedule yet, the install takes it from an existing proxsave cron line; see [DAEMON.md](DAEMON.md#the-schedule-is-inherited-not-reset).
-14. **Post-install check (optional)**: Runs `proxsave --dry-run` and shows actionable warnings like `set BACKUP_*=false to disable`, allowing you to disable unused collectors and reduce WARNING noise
+14. **Post-install check (optional)**: Runs a diagnostic simulation, writes logs without creating or uploading archives, and shows actionable warnings like `set BACKUP_*=false to disable`, allowing you to disable unused collectors and reduce WARNING noise
15. **Telegram pairing (optional)**: If Telegram centralized mode is enabled and the installer can load a valid config plus a Server ID, it shows your Server ID and lets you verify pairing with the bot (retry/skip supported). Otherwise installation continues and logs why pairing was skipped.
-#### Backup monitoring wizard (TUI)
-
-When the daemon engine is selected with monitoring on, the installer opens a **Backup monitoring (healthchecks)** screen after the config has been written. Self mode gets a parameters screen first, where you paste the full ping URL of each check (alive and backup required; updates and the four notification delivery check URLs optional, which are checks on your own server that watch each channel, not the channels' own addresses: see [HEALTHCHECKS.md](HEALTHCHECKS.md#notification-delivery-checks)); those go into `backup.env`. The verification screen itself writes nothing.
-**What you see:**
-- A short explanation of what gets reported
-- **Centralized only**: your monitoring portal, boxed. Which form it takes depends on whether you already have a portal password. Without one you get a **single-use link, valid about an hour**, with the instruction to open it and **set a password and configure alert channels**: choosing that password is what turns the link into an account you can return to. Once you have one, the box shows the portal address and the identity to sign in with instead, under `Sign in with the password you set.`
-- **Status**: a state keyword plus a plain-language explanation
-- **Sensors**: after a check, one colored line per monitored check with its state and last-ping age
-- **Actions**: `Check` (repeatable up to the attempt cap), then `Continue` once verified or `Skip` to move on. A hard blocker removes `Check`, since another attempt cannot help
-
-The screen is skipped, with the reason logged, when monitoring is off, the config cannot be loaded, self mode has no alive URL yet, or the host has no server identity. It is also skipped, along with every other config-dependent post-step, when you answer **Keep existing & continue** at the existing-configuration prompt.
-
-Centralized mode needs no pairing and no API key: the credential is provisioned automatically. `PROVISIONING` simply means it has not completed yet.
+### Scheduling and the daemon
-**CLI mode:**
-- With `--install --cli` the installer applies the same rules and prints the same information as plain text, portal details included in whichever of the two forms applies, then asks whether to run the check now, with a retry loop.
+With the daemon selected, both the CLI and dashboard installers prepare the service before monitoring verification, installing it if missing. Finalization reuses that preparation without repeating service activation. With **Keep existing & continue**, monitoring verification is skipped and preparation runs during finalization. Cron setup remains a final installation step.
-Status keywords, sensor states, and what to do about each are in [HEALTHCHECKS.md](HEALTHCHECKS.md).
+The resident daemon is the default and is required for Healthchecks transmissions. Cron is an opt-out for schedules the daemon cannot express. Review [scheduling](DAEMON.md) and [monitoring](HEALTHCHECKS.md) for their complete setup and verification procedures, including what to do if the installer requires a manual restart.
-#### Telegram pairing wizard (TUI)
+`BASE_DIR` is detected from the executable. An active `BASE_DIR` assignment is ignored and removed by configuration upgrades. On architectures without published releases, continue maintaining your source build: the binary upgrade downloads Linux amd64 rather than compiling your source.
-If you enable Telegram notifications during `--install`, the installer opens an additional **Telegram Setup** screen only when all of these are true:
-- `TELEGRAM_ENABLED=true`
-- `BOT_TELEGRAM_TYPE=centralized` (or left empty, which defaults to centralized)
-- `backup.env` loads successfully
-- a Server ID can be resolved from `/identity/.server_identity`
+
-If any of those checks fail, installation continues without this screen and logs the skip reason (for example config load failure, personal mode, or missing server identity).
+
-When shown, it does **not** modify your `backup.env`. It only:
-- Computes/loads the **Server ID** and persists it (identity file)
-- Guides you through pairing with the centralized bot
-- Lets you verify pairing immediately (retry supported)
+## Legacy migration
-**What you see:**
-- **Instructions**: steps to start the bot and send the Server ID
-- **Server ID**: digits-only identifier + identity file path/persistence status
-- **Status**: live feedback from the pairing check
-- **Actions**:
- - `Check`: verify pairing (press again to retry)
- - `Continue`: available only after a successful check
- - `Skip`: leave without verification (in centralized mode, `ESC` behaves like Skip when not verified)
+Current ProxSave has no automatic legacy migration command. Configuration template merging adds current keys and prunes retired ones; it does not translate a historical installation or guarantee that an old archive can be restored.
-**Where the Server ID is stored:**
-- `/identity/.server_identity`
+### Preserve the old installation
-**If `Check` fails:**
-- `403` / `409`: start the bot, send the Server ID, then try again
-- `422`: the Server ID looks invalid; re-run the installer or regenerate the identity file
-- Other errors: temporary server/network issue; retry or skip and pair later
+1. Identify the historical installation directory, executable or scripts, configuration, archive destinations and scheduler. Record its cron entries, timers or service units before changing them.
+2. Copy the original files and required archives to an independent destination. Keep the historical restore tooling and any required keys with those copies. Do not wipe the old installation or overwrite its configuration.
+3. Choose the new installation location. The release installer always uses `/opt/proxsave`; if the old installation already occupies that directory, preserve it independently before proceeding. Avoid running old and new schedulers against the same destinations.
-**CLI mode:**
-- With `--install --cli`, the installer follows the same eligibility rules, then prints the Server ID and asks whether to run the check now (with a retry loop).
+### Map settings to the current template
-**Features:**
+Install the current version following [Fast Install](#fast-install). In the dashboard choose **Install > Edit install** for the supported wizard fields. Map advanced values manually against the [configuration key reference](CONFIGURATION.md#general-settings), using names, units and accepted values from the current template rather than copying the old file wholesale.
-- Input sanitization (no newlines/control characters)
-- Template comment preservation
-- Creates all necessary directories with proper permissions (0700)
-- Immediate AGE key generation if encryption is enabled
-- Optional post-install audit to disable unused collectors (keeps changes explicit; nothing is disabled silently)
-- Optional Telegram pairing wizard (centralized mode, valid config, Server ID available) that displays Server ID and verifies the bot registration (retry/skip supported)
-- Install session log under `/tmp/proxsave/install-*.log` (includes audit results and Telegram pairing outcome)
+Do not carry forward `BASE_DIR` or `CRON_*` assignments. The executable determines the installation directory, while `SCHEDULER_MODE`, `SCHEDULER_FREQUENCY`, its applicable day and `SCHEDULER_TIME` define the current schedule. Retired chunking and user-home toggles are not supported. Recipient configuration and private recovery keys are different: preserve the private keys independently, and verify the current public recipient before encrypting new backups.
-After completion, re-open the wizard from the dashboard (`Install` > `Edit install`) to change any answer,
-or edit the configuration file directly for the advanced variables the wizard does not ask about. That
-file is `configs/backup.env` under `BASE_DIR` unless you passed `--config`, in which case it is the path
-the install banner printed. See [CONFIGURATION.md](CONFIGURATION.md).
+### Transfer scheduler ownership and verify
-### Scheduling and the daemon
+Disable the historical scheduler before enabling the new one. For a historical cron command that the current installer does not recognize, remove or disable that entry manually; do not assume current finalization discovers every old script name. Choose the new engine in **Install > Edit install**, then inspect **Daemon > Status** for a daemon installation. For cron, inspect the actual crontab and confirm there is only one intended schedule. Only the resident daemon transmits Healthchecks monitoring.
-ProxSave runs the scheduled backup from the resident daemon (`proxsave-daemon.service`) or from cron,
-chosen in the wizard above. The daemon is the normal scheduler and the default on a fresh install: it
-supervises the run with a hang watchdog and it is the only engine that transmits monitoring
-(healthchecks), which reports nothing on a cron host no matter how it is configured. Cron is the legacy
-opt-out path, kept for hosts that must schedule everything from crontab.
+Run **Post-install > Check**, review warnings, then create and verify a new **Backup** using the [first backup guide](BACKUP_GUIDE.md#run-and-verify-your-first-backup). Test restore on a disposable compatible host. Inspect historical archives separately with the original tooling where necessary; a successful current backup does not establish historical format compatibility.
-From the dashboard, the `Daemon` group offers only the commands that apply to your current state:
-`Install` while cron is the scheduler, `Disable` and `Restart` while the daemon is, and `Status` in
-every state (`Status` alone when the configuration cannot be read). On the command line those are
-`proxsave --daemon-setup`, `proxsave --daemon-remove` and `proxsave --daemon-status`; `Restart` has no
-flag of its own and runs `systemctl restart proxsave-daemon.service`. See
-[DAEMON.md](DAEMON.md) and [HEALTHCHECKS.md](HEALTHCHECKS.md).
+Retain the old files until both a new backup and a recovery test have succeeded. If verification fails, stop the new schedule before reinstating the old one, preserving both sets of archives and logs for diagnosis.
-`BASE_DIR` is detected from the installed `proxsave` executable. Do not add an active `BASE_DIR=...` line to `backup.env`; upgrades remove it and runtime ignores it if present.
+
diff --git a/docs/NOTIFICATIONS.md b/docs/NOTIFICATIONS.md
index 83d3818e..2f2948dc 100644
--- a/docs/NOTIFICATIONS.md
+++ b/docs/NOTIFICATIONS.md
@@ -1,46 +1,271 @@
-# Notifications and the centralized bot relay
+# Backup notifications
+
+
+
+## Set up backup notifications
+
+ProxSave reports backup outcomes through Email, Telegram, Gotify and Webhooks.
+Notifications are separate from missing-run monitoring: a dead host or a backup that
+never starts cannot send its own failure message. Use
+[external monitoring](HEALTHCHECKS.md#configure-and-verify-backup-monitoring) for those cases.
+
+A delivery failure does not undo a saved backup. Sending, retries and relay polling are
+awaited and can extend the run. A notification error can promote an otherwise clean
+run to a warning exit outcome, so inspect storage and notification results separately.
+
+### Configure the channels
+
+Run `proxsave` without arguments on an interactive terminal and choose
+**Maintenance** > **Install** > **Edit install**. The wizard offers `Telegram notifications`,
+`Email notifications` and `Email delivery mode`, alongside scheduler and monitoring
+choices. It does not configure every channel field. Edit the active `configs/backup.env`
+for email recipients, Gotify, webhook endpoints and advanced Telegram settings.
+Keep tokens, passwords and endpoint credentials private.
+
+Use **Diagnostic Checks** > **Telegram** for pairing and registration checks.
+Use **Diagnostic Checks** > **Healthchecks** for monitoring state and portal details.
+There is no separate dashboard send-test action for every notification channel;
+verify actual delivery through a backup.
+
+### Choose Email delivery
+
+| Method | Delivery route | Possible fallback |
+| --- | --- | --- |
+| relay | Shared cloud relay | sendmail when enabled |
+| pmf | Proxmox mail-forward | relay, then sendmail |
+| sendmail | Local sendmail queue | None |
+
+Set `EMAIL_ENABLED=true`, choose `EMAIL_DELIVERY_METHOD` and review `EMAIL_RECIPIENT`.
+An empty recipient triggers detection of the `root@pam` email configured in PVE or PBS.
+Relay and sendmail require a valid recipient. The pmf route uses Proxmox Notifications
+and only warns about a missing or malformed address because its routing is external.
+
+Relay blocks root recipients. With sendmail fallback enabled it bypasses relay for
+such an address; otherwise it fails. For pmf the relay fallback is skipped for an
+empty or root recipient. Queue acceptance from sendmail or pmf is not proof of inbox
+delivery, and an accepted relay request is not an end-to-end delivery receipt.
+
+The shared relay cannot be redirected through a private-worker configuration key.
+If reports must avoid that relay, use `sendmail`: pmf can fall back through the shared
+relay for a non-root recipient. See [Email](#email) for recipient detection, sender
+handling and the detailed fallback rules.
+
+### Choose Telegram delivery
+
+Set `TELEGRAM_ENABLED=true` and choose the configured personal or centralized mode.
+Personal mode sends directly with your bot token and chat ID. Centralized mode uses
+the ProxSave relay and host identity; complete pairing through **Diagnostic Checks** >
+**Telegram**. See [Telegram modes](#telegram-personal-vs-centralized) for credential
+boundaries and registration requirements.
+
+In centralized mode, relay acceptance and Telegram confirmation are distinct outcomes.
+An accepted message can be queued or not yet confirmed. The optional delivery poll
+uses the notification ID and has bounded timeouts. Do not equate `accepted` with a
+message visible in chat. Inspect the actual message and, on daemon-supervised runs,
+the delivery sensor. The detailed reference explains
+[all relay outcomes](#the-two-response-delivery-model), including undelivered messages
+that keep a Tier 1 accepted result but mark the Tier 2 delivery sensor down.
+
+### Configure Gotify or Webhooks
+
+Gotify requires `GOTIFY_ENABLED=true`, `GOTIFY_SERVER_URL` and `GOTIFY_TOKEN`. Its
+success, warning and failure priorities default to 2, 5 and 8. Check the application
+receives the message and token permissions allow sending.
+
+Webhooks require `WEBHOOK_ENABLED=true` and `WEBHOOK_ENDPOINTS`, with a named block
+of `WEBHOOK__` fields for each endpoint. Supported formats are generic, Discord,
+Slack, Teams and Pushover. Review each endpoint's URL, method, authentication and custom
+headers in the [Webhooks reference](#webhooks). It includes retry limits and protected
+headers; not every failed HTTP status is retried.
+
+All endpoints are attempted, but the channel reports success when at least one succeeds.
+Verify each destination you rely on rather than only the aggregate result. Pushover
+requires POST, carries its app token and user key in the body and supports priorities
+from -2 to 1; emergency priority 2 is unsupported.
+
+### Decide which outcomes send a message
+
+`NOTIFY_ON` applies a shared threshold across enabled channels. Start with `always`
+while proving delivery. Lower thresholds depend on confirmed external alert delivery:
+monitoring is what catches silent failures when clean-run messages are suppressed.
+Read [notification filtering](#which-runs-get-notified-notify_on) for supported values,
+comparison and override behavior. Enabling notification check URLs does not enable the
+corresponding channel.
+
+### Verify delivery and diagnose failures
+
+1. Save configuration, complete Telegram pairing when applicable, then choose
+ **Backup** in the dashboard.
+2. Read each channel's result and confirm the actual inbox, chat, Gotify application
+ or webhook destination received the message.
+3. On a daemon host check the delivery sensors after the next scheduled run through
+ **Diagnostic Checks** > **Healthchecks** and the monitoring portal. A standalone
+ dashboard backup leaves these per-channel checks untouched.
+4. Resolve queue or relay errors before reducing notification frequency. Recheck
+ credentials, address, endpoint permissions and destination-side spam or routing rules.
+
+Centralized monitoring creates sensors for enabled channels. In self mode you create
+checks and set their `HEALTHCHECK_NOTIFY__URL` or ID. These settings watch
+transmission outcomes and do not send messages. The daemon is the only pinger; cron
+cannot provide this layer.
+
+Secret masking limits accidental log disclosure but is not a reason to share raw
+configuration or payloads. Review diagnostic material before sending it. For specific
+failure messages see [Troubleshooting](#troubleshooting); command equivalents belong in
+[CLI_REFERENCE.md](CLI_REFERENCE.md).
+
+
+
+## Implementation appendix
-ProxSave reports the outcome of every backup run over a small set of channels:
-**Email**, **Telegram**, **Gotify**, and **Webhooks**. On top of those it runs a
-separate monitoring layer that turns each channel's outcome into an external
-dead-man sensor. This document explains how the channels work, the centralized
-Telegram relay (where the bot token stays on the host), the two-response delivery
-model, the portal magic-link, and the log-redaction rules that keep secrets out of
-the logs.
+### The per-channel handoff file
-For the full list of `backup.env` keys see [CONFIGURATION.md](CONFIGURATION.md).
-For the per-channel healthchecks sensors, the monitoring portal, and what each state
-means see [HEALTHCHECKS.md](HEALTHCHECKS.md); for the daemon that pings them see
-[DAEMON.md](DAEMON.md).
+The backup child writes its per-channel outcomes to
+`/daemon_state/.notify_results.json` (atomic write, mode `0600`), and the
+resident daemon (the only process that pings the monitor) reads it after the child
+exits. Two guards keep it honest:
-## Setting the channels up
+- The write is **gated on `PROXSAVE_RUN_ID`**, which only the daemon sets on its
+ child. A run that is not the daemon's child writes no file and leaves nothing stale:
+ that covers a dashboard **Backup**, which runs in the same process as the menu, and a
+ bare `proxsave --backup` by hand.
+- The daemon **rejects any file whose run id is not the run it supervised**, and an
+ empty result set is written as an empty object so the daemon can tell "child ran,
+ nothing to report" from "child crashed" (missing file).
+
+The pings are driven by the channel set **in the file**, not by the daemon's cached
+config, so a channel toggled off between runs never flaps a stale DOWN. The
+Healthchecks section is a reporting surface, not a delivery channel, so it never
+gets a `notify-*` result of its own.
+
+## TOFU secret provisioning
+
+The per-server relay secret is provisioned trust-on-first-use:
+
+1. **Fetch.** The client calls `GET /api/get-chat-id?server_id=` with no
+ `X-Server-Auth` (there is no secret yet). It sends `X-Proxsave-Provision: 1` only
+ when a persist target exists (`BaseDir` set), so a run with nowhere to store a
+ secret never churns one on the server.
+2. **Adopt and persist.** If the `200` response carries a `notify_secret`, the client
+ registers it with the logger for scrubbing, then persists it to
+ `/identity/.notify_secret` (mode `0600`, then `chattr +i`, the same
+ immutable mechanism used for the server identity file). Adoption **overwrites** any
+ existing secret rather than skipping: a `200` carrying a secret means the server
+ wants this one adopted, so a re-issued secret is never stranded.
+3. **Confirm.** The client POSTs `/api/confirm-secret` with `{server_id}` and the new
+ secret in `X-Server-Auth`, which tells the server to stop re-issuing it. This step
+ is best-effort and non-fatal.
+4. **Relay.** The same run then relays through `/api/notify` with the fresh secret.
+
+The persisted secret matches `^[0-9a-z]+(-[0-9a-z]+)*$` (for example
+`3h64-dyi8-q3d6-wcm5`) and is format-validated on **both write and read**.
+`LoadNotifySecret` returns an empty string for an absent, empty, or malformed file
+(junk is never fed into the auth header) and reads under `os.Root` confinement.
+
+`get-chat-id` status codes: `200` success; `403` first contact or the bot has not been
+started; `409` missing registration; `422` invalid `SERVER_ID`; `426` "Upgrade
+ProxSave to v0.28.0 or later to complete pairing".
+
+### Stale-secret recovery
+
+If `/api/notify` answers `401` or `403` (a rotated or stale secret), the notifier
+drops the in-memory secret, reprovisions once through the fetch path, and relays that
+run once (or falls back to the legacy token path). It never loops. Like every other
+notification failure, this is non-critical and never touches the backup.
+
+### The shared cloud relay worker
+
+The `relay` method POSTs to a hardcoded Cloudflare Worker
+(`https://relay-tis24.weathered-hill-5216.workers.dev/send`) with these headers:
+`Authorization: Bearer `, `X-Signature` (HMAC-SHA256 of the JSON
+payload), `X-Script-Version`, `X-Server-MAC`, and a `proxsave/` user agent.
+
+The `WorkerToken` (`v1_public_20251024`) and the HMAC secret are a **shared public
+anti-abuse credential, not a confidential secret**: the same values ship in every
+distributed binary and are published in the repository, so they cannot be kept secret
+on the client. They only gate the free shared worker, whose real protection is
+server-side rate limiting keyed on `server_mac` / `server_id`. Both sites carry a
+`#nosec G101` documenting this. See
+[SECURITY.md](SECURITY.md#hardcoded-relay-credential-g101).
-The everyday route is the dashboard: run `proxsave` with no arguments on a TTY and it
-opens. **Install** > **Edit install** re-runs the install wizard against the existing
-configuration, and its fields cover the switches this document depends on: `Telegram
-notifications`, `Email notifications` with its `Email delivery mode`, `Scheduler engine`
-and `Healthchecks`. The **Diagnostic Checks** group then verifies what the wizard wrote:
-**Telegram** runs the relay pairing screen and re-checks the registration, **Healthchecks**
-shows the monitoring state and the portal details.
-
-Two of those fields are coupled. `Healthchecks` is only selectable when `Scheduler engine`
-is the daemon, because the daemon is the only process that pings; with cron the field is
-dimmed and monitoring is written off: the wizard writes `HEALTHCHECK_ENABLED=false` and
-`HEALTHCHECK_MODE=off`, and only the first of the two turns anything off (see
-[HEALTHCHECKS.md](HEALTHCHECKS.md#turning-monitoring-off)).
-Tier 2 below therefore exists only on a host the daemon schedules.
-
-Everything the wizard does not ask about is a hand edit of `backup.env`: the email
-recipient, Gotify, webhooks, the Telegram delivery-confirmation keys, the Gotify
-priorities. See [CONFIGURATION.md](CONFIGURATION.md).
-
-`--install` and `--new-install` reach the same wizard without going through the dashboard,
-for headless hosts, scripts, and recovery. They still draw the TUI; add `--cli` for
-text-mode prompts when the terminal cannot render it. See [DASHBOARD.md](DASHBOARD.md).
+The worker URL, token and HMAC secret are **compiled-in constants with no configuration
+key behind them**. `CLOUDFLARE_WORKER_URL`, `CLOUDFLARE_WORKER_TOKEN` and
+`CLOUDFLARE_HMAC_SECRET` are not read from `backup.env` or the environment: adding them
+produces no error, no log line and no change, and mail keeps going through the shared
+worker. Pointing the relay at a private worker is not supported today. To keep reports
+off a third-party relay entirely, use `EMAIL_DELIVERY_METHOD=sendmail`: it is the only
+method with no relay fallback. `pmf` is not an alternative. When `proxmox-mail-forward`
+fails and a non-root recipient is configured, ProxSave tries the shared relay **first** and
+only then sendmail, and no configuration key disables that hop.
+
+The worker builds the email from the JSON report (`buildReportData`): a key added or
+changed there also needs the worker's template, or the email sent through the relay
+will not show it.
+
+## Developer notes
+
+### The `serverbot` transport
+
+`internal/serverbot` provides the host-to-bot-server transport for relay and control
+requests. Centralized Telegram messages are delivered through the bot server;
+personal-bot messages use Telegram directly. The daemon sends Healthchecks pings
+directly to the resolved monitoring URL, including self-hosted endpoints.
+The bot-server transport has these contracts:
+
+- It is a **leaf**: it owns headers, a per-request timeout (default 5 s), a bounded
+ response read (default 8192 bytes), and transport-error redaction, and nothing else.
+ It carries no endpoint paths, query keys, DTOs, or HTTP-status semantics; those live
+ in the callers (`notify`, `health`). A Makefile guard (`check-serverbot-leaf`)
+ fails the build if it imports `internal/health`, `internal/notify`,
+ `internal/orchestrator`, `internal/config`, or `internal/identity` (the packages
+ that would create an import cycle and drag endpoint vocabulary back into the
+ transport); the intended contract is `internal/logging`, `internal/version`, and
+ the standard library only.
+- **An HTTP status is never an error.** `Client.Do` returns `(Response, nil)` for any
+ completed exchange, including non-2xx; the caller inspects `Response.Status`. An
+ error comes back only on an encode, build, dial, or read failure, and it is a
+ pre-redacted `*TransportError`. `AuthRejected(status)` is a helper for the shared
+ `401`/`403` concept, not an error path.
+- The `serverID` and secret are **per-request**, not on the client. One stateless
+ client serves the no-secret `get-chat-id` call, the authenticated `notify` call, and
+ the `confirm-secret` call. Headers are stamped conditionally: `X-Proxsave-Version`
+ always, `X-Server-Auth` only when a secret is present, `X-Proxsave-Provision: 1` only
+ when provisioning, `X-Notify-Id` only when set.
+- It must never be pointed at `api.telegram.org` or the `hc.proxsave.dev` monitor.
+
+### Adding a notifier
+
+A channel is anything that implements `notify.Notifier`
+(`Name`, `IsEnabled`, `Send`, `IsCritical`). To add one:
+
+1. Implement the interface. `IsCritical()` **must** return `false`, and `Send` should
+ return a `*NotificationResult` with `Success=false` on failure rather than a
+ non-nil error where possible; a notification must never abort the backup.
+2. Register secrets (`RegisterSecret`) for any token or URL that could appear in a log
+ or an error before you make the first request.
+3. Wire it in `initializeBackupNotifications` (skip with a `disabled` log line when its
+ `*_ENABLED` flag is off) and add it to the fixed `dispatchNotifications` entries,
+ keeping Healthchecks last.
+4. The adapter records the per-channel severity into `.notify_results.json` for you, so
+ the daemon can raise a `proxsave-notify-` sensor without further work.
+5. The `NOTIFY_ON` gate in the entries loop picks the new channel up automatically. Give it
+ a `reportingOnly()` method **only** if it sends nothing outward, the way the Healthchecks
+ section does; a channel that reaches the operator belongs under the threshold. The
+ exemption is claimed by that marker and never by the channel's name, so a display name
+ cannot grant it by accident. Note that an exempt entry is also responsible for its own
+ `.notify_results.json` story, since the gate is what records `filtered` for the others.
+
+
+
+## Detailed reference
+
+The task above is the operator procedure. The following material preserves detailed behavior, limits and implementation context.
## The one invariant: notifications never abort the backup
-A notification is always best-effort. No channel can fail, delay, or block a backup:
+A notification is best-effort: delivery failure does not undo the completed archive.
+Sending and relay polling are awaited, so retries and timeouts can delay run completion.
+The backup result and notification result remain distinct:
- Every notifier reports `IsCritical() == false`. The interface comment is explicit:
"notifications never abort backup" (`internal/notify/notify.go`).
@@ -82,7 +307,7 @@ its own section below (Gotify with `GOTIFY_SERVER_URL` and `GOTIFY_TOKEN`). See
Tier 2 requires the daemon. It is the only process that pings, so a host still on the
cron scheduler raises no `notify-*` sensor at all, however the keys are set, and a run
you start yourself (from the dashboard, or `proxsave --backup` by hand) leaves them
-untouched even under the daemon: see the handoff file below.
+untouched even under the daemon: see the [handoff implementation](#the-per-channel-handoff-file).
The two tiers are decoupled on purpose. A Telegram message the relay accepted but
Telegram did not deliver keeps the run green (Tier 1 success), yet drives the
@@ -123,15 +348,15 @@ INFO Applying notification filter...
INFO Setting: warning
INFO Healthchecks status: ready
INFO Filter in effect: warning
-INFO ✓ Notification filter: applied
+INFO Notification filter: applied
```
When the monitor cannot be confirmed, the block ends with the reason and
-`⚠ Notification filter: not applied`, and `Filter in effect` reads `always`. The outcome is
+`Warning Notification filter: not applied`, and `Filter in effect` reads `always`. The outcome is
stated again at dispatch, where a filtered channel is told apart from a switched-off one:
```text
-INFO ✓ Notification filter: applied
+INFO Notification filter: applied
INFO Notifications: skipped
SKIP Email: filtered # enabled, below the filter
SKIP Gotify: disabled # GOTIFY_ENABLED=false
@@ -158,26 +383,6 @@ These boundaries are what keep the filter from losing information rather than ju
- **An early error is always notified.** A run that fails before its notification setup
never reaches the filter.
-### The per-channel handoff file
-
-The backup child writes its per-channel outcomes to
-`/identity/.notify_results.json` (atomic write, mode `0600`), and the
-resident daemon (the only process that pings the monitor) reads it after the child
-exits. Two guards keep it honest:
-
-- The write is **gated on `PROXSAVE_RUN_ID`**, which only the daemon sets on its
- child. A run that is not the daemon's child writes no file and leaves nothing stale:
- that covers a dashboard **Backup**, which runs in the same process as the menu, and a
- bare `proxsave --backup` by hand.
-- The daemon **rejects any file whose run id is not the run it supervised**, and an
- empty result set is written as an empty object so the daemon can tell "child ran,
- nothing to report" from "child crashed" (missing file).
-
-The pings are driven by the channel set **in the file**, not by the daemon's cached
-config, so a channel toggled off between runs never flaps a stale DOWN. The
-Healthchecks section is a reporting surface, not a delivery channel, so it never
-gets a `notify-*` result of its own.
-
## Telegram: personal vs centralized
Telegram has two modes, chosen by `BOT_TELEGRAM_TYPE` (`personal` or `centralized`,
@@ -205,41 +410,6 @@ itself, so the bot token never leaves the host.** The legacy direct
This is the security keystone of centralized mode: the client stores a low-capability
per-server secret, not the bot token.
-## TOFU secret provisioning
-
-The per-server relay secret is provisioned trust-on-first-use:
-
-1. **Fetch.** The client calls `GET /api/get-chat-id?server_id=` with no
- `X-Server-Auth` (there is no secret yet). It sends `X-Proxsave-Provision: 1` only
- when a persist target exists (`BaseDir` set), so a run with nowhere to store a
- secret never churns one on the server.
-2. **Adopt and persist.** If the `200` response carries a `notify_secret`, the client
- registers it with the logger for scrubbing, then persists it to
- `/identity/.notify_secret` (mode `0600`, then `chattr +i`, the same
- immutable mechanism used for the server identity file). Adoption **overwrites** any
- existing secret rather than skipping: a `200` carrying a secret means the server
- wants this one adopted, so a re-issued secret is never stranded.
-3. **Confirm.** The client POSTs `/api/confirm-secret` with `{server_id}` and the new
- secret in `X-Server-Auth`, which tells the server to stop re-issuing it. This step
- is best-effort and non-fatal.
-4. **Relay.** The same run then relays through `/api/notify` with the fresh secret.
-
-The persisted secret matches `^[0-9a-z]+(-[0-9a-z]+)*$` (for example
-`3h64-dyi8-q3d6-wcm5`) and is format-validated on **both write and read**.
-`LoadNotifySecret` returns an empty string for an absent, empty, or malformed file
-(junk is never fed into the auth header) and reads under `os.Root` confinement.
-
-`get-chat-id` status codes: `200` success; `403` first contact or the bot has not been
-started; `409` missing registration; `422` invalid `SERVER_ID`; `426` "Upgrade
-ProxSave to v0.28.0 or later to complete pairing".
-
-### Stale-secret recovery
-
-If `/api/notify` answers `401` or `403` (a rotated or stale secret), the notifier
-drops the in-memory secret, reprovisions once through the fetch path, and relays that
-run once (or falls back to the legacy token path). It never loops. Like every other
-notification failure, this is non-critical and never touches the backup.
-
## The two-response delivery model
Centralized Telegram delivery has **two responses**, and the distinction is the
@@ -293,8 +463,8 @@ distinct from `pending`) and no poll runs.
Telegram prints **two lines**. The first is server acceptance, the second is delivery:
```text
-✓ Telegram: sent to ProxSave server (in 240ms)
-✓ Telegram: delivered to Telegram
+Telegram: sent to ProxSave server (in 240ms)
+Telegram: delivered to Telegram
```
The first-line latency is acceptance-only (from `relay_accept_duration`), so it
@@ -303,14 +473,14 @@ from the delivery state:
| State | Second line | Level |
|-------|-------------|-------|
-| `delivered` | `✓ Telegram: delivered to Telegram` | info |
-| `failed` | `❌ Telegram: not delivered ()` | warning |
-| `pending` | `⚠️ Telegram: accepted; delivery in progress (auto-retry)` | warning |
+| `delivered` | `Telegram: delivered to Telegram` | info |
+| `failed` | `Telegram: not delivered ()` | warning |
+| `pending` | `Warning Telegram: accepted; delivery in progress (auto-retry)` | warning |
| `unconfirmed` | (quiet, confirmation disabled) | debug |
-| `unknown` | `⚠️ Telegram: accepted; delivery not confirmed` | warning |
+| `unknown` | `Warning Telegram: accepted; delivery not confirmed` | warning |
If acceptance itself failed, the first line reads
-`❌ Telegram: could not send to ProxSave server`. The failure `` on the
+`Telegram: could not send to ProxSave server`. The failure `` on the
`failed` line is translated for humans: `bot blocked by the user` (`http_403`),
`invalid chat` (`http_400` / `http_404`), `message too long` (`http_413`),
`Telegram unreachable too long (expired)` and `too many failed attempts` (the
@@ -396,34 +566,13 @@ bypasses relay and goes straight to sendmail; without a fallback it hard-fails w
(HTTP `200` from the worker); sendmail and pmf explicitly warn that exit code `0`
means "accepted to queue, not necessarily delivered".
-### The shared cloud relay worker
-
-The `relay` method POSTs to a hardcoded Cloudflare Worker
-(`https://relay-tis24.weathered-hill-5216.workers.dev/send`) with these headers:
-`Authorization: Bearer `, `X-Signature` (HMAC-SHA256 of the JSON
-payload), `X-Script-Version`, `X-Server-MAC`, and a `proxsave/` user agent.
+### Keep email reports off the shared relay
-The `WorkerToken` (`v1_public_20251024`) and the HMAC secret are a **shared public
-anti-abuse credential, not a confidential secret**: the same values ship in every
-distributed binary and are published in the repository, so they cannot be kept secret
-on the client. They only gate the free shared worker, whose real protection is
-server-side rate limiting keyed on `server_mac` / `server_id`. Both sites carry a
-`#nosec G101` documenting this. See
-[SECURITY.md](SECURITY.md#hardcoded-relay-credential-g101).
-
-The worker URL, token and HMAC secret are **compiled-in constants with no configuration
-key behind them**. `CLOUDFLARE_WORKER_URL`, `CLOUDFLARE_WORKER_TOKEN` and
-`CLOUDFLARE_HMAC_SECRET` are not read from `backup.env` or the environment: adding them
-produces no error, no log line and no change, and mail keeps going through the shared
-worker. Pointing the relay at a private worker is not supported today. To keep reports
-off a third-party relay entirely, use `EMAIL_DELIVERY_METHOD=sendmail`: it is the only
-method with no relay fallback. `pmf` is not an alternative. When `proxmox-mail-forward`
-fails and a non-root recipient is configured, ProxSave tries the shared relay **first** and
-only then sendmail, and no configuration key disables that hop.
-
-The worker builds the email from the JSON report (`buildReportData`): a key added or
-changed there also needs the worker's template, or the email sent through the relay
-will not show it.
+The relay endpoint and its client credentials are compiled into ProxSave; there is no
+supported private-worker override. To avoid sending email reports to the shared relay,
+use `EMAIL_DELIVERY_METHOD=sendmail`. The `pmf` mode can fall back to the shared relay
+before sendmail when a non-root recipient is configured. `CLOUDFLARE_WORKER_URL`,
+`CLOUDFLARE_WORKER_TOKEN` and `CLOUDFLARE_HMAC_SECRET` do not change this behavior.
## Gotify
@@ -501,57 +650,6 @@ is safe to log as-is. Debug logging in the transport is body-free and secret-fre
runes for console safety but is **not** secret-redacted, so a caller must wrap it with
`RedactSecrets` when the per-request secret could appear in the body.
-## Developer notes
-
-### The `serverbot` transport
-
-`internal/serverbot` is the single host-to-bot-server transport, and the **only**
-thing on the host that talks to `bot.proxsave.dev`. Telegram and Healthchecks
-delivery happen beyond the bot-server, not from the host directly. Key contracts:
-
-- It is a **leaf**: it owns headers, a per-request timeout (default 5 s), a bounded
- response read (default 8192 bytes), and transport-error redaction, and nothing else.
- It carries no endpoint paths, query keys, DTOs, or HTTP-status semantics; those live
- in the callers (`notify`, `health`). A Makefile guard (`check-serverbot-leaf`)
- fails the build if it imports `internal/health`, `internal/notify`,
- `internal/orchestrator`, `internal/config`, or `internal/identity` (the packages
- that would create an import cycle and drag endpoint vocabulary back into the
- transport); the intended contract is `internal/logging`, `internal/version`, and
- the standard library only.
-- **An HTTP status is never an error.** `Client.Do` returns `(Response, nil)` for any
- completed exchange, including non-2xx; the caller inspects `Response.Status`. An
- error comes back only on an encode, build, dial, or read failure, and it is a
- pre-redacted `*TransportError`. `AuthRejected(status)` is a helper for the shared
- `401`/`403` concept, not an error path.
-- The `serverID` and secret are **per-request**, not on the client. One stateless
- client serves the no-secret `get-chat-id` call, the authenticated `notify` call, and
- the `confirm-secret` call. Headers are stamped conditionally: `X-Proxsave-Version`
- always, `X-Server-Auth` only when a secret is present, `X-Proxsave-Provision: 1` only
- when provisioning, `X-Notify-Id` only when set.
-- It must never be pointed at `api.telegram.org` or the `hc.proxsave.dev` monitor.
-
-### Adding a notifier
-
-A channel is anything that implements `notify.Notifier`
-(`Name`, `IsEnabled`, `Send`, `IsCritical`). To add one:
-
-1. Implement the interface. `IsCritical()` **must** return `false`, and `Send` should
- return a `*NotificationResult` with `Success=false` on failure rather than a
- non-nil error where possible; a notification must never abort the backup.
-2. Register secrets (`RegisterSecret`) for any token or URL that could appear in a log
- or an error before you make the first request.
-3. Wire it in `initializeBackupNotifications` (skip with a `disabled` log line when its
- `*_ENABLED` flag is off) and add it to the fixed `dispatchNotifications` entries,
- keeping Healthchecks last.
-4. The adapter records the per-channel severity into `.notify_results.json` for you, so
- the daemon can raise a `proxsave-notify-` sensor without further work.
-5. The `NOTIFY_ON` gate in the entries loop picks the new channel up automatically. Give it
- a `reportingOnly()` method **only** if it sends nothing outward, the way the Healthchecks
- section does; a channel that reaches the operator belongs under the threshold. The
- exemption is claimed by that marker and never by the channel's name, so a display name
- cannot grant it by accident. Note that an exempt entry is also responsible for its own
- `.notify_results.json` story, since the gate is what records `filtered` for the others.
-
## Troubleshooting
| Symptom | Likely cause | Where to look |
@@ -572,3 +670,13 @@ See [CONFIGURATION.md](CONFIGURATION.md) for every key, [DAEMON.md](DAEMON.md) f
monitoring sensors, and [DASHBOARD.md](DASHBOARD.md) for the dashboard screens that
pair Telegram and show the monitoring state. [INSTALL.md](INSTALL.md) covers the same
pairing step inside the installer.
+
+## Earlier guide entry points
+
+## Setting the channels up
+
+See the complete [operator procedure](#set-up-backup-notifications). Detailed settings and implementation material remain in the reference sections above.
+
+## Verify notification delivery
+
+See the complete [operator procedure](#set-up-backup-notifications). Detailed settings and implementation material remain in the reference sections above.
diff --git a/docs/PROVENANCE_VERIFICATION.md b/docs/PROVENANCE_VERIFICATION.md
index 230cc2e7..59ab2fef 100644
--- a/docs/PROVENANCE_VERIFICATION.md
+++ b/docs/PROVENANCE_VERIFICATION.md
@@ -1,14 +1,91 @@
-# Provenance Attestation Verification
+# Verify release authenticity
+
+
+
+## Verify a ProxSave release
+
+ProxSave's installer and upgrade workflow verify a signed checksum file using a public
+key pinned in the tool. A missing or invalid signature stops the operation; the selected
+archive must also match its authenticated checksum. Build attestations provide an
+additional, optional check of artifact identity and recorded provenance.
+
+### Install or upgrade through the verified workflow
+
+For a first installation, use the script in [Install ProxSave](INSTALL.md#fast-install).
+It performs signature and checksum verification before installing the release. Keep a
+trusted existing copy or recovery route available if you are upgrading a working host.
+
+For an existing installation:
+
+1. Run `proxsave` without arguments on an interactive terminal.
+2. Choose **Maintenance** > **Upgrade** > **Check upgrade**. This opens the release
+ check and displays the available version and release notes; it does not install it.
+3. Inspect the result. When an update is available, choose **Run upgrade** to download,
+ verify and install it. A failed signature or checksum is a reason to stop.
+4. Read the final result, including configuration merging and daemon restart status.
+ Choose **Daemon** > **Status** to check the running binary when using the resident
+ daemon. A deferred or failed restart can leave the old process running.
+
+The adjacent **Check config** action reviews missing configuration variables and offers
+an explicit apply step. It is separate from checking for a new binary. See
+[configuration upgrades](CONFIGURATION.md#editing-the-configuration-from-the-dashboard) for details.
+
+The installed binary drives an in-place upgrade, including its verification. Only the
+post-install finalize phase can be delegated to the new binary when both releases
+support it. A fix to upgrade code in the new release cannot change the old binary that
+is currently downloading it. If release instructions require the externally fetched
+installer, follow [Which binary runs the upgrade](#which-binary-runs-the-upgrade).
+
+### Verify a downloaded artifact with GitHub CLI
+
+This optional check is useful before manually installing an artifact. Install `gh`
+using the [prerequisites](#prerequisites), obtain the intended release asset, then set
+the exact tag and filename:
+
+```bash
+TAG=vX.Y.Z
+VER=${TAG#v}
+ASSET="proxsave_${VER}_linux_amd64"
+gh attestation verify "$ASSET" \
+ --repo tis24dev/proxsave \
+ --signer-workflow tis24dev/proxsave/.github/workflows/release.yml \
+ --source-ref "refs/tags/${TAG}" \
+ --deny-self-hosted-runners
+```
+
+Require a successful verifier exit status. This policy checks the artifact digest,
+repository, release workflow, source reference and runner type. To require an independently
+trusted commit, add the source-digest policy described in [What gets verified](#what-gets-verified).
+The [manual signature procedure](#verify-a-download-manually) contains the pinned key and
+signed-checksum commands. [Verification methods](#verification-methods) also covers archives,
+JSON results and offline verification with previously obtained trust material.
+
+Successful verification connects the artifact to the selected identity and recorded build.
+It does not establish that the source, dependencies or workflow are safe or uncompromised.
+The signed checksum and attestation serve different verification policies; keep those
+limits in mind when evaluating a release.
+
+### Respond to a failed check
+
+Do not run the unverified binary or disable verification to finish the upgrade. Confirm
+the tag, asset name and download completeness, then follow the matching
+[verification error](#troubleshooting). Retry a clean download when appropriate. If the
+failure remains, preserve the error and request support without replacing the working
+installation. Verification of a release is separate from checking that a backup or
+restore succeeds on your host.
+
+
## Introduction
-Every Proxsave release binary includes cryptographically signed provenance attestations that prove:
-- The binary was built from this repository
-- The binary was built using GitHub Actions
-- The binary has not been tampered with after the build
-- The build process is traceable and verifiable
+The release workflow creates signed build-provenance attestations for its binary,
+archive and SBOM assets. Verification checks the artifact digest and signing identity
+against the policy you request. The recorded provenance identifies the source and
+build workflow; it does not prove that their contents are safe or uncompromised.
-Attestations use the SLSA (Supply-chain Levels for Software Artifacts) standard and are registered in an immutable public transparency log (Sigstore).
+Public-repository attestations use Sigstore and a public transparency log. See
+[GitHub's explanation of artifact attestations](https://docs.github.com/en/actions/concepts/security/artifact-attestations)
+for their guarantees and limits.
Proxsave publishes a single build target, `linux/amd64`. The release assets for a tag `vX.Y.Z` are:
@@ -57,7 +134,11 @@ sha256sum --ignore-missing -c SHA256SUMS
### How an operator gets a verified release
-The everyday upgrade route is the dashboard: run `proxsave` with no arguments on a TTY, then **Upgrade** > **Check upgrade**. It runs the same `--upgrade` code in-session, so the signature and checksum check described above is the same one, not a second path. `--upgrade` on its own is the headless equivalent, for scripts and for hosts with no terminal; append `y` to auto-confirm. Both also merge new configuration keys and, on a host where the resident daemon is actually running, restart it onto the new binary, which downloading a file by hand does not: a replaced binary leaves the running daemon on the old code until the service is restarted (see [DAEMON.md](DAEMON.md)). A host on the cron scheduler has no resident daemon, so there is nothing to restart there.
+Follow [Verify a ProxSave release](#verify-a-proxsave-release) for the dashboard
+procedure. **Check upgrade** checks availability; **Run upgrade** installs the release.
+**Check config** is the separate action for reviewing and merging configuration keys.
+The signature and checksum verification uses the same implementation as direct upgrade.
+Command equivalents are in [CLI_REFERENCE.md](CLI_REFERENCE.md).
### Which binary runs the upgrade
@@ -73,11 +154,14 @@ See [SECURITY.md](SECURITY.md#threat-model) for the same split stated against th
## Why attestations matter
-Provenance attestations protect against:
-- **Supply chain attacks**: verifies that the binary comes from the official repository
-- **Tampering**: guarantees that no one has modified the binary after the build
-- **Compromises**: proves that the binary was built in a trusted environment (GitHub Actions)
-- **Unauthorized builds**: confirms that only maintainers can create releases
+A successful verification establishes that the artifact matches the attested digest
+and satisfies the selected identity policy. Provenance also records source and build
+information that can be checked against an independently trusted release.
+
+It does not establish that only maintainers can publish releases, or rule out malicious
+source, dependencies or a compromised build workflow. Inspect the selected policy in
+[What gets verified](#what-gets-verified); repository identity alone is less restrictive
+than also requiring the expected workflow, source reference and commit.
## Prerequisites
@@ -139,7 +223,8 @@ cd ~/downloads
wget "https://github.com/tis24dev/proxsave/releases/download/${TAG}/${ASSET}"
wget "https://github.com/tis24dev/proxsave/releases/download/${TAG}/${ASSET}.tar.gz"
-gh attestation verify proxsave_${VER}_linux_amd64* --repo tis24dev/proxsave
+gh attestation verify "${ASSET}" --repo tis24dev/proxsave &&
+ gh attestation verify "${ASSET}.tar.gz" --repo tis24dev/proxsave
```
### Method 3: verification with JSON output
@@ -152,54 +237,49 @@ gh attestation verify "${ASSET}" \
--format json | jq
```
-**JSON output** (example):
-```json
-{
- "verificationResult": {
- "verifiedTimestamps": [
- { "timestamp": "2025-06-20T10:30:45Z", "source": "Rekor" }
- ],
- "statement": {
- "_type": "https://in-toto.io/Statement/v1",
- "subject": [
- {
- "name": "proxsave_0.29.0_linux_amd64",
- "digest": { "sha256": "abc123..." }
- }
- ],
- "predicateType": "https://slsa.dev/provenance/v1",
- "predicate": {
- "buildDefinition": {
- "buildType": "https://slsa.dev/provenance/github/actions/v1",
- "externalParameters": {
- "workflow": {
- "ref": "refs/tags/v0.29.0",
- "repository": "https://github.com/tis24dev/proxsave"
- }
- }
- }
- }
- }
- }
-}
+Successful `--format json` output is an array, with one entry per verified
+attestation. Each entry contains `attestation` and `verificationResult`. For example,
+extract the attested subjects with:
+
+```bash
+set -o pipefail
+gh attestation verify "${ASSET}" --repo tis24dev/proxsave --format json \
+ | jq 'map(.verificationResult.statement.subject)'
```
+Keep the verifier's exit status when automating this check; formatted JSON alone
+is not a substitute for a successful verification.
+
### Method 4: offline verification (with downloaded bundle)
-Useful for air-gapped environments or for archiving attestations.
+Prepare the artifact, attestation and trust material on a connected Linux host:
```bash
-# Download the attestation as a bundle
-gh attestation download "${ASSET}" \
- --repo tis24dev/proxsave \
- --output attestation.jsonl
+# The artifact must already be present
+gh attestation download "${ASSET}" --repo tis24dev/proxsave
+gh attestation trusted-root > trusted_root.jsonl
+
+# Linux download filenames are derived from the artifact digest
+DIGEST=$(sha256sum "${ASSET}" | cut -d' ' -f1)
+BUNDLE="sha256:${DIGEST}.jsonl"
+test -s "$BUNDLE" && test -s trusted_root.jsonl
+```
-# Verify offline using the bundle
+Transfer those three files through your trusted channel. On the offline host, set
+`ASSET` to the transferred artifact, recompute `DIGEST` and `BUNDLE` as above, then run:
+
+```bash
gh attestation verify "${ASSET}" \
- --bundle attestation.jsonl \
+ --bundle "$BUNDLE" \
+ --custom-trusted-root trusted_root.jsonl \
--repo tis24dev/proxsave
```
+The trust-root file must come from the trusted preparation step, not from an
+untrusted source alongside a suspect binary. The commands and filename convention
+are documented by [GitHub CLI download](https://cli.github.com/manual/gh_attestation_download)
+and [trusted-root](https://cli.github.com/manual/gh_attestation_trusted-root).
+
## A complete verify-and-install example (Linux)
```bash
@@ -227,28 +307,40 @@ sudo mv "${ASSET}" /usr/local/bin/proxsave
proxsave --version
```
-The recipe above is the manual path, for an air-gapped host or an audit. For a first install the recommended path is the install script, which performs the `SHA256SUMS.sig` signature check automatically:
+The recipe above is a connected, manual installation with repository-scoped attestation verification. Offline verification needs the files prepared in Method 4. For a first install the recommended path is the install script, which performs the `SHA256SUMS.sig` signature check automatically:
```bash
bash -c "$(curl -fsSL https://raw.githubusercontent.com/tis24dev/proxsave/main/install.sh)"
```
-On a host that already runs ProxSave, upgrade from the dashboard (**Upgrade** > **Check upgrade**) rather than downloading a binary by hand; see [How an operator gets a verified release](#how-an-operator-gets-a-verified-release).
+On a host that already runs ProxSave, use **Maintenance** > **Upgrade** > **Check upgrade**, inspect the result and select **Run upgrade** when available; see [How an operator gets a verified release](#how-an-operator-gets-a-verified-release).
## What gets verified
-When you run `gh attestation verify`, the following checks are performed:
+The examples using only `--repo` check artifact integrity and repository identity.
+They do not pin a particular release workflow, expected commit or runner type.
+
+| Check | Policy in the examples above |
+|-------|------------------------------|
+| Artifact digest | Must match the attested subject |
+| Repository identity | Must match `tis24dev/proxsave` |
+| Signature and trust | Validated by the verifier using its trusted roots and signed attestation material |
+| Predicate type | Defaults to SLSA provenance v1; this is not a general SLSA certification |
+| Commit, workflow and runner | Reported provenance must be distinguished from an explicitly required policy |
-| Verification | Description |
-|--------------|-------------|
-| Source repository | Confirms the build comes from `github.com/tis24dev/proxsave` |
-| Commit SHA | Verifies the exact commit used for the build |
-| Workflow | Checks that `.github/workflows/release.yml` was used |
-| Build environment | Confirms the build occurred on a GitHub-hosted runner |
-| SHA256 integrity | Recomputes the file hash and compares it with the attested one |
-| Cryptographic signature | Verifies the OIDC/Sigstore signature on the attestation |
-| Rekor timestamp | Checks the immutable record in the transparency log |
-| SLSA compliance | Verifies the attestation complies with the SLSA v1 standard |
+To require the release workflow, the chosen source tag and a GitHub-hosted runner:
+
+```bash
+gh attestation verify "${ASSET}" \
+ --repo tis24dev/proxsave \
+ --signer-workflow tis24dev/proxsave/.github/workflows/release.yml \
+ --source-ref "refs/tags/${TAG}" \
+ --deny-self-hosted-runners
+```
+
+To pin an independently trusted commit, also pass `--source-digest` with that commit
+SHA. For offline use, add Method 4's bundle and trust-root arguments. See the
+[GitHub CLI verification policy](https://cli.github.com/manual/gh_attestation_verify).
## Troubleshooting
@@ -256,7 +348,7 @@ The variables `TAG`, `VER`, and `ASSET` below are the ones defined in [Verificat
### Error: "no attestations found"
-**Cause**: the release does not include attestations (a release created before this feature).
+**Cause**: no matching attestation was found for this artifact and policy. Check the selected asset and release; older releases may predate attestations.
**Solution**:
```bash
@@ -293,9 +385,12 @@ ls -lh "${ASSET}"
rm -f "${ASSET}"
wget "https://github.com/tis24dev/proxsave/releases/download/${TAG}/${ASSET}"
-# Optional: cross-check against the signed checksums
+# Optional: authenticate the checksum file before checking the artifact
+# Save the pinned public key from this guide as proxsave_pub.pem first
wget "https://github.com/tis24dev/proxsave/releases/download/${TAG}/SHA256SUMS"
-sha256sum --ignore-missing -c SHA256SUMS
+wget "https://github.com/tis24dev/proxsave/releases/download/${TAG}/SHA256SUMS.sig"
+openssl dgst -sha256 -verify proxsave_pub.pem -signature SHA256SUMS.sig SHA256SUMS &&
+ sha256sum --ignore-missing -c SHA256SUMS
```
### Error: "HTTP 401: Bad credentials"
@@ -324,7 +419,7 @@ Attestations are based on:
2. **Sigstore/Rekor**: a public transparency log that records all attestations
3. **SLSA framework**: an industry standard for provenance metadata
-**What this means**: you must trust GitHub as the root of trust for the attestations. If GitHub is compromised, attestations could be forged. The pinned-key `SHA256SUMS.sig` signature is an independent check that does not rely on GitHub as a signer.
+The verification depends on its trusted identity and certificate roots, as well as trust in the selected source and build workflow. The pinned-key `SHA256SUMS.sig` signature uses a separate signing key. Both checks still depend on the release workflow and protection of its credentials; neither proves the program is free of vulnerabilities.
### Transparency log (Rekor)
diff --git a/docs/README.md b/docs/README.md
index 9961cd23..fd3b3f37 100644
--- a/docs/README.md
+++ b/docs/README.md
@@ -1,43 +1,83 @@
-# Proxsave Documentation Index
+# ProxSave documentation
-This directory contains the authoritative project documentation.
+These guides describe host configuration backup and recovery for Proxmox VE and Proxmox Backup Server
-Start with [DASHBOARD.md](DASHBOARD.md). The interactive dashboard, which opens when you run
-`proxsave` with no arguments on a terminal, is the primary way to operate ProxSave: backup,
-restore, configuration, upgrade, daemon management and the diagnostic checks all live there.
-The command-line flags in [CLI_REFERENCE.md](CLI_REFERENCE.md) cover the automation, headless
-and recovery routes.
-
-The repository root `README.md` stays a short overview. Use the documents
-below for the current operational and technical behavior.
+After installation, open an interactive terminal and run `proxsave` without arguments to use the dashboard. The operator guides follow its menus. Command-line options for automation and headless use are kept in the [CLI reference](CLI_REFERENCE.md)
## User Guides
-- [DASHBOARD.md](DASHBOARD.md): the interactive dashboard, screen by screen (start here)
-- [INSTALL.md](INSTALL.md): installation, reinstall, and upgrade flows
-- [CONFIGURATION.md](CONFIGURATION.md): complete `backup.env` reference, and which settings the dashboard form covers
-- [DAEMON.md](DAEMON.md): the resident daemon, the scheduler a new install gets, its watchdog and the engines
-- [HEALTHCHECKS.md](HEALTHCHECKS.md): backup monitoring under the daemon, the monitoring portal, and self-hosted setups
-- [RESTORE_GUIDE.md](RESTORE_GUIDE.md): full restore guide and category behavior
-- [NOTIFICATIONS.md](NOTIFICATIONS.md): notification channels and the centralized bot relay
-- [EXAMPLES.md](EXAMPLES.md): ready-to-use configuration examples
-- [CLI_REFERENCE.md](CLI_REFERENCE.md): flags for automation, headless hosts, cron jobs and recovery
-- [TROUBLESHOOTING.md](TROUBLESHOOTING.md): operational diagnostics and fixes
+### Start and maintain
+
+| Task | Guide |
+| --- | --- |
+| Understand what is protected | [Backup scope](BACKUP_GUIDE.md#what-proxsave-backs-up) |
+| Install ProxSave | [Installation](INSTALL.md#fast-install) |
+| Make and verify the first backup | [First backup](BACKUP_GUIDE.md#run-and-verify-your-first-backup) |
+| Navigate the application | [Dashboard](DASHBOARD.md) |
+| Update an existing installation | [Upgrade](INSTALL.md#upgrading-proxsave-binary) |
+| Build from source | [Manual installation](INSTALL.md#manual-installation) |
+
+### Backup and storage
+
+| Task | Guide |
+| --- | --- |
+| Choose files and collectors | [Collection policy](BACKUP_GUIDE.md#choose-what-to-collect) |
+| Understand the run stages | [Backup workflow](BACKUP_GUIDE.md#how-a-backup-runs) |
+| Choose local, NAS, cloud or PBS storage | [Destinations](STORAGE.md#choose-and-verify-backup-destinations) |
+| Configure retention | [Retention policy](STORAGE.md#set-backup-retention) |
+| Save a host backup directly to PBS | [Native PBS backups](STORAGE.md#create-native-pbs-backups) |
+| Configure rclone and remote paths | [Cloud storage](CLOUD_STORAGE.md) |
+| Combine features for a particular host | [Practical examples](EXAMPLES.md) |
+
+### Encryption and trust
+
+| Task | Guide |
+| --- | --- |
+| Encrypt archives and retain recovery keys | [Encryption](ENCRYPTION.md) |
+| Decrypt a bundle | [Decryption](ENCRYPTION.md#decrypting-backups) |
+| Verify release signatures and attestations | [Release verification](PROVENANCE_VERIFICATION.md) |
+
+### Scheduling and alerts
+
+| Task | Guide |
+| --- | --- |
+| Schedule and supervise backup runs | [Resident daemon](DAEMON.md) |
+| Detect missed or failed backups | [Healthchecks monitoring](HEALTHCHECKS.md) |
+| Configure result messages | [Notifications](NOTIFICATIONS.md) |
+
+### Restore and recovery
+
+| Task | Guide |
+| --- | --- |
+| Plan and perform a host configuration restore | [Restore workflow](RESTORE_GUIDE.md#restore-a-host) |
+| Understand what a restore mode includes | [Restore modes](RESTORE_GUIDE.md#choose-restore-modes-and-categories) |
+| Recover cluster configuration | [Cluster recovery](CLUSTER_RECOVERY.md#recover-a-proxmox-cluster) |
+| Recover boot and passthrough settings | [IOMMU, VFIO and passthrough](RESTORE_GUIDE.md#restore-iommu-vfio-and-passthrough-settings) |
+| Retrieve archived cloud backups before restoring | [Cold-storage recovery](CLOUD_STORAGE.md#recover-archives-from-cold-object-storage) |
+
+### Reference and help
+
+| Task | Guide |
+| --- | --- |
+| Look up settings and defaults | [Configuration reference](CONFIGURATION.md) |
+| Automate operations | [CLI reference](CLI_REFERENCE.md) |
+| Diagnose failures and collect debug logs | [Troubleshooting](TROUBLESHOOTING.md#diagnose-backup-and-restore-failures) |
+| Prepare a support request | [Getting help](TROUBLESHOOTING.md#prepare-a-support-request) |
## Architecture & Developer Docs
-- [DEVELOPER_GUIDE.md](DEVELOPER_GUIDE.md): contributor setup and development workflow
-- [COLLECTOR_ARCHITECTURE.md](COLLECTOR_ARCHITECTURE.md): collector recipes, bricks, and `dual`
-- [DASHBOARD_TUI.md](DASHBOARD_TUI.md): internals of the dashboard and every graphical flow, components, and screen contracts
-- [RESTORE_TECHNICAL.md](RESTORE_TECHNICAL.md): restore internals and orchestration details
-- [RESTORE_DIAGRAMS.md](RESTORE_DIAGRAMS.md): visual restore workflow diagrams
-- [SECURITY.md](SECURITY.md): execution model, preflight checks, and secret handling
-- [TEST_STRATEGY.md](TEST_STRATEGY.md): test conventions and coverage policy
+These references explain implementation and contribution work. Operator procedures live in the task guides above
+
+- [Developer guide](DEVELOPER_GUIDE.md): build, test and contributor workflow
+- [Collector architecture](COLLECTOR_ARCHITECTURE.md): role-specific recipes and shared collection
+- [Dashboard architecture](DASHBOARD_TUI.md): screens, sessions and workflow integration
+- [Restore internals](RESTORE_TECHNICAL.md): orchestration, category handling and diagrams
+- [Security model](SECURITY.md): execution boundaries, preflight checks and secret handling
+- [Test strategy](TEST_STRATEGY.md): testing conventions and UI-driver coverage
+- [Release process](RELEASE-PROCESS.md): branches, review and release engineering
## Supporting References
-- [CLOUD_STORAGE.md](CLOUD_STORAGE.md): cloud/rclone behavior
-- [ENCRYPTION.md](ENCRYPTION.md): archive encryption and decrypt/restore flow
-- [PROVENANCE_VERIFICATION.md](PROVENANCE_VERIFICATION.md): release signature and SLSA attestation verification
-- [CLUSTER_RECOVERY.md](CLUSTER_RECOVERY.md): PVE cluster disaster recovery
-- [RELEASE-PROCESS.md](RELEASE-PROCESS.md): release engineering notes
+[Restore diagram links](RESTORE_DIAGRAMS.md) remain available for existing references. Diagrams are maintained beside the corresponding explanations in the restore technical guide
+
+The [website source map](publishing/site-map.json) identifies the task sections intended for GH Sync. Editorial review and preview checks are required before publishing a changed mapping; the file is not a record that an import has happened
diff --git a/docs/RELEASE-PROCESS.md b/docs/RELEASE-PROCESS.md
index 591a3e0b..dfd2ae5b 100644
--- a/docs/RELEASE-PROCESS.md
+++ b/docs/RELEASE-PROCESS.md
@@ -43,6 +43,8 @@ One consequence is worth stating plainly: once a `vX.Y.Z` tag exists it cannot b
After an upgrade the dashboard opens on Screen 0 to show what changed. Its copy lives in the `notes` slice in `internal/whatsnew/registry.go`, one entry per FINAL release. The authoring rules (what belongs in `Lines`, what belongs in `Actions`, the fixed section headers) are documented in that file, above the slice.
+List only new user features, without individual fixes or refinements. When a release has no new features, its only `Lines` entry is `This release includes a collection of fixes and corrections.` If a new feature is added before release, replace that generic line with the feature notes. The release still needs its own registry entry and passes the same release-notes guard.
+
Write the entry BEFORE the first tag of a line, beta included, not in the final's release PR. Notes are keyed to the final version and the seen-flag is compared on FINALIZED versions, so `0.31.0-beta1` and `0.31.0` are the same line. A beta released without the entry renders the empty state and still records the line as seen, which suppresses Screen 0 when the final lands: the users who tested the betas are exactly the ones who never see that release's notes.
The gate enforces this. `TestReleaseNotesPresent` finalizes the requested tag, so `pr-v0.31.0-beta1` demands the `0.31.0` entry just as `pr-v0.31.0` does.
diff --git a/docs/RESTORE_DIAGRAMS.md b/docs/RESTORE_DIAGRAMS.md
index d33fc941..52b7413d 100644
--- a/docs/RESTORE_DIAGRAMS.md
+++ b/docs/RESTORE_DIAGRAMS.md
@@ -1,804 +1,64 @@
# Restore Workflow Diagrams
-Visual diagrams for understanding the restore system architecture and flow.
-Use this file as a visual companion to [RESTORE_GUIDE.md](RESTORE_GUIDE.md) and
-[RESTORE_TECHNICAL.md](RESTORE_TECHNICAL.md), not as the primary place for
-textual restore rules.
-
-Every flow below starts at the same place. The normal entry is the dashboard:
-`proxsave` with no arguments on a terminal, then **Tools > Restore** (see
-[DASHBOARD.md](DASHBOARD.md)). `proxsave --restore` enters the identical workflow
-directly and is the path for a headless host, a rescue shell, or any terminal the
-dashboard cannot use. Nothing downstream of the entry point differs between the two.
-
-## Table of Contents
-
-- [Complete Restore Workflow](#complete-restore-workflow)
-- [Category Decision Tree](#category-decision-tree)
-- [Service Management Flow](#service-management-flow)
-- [Three-Tier Extraction](#three-tier-extraction)
-- [Cluster Database Restore Sequence](#cluster-database-restore-sequence)
-- [Error Handling Flow](#error-handling-flow)
-- [PBS Datastore Mount Guards](#pbs-datastore-mount-guards)
-
----
+Diagrams now accompany the implementation explanations in [Restore technical documentation](RESTORE_TECHNICAL.md#architecture-overview). Existing headings below preserve links to this file.
## Complete Restore Workflow
-```mermaid
-flowchart TD
- Start(["Dashboard, Tools group: Restore
or proxsave --restore"]) --> SelectBackup[Select Backup Source]
- SelectBackup --> ScanBackups[Scan for Backups]
- ScanBackups --> ChooseBackup[Choose Specific Backup]
-
- ChooseBackup --> CheckEncryption{Encrypted?}
- CheckEncryption -->|Yes| Decrypt[Decrypt with AGE]
- CheckEncryption -->|No| SystemDetect[Detect System Type]
- Decrypt --> VerifyChecksum[Verify SHA256]
- VerifyChecksum --> SystemDetect
-
- SystemDetect --> Compatibility[Validate Compatibility]
- Compatibility --> CompatCheck{Compatible?}
- CompatCheck -->|No| WarnUser[Warn User]
- WarnUser --> UserDecision{Continue?}
- UserDecision -->|No| Abort([Abort])
- UserDecision -->|Yes| AnalyzeCategories
- CompatCheck -->|Yes| AnalyzeCategories[Analyze Categories]
-
- AnalyzeCategories --> SelectMode[Select Restore Mode]
- SelectMode --> ModeChoice{Mode?}
- ModeChoice -->|Full| GetFullCats[All Categories]
- ModeChoice -->|Storage| GetStorageCats[Storage Categories]
- ModeChoice -->|Base| GetBaseCats[Base Categories]
- ModeChoice -->|Custom| CustomSelect[Interactive Selection]
-
- GetFullCats --> ShowPlan[Show Restore Plan]
- GetStorageCats --> ShowPlan
- GetBaseCats --> ShowPlan
- CustomSelect --> ShowPlan
-
- ShowPlan --> Confirm{Type RESTORE?}
- Confirm -->|No| Abort
- Confirm -->|Yes| ConfirmOverwrite{Confirm overwrite?}
- ConfirmOverwrite -->|No| Abort
- ConfirmOverwrite -->|Yes| SafetyBackup[Create Safety Backup]
-
- SafetyBackup --> SafetyOK{Success?}
- SafetyOK -->|No| AskContinue{Continue anyway?}
- AskContinue -->|No| Abort
- AskContinue -->|Yes| CheckCluster
- SafetyOK -->|Yes| CheckCluster{Cluster Restore?}
-
- CheckCluster -->|Yes| StopServices["Stop pve-ha-lrm, pve-ha-crm,
then PVE Services"]
- StopServices --> UnmountPVE[Unmount /etc/pve]
- UnmountPVE --> DeferRestart["Arm fallback restart
(runs only if the restore
ends before the early restart)"]
- DeferRestart --> ZFSHostFiles
-
- CheckCluster -->|No| ZFSHostFiles["ZFS host files check (zfs or services selected):
keep this host's /etc/hostid and
pool cache when it has pools imported,
and its own zfs.conf ARC limit"]
- ZFSHostFiles --> ExtractNormal["Extract Normal Categories
(the old host's GRUB settings,
kernel cmdline, ESP list: never)"]
- ExtractNormal --> RestartPVE["Cluster RECOVERY only: restart
pve-cluster, pvedaemon, pveproxy,
pvestatd, then pve-ha-crm, pve-ha-lrm"]
- RestartPVE --> ExtractExport{Export Categories?}
- ExtractExport -->|Yes| ExtractToExport[Extract to Export Dir]
- ExtractExport -->|No| PostRestore
- ExtractToExport --> PostRestore[Post-Restore Tasks]
-
- PostRestore --> RecreateDir[Recreate Directories]
- RecreateDir --> CheckBoot{boot Category?}
- CheckBoot -->|Yes| BootMerge["Merge the old host's kernel
parameters into this host's GRUB
or /etc/kernel/cmdline, then rebuild
initramfs + bootloader once"]
- CheckBoot -->|No| CheckZFS
- BootMerge --> CheckZFS{ZFS Category?}
- CheckZFS -->|Yes| WarnZFS[Warn About ZFS Import]
- CheckZFS -->|No| RestartServices
- WarnZFS --> RestartServices[Restart PBS Services - Deferred]
-
- RestartServices --> DisplaySummary[Display Summary]
- DisplaySummary --> Success([Success])
-
- style Start fill:#90EE90
- style Success fill:#90EE90
- style Abort fill:#FFB6C1
- style StopServices fill:#FFD700
- style RestartServices fill:#FFD700
-```
-
----
+See [Diagram: Complete Restore Workflow](RESTORE_TECHNICAL.md#diagram-complete-restore-workflow).
## Category Decision Tree
-```mermaid
-flowchart TD
- Start([Select Restore Mode]) --> Mode{Which Mode?}
-
- Mode -->|1. FULL| Full[FULL Mode]
- Mode -->|2. STORAGE| Storage[STORAGE Mode]
- Mode -->|3. BASE| Base[BASE Mode]
- Mode -->|4. CUSTOM| Custom[CUSTOM Mode]
-
- Full --> SystemFull{System Type?}
- SystemFull -->|PVE| PVEFull[PVE Categories:
- pve_cluster
- storage_pve
- pve_jobs
- pve_notifications
- pve_access_control
- pve_firewall
- pve_ha
- pve_sdn
- corosync
- ceph
+ Common]
- SystemFull -->|PBS| PBSFull[PBS Categories:
- pbs_host
- datastore_pbs
- maintenance_pbs
- pbs_jobs
- pbs_remotes
- pbs_notifications
- pbs_access_control
- pbs_tape
+ Common]
- SystemFull -->|DUAL| DualFull[Dual Categories:
- PVE categories
- PBS categories
- Common categories]
- SystemFull -->|Unknown| CommonFull[Common Only:
- filesystem
- storage_stack
- network
- ssl
- ssh
- scripts
- crontabs
- services
- accounts
- user_data
- zfs
- boot
- proxsave_info]
-
- Storage --> SystemStorage{System Type?}
- SystemStorage -->|PVE| PVEStorage[- pve_cluster
- storage_pve
- pve_jobs
- filesystem
- storage_stack
- zfs]
- SystemStorage -->|PBS| PBSStorage[- datastore_pbs
- maintenance_pbs
- pbs_jobs
- pbs_remotes
- filesystem
- storage_stack
- zfs]
- SystemStorage -->|DUAL| DualStorage[- PVE storage categories
- PBS storage categories
- filesystem
- storage_stack
- zfs]
-
- Base --> BaseCats[- network
- ssl
- ssh
- services
- filesystem]
-
- Custom --> CheckboxMenu[Interactive Menu]
- CheckboxMenu --> ToggleLoop{Toggle Categories}
- ToggleLoop -->|Number| Toggle[Toggle Category]
- Toggle --> ToggleLoop
- ToggleLoop -->|'a'| SelectAll[Select All]
- SelectAll --> ToggleLoop
- ToggleLoop -->|'n'| DeselectAll[Deselect All]
- DeselectAll --> ToggleLoop
- ToggleLoop -->|'c'| CustomSelected[User Selection]
- ToggleLoop -->|'0'| Cancel([Cancel])
-
- PVEFull --> FilterExport[Filter Export-Only]
- PBSFull --> FilterExport
- CommonFull --> FilterExport
- PVEStorage --> FilterExport
- PBSStorage --> FilterExport
- BaseCats --> FilterExport
- CustomSelected --> NoFilter[Include Export if Selected]
-
- FilterExport --> Split[Split: Normal vs Export]
- NoFilter --> Split
- Split --> Result([Selected Categories])
-
- style Start fill:#90EE90
- style Result fill:#90EE90
- style Cancel fill:#FFB6C1
- style Custom fill:#87CEEB
- style CheckboxMenu fill:#87CEEB
-```
-
-**Note (PBS)**: ProxSave applies supported PBS staged categories via `proxmox-backup-manager` by default. In **Clean 1:1** mode it may fall back to writing staged `*.cfg` files back to `/etc/proxmox-backup` when API apply is unavailable or fails.
-
----
+See [Diagram: Category Decision Tree](RESTORE_TECHNICAL.md#diagram-category-decision-tree).
## Service Management Flow
-```mermaid
-sequenceDiagram
- participant User
- participant Restore
- participant Services
- participant FS as Filesystem
- participant DB as config.db
-
- User->>Restore: Start restore with pve_cluster, choose RECOVERY
- Restore->>Services: pvecm status (only with corosync.conf present)
- Services-->>Restore: Quorate with more than 1 node online: refused, run stops
- Services-->>Restore: Otherwise (1 node, not quorate, unreadable): proceed
- Restore->>Restore: Detect needsClusterRestore = true
-
- Note over Restore,Services: Service Stop Phase
- Restore->>Services: systemctl stop --no-block pve-ha-lrm (wait up to 180 s, never killed)
- Services-->>Restore: Stopped (HA resources frozen, watchdog closed)
- Restore->>Services: systemctl stop pve-ha-crm
- Services-->>Restore: Stopped (CRM lock released)
- Restore->>Services: systemctl stop pve-cluster
- Services->>FS: Unmount /etc/pve (FUSE)
- Services->>DB: Close file handles
- Services-->>Restore: Stopped
-
- Restore->>Services: systemctl stop pvedaemon
- Services-->>Restore: Stopped
- Restore->>Services: systemctl stop pveproxy
- Services-->>Restore: Stopped
- Restore->>Services: systemctl stop pvestatd
- Services-->>Restore: Stopped
-
- Note over Restore,FS: Unmount Phase
- Restore->>FS: umount /etc/pve
- FS-->>Restore: Unmounted (or already unmounted)
-
- Note over Restore: Arm fallback restart (defer), used only if the run ends before the restart below
-
- Note over Restore,DB: Restore Phase
- Restore->>DB: Extract /var/lib/pve-cluster/
- Restore->>DB: Extract config.db
- DB-->>Restore: Files restored
-
- Note over Restore,Services: Restart right after the extraction
- Restore->>Services: systemctl start pve-cluster
- Services->>DB: Open config.db
- Services->>FS: Mount /etc/pve (FUSE)
- Services-->>Restore: Started
-
- Restore->>Services: systemctl start pvedaemon
- Services->>FS: Read /etc/pve config
- Services-->>Restore: Started
-
- Restore->>Services: systemctl start pveproxy
- Services-->>Restore: Started
-
- Restore->>Services: systemctl start pvestatd
- Services-->>Restore: Started
-
- Restore->>Services: systemctl start pve-ha-crm
- Services-->>Restore: Started
- Restore->>Services: systemctl start pve-ha-lrm
- Services-->>Restore: Started (HA resources resumed)
-
- Note over Restore,Services: Later steps (network apply with PVE health checks, boot rebuild)
-
- Restore-->>User: Restore Complete
-
- Note over User,Services: Verification Phase
- User->>Services: pvecm status
- Services->>DB: Query cluster state
- Services-->>User: Quorate
- User->>FS: ls /etc/pve/
- FS->>DB: Query via pmxcfs
- FS-->>User: Config files visible
-```
-
----
+See [Diagram: Service Management Flow](RESTORE_TECHNICAL.md#diagram-service-management-flow).
## Three-Tier Extraction
-`splitRestoreCategories` divides the selected categories into three tiers. Normal
-categories go straight to `/`, export-only categories go to a read-only export
-directory, and staged (sensitive) categories are extracted strictly into a stage
-directory and then applied (Phase 10). If any staged entry fails, the staged apply is
-skipped and the live system is left untouched (BH-002).
-
-```mermaid
-flowchart LR
- subgraph Input
- Archive[backup archive]
- end
-
- subgraph "Tier 1: Normal categories"
- Filter1{Matches a
Normal category?}
- Extract1[Extract to /]
- end
-
- subgraph "Tier 2: Export-only categories"
- Filter2{Matches an
Export-only category?}
- Extract2[Extract to
Export Dir, read-only]
- end
-
- subgraph "Tier 3: Staged (sensitive) categories"
- Filter3{Matches a
Staged category?}
- Stage3[Extract to
stage dir, strict]
- Apply3[Staged apply
PBS/PVE/SDN/ACL/accounts/notify]
- end
-
- subgraph Output
- SystemRoot[System Root /
- /var/lib/pve-cluster/
- /etc/network/
- etc.]
- ExportDir[Export Directory
BASE_DIR/proxmox-config-export-TIMESTAMP/
- etc/pve/storage.cfg
- etc.]
- Live[Live config applied
atomically, or skipped on
any staged failure - BH-002]
- end
-
- Archive --> Filter1
- Filter1 -->|Yes| Extract1 --> SystemRoot
-
- Archive --> Filter2
- Filter2 -->|Yes| Extract2 --> ExportDir
-
- Archive --> Filter3
- Filter3 -->|Yes| Stage3 --> Apply3 --> Live
-
- style Archive fill:#87CEEB
- style SystemRoot fill:#90EE90
- style ExportDir fill:#FFD700
- style Live fill:#FFA500
-```
-
----
+See [Diagram: Three-Tier Extraction](RESTORE_TECHNICAL.md#diagram-three-tier-extraction).
## Cluster Database Restore Sequence
-```mermaid
-stateDiagram-v2
- [*] --> Running: Initial State
-
- state Running {
- [*] --> ServicesActive
- ServicesActive: pve-cluster: active
- ServicesActive: pvedaemon: active
- ServicesActive: pveproxy: active
- ServicesActive: /etc/pve: mounted
- }
-
- Running --> Stopping: User initiates restore
-
- state Stopping {
- [*] --> StopLRM
- StopLRM: systemctl stop --no-block pve-ha-lrm (up to 180 s, never killed)
- StopLRM --> StopCRM
- StopCRM: systemctl stop pve-ha-crm
- StopCRM --> StopCluster
- StopCluster: systemctl stop pve-cluster
- StopCluster --> StopDaemon
- StopDaemon: systemctl stop pvedaemon
- StopDaemon --> StopProxy
- StopProxy: systemctl stop pveproxy
- StopProxy --> StopStatd
- StopStatd: systemctl stop pvestatd
- StopStatd --> UnmountPVE
- UnmountPVE: umount /etc/pve
- UnmountPVE --> [*]
- }
-
- Stopping --> Stopped: All services stopped
-
- state Stopped {
- [*] --> ServicesStopped
- ServicesStopped: All services: inactive
- ServicesStopped: /etc/pve: unmounted
- ServicesStopped: config.db: not in use
- }
-
- Stopped --> Restoring: Extract files
-
- state Restoring {
- [*] --> ExtractDB
- ExtractDB: Extract /var/lib/pve-cluster/
- ExtractDB --> WriteFiles
- WriteFiles: Write config.db
- WriteFiles: Write supporting files
- WriteFiles --> [*]
- }
-
- Restoring --> Restarting: Files restored
-
- state Restarting {
- [*] --> StartCluster
- StartCluster: systemctl start pve-cluster
- StartCluster --> ReadDB
- ReadDB: pmxcfs reads config.db
- ReadDB --> MountPVE
- MountPVE: Mount /etc/pve (FUSE)
- MountPVE --> StartDaemon
- StartDaemon: systemctl start pvedaemon
- StartDaemon --> StartProxy
- StartProxy: systemctl start pveproxy
- StartProxy --> StartStatd
- StartStatd: systemctl start pvestatd
- StartStatd --> StartCRM
- StartCRM: systemctl start pve-ha-crm
- StartCRM --> StartLRM
- StartLRM: systemctl start pve-ha-lrm
- StartLRM --> [*]
- }
-
- Restarting --> Restored: Services restarted right after the extraction
-
- state Restored {
- [*] --> ServicesRestored
- ServicesRestored: All services: active
- ServicesRestored: /etc/pve: mounted with RESTORED config
- ServicesRestored: Cluster: operational
- }
-
- Restored --> [*]: Restore complete
-```
-
----
+See [Diagram: Cluster Database Restore Sequence](RESTORE_TECHNICAL.md#diagram-cluster-database-restore-sequence).
## Error Handling Flow
-```mermaid
-flowchart TD
- Start([Operation]) --> Operation{Operation Type}
-
- Operation -->|User Action| UserAbort{User Cancels?}
- UserAbort -->|Yes| ReturnAbort[Return ErrRestoreAborted]
- UserAbort -->|No| Continue[Continue]
-
- Operation -->|Service Stop| ServiceStop[Stop Service]
- ServiceStop --> StopResult{Success?}
- StopResult -->|No| FailFast[FAIL-FAST: Abort Restore]
- StopResult -->|Yes| Continue
-
- Operation -->|Safety Backup| CreateBackup[Create Safety Backup]
- CreateBackup --> BackupResult{Success?}
- BackupResult -->|No| AskUser{Ask User Continue?}
- AskUser -->|No| ReturnAbort
- AskUser -->|Yes| Continue
- BackupResult -->|Yes| Continue
-
- Operation -->|File Extract| ExtractFile[Extract File]
- ExtractFile --> ExtractResult{Success?}
- ExtractResult -->|No| LogWarning[Log Warning, Increment Failed]
- ExtractResult -->|Yes| Continue
- LogWarning --> ContinueLoop[Continue to Next File]
-
- Operation -->|Service Restart| RestartService[Restart Service - Deferred]
- RestartService --> RestartResult{Success?}
- RestartResult -->|No| WarnOnly[Log Warning Only]
- RestartResult -->|Yes| Continue
- WarnOnly --> ContinueFinal[Continue Anyway]
-
- Operation -->|Unmount| UnmountFS[Unmount /etc/pve]
- UnmountFS --> UnmountResult{Success?}
- UnmountResult -->|No| WarnContinue[Log Warning, Continue]
- UnmountResult -->|Yes| Continue
- WarnContinue --> Continue
-
- FailFast --> Abort([Abort Restore])
- ReturnAbort --> Abort
- Continue --> Success([Success])
- ContinueLoop --> Success
- ContinueFinal --> Success
-
- style Start fill:#87CEEB
- style Success fill:#90EE90
- style Abort fill:#FFB6C1
- style FailFast fill:#FF6347
- style LogWarning fill:#FFD700
- style WarnOnly fill:#FFD700
- style WarnContinue fill:#FFD700
-```
-
----
+See [Diagram: Error Handling Flow](RESTORE_TECHNICAL.md#diagram-error-handling-flow).
## Path Matching Algorithm
-```mermaid
-flowchart TD
- Start([Archive Entry]) --> GetName[Get Entry Name]
- GetName --> Normalize{Starts with ./ ?}
- Normalize -->|No| AddPrefix["Prepend './'"]
- Normalize -->|Yes| LoopCats[For Each Category]
- AddPrefix --> LoopCats
-
- LoopCats --> LoopPaths[For Each Category Path]
- LoopPaths --> CheckExact{Exact Match?}
- CheckExact -->|Yes| Match([MATCH])
- CheckExact -->|No| CheckDir{Path Ends with / ?}
-
- CheckDir -->|No| NextPath[Next Path]
- CheckDir -->|Yes| CheckPrefix{Entry Starts with Path?}
- CheckPrefix -->|Yes| Match
- CheckPrefix -->|No| CheckParent{Entry == Path without / ?}
- CheckParent -->|Yes| Match
- CheckParent -->|No| NextPath
-
- NextPath --> MorePaths{More Paths?}
- MorePaths -->|Yes| LoopPaths
- MorePaths -->|No| NextCat[Next Category]
- NextCat --> MoreCats{More Categories?}
- MoreCats -->|Yes| LoopCats
- MoreCats -->|No| NoMatch([NO MATCH])
-
- style Start fill:#87CEEB
- style Match fill:#90EE90
- style NoMatch fill:#FFB6C1
-```
-
-**Examples**:
-
-| Archive Entry | Category Path | Result |
-|--------------|---------------|--------|
-| `./etc/network/interfaces` | `./etc/network/` | ✅ Prefix match |
-| `./etc/hostname` | `./etc/network/` | ❌ No match |
-| `etc/hostname` | `./etc/hostname` | ✅ After normalize |
-| `./var/lib/pve-cluster/config.db` | `./var/lib/pve-cluster/` | ✅ Prefix match |
-
----
+See [Diagram: Path Matching Algorithm](RESTORE_TECHNICAL.md#diagram-path-matching-algorithm).
## Category Type Filter
-```mermaid
-flowchart TD
- Start([All Categories]) --> CheckSystem{System Type?}
-
- CheckSystem -->|PVE| FilterPVE[Filter Categories]
- CheckSystem -->|PBS| FilterPBS[Filter Categories]
- CheckSystem -->|DUAL| FilterDual[Filter Categories]
- CheckSystem -->|Unknown| FilterCommon[Filter Categories]
-
- FilterPVE --> IncludePVE["Include:
- CategoryTypePVE
- CategoryTypeCommon"]
- FilterPBS --> IncludePBS["Include:
- CategoryTypePBS
- CategoryTypeCommon"]
- FilterDual --> IncludeDual["Include:
- CategoryTypePVE
- CategoryTypePBS
- CategoryTypeCommon"]
- FilterCommon --> IncludeOnlyCommon["Include:
- CategoryTypeCommon only"]
-
- IncludePVE --> CheckMode{Restore Mode?}
- IncludePBS --> CheckMode
- IncludeDual --> CheckMode
- IncludeOnlyCommon --> CheckMode
-
- CheckMode -->|Full/Storage/Base| RemoveExport[Remove ExportOnly = true]
- CheckMode -->|Custom| KeepAll[Keep All - User Choice]
-
- RemoveExport --> Available{In Archive?}
- KeepAll --> Available
-
- Available --> CheckAvailable[Check IsAvailable]
- CheckAvailable --> Result([Final Category List])
-
- style Start fill:#87CEEB
- style Result fill:#90EE90
-```
-
----
+See [Diagram: Category Type Filter](RESTORE_TECHNICAL.md#diagram-category-type-filter).
## Safety Backup Process
-```mermaid
-flowchart TD
- Start([Categories Selected]) --> CreatePath[Create /opt/proxsave/restore/TIMESTAMP/]
- CreatePath --> CreateArchive[Create restore_backup_TIMESTAMP.tar.gz]
- CreateArchive --> LoopCats[For Each Category]
-
- LoopCats --> LoopPaths[For Each Path in Category]
- LoopPaths --> BuildFull["Build Full Path:
/ + path"]
- BuildFull --> CheckExists{Path Exists?}
-
- CheckExists -->|No| NextPath[Next Path]
- CheckExists -->|Yes| CheckType{Type?}
-
- CheckType -->|File| BackupFile[Add File to TAR]
- CheckType -->|Directory| WalkDir[Walk Directory Recursively]
-
- WalkDir --> BackupTree[Add All Files/Dirs to TAR]
- BackupTree --> NextPath
- BackupFile --> NextPath
-
- NextPath --> MorePaths{More Paths?}
- MorePaths -->|Yes| LoopPaths
- MorePaths -->|No| NextCat[Next Category]
-
- NextCat --> MoreCats{More Categories?}
- MoreCats -->|Yes| LoopCats
- MoreCats -->|No| CloseTar[Close TAR Archive]
-
- CloseTar --> Success([Safety Backup Created])
- Success --> DisplayPath["Display:
/opt/proxsave/restore/TIMESTAMP/restore_backup_TIMESTAMP.tar.gz"]
- DisplayPath --> Rollback["Show Rollback Command:
tar -xzf backup.tar.gz -C /"]
-
- style Start fill:#87CEEB
- style Success fill:#90EE90
- style DisplayPath fill:#FFD700
-```
-
----
+See [Diagram: Safety Backup Process](RESTORE_TECHNICAL.md#diagram-safety-backup-process).
## Decryption Workflow
-```mermaid
-flowchart TD
- Start([Backup Selected]) --> ReadManifest[Read Manifest]
- ReadManifest --> CheckEnc{EncryptionMode?}
-
- CheckEnc -->|"none"| Plain[Use Archive Directly]
- CheckEnc -->|"age"| GetSecret[Prompt: AGE key or passphrase
single field, 0 = exit]
-
- GetSecret -->|"0 = exit"| Abort([Abort])
- GetSecret --> PrepareTemp[Prepare /tmp/proxsave/proxmox-decrypt-XXXX/]
-
- PrepareTemp --> Decrypt[Run AGE Decrypt]
- Decrypt --> DecryptResult{Success?}
-
- DecryptResult -->|No| RetryPrompt{Retry?}
- RetryPrompt -->|Yes| GetSecret
- RetryPrompt -->|No| Abort
-
- DecryptResult -->|Yes| ChecksumCheck{Checksum Available?}
- ChecksumCheck -->|No| WarnNoCheck[Warn: No Checksum]
- ChecksumCheck -->|Yes| VerifySum[Calculate SHA256]
-
- VerifySum --> CompareSum{Match?}
- CompareSum -->|No| ChecksumFail[Error: Checksum Mismatch]
- CompareSum -->|Yes| Success
-
- ChecksumFail --> Abort
- WarnNoCheck --> Success([Decrypted Archive Ready])
- Plain --> Success
-
- Success --> DeferCleanup["Schedule Cleanup
(remove temp files on exit)"]
-
- style Start fill:#87CEEB
- style Success fill:#90EE90
- style Abort fill:#FFB6C1
- style ChecksumFail fill:#FF6347
-```
-
----
+See [Diagram: Decryption Workflow](RESTORE_TECHNICAL.md#diagram-decryption-workflow).
## Storage Directory Recreation
-```mermaid
-flowchart TD
- Start([Post-Restore]) --> CheckSystem{System Type?}
-
- CheckSystem -->|PVE| CheckPVECat{storage_pve
Restored?}
- CheckSystem -->|PBS| CheckPBSCat{datastore_pbs
Restored?}
- CheckSystem -->|Unknown| Skip([Skip])
-
- CheckPVECat -->|No| Skip
- CheckPVECat -->|Yes| ParsePVE[Parse /etc/pve/storage.cfg]
-
- CheckPBSCat -->|No| Skip
- CheckPBSCat -->|Yes| ParsePBS[Parse /etc/proxmox-backup/datastore.cfg]
-
- ParsePVE --> LoopPVE[For Each Storage]
- LoopPVE --> CheckPVEMount{"Unmounted ZFS/
dedicated mount?
(resolves to rootfs)"}
-
- CheckPVEMount -->|Yes| WarnPVEMount["Warn: Don't create
(mount disk / import pool first)"]
- CheckPVEMount -->|No| CheckPVEType{Storage Type?}
-
- CheckPVEType -->|dir| CreateDirStruct["Create:
- dump/
- images/
- template/
- snippets/
- private/"]
- CheckPVEType -->|nfs/cifs| CreateNFSStruct["Create:
- dump/
- images/
- template/"]
- CheckPVEType -->|Other| NextPVE[Next Storage]
-
- CreateDirStruct --> NextPVE
- CreateNFSStruct --> NextPVE
- WarnPVEMount --> NextPVE
- NextPVE --> MorePVE{More Storage?}
- MorePVE -->|Yes| LoopPVE
- MorePVE -->|No| Done([Done])
-
- ParsePBS --> LoopPBS[For Each Datastore]
- LoopPBS --> CheckZFSMount{Likely ZFS Mount?}
-
- CheckZFSMount -->|Yes| WarnZFS["Warn: Don't create
(would block mount)"]
- CheckZFSMount -->|No| CreatePBSStruct["Create:
- .chunks/
- .lock/"]
-
- WarnZFS --> LogOwner["Log: Should be
backup:backup"]
- CreatePBSStruct --> LogOwner
- LogOwner --> NextPBS[Next Datastore]
-
- NextPBS --> MorePBS{More Datastores?}
- MorePBS -->|Yes| LoopPBS
- MorePBS -->|No| CheckZFSCat{zfs Category
Restored?}
-
- CheckZFSCat -->|Yes| WarnZFSImport["Info: ZFS pools
importable, not imported"]
- CheckZFSCat -->|No| Done
- WarnZFSImport --> DisplayCmds["Display:
zpool import
zpool import pool-name"]
- DisplayCmds --> Done
-
- style Start fill:#87CEEB
- style Done fill:#90EE90
- style Skip fill:#D3D3D3
-```
-
----
+See [Diagram: Storage Directory Recreation](RESTORE_TECHNICAL.md#diagram-storage-directory-recreation).
## Compatibility Validation
-```mermaid
-flowchart TD
- Start([Backup Prepared]) --> DetectCurrent[Detect Current System]
- DetectCurrent --> CheckSystem{PVE indicators?
PBS indicators?}
-
- CheckSystem -->|PVE only| CurrentPVE[Current: PVE]
- CheckSystem -->|PBS only| CurrentPBS[Current: PBS]
- CheckSystem -->|Both| CurrentDual[Current: DUAL]
- CheckSystem -->|Neither| CurrentUnknown[Current: Unknown]
-
- CurrentPVE --> ReadManifest
- CurrentPBS --> ReadManifest
- CurrentDual --> ReadManifest
- CurrentUnknown --> ReadManifest[Read Backup Manifest]
-
- ReadManifest --> CheckBackupType{manifest.ProxmoxTargets
or ProxmoxType
or hostname pattern}
- CheckBackupType -->|pve| BackupPVE[Backup: PVE]
- CheckBackupType -->|pbs| BackupPBS[Backup: PBS]
- CheckBackupType -->|dual| BackupDual[Backup: DUAL]
- CheckBackupType -->|Unknown| BackupUnknown[Backup: Unknown]
-
- BackupPVE --> Compare
- BackupPBS --> Compare
- BackupDual --> Compare
- BackupUnknown --> Compare[Compare Capability Sets]
-
- Compare --> SharedRole{Any shared role?}
- SharedRole -->|Yes| ExactMatch{Same role set?}
- ExactMatch -->|Yes| Compatible([Full Compatibility])
- ExactMatch -->|No| Partial[Partial Compatibility]
- Partial --> Filter["Warn user and filter to
supported categories"]
- Filter --> ProceedAnyway([Proceed with Warning])
-
- SharedRole -->|No| CheckUnknown{Either side unknown?}
- CheckUnknown -->|Yes| WarnUnknown["Warn: compatibility
cannot be fully verified"]
- WarnUnknown --> Proceed([Proceed])
- CheckUnknown -->|No| Incompatible["No overlapping role"]
-
- Incompatible --> DisplayWarning["Display Warning:
backup and host roles differ"]
- DisplayWarning --> AskOverride{Type 'yes'
to continue?}
-
- AskOverride -->|No| Abort([Abort])
- AskOverride -->|Yes| ProceedAnyway
-
- Compatible --> Proceed
-
- style Start fill:#87CEEB
- style Proceed fill:#90EE90
- style ProceedAnyway fill:#FFD700
- style Abort fill:#FFB6C1
-```
-
----
+See [Diagram: Compatibility Validation](RESTORE_TECHNICAL.md#diagram-compatibility-validation).
## PBS Datastore Mount Guards
-When restoring PBS configuration, a datastore's backing mount may be **offline**
-(not yet mounted). Without protection, restoring the datastore layout, or PBS
-starting afterwards, would write into the empty mount-point directory on the
-**root filesystem**, filling `/` and creating a "ghost" datastore. The mount
-guard blocks that path until the real storage is back.
-
-```mermaid
-flowchart TD
- Start([Apply PBS datastore guards
Clean 1:1 restore]) --> Each{For each staged
datastore mount target}
- Each --> Valid{In fstab + valid target?}
- Valid -->|No| Skip[Leave unguarded]
- Valid -->|Yes| Root{Mount-point dir on the ROOT
filesystem? i.e. real mount offline}
- Root -->|No, real mount present| NoOp[No-op]
- Root -->|Yes| Try{Real storage mounts now?}
- Try -->|Yes| NoOp
- Try -->|No| Bind[Bind-mount empty read-only guard dir
RO + nodev + nosuid + noexec]
- Bind -->|success| Guarded[Path guarded:
writes cannot land on root FS]
- Bind -->|bind unavailable| Warn[Warn-only: log that the mountpoint
is unguarded; no persistent flag set]
-
- style Start fill:#87CEEB
- style Guarded fill:#90EE90
- style NoOp fill:#90EE90
- style Warn fill:#FFD700
- style Skip fill:#FFB6C1
-```
-
-**Auto-restore (shadowing)**: when the real datastore mount comes back online it
-stacks **on top of** the guard (overlay), so the datastore is usable again, but
-the guard is only **shadowed**, not removed.
-
-**Warn-only fallback**: if the read-only bind mount cannot be created, ProxSave logs
-a warning and proceeds **without** a persistent guard. Older versions set a
-`chattr +i` immutable flag here; it survived reboots and could silently re-block the
-mountpoint once the storage was later unmounted, so it was removed.
-
-**Cleanup** (dashboard **Recovery > Cleanup guards**, or `proxsave --cleanup-guards`
-on a headless host):
-- bind-mount guards are unmounted (they also disappear on reboot);
-- **legacy** `chattr +i` immutable flags (from older versions) are cleared, but
- **skipped while the target is masked by a real mount** (clearing would touch the
- mounted filesystem);
-- a summary line reports unmounted / hidden-remaining / immutable-cleared /
- immutable-pending.
-
-Code: `internal/orchestrator/mount_guard.go` (`guardMountPoint` →
-`bindReadOnlyGuard`), `mount_guard_apply.go`
-(`maybeApplyPBSDatastoreMountGuards` → `protectOfflineTarget`), and
-`guards_cleanup.go` (`CleanupMountGuards`).
-
----
+See [Diagram: PBS Datastore Mount Guards](RESTORE_TECHNICAL.md#diagram-pbs-datastore-mount-guards).
## Usage Examples
-### Viewing Diagrams
-
-**GitHub**: Mermaid diagrams render automatically in GitHub markdown.
-
-**VS Code**: Install "Markdown Preview Mermaid Support" extension.
-
-**Command Line**: Use `mermaid-cli` to generate images:
-```bash
-npm install -g @mermaid-js/mermaid-cli
-
-# Generate PNG
-mmdc -i docs/RESTORE_DIAGRAMS.md -o diagrams/
-
-# Generate SVG
-mmdc -i docs/RESTORE_DIAGRAMS.md -o diagrams/ -t svg
-```
-
-**Web Browser**: Copy diagram to https://mermaid.live/
-
----
+GitHub renders Mermaid diagrams in the technical guide. For local rendering instructions, see [Mermaid CLI](https://github.com/mermaid-js/mermaid-cli).
## Related Documentation
-- [RESTORE_GUIDE.md](RESTORE_GUIDE.md) - Complete user guide
-- [DASHBOARD.md](DASHBOARD.md) - The menu restore is normally started from
-- [RESTORE_TECHNICAL.md](RESTORE_TECHNICAL.md) - Technical architecture
-- [CLUSTER_RECOVERY.md](CLUSTER_RECOVERY.md) - Disaster recovery procedures
+- [Choose restore modes and categories](RESTORE_GUIDE.md#choose-restore-modes-and-categories)
+- [Recover a Proxmox cluster](CLUSTER_RECOVERY.md#recover-a-proxmox-cluster)
diff --git a/docs/RESTORE_GUIDE.md b/docs/RESTORE_GUIDE.md
index 6d4339c6..02feb0fa 100644
--- a/docs/RESTORE_GUIDE.md
+++ b/docs/RESTORE_GUIDE.md
@@ -4,12 +4,13 @@ Complete guide for restoring Proxmox VE, Proxmox Backup Server, and dual-role
PVE+PBS backups using the interactive restore workflow.
Restore is a **dashboard** action: run `proxsave` with no arguments on a terminal and
-pick **Tools > Restore**. The `--restore` flag runs the same workflow directly, and
-stays fully documented here as the path for headless hosts, rescue shells and any
-situation where the dashboard cannot open.
+pick **Tools > Restore**. Direct restore entry and terminal options for rescue shells and headless hosts are documented in [CLI reference](CLI_REFERENCE.md).
## Table of Contents
+- [Choose restore modes and categories](#choose-restore-modes-and-categories)
+- [Restore a host](#restore-a-host)
+- [Restore IOMMU, VFIO and passthrough settings](#restore-iommu-vfio-and-passthrough-settings)
- [Quick Start](#quick-start)
- [Overview](#overview)
- [Category System](#category-system)
@@ -43,26 +44,11 @@ full menu is documented in [DASHBOARD.md](DASHBOARD.md).
The dashboard opens only when the invocation is **completely bare** (any flag, even
`--config`, skips it) and stdin and stdout are both real terminals with `TERM` set and
-not `dumb`. That is why a restore driven from cron, from a pipe, or over `ssh` without a
-TTY has to use the flag below.
+not `dumb`. Direct entry and terminal requirements are in [CLI reference](CLI_REFERENCE.md#restore-from-backup).
### Emergency, headless and recovery path: `--restore`
-```bash
-# Same workflow, entered directly (launches the TUI by default)
-proxsave --restore
-
-# Force the classic text prompts instead of the TUI
-proxsave --restore --cli
-```
-
-Use the flag when the dashboard is not available or not wanted:
-
-- a broken or freshly reinstalled host where you want to skip straight to the workflow
-- a serial or `dumb` terminal, or `ssh` without a TTY (the workflow falls back to the
- text prompts automatically, exactly as `--cli` would)
-- a rescue shell or a console session with a limited terminal
-- a restore that needs a non-default `--config` path, since any flag skips the menu
+If the dashboard cannot open, use the interactive restore entry and terminal options in [CLI reference](CLI_REFERENCE.md). A text prompt still needs operator answers; it is not unattended recovery.
### The steps, either way
@@ -82,16 +68,118 @@ Use the flag when the dashboard is not available or not wanted:
- **Sufficient disk space**: For decryption and safety backups
- **Service availability**: Target system services must be accessible
- **Network isolation**: For cluster restores, node should be isolated
-- **A real terminal**: For the dashboard. Without one, use `proxsave --restore`
+- **A real terminal**: For the dashboard. Without one, use the [direct restore entry](CLI_REFERENCE.md#restore-from-backup), which still requires answers
---
+
+
+
+
+
+
+## Choose restore modes and categories
+
+Choose a restore scope before accepting any overwrite. ProxSave restores host configuration from a complete backup set or bundle. It does not restore VM/CT disks, PBS chunks, partitions or filesystem contents outside the backed-up paths, and it does not format disks or import ZFS pools. Recover workload data through its own backup system.
+
+### Prepare the selection
+
+Run `proxsave` without arguments as root on an interactive console and choose **Tools > Restore**. Select the source location, choose the complete backup and supply its AGE key or passphrase if encrypted. Keep the archive and required sidecars together; if a cloud scan is empty, check the selected directory because scanning is non-recursive. ProxSave verifies the stored archive before decryption and analyzes which categories actually contain files. A missing key cannot be replaced by generating a new one.
+
+Restore compares the backup's roles with the destination: PVE, PBS, dual or unknown. Matching roles permit their categories. A partial match filters live restores to shared roles; incompatible product configuration is exported for review. An unknown role produces a warning, and a disjoint known role needs explicit override. Review that warning instead of assuming an override makes the configuration compatible.
+
+### Choose a mode
+
+| Mode | Selection and limits |
+| --- | --- |
+| Full | All available compatible categories, including export-only material. Sensitive categories still use staged apply; Full does not write every archived file directly to the host. |
+| Storage | The available role-specific storage, jobs and common mount/storage categories. On PVE it can include `pve_cluster`; on PBS it includes datastore and maintenance configuration. Export-only categories are excluded. |
+| System base | Network, SSL, SSH, services and filesystem configuration. SSH covers `/root/.ssh/` and `/etc/ssh/`; `/home/` keys require `user_data`. This mode excludes `boot`, `pve_cluster` and export-only categories. |
+| Custom | The available categories you explicitly select, including export-only categories when required. Use this for a limited node-local restore or a selected sensitive apply. |
+
+Preset membership, exact category paths and role-specific differences are in [Restore Modes](#restore-modes) and the [Category System reference](#category-system). A category absent from the archive cannot be selected.
+
+### Understand where changes go
+
+Normal categories write their selected system paths. Export-only categories write a separate timestamped export directory for inspection. Staged categories first extract sensitive configuration into a private stage, then their own apply steps validate and install it through the relevant API or file workflow. Individual file replacement does not make the whole restore a transaction.
+
+The category reference covers all 33 categories. For selection, these are the important boundaries:
+
+| Area | Categories and decision |
+| --- | --- |
+| PVE database and guest exports | `pve_cluster` controls database handling; `pve_config_export` supplies exported `/etc/pve` configuration, including guest definitions when backed up. Full includes the export; Storage and System base do not. |
+| PVE live configuration | `storage_pve`, `pve_jobs`, `pve_notifications`, `pve_access_control`, `pve_firewall`, `pve_ha`, `pve_sdn` have category-specific apply paths. `corosync` and `ceph` require a reviewed cluster/storage scenario. |
+| PBS exports and integrations | `pbs_config` is export-only. `pbs_host`, `datastore_pbs`, `maintenance_pbs`, `pbs_jobs`, `pbs_remotes`, `pbs_notifications`, `pbs_access_control`, `pbs_tape` cover distinct host, datastore, job, credential and tape settings. Datastore definitions do not recover chunks. |
+| Host identity and access | `network`, `ssl`, `ssh`, `accounts`, `user_data` can alter access or identity. Account databases merge while retaining current root/system accounts; validated `/etc/sudoers` is replaced, and `/etc/sudoers.d` is excluded. Access-control categories perform their own 1:1 apply and root@pam safeguard. |
+| Mounts and drivers | `filesystem`, `storage_stack`, `zfs`, `services`, `boot` require destination disk, mount and hardware review. Boot parameters merge into the destination configuration; old boot files are exported. |
+| Scripts and diagnostics | `scripts`, `crontabs`, `proxsave_info` cover custom tools, scheduled tasks and export-only diagnostics. Inspect any restored automation before enabling it. |
+
+### Separate cluster mode from category mode
+
+When selected PVE cluster data is present, choose SAFE or RECOVERY after the scope. SAFE avoids replacing the archived database but confirmed API and pmxcfs applies mutate live configuration, potentially cluster-wide. RECOVERY overwrites the cluster database and requires an offline or isolated target. It refuses a quorate cluster with more than one online node; unreadable quorum permits continuation only when corosync is confirmed inactive or failed. Use [Recover a Proxmox cluster](CLUSTER_RECOVERY.md#recover-a-proxmox-cluster) before making this decision.
+
+### Review before accepting
+
+Check the plan's selected categories, file paths, destination roles and warnings. For guest configuration through SAFE, confirm that the exported source node and eligible batch are the ones you intend. Cluster-wide inventory must be readable and unambiguous; guests owned elsewhere or with another type are skipped, never moved. A stopped-guest file fallback requires a recognized API schema refusal, not any API error.
+
+Proceed to [Restore a host](#restore-a-host) only when those choices are correct. Both the RESTORE gate and overwrite confirmation are required. If the stage later fails, its consumers are skipped, but preceding normal extraction, fstab changes or SAFE operations may already have changed the host. Cancel before confirmation when the plan or compatibility warning is unclear. Direct entry and terminal options are in [CLI reference](CLI_REFERENCE.md#restore-from-backup).
+
+
+
+
+
+## Restore a host
+
+This procedure restores selected Proxmox and operating-system configuration after a reinstall or configuration failure. It does not restore workload disks or PBS backup chunks. Use a compatible destination and a tested backup; reserve space for a decrypted working archive, export material and persistent safety artifacts.
+
+### Prerequisites
+
+- Keep root access through a local console or IPMI. Network, firewall, HA and access-control changes can disconnect SSH or alter running workloads.
+- Install the appropriate PVE/PBS role and confirm the destination hostname, networking and storage plan. For cluster membership, hostname changes or database replacement, use the matching [cluster scenario](CLUSTER_RECOVERY.md#recover-a-proxmox-cluster) first. Never rename a live member as a recovery shortcut.
+- Retrieve the complete archive or bundle and recover its AGE key or passphrase independently. Verify that the destination can read the backup source. Do not rely on restoring credentials that are needed to retrieve or decrypt that same backup.
+- Identify which data disks, shares or ZFS pools are already mounted/imported and which are offline. ProxSave neither formats disks nor imports pools. Have a separate recovery plan for VM disks and PBS chunks.
+
+### Run and review
+
+1. Run `proxsave` without arguments as root on the console and choose **Tools > Restore**. For a console where the dashboard cannot open, follow [CLI restore entry](CLI_REFERENCE.md#restore-from-backup); text prompts still require answers.
+2. Select the source and complete backup. For cloud storage, choose the directory containing the backup, because discovery is non-recursive. Supply the AGE key or passphrase if prompted. Stop on a failed integrity check or missing credential.
+3. Choose the scope using [Choose restore modes and categories](#choose-restore-modes-and-categories). On a live replacement cluster member, use Custom and keep `pve_cluster` unselected; do not accept Full as a substitute for a deliberately limited plan.
+4. If cluster payload is selected, decide SAFE or RECOVERY with the canonical cluster runbook. SAFE changes confirmed live configuration; RECOVERY manages database replacement only after its quorum and isolation guards. Do not proceed after a refused guard.
+5. Review all categories, paths and warnings, then accept the RESTORE gate and separate overwrite confirmation. A successful safety backup is the preferred prerequisite for continuing. If creating it fails, cancel and correct space/permissions rather than assuming the restore can undo later changes.
+
+### Follow the apply decisions
+
+ProxSave extracts normal categories, exports protected categories and applies staged sensitive configuration. A failed or incomplete stage is discarded and its consumers are skipped, including later network installation, firewall, HA and notification repair. This does not undo changes from earlier normal extraction, filesystem merge or SAFE apply. Read the resulting per-category warnings before retrying.
+
+The smart fstab merge proposes safe data/network mounts instead of copying the old file wholesale. Destination UUID/label references and available inventory influence device remapping. The prompt has a 90-second countdown that always answers No at expiry. A matching root/swap can make Yes the Enter-key default; it does not make the timeout accept the merge. Review each proposed mount. Details are in [Smart fstab Merge](#5-smart-etcfstab-merge-optional).
+
+Network files may be installed even if the optional live reload is skipped. A confirmed live network apply arms a 180-second rollback and needs COMMIT before the timer expires. Firewall, HA and access-control applies have their own rollback gates. Keep console access, test connectivity and inspect what each gate actually controls; these timers do not reverse every earlier restore operation. See [Network Safe Apply](#4-network-safe-apply-optional).
+
+During cluster RECOVERY, HA services stop before pmxcfs and PVE API services. The LRM receives a graceful stop and up to 180 seconds; it must never be killed to force progress because its watchdog can fence the host. PVE services restart after database extraction, before remaining restore steps. Verify quorum separately from service startup. PBS restart and staged configuration checks have their own warnings; successful extraction alone is not proof of a healthy service.
+
+Mount-backed PVE storage and PBS datastores can receive temporary read-only bind guards when the backing filesystem is offline and the path resolves to `/`. A failed guard is warning-only and leaves that path unguarded. A real mount shadows a guard; it does not remove it. Bring the correct storage online and use **Recovery > Cleanup guards**, which checks first and offers Apply only when guards are found. Legacy immutable flags can remain pending while a real mount masks their directory. Do not create a datastore layout on the root disk merely to silence an unavailable-storage warning.
+
+For boot or driver restoration, use [Restore IOMMU, VFIO and passthrough settings](#restore-iommu-vfio-and-passthrough-settings). The old host's boot files are never blindly copied over the destination boot configuration. Inspect boot rebuild warnings before rebooting.
+
+### Verify before returning to service
+
+Read the printed session and detailed restore logs, including extraction counts, stage failures and skipped applies. Retain `/restore/TIMESTAMP/` safety/rollback artifacts, normally under `/opt/proxsave/restore/`, until recovery is verified. Temporary working stages are cleaned on normal exit; the persistent safety directory is retained.
+
+Verify relevant PVE/PBS services, the mounted configuration, actual cluster membership/quorum, storage paths and the product UI/API. Check that each storage path resolves to its expected backing filesystem. Confirm SSH/network/firewall access and user permissions, then compare job schedules and notifications. Start guests only after their configuration, device assignments and disks are correct; restored definitions do not prove those resources exist.
+
+If the result reports warnings, establish which operations succeeded before repeating anything. Use [diagnose backup and restore failures](TROUBLESHOOTING.md#diagnose-backup-and-restore-failures) for logs and triage, and the [cluster verification procedure](CLUSTER_RECOVERY.md#post-recovery-verification) when applicable. Exported guest handling and application methods remain in [VM/CT Configuration Restore](#vmct-configuration-restore).
+
+### Roll back only the reviewed scope
+
+The safety archive preserves selected pre-restore files, not a complete inverse of API changes. Never extract it blindly over a running cluster database. Follow [manual rollback prerequisites](#manual-rollback-prerequisites), including verified isolation, graceful HA shutdown, pmxcfs handling and file ownership/mode requirements. Network, firewall, HA and access control have separate rollback files and scope. If those prerequisites cannot be established, stop and prepare a reviewed [support request](TROUBLESHOOTING.md#prepare-a-support-request).
+
+
+
## Overview
Restore is an **interactive, category-based restoration system** that allows selective
or full restoration of Proxmox configuration files from backup archives. It is reached
-from the dashboard (**Tools > Restore**) or, on a host where the dashboard cannot open,
-with `proxsave --restore`. Both entry points run the same workflow.
+from the dashboard (**Tools > Restore**). For consoles where the dashboard cannot open, use the direct-entry instructions in [CLI reference](CLI_REFERENCE.md#restore-from-backup).
### How to Use the Restore Docs
@@ -104,18 +192,7 @@ The restore documentation is split on purpose:
### Interactive UI: TUI by default, `--cli` for text prompts
-The restore and decrypt workflows run a **Charm TUI** by default, whether they were
-started from the dashboard or from `proxsave --restore` / `proxsave --decrypt`: a
-selector for the restore mode, a multi-select list for CUSTOM categories, and labeled
-confirmation buttons. Add **`--cli`** to force the classic text prompts and numbered
-menus instead (`--cli` works with `--install`, `--new-install`, `--newkey`,
-`--decrypt`, and `--restore`). Both paths run the same restore engine and ask the same
-questions. A `--restore` run that has no interactive terminal uses the text prompts
-automatically, without `--cli`.
-
-The numbered-menu and text transcripts throughout this guide show the `--cli`
-experience because it is the clearest to read on the page; in the default TUI the same
-steps appear as a selector, a multi-select, and buttons.
+Restore uses selectors, multi-select category lists and confirmation screens. Transcripts in the detailed examples show the equivalent text prompts. Both interfaces require operator answers. Direct entry and text-mode options are in [CLI reference](CLI_REFERENCE.md#restore-from-backup).
### Key Features
@@ -189,7 +266,7 @@ PVE + 13 Common) and a **PBS host sees 22** (9 PBS + 13 Common); a `dual` host s
Each category is handled in one of three ways:
- **Normal**: extracted directly to `/` (system paths) after safety backup
-- **Staged**: extracted to `/tmp/proxsave/restore-stage-*` and then applied in a controlled way (file copy/validation or API apply: `pvesh`/`pveum` on PVE, `proxmox-backup-manager` on PBS); when staged files are written to system paths, ProxSave applies them **atomically** and enforces the final permissions/ownership (including for any created parent directories; not left to `umask`)
+- **Staged**: extracted to `/tmp/proxsave/restore-stage-*` and then applied in a controlled way (file copy/validation or API apply: `pvesh`/`pveum` on PVE, `proxmox-backup-manager` on PBS); when staged files are written to system paths, ProxSave uses **individual file replacement** (not a transaction across categories or API updates) and enforces the final permissions/ownership (including for any created parent directories; not left to `umask`)
- **Export-only**: extracted to an export directory for manual review (never written to system paths)
### PVE-Specific Categories (11 categories)
@@ -198,13 +275,13 @@ Each category is handled in one of three ways:
|----------|------|-------------|-------|
| `pve_config_export` | PVE Config Export | **Export-only** copy of /etc/pve (never written to system) | `./etc/pve/` |
| `pve_cluster` | PVE Cluster Configuration | Cluster configuration and database | `./var/lib/pve-cluster/` |
-| `storage_pve` | PVE Storage Configuration | **Staged** storage definitions (applied via API) + VZDump config | `./etc/pve/storage.cfg`
`./etc/pve/datacenter.cfg`
`./etc/vzdump.conf` |
-| `pve_jobs` | PVE Backup Jobs | **Staged** scheduled backup jobs (applied via API) | `./etc/pve/jobs.cfg`
`./etc/pve/vzdump.cron` |
-| `pve_notifications` | PVE Notifications | **Staged** notification targets and matchers (applied via API) | `./etc/pve/notifications.cfg`
`./etc/pve/priv/notifications.cfg` |
-| `pve_access_control` | PVE Access Control | **Staged** access control + secrets restored 1:1 via pmxcfs file apply (root@pam safety rail) | `./etc/pve/user.cfg`
`./etc/pve/domains.cfg` (when present)
`./etc/pve/priv/shadow.cfg`
`./etc/pve/priv/token.cfg`
`./etc/pve/priv/tfa.cfg` |
-| `pve_firewall` | PVE Firewall | **Staged** firewall rules and node host firewall (pmxcfs file apply + rollback timer) | `./etc/pve/firewall/`
`./etc/pve/nodes/*/host.fw` |
-| `pve_ha` | PVE High Availability (HA) | **Staged** HA resources/groups/rules (pmxcfs file apply + rollback timer) | `./etc/pve/ha/resources.cfg`
`./etc/pve/ha/groups.cfg`
`./etc/pve/ha/rules.cfg` |
-| `pve_sdn` | PVE SDN | **Staged** SDN definitions (pmxcfs file apply; definitions only) | `./etc/pve/sdn/`
`./etc/pve/sdn.cfg` |
+| `storage_pve` | PVE Storage Configuration | **Staged** storage definitions (applied via API) + VZDump config | `./etc/pve/storage.cfg`; `./etc/pve/datacenter.cfg`; `./etc/vzdump.conf` |
+| `pve_jobs` | PVE Backup Jobs | **Staged** scheduled backup jobs (applied via API) | `./etc/pve/jobs.cfg`; `./etc/pve/vzdump.cron` |
+| `pve_notifications` | PVE Notifications | **Staged** notification targets and matchers (applied via API) | `./etc/pve/notifications.cfg`; `./etc/pve/priv/notifications.cfg` |
+| `pve_access_control` | PVE Access Control | **Staged** access control + secrets restored 1:1 via pmxcfs file apply (root@pam safety rail) | `./etc/pve/user.cfg`; `./etc/pve/domains.cfg` (when present); `./etc/pve/priv/shadow.cfg`; `./etc/pve/priv/token.cfg`; `./etc/pve/priv/tfa.cfg` |
+| `pve_firewall` | PVE Firewall | **Staged** firewall rules and node host firewall (pmxcfs file apply + rollback timer) | `./etc/pve/firewall/`; `./etc/pve/nodes/*/host.fw` |
+| `pve_ha` | PVE High Availability (HA) | **Staged** HA resources/groups/rules (pmxcfs file apply + rollback timer) | `./etc/pve/ha/resources.cfg`; `./etc/pve/ha/groups.cfg`; `./etc/pve/ha/rules.cfg` |
+| `pve_sdn` | PVE SDN | **Staged** SDN definitions (pmxcfs file apply; definitions only) | `./etc/pve/sdn/`; `./etc/pve/sdn.cfg` |
| `corosync` | Corosync Configuration | Cluster communication settings | `./etc/corosync/` |
| `ceph` | Ceph Configuration | Ceph storage cluster config | `./etc/ceph/` |
@@ -219,32 +296,32 @@ API apply is automatic for supported PBS staged categories, and file-based fallb
| Category | Name | Description | Paths |
|----------|------|-------------|-------|
| `pbs_config` | PBS Config Export | **Export-only** copy of /etc/proxmox-backup (never written to system) | `./etc/proxmox-backup/` |
-| `pbs_host` | PBS Host & Integrations | **Staged** node settings, ACME, proxy, metric servers and traffic control (API/file apply) | `./etc/proxmox-backup/node.cfg`
`./etc/proxmox-backup/proxy.cfg`
`./etc/proxmox-backup/acme/accounts/`
`./etc/proxmox-backup/acme/plugins.cfg`
`./etc/proxmox-backup/metricserver.cfg`
`./etc/proxmox-backup/traffic-control.cfg`
`./var/lib/proxsave-info/commands/pbs/node_config.json`
`./var/lib/proxsave-info/commands/pbs/acme_accounts.json`
`./var/lib/proxsave-info/commands/pbs/acme_plugins.json`
`./var/lib/proxsave-info/commands/pbs/acme_account_*_info.json`
`./var/lib/proxsave-info/commands/pbs/acme_plugin_*_config.json`
`./var/lib/proxsave-info/commands/pbs/traffic_control.json` |
-| `datastore_pbs` | PBS Datastore Configuration | **Staged** datastore definitions (incl. S3 endpoints) (API/file apply) | `./etc/proxmox-backup/datastore.cfg`
`./etc/proxmox-backup/s3.cfg`
`./var/lib/proxsave-info/commands/pbs/datastore_list.json`
`./var/lib/proxsave-info/commands/pbs/datastore_*_status.json`
`./var/lib/proxsave-info/commands/pbs/s3_endpoints.json`
`./var/lib/proxsave-info/commands/pbs/s3_endpoint_*_buckets.json`
`./var/lib/proxsave-info/commands/pbs/pbs_datastore_inventory.json`
Note: `PBS_DATASTORE_PATH` override scan roots are inventory context only and are not recreated as datastore definitions during restore. |
+| `pbs_host` | PBS Host & Integrations | **Staged** node settings, ACME, proxy, metric servers and traffic control (API/file apply) | `./etc/proxmox-backup/node.cfg`; `./etc/proxmox-backup/proxy.cfg`; `./etc/proxmox-backup/acme/accounts/`; `./etc/proxmox-backup/acme/plugins.cfg`; `./etc/proxmox-backup/metricserver.cfg`; `./etc/proxmox-backup/traffic-control.cfg`; `./var/lib/proxsave-info/commands/pbs/node_config.json`; `./var/lib/proxsave-info/commands/pbs/acme_accounts.json`; `./var/lib/proxsave-info/commands/pbs/acme_plugins.json`; `./var/lib/proxsave-info/commands/pbs/acme_account_*_info.json`; `./var/lib/proxsave-info/commands/pbs/acme_plugin_*_config.json`; `./var/lib/proxsave-info/commands/pbs/traffic_control.json` |
+| `datastore_pbs` | PBS Datastore Configuration | **Staged** datastore definitions (incl. S3 endpoints) (API/file apply) | `./etc/proxmox-backup/datastore.cfg`; `./etc/proxmox-backup/s3.cfg`; `./var/lib/proxsave-info/commands/pbs/datastore_list.json`; `./var/lib/proxsave-info/commands/pbs/datastore_*_status.json`; `./var/lib/proxsave-info/commands/pbs/s3_endpoints.json`; `./var/lib/proxsave-info/commands/pbs/s3_endpoint_*_buckets.json`; `./var/lib/proxsave-info/commands/pbs/pbs_datastore_inventory.json`; Note: `PBS_DATASTORE_PATH` override scan roots are inventory context only and are not recreated as datastore definitions during restore. |
| `maintenance_pbs` | PBS Maintenance | Maintenance settings | `./etc/proxmox-backup/maintenance.cfg` |
-| `pbs_jobs` | PBS Jobs | **Staged** sync/verify/prune jobs (API/file apply) | `./etc/proxmox-backup/sync.cfg`
`./etc/proxmox-backup/verification.cfg`
`./etc/proxmox-backup/prune.cfg`
`./var/lib/proxsave-info/commands/pbs/sync_jobs.json`
`./var/lib/proxsave-info/commands/pbs/verification_jobs.json`
`./var/lib/proxsave-info/commands/pbs/prune_jobs.json`
`./var/lib/proxsave-info/commands/pbs/gc_jobs.json` |
-| `pbs_remotes` | PBS Remotes | **Staged** remotes for sync/verify (may include credentials) (API/file apply) | `./etc/proxmox-backup/remote.cfg`
`./var/lib/proxsave-info/commands/pbs/remote_list.json` |
-| `pbs_notifications` | PBS Notifications | **Staged** notification targets and matchers (API/file apply) | `./etc/proxmox-backup/notifications.cfg`
`./etc/proxmox-backup/notifications-priv.cfg`
`./var/lib/proxsave-info/commands/pbs/notification_targets.json`
`./var/lib/proxsave-info/commands/pbs/notification_matchers.json`
`./var/lib/proxsave-info/commands/pbs/notification_endpoints_*.json`
Note: restore rebuilds targets and matchers from the two `.cfg` files only. The `notification_*.json` listings are captured as context and are never read back during restore. |
-| `pbs_access_control` | PBS Access Control | **Staged** access control + secrets restored 1:1 (root@pam safety rail) | `./etc/proxmox-backup/user.cfg`
`./etc/proxmox-backup/domains.cfg`
`./etc/proxmox-backup/acl.cfg`
`./etc/proxmox-backup/token.cfg`
`./etc/proxmox-backup/shadow.json`
`./etc/proxmox-backup/token.shadow`
`./etc/proxmox-backup/tfa.json`
`./var/lib/proxsave-info/commands/pbs/user_list.json`
`./var/lib/proxsave-info/commands/pbs/realms_ldap.json`
`./var/lib/proxsave-info/commands/pbs/realms_ad.json`
`./var/lib/proxsave-info/commands/pbs/realms_openid.json`
`./var/lib/proxsave-info/commands/pbs/acl_list.json` |
-| `pbs_tape` | PBS Tape Backup | **Staged** tape config, jobs and encryption keys | `./etc/proxmox-backup/tape.cfg`
`./etc/proxmox-backup/tape-job.cfg`
`./etc/proxmox-backup/media-pool.cfg`
`./etc/proxmox-backup/tape-encryption-keys.json`
`./var/lib/proxsave-info/commands/pbs/tape_drives.json`
`./var/lib/proxsave-info/commands/pbs/tape_changers.json`
`./var/lib/proxsave-info/commands/pbs/tape_pools.json` |
+| `pbs_jobs` | PBS Jobs | **Staged** sync/verify/prune jobs (API/file apply) | `./etc/proxmox-backup/sync.cfg`; `./etc/proxmox-backup/verification.cfg`; `./etc/proxmox-backup/prune.cfg`; `./var/lib/proxsave-info/commands/pbs/sync_jobs.json`; `./var/lib/proxsave-info/commands/pbs/verification_jobs.json`; `./var/lib/proxsave-info/commands/pbs/prune_jobs.json`; `./var/lib/proxsave-info/commands/pbs/gc_jobs.json` |
+| `pbs_remotes` | PBS Remotes | **Staged** remotes for sync/verify (may include credentials) (API/file apply) | `./etc/proxmox-backup/remote.cfg`; `./var/lib/proxsave-info/commands/pbs/remote_list.json` |
+| `pbs_notifications` | PBS Notifications | **Staged** notification targets and matchers (API/file apply) | `./etc/proxmox-backup/notifications.cfg`; `./etc/proxmox-backup/notifications-priv.cfg`; `./var/lib/proxsave-info/commands/pbs/notification_targets.json`; `./var/lib/proxsave-info/commands/pbs/notification_matchers.json`; `./var/lib/proxsave-info/commands/pbs/notification_endpoints_*.json`; Note: restore rebuilds targets and matchers from the two `.cfg` files only. The `notification_*.json` listings are captured as context and are never read back during restore. |
+| `pbs_access_control` | PBS Access Control | **Staged** access control + secrets restored 1:1 (root@pam safety rail) | `./etc/proxmox-backup/user.cfg`; `./etc/proxmox-backup/domains.cfg`; `./etc/proxmox-backup/acl.cfg`; `./etc/proxmox-backup/token.cfg`; `./etc/proxmox-backup/shadow.json`; `./etc/proxmox-backup/token.shadow`; `./etc/proxmox-backup/tfa.json`; `./var/lib/proxsave-info/commands/pbs/user_list.json`; `./var/lib/proxsave-info/commands/pbs/realms_ldap.json`; `./var/lib/proxsave-info/commands/pbs/realms_ad.json`; `./var/lib/proxsave-info/commands/pbs/realms_openid.json`; `./var/lib/proxsave-info/commands/pbs/acl_list.json` |
+| `pbs_tape` | PBS Tape Backup | **Staged** tape config, jobs and encryption keys | `./etc/proxmox-backup/tape.cfg`; `./etc/proxmox-backup/tape-job.cfg`; `./etc/proxmox-backup/media-pool.cfg`; `./etc/proxmox-backup/tape-encryption-keys.json`; `./var/lib/proxsave-info/commands/pbs/tape_drives.json`; `./var/lib/proxsave-info/commands/pbs/tape_changers.json`; `./var/lib/proxsave-info/commands/pbs/tape_pools.json` |
### Common Categories (13 categories)
| Category | Name | Description | Paths |
|----------|------|-------------|-------|
| `filesystem` | Filesystem Configuration | Mount points and filesystems (/etc/fstab) - WARNING: Critical for boot | `./etc/fstab` |
-| `storage_stack` | Storage Stack (Mounts/Targets) | Storage stack configuration used by mounts (iSCSI/LVM/MDADM/multipath/autofs/crypttab) | `./etc/crypttab`
`./etc/iscsi/`
`./var/lib/iscsi/`
`./etc/multipath/`
`./etc/multipath.conf`
`./etc/mdadm/`
`./etc/lvm/backup/`
`./etc/lvm/archive/`
`./etc/autofs.conf`
`./etc/auto.master`
`./etc/auto.master.d/`
`./etc/auto.*`
`./etc/keys/`
`./etc/luks-keys/`
`./etc/cryptsetup-keys.d/` |
-| `network` | Network Configuration | Network interfaces and routing | `./etc/network/`
`./etc/netplan/`
`./etc/systemd/network/`
`./etc/NetworkManager/system-connections/`
`./etc/hosts`
`./etc/hostname`
`./etc/resolv.conf`
`./etc/cloud/cloud.cfg.d/99-disable-network-config.cfg`
`./etc/dnsmasq.d/lxc-vmbr1.conf` |
-| `ssl` | SSL Certificates | SSL/TLS certificates and keys | `./etc/ssl/`
`./etc/proxmox-backup/proxy.pem`
`./etc/proxmox-backup/proxy.key`
`./etc/proxmox-backup/ssl/` |
-| `ssh` | SSH Configuration | SSH keys and authorized_keys | `./root/.ssh/`
`./etc/ssh/` |
-| `scripts` | Custom Scripts | User scripts and tools | `./usr/local/bin/`
`./usr/local/sbin/` |
-| `crontabs` | Scheduled Tasks | Cron jobs and systemd timers | `./etc/cron.d/`
`./etc/crontab`
`./var/spool/cron/` |
-| `services` | System Services | Systemd service configs and related system settings. `/etc/modprobe.d/zfs.conf` is **not written** when this host has its own and it differs: the PVE installer sets `zfs_arc_max` there to 10% of the RAM it found, so the old machine's limit would cap the ARC on more RAM or take memory from the guests on less. A warning gives both values and the backup's copy goes to the export directory. A host without a `zfs.conf` gets the backup's | `./etc/systemd/system/`
`./etc/default/`
`./etc/udev/rules.d/`
`./etc/apt/`
`./etc/logrotate.d/`
`./etc/timezone`
`./etc/sysctl.conf`
`./etc/sysctl.d/`
`./etc/modprobe.d/`
`./etc/modules`
`./etc/iptables/`
`./etc/nftables.conf`
`./etc/nftables.d/` |
-| `accounts` | System Accounts & Auth (WARNING) | Local system accounts and sudo policy, applied with a **safe merge** for `passwd`/`group`/`shadow`/`gshadow` that preserves the current host root and system accounts. `/etc/sudoers` is **replaced wholesale** with the backed-up file once `visudo -c` passes, so sudo rules added since the backup are lost; `/etc/sudoers.d` is not part of the category | `./etc/passwd`
`./etc/group`
`./etc/shadow`
`./etc/gshadow`
`./etc/sudoers` |
-| `user_data` | User Data (Home Directories) | Root and user home directories (/root and /home) | `./root/`
`./home/` |
-| `zfs` | ZFS Configuration | ZFS pool cache and configs. `/etc/hostid` is **not written** when this host has ZFS pools imported under a different hostid, or when its pools cannot be listed: a pool records the hostid it was imported under, and an initramfs rebuilt with another one refuses to import it (for a root pool, the host stops at boot). A warning gives both values. With no pool imported it is written, so pools on disks moved from the old host import under their own hostid. The same rule keeps this host's `/etc/zfs/zpool.cache` and `/etc/zfs/zfs-list.cache/`: another host's cache makes `zfs-import-cache.service` fail at boot and leaves this host's data pools out (PVE brings back a pool that is a `zfspool` storage; a PBS datastore or a manually mounted pool stays out) | `./etc/zfs/`
`./etc/hostid` |
-| `boot` | Boot Configuration (Kernel Command Line) | Kernel parameters of the backed-up host (IOMMU, VFIO, ...) **merged** into this host's boot configuration, then initramfs and bootloader rebuilt; see [Kernel Command Line Merge](#11-kernel-command-line-merge-boot-category). Not in BASE or STORAGE | `./var/lib/proxsave-info/commands/system/kernel_cmdline.txt` (the source)
`./etc/default/grub`, `./etc/kernel/cmdline` (the live files the merge may write, listed so the safety backup covers them) |
-| `proxsave_info` | ProxSave Diagnostics (Export Only) | **Export-only** ProxSave command outputs and inventory reports, and the backed-up host's boot files (GRUB, kernel command line, ESP list) (never written to system) | `./var/lib/proxsave-info/`
`./manifest.json`
`./etc/default/grub`
`./etc/default/grub.d/`
`./etc/kernel/cmdline`
`./etc/kernel/proxmox-boot-uuids` |
+| `storage_stack` | Storage Stack (Mounts/Targets) | Storage stack configuration used by mounts (iSCSI/LVM/MDADM/multipath/autofs/crypttab) | `./etc/crypttab`; `./etc/iscsi/`; `./var/lib/iscsi/`; `./etc/multipath/`; `./etc/multipath.conf`; `./etc/mdadm/`; `./etc/lvm/backup/`; `./etc/lvm/archive/`; `./etc/autofs.conf`; `./etc/auto.master`; `./etc/auto.master.d/`; `./etc/auto.*`; `./etc/keys/`; `./etc/luks-keys/`; `./etc/cryptsetup-keys.d/` |
+| `network` | Network Configuration | Network interfaces and routing | `./etc/network/`; `./etc/netplan/`; `./etc/systemd/network/`; `./etc/NetworkManager/system-connections/`; `./etc/hosts`; `./etc/hostname`; `./etc/resolv.conf`; `./etc/cloud/cloud.cfg.d/99-disable-network-config.cfg`; `./etc/dnsmasq.d/lxc-vmbr1.conf` |
+| `ssl` | SSL Certificates | SSL/TLS certificates and keys | `./etc/ssl/`; `./etc/proxmox-backup/proxy.pem`; `./etc/proxmox-backup/proxy.key`; `./etc/proxmox-backup/ssl/` |
+| `ssh` | SSH Configuration | SSH keys and authorized_keys | `./root/.ssh/`; `./etc/ssh/` |
+| `scripts` | Custom Scripts | User scripts and tools | `./usr/local/bin/`; `./usr/local/sbin/` |
+| `crontabs` | Scheduled Tasks | Cron jobs and systemd timers | `./etc/cron.d/`; `./etc/crontab`; `./var/spool/cron/`; `./etc/cron.daily/`; `./etc/cron.hourly/`; `./etc/cron.weekly/`; `./etc/cron.monthly/` |
+| `services` | System Services | Systemd service configs and related system settings. `/etc/modprobe.d/zfs.conf` is **not written** when this host has its own and it differs: the PVE installer sets `zfs_arc_max` there to 10% of the RAM it found, so the old machine's limit would cap the ARC on more RAM or take memory from the guests on less. A warning gives both values and the backup's copy goes to the export directory. A host without a `zfs.conf` gets the backup's | `./etc/systemd/system/`; `./etc/default/`; `./etc/udev/rules.d/`; `./etc/apt/`; `./etc/logrotate.d/`; `./etc/timezone`; `./etc/sysctl.conf`; `./etc/sysctl.d/`; `./etc/modprobe.d/`; `./etc/modules`; `./etc/iptables/`; `./etc/nftables.conf`; `./etc/nftables.d/` |
+| `accounts` | System Accounts & Auth (WARNING) | Local system accounts and sudo policy, applied with a **safe merge** for `passwd`/`group`/`shadow`/`gshadow` that preserves the current host root and system accounts. `/etc/sudoers` is **replaced wholesale** with the backed-up file once `visudo -c` passes, so sudo rules added since the backup are lost; `/etc/sudoers.d` is not part of the category | `./etc/passwd`; `./etc/group`; `./etc/shadow`; `./etc/gshadow`; `./etc/sudoers` |
+| `user_data` | User Data (Home Directories) | Root and user home directories (/root and /home) | `./root/`; `./home/` |
+| `zfs` | ZFS Configuration | ZFS pool cache and configs. `/etc/hostid` is **not written** when this host has ZFS pools imported under a different hostid, or when its pools cannot be listed: a pool records the hostid it was imported under, and an initramfs rebuilt with another one refuses to import it (for a root pool, the host stops at boot). A warning gives both values. With no pool imported it is written, so pools on disks moved from the old host import under their own hostid. The same rule keeps this host's `/etc/zfs/zpool.cache` and `/etc/zfs/zfs-list.cache/`: another host's cache makes `zfs-import-cache.service` fail at boot and leaves this host's data pools out (PVE brings back a pool that is a `zfspool` storage; a PBS datastore or a manually mounted pool stays out) | `./etc/zfs/`; `./etc/hostid` |
+| `boot` | Boot Configuration (Kernel Command Line) | Kernel parameters of the backed-up host (IOMMU, VFIO, ...) **merged** into this host's boot configuration, then initramfs and bootloader rebuilt; see [Kernel Command Line Merge](#11-kernel-command-line-merge-boot-category). Not in BASE or STORAGE | `./var/lib/proxsave-info/commands/system/kernel_cmdline.txt` (the source); `./etc/default/grub`, `./etc/kernel/cmdline` (the live files the merge may write, listed so the safety backup covers them) |
+| `proxsave_info` | ProxSave Diagnostics (Export Only) | **Export-only** ProxSave command outputs and inventory reports, and the backed-up host's boot files (GRUB, kernel command line, ESP list) (never written to system) | `./var/lib/proxsave-info/`; `./manifest.json`; `./etc/default/grub`; `./etc/default/grub.d/`; `./etc/kernel/cmdline`; `./etc/kernel/proxmox-boot-uuids` |
### Category Availability
@@ -379,7 +456,7 @@ Select restore mode:
**Categories Included**:
- `network` - Network interfaces, hostname, routing
- `ssl` - SSL/TLS certificates
-- `ssh` - SSH daemon configuration (`/etc/ssh`) and SSH keys (root/home users)
+- `ssh` - SSH daemon configuration (`/etc/ssh`) and root SSH keys (`/root/.ssh/`); keys under `/home/` require the separate `user_data` category
- `services` - Systemd service configs and udev rules
- `filesystem` - /etc/fstab (Smart merge prompt)
@@ -403,7 +480,7 @@ Select restore mode:
**Interactive Menu**:
```text
-Available categories:
+- categories:
[1] [ ] PVE Cluster Configuration
Proxmox VE cluster configuration and database
[2] [ ] Network Configuration
@@ -429,6 +506,8 @@ Your selection: c # Continue to restore plan
---
+
+
## Complete Workflow
The restore process follows a phased workflow with safety checks at each step.
@@ -487,9 +566,9 @@ Phase 7: Restore Plan & Confirmation
└─ User types "RESTORE" to confirm
Phase 8: Safety Backup
- ├─ Create /tmp backup of files to be overwritten
+ ├─ Create persistent /restore/TIMESTAMP/ safety backup
├─ Preserve permissions, ownership, timestamps
- └─ Display rollback command
+ └─ Display retained safety archive; follow manual rollback prerequisites
Phase 9: Service Management (PVE Cluster Restore)
├─ Detect if pve_cluster category selected (RECOVERY mode)
@@ -551,7 +630,7 @@ Select the backup source:
than from its filename:
```text
-Available backups:
+- backups:
[1] 2025-11-20 14:30:52 • Host pve01 • ENCRYPTED • Tool v1.2.0 • PVE v8.2.4 (standalone)
[2] 2025-11-19 02:00:15 • Host pve01 • ENCRYPTED • Tool v1.2.0 • PVE v8.2.4 (standalone)
[0] Exit
@@ -583,12 +662,12 @@ Checksum verified successfully.
```text
Current system type: Proxmox Virtual Environment (PVE)
Backup system type: Proxmox Virtual Environment (PVE)
-✓ Systems are compatible
+Yes Systems are compatible
```
**Partial-compatibility warning**:
```text
-⚠ WARNING: Partial compatibility detected
+Warning: WARNING: Partial compatibility detected
Current system: Proxmox Virtual Environment (PVE)
Backup source: Proxmox VE + Proxmox Backup Server (DUAL)
@@ -600,7 +679,7 @@ ProxSave will continue with the categories compatible with the current host:
**Incompatibility warning**:
```text
-⚠ WARNING: Potential incompatibility detected!
+Warning: WARNING: Potential incompatibility detected!
Current system: Proxmox Backup Server (PBS)
Backup source: Proxmox Virtual Environment (PVE)
@@ -692,7 +771,7 @@ Categories to restore:
• /etc/zfs/
• /etc/hostid
-⚠ WARNING:
+Warning: WARNING:
• Existing files at these locations will be OVERWRITTEN
• A safety backup will be created before restoration
• Services may need to be restarted after restoration
@@ -831,510 +910,67 @@ Storage directories recreated successfully.
## PVE Restore: Standalone vs Cluster
-The restore workflow behaves differently based on whether the backup originated from a **standalone PVE node** or a **cluster member**. This is critical for understanding what happens during restore.
+Use [cluster decisions and recovery scenarios](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery). SAFE applies live configuration; RECOVERY replaces the database only on an offline or isolated target.
### Detection
-The prompt is decided by the **payload**, not by the manifest: it appears whenever the archive carries anything under the `pve_cluster` category (`/var/lib/pve-cluster/`) and that category is part of the restore. The manifest's `ClusterMode` field is only used to log a warning when the two disagree.
-
-That matters because a standalone PVE backup normally does carry that payload: `config.db` is collected whenever `BACKUP_CLUSTER_CONFIG` is on, which is the default, and the PVE info files are written under `var/lib/pve-cluster/info` on every PVE run. So **expect the SAFE/RECOVERY prompt on a standalone PVE restore too**.
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Behavior Comparison
-| Scenario | SAFE/RECOVERY Prompt | Restore Behavior |
-|----------|----------------------|------------------|
-| **No `pve_cluster` payload, or category not selected** | NOT shown | Nothing cluster-related is restored |
-| **Payload present, SAFE** | Shown, choice 1 | Export only, no `config.db` write, `pvesh` API apply |
-| **Payload present, RECOVERY** | Shown, choice 2 | Database restored directly |
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Standalone Restore
-On a standalone node the prompt still appears, and the answer that does what you want is **RECOVERY**: it writes `config.db` back. There is no split-brain risk to protect against on a single node.
-
-SAFE never writes `config.db`: it exports the cluster database and reapplies the rest of the selected categories through `pvesh`. If you are rebuilding a node whose pmxcfs is empty or broken, that is not what you want, so answer RECOVERY. On a standalone node that is already running, where you only want the backed-up configuration merged back in, SAFE is still the safer answer.
-
-With RECOVERY selected:
-
-1. **Direct database restore** - `/var/lib/pve-cluster/config.db` is overwritten
-2. **Automatic service management** - PVE services are stopped, database restored, services restarted
-3. **No isolation required** - Single node has no split-brain risk
-
-```text
-Detected system type: Proxmox Virtual Environment (PVE)
-
-Cluster payload detected. Choose how to restore the cluster database:
- [1] SAFE [2] RECOVERY
-> 2
-
-Preparing system for cluster database restore: stopping PVE services...
-Stopping pve-ha-lrm, pve-ha-crm, pve-cluster, pvedaemon, pveproxy, pvestatd...
-Unmounting /etc/pve...
-Extracting /var/lib/pve-cluster/config.db...
-Restarting PVE services (pve-cluster, pvedaemon, pveproxy, pvestatd, pve-ha-crm, pve-ha-lrm)...
-```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Cluster Restore - SAFE Mode
-When restoring from a **cluster backup** and selecting **SAFE mode** (option 1):
-
-1. **Files are EXPORTED only** - NOT written to system paths
-2. **Database is NOT modified** - Current cluster state preserved
-3. **pvesh API apply** - User can selectively apply configurations:
- - VM/CT configs applied one by one
- - Storage definitions applied individually
- - Datacenter config applied if desired
-4. **Non-destructive** - Safe for active clusters
-
-```text
-Cluster backup detected. Choose how to restore:
- [1] SAFE: Export cluster files only (apply via API) ← SELECTED
- [2] RECOVERY: Full database restore
-
-Exporting 1 export-only category(ies) to: /opt/proxsave/proxmox-config-export-*/
-
-SAFE cluster restore: applying configs (node=pve01)
-Found 5 VM/CT configs for node pve01
-Apply all VM/CT configs via pvesh? (y/N): y
-Applied VM/CT config 100 (webserver)
-Applied VM/CT config 101 (database)
-...
-```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Cluster Restore - RECOVERY Mode
-When restoring from a **cluster backup** and selecting **RECOVERY mode** (option 2):
-
-1. **Direct database restore** - The selected `pve_cluster` payload, including `config.db`, is restored
-2. **WARNING displayed** - User must confirm node isolation
-3. **Split-brain risk** - CRITICAL to isolate node before proceeding
-4. **Quorum probe** - A node that is a member of a quorate cluster with more than 1 node online is refused before anything is stopped or written: its cluster would replace the restored `config.db` as soon as `pve-cluster` starts again (see [Phase 6](#phase-6-cluster-restore-mode-pve-backups-carrying-pve_cluster))
-
-```text
-Cluster backup detected. Choose how to restore:
- [1] SAFE: Export cluster files only
- [2] RECOVERY: Full database restore ← SELECTED
-
-WARNING: Selected RECOVERY cluster restore
-Ensure other nodes are ISOLATED before proceeding!
-
-Preparing system for cluster database restore...
-[Same flow as Standalone]
-```
-
-On a node that is still quorate with its peers, the run stops at this point instead:
-
-```text
-Cluster RECOVERY refused - quorate cluster, 3 nodes online: its copy would replace the restored config.db
-```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### When to Use Each Mode
-| Use Case | Recommended Mode |
-|----------|------------------|
-| Recovering a single standalone node | RECOVERY (the prompt still appears) |
-| Recovering specific VM configs from cluster backup | Cluster SAFE |
-| Recovering storage definitions from cluster backup | Cluster SAFE |
-| Full disaster recovery, cluster destroyed | Cluster RECOVERY |
-| Single surviving node after cluster failure | Cluster RECOVERY + isolate first |
-
----
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
## Cluster Database Restore
-Restoring the PVE cluster database (`/var/lib/pve-cluster/config.db`) requires special handling due to the cluster filesystem architecture.
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Understanding PVE Cluster Filesystem
-**Architecture**:
-```text
-pmxcfs (daemon)
- ↓
-reads/writes config.db (/var/lib/pve-cluster/config.db)
- ↓
-presents as FUSE mount (/etc/pve)
- ↓
-syncs via corosync (cluster communication)
-```
-
-**Critical Files**:
-- `/var/lib/pve-cluster/config.db` - SQLite database (actual storage)
-- `/etc/pve/` - FUSE mount (view into database)
-
-**Why Special Handling Needed**:
-- Cannot write to `/etc/pve` directly (it's a FUSE mount)
-- Must stop pmxcfs to safely replace config.db
-- Must ensure cluster synchronization after restore
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Cluster Restore Modes: SAFE vs RECOVERY
-When the analyzed archive contains the `pve_cluster` payload and that category is selected, the restore workflow presents two options. The manifest's `ClusterMode` is used only to warn when its claim disagrees with the payload:
-
-```text
-Cluster backup detected. Choose how to restore the cluster database:
- [1] SAFE: Do NOT write /var/lib/pve-cluster/config.db. Export cluster files only (manual/apply via API).
- [2] RECOVERY: Restore full cluster database (/var/lib/pve-cluster). Use only when cluster is offline/isolated.
- [0] Exit
-```
-
-#### Option 1: SAFE Mode (Recommended for Active Clusters)
-
-**What it does**:
-- Does **NOT** write to `/var/lib/pve-cluster/config.db`
-- Redirects the `pve_cluster` category into an export directory for review
-- Offers to apply configurations via `pvesh` API (non-destructive)
-- Preserves your current running cluster state
-
-> SAFE only redirects `pve_cluster`, whose paths are `./var/lib/pve-cluster/`. The `pvesh` apply below reads `/etc/pve/nodes/...`, `storage.cfg` and `datacenter.cfg` from the export, and those arrive only with the `pve_config_export` category. FULL includes it, CUSTOM includes it if you tick it, and **STORAGE and SYSTEM BASE strip it**, so in those modes the apply reports "No VM/CT configs found" and "No storage.cfg found in export" and does nothing.
-
-**When to use**:
-- Cluster is still operational
-- You want to selectively restore specific VMs or storage definitions
-- You're recovering individual configurations, not the entire cluster
-- You want to review changes before applying them
-
-**Post-restore actions (SAFE mode)**:
-After export, the workflow offers interactive options to apply configurations via `pvesh`:
-1. **VM/CT configs**: Scans exported configs (under `/etc/pve/nodes//...`) and first loads the cluster-wide guest inventory. Existing guests on the current node are applied via `pvesh set /nodes//qemu|lxc//config` (create-only keys such as `meta`/`ostemplate` are stripped; if the set fails, the exported conf is written into pmxcfs only when `status/current` explicitly reports `stopped`). A VMID absent cluster-wide is registered by writing its conf; a VMID owned by another node or present as the other guest type is skipped without mutation. An unavailable or invalid inventory stops the entire guest batch before mutation.
- - If the target node hostname differs from the hostname stored in the backup (common after hardware migration / reinstall), ProxSave detects the mismatch and prompts you to select the exported node directory to import from (instead of silently reporting "No VM/CT configs found").
-2. **Storage configuration**: applies each `storage.cfg` block via `pvesh create /storage --storage= --type= ...`, falling back to `pvesh set /storage/` when the definition already exists (as `local` always does)
-3. **Datacenter configuration**: writes `datacenter.cfg` into pmxcfs (`/etc/pve`), which replicates it cluster-wide - the API has no whole-file endpoint for it
-
-Each action prompts for confirmation before execution.
-
-#### Option 2: RECOVERY Mode (Full Cluster Restore)
-
-**What it does**:
-- Probes the quorum with `pvecm status` and refuses a quorate cluster with more than 1 node online
-- Stops the HA services (pve-ha-lrm, pve-ha-crm), then the PVE cluster services (pve-cluster, pvedaemon, pveproxy, pvestatd)
-- Unmounts `/etc/pve` FUSE filesystem
-- Writes directly to `/var/lib/pve-cluster/config.db`
-- Restarts the services with the restored configuration right after that write, before the later restore steps
-- Avoids restoring files under `/etc/pve/*` while pmxcfs is stopped/unmounted (to prevent "shadowed" writes on the underlying disk). Those files are expected to come from the restored `config.db`.
-
-**When to use**:
-- Complete disaster recovery
-- Cluster is completely offline or destroyed
-- Node is isolated from other cluster members
-- You have no working cluster to preserve
-
-**CRITICAL WARNING**:
-- Using RECOVERY mode on a node that is still part of an active cluster can cause split-brain
-- Always isolate the node first (stop corosync, disconnect network)
-- Other nodes may need to be removed and rejoined after restore
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Prerequisites
-**CRITICAL: Before starting restore**:
-
-1. **Isolate Node** (for multi-node clusters):
- ```bash
- # Stop cluster communication
- systemctl stop corosync
-
- # Or disconnect from cluster network
- # ip link set down
- ```
-
-2. **Verify Node Isolation**:
- ```bash
- pvecm nodes
- # Should show only this node or error
- ```
-
-3. **Document Current State**:
- ```bash
- pvecm status > /root/cluster-state-before-restore.txt
- pvesm status > /root/storage-state-before-restore.txt
- ```
-
-4. **Backup Current State** (in addition to automatic safety backup):
- ```bash
- tar -czf /root/manual-cluster-backup.tar.gz /var/lib/pve-cluster/
- ```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#pre-recovery-checklist).
### Automatic Service Management
-When restoring the `pve_cluster` category, the workflow automatically:
-
-**Stops services** (in order):
-```text
-1. pve-ha-lrm → Freezes HA resources, closes the watchdog cleanly (no-block stop, up to 180 s, never killed)
-2. pve-ha-crm → Releases the CRM lock; the master moves to another node
-3. pve-cluster → Stops pmxcfs, unmounts /etc/pve
-4. pvedaemon → Stops API daemon
-5. pveproxy → Stops web interface
-6. pvestatd → Stops statistics collection
-```
-
-The HA services go first because `pve-ha-lrm` left running while pmxcfs is down lets its watchdog expire after 60 seconds, and the node is hard-reset (fenced) in the middle of the restore.
-
-**Unmounts filesystem**:
-```bash
-umount /etc/pve
-```
-
-**Restores files**:
-- Extracts `/var/lib/pve-cluster/` directory
-- Includes config.db and all related files
-- Preserves permissions and ownership
-
-**Restarts services** (in order), right after the cluster database is written and before the later steps (network apply, boot rebuild); if the restore fails before that point, when the run ends:
-```text
-1. pve-cluster → Starts pmxcfs, reads restored config.db, remounts /etc/pve
-2. pvedaemon → Reads cluster config from /etc/pve
-3. pveproxy → Connects to pvedaemon
-4. pvestatd → Resumes statistics
-5. pve-ha-crm → Rejoins the CRM election
-6. pve-ha-lrm → Resumes the HA resources it froze
-```
-
-Because the services are already running when the network is applied, the post-apply network health check runs its PVE checks (`pvecm status`, ports, services) in RECOVERY as in any other restore.
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Service Stop/Restart Flow
-```text
-┌─────────────────────────────────────────────────┐
-│ CLUSTER DATABASE RESTORE SEQUENCE │
-└─────────────────────────────────────────────────┘
-
-Before Restore:
- ┌─────────────┐
- │ pve-cluster │ ─┐
- │ (running) │ │
- └─────────────┘ │
- ┌─────────────┐ │ All services
- │ pvedaemon │ ─┤ running
- └─────────────┘ │ /etc/pve mounted
- ┌─────────────┐ │
- │ pveproxy │ ─┤
- └─────────────┘ │
- ┌─────────────┐ │
- │ pvestatd │ ─┘
- └─────────────┘
-
-Stop Phase:
- systemctl stop --no-block pve-ha-lrm ← Wait up to 180 s, never killed;
- watchdog closed, HA resources frozen
- systemctl stop pve-ha-crm
- systemctl stop pve-cluster ← /etc/pve unmounted
- systemctl stop pvedaemon
- systemctl stop pveproxy
- systemctl stop pvestatd
- umount /etc/pve (if needed)
-
-Restore Phase:
- Extract: /var/lib/pve-cluster/config.db
- Extract: /var/lib/pve-cluster/* (all files)
-
-Restart Phase (right after the extraction):
- systemctl start pve-cluster ← Reads restored config.db
- ← Remounts /etc/pve
- systemctl start pvedaemon ← Reads /etc/pve config
- systemctl start pveproxy
- systemctl start pvestatd
- systemctl start pve-ha-crm
- systemctl start pve-ha-lrm
-
-Later steps (network apply, boot rebuild) run with the services up.
-
-After Restore:
- ┌─────────────┐
- │ pve-cluster │ ─┐
- │ (running) │ │
- └─────────────┘ │
- ┌─────────────┐ │ All services
- │ pvedaemon │ ─┤ restarted
- └─────────────┘ │ /etc/pve remounted
- ┌─────────────┐ │ with RESTORED config
- │ pveproxy │ ─┤
- └─────────────┘ │
- ┌─────────────┐ │
- │ pvestatd │ ─┘
- └─────────────┘
-```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#cluster-restore-modes-safe-vs-recovery).
### Post-Restore Verification
-**Immediate Checks**:
-
-1. **Verify Services Running**:
- ```bash
- systemctl status pve-cluster pvedaemon pveproxy pvestatd
- ```
- All should show: `active (running)`
-
-2. **Verify /etc/pve Mounted**:
- ```bash
- mount | grep pve
- # Output: /etc/pve type fuse.pmxcfs (rw,nosuid,nodev,relatime,user_id=0,group_id=0)
-
- ls -la /etc/pve/
- # Should show: storage.cfg, datacenter.cfg, user.cfg, etc.
- ```
-
-3. **Verify Cluster Status**:
- ```bash
- pvecm status
- ```
- Expected output:
- ```text
- Cluster information
- -------------------
- Name: pve-cluster
- Config Version: X
- Transport: knet
- Secure auth: on
-
- Quorum information
- ------------------
- Date: ...
- Quorum provider: corosync_votequorum
- Nodes: 1 # For single-node
- Expected votes: 1
- Total votes: 1
- Quorum: 1
- Flags: Quorate
- ```
-
-4. **Verify API Access**:
- ```bash
- pvesh get /version
- # Should return PVE version info without errors
-
- pvesh get /cluster/resources
- # Should list cluster resources
- ```
-
-5. **Verify Storage Configuration**:
- ```bash
- pvesm status
- # Should list all storage as 'active'
- ```
-
-6. **Check Logs for Errors**:
- ```bash
- journalctl -u pve-cluster --since "5 minutes ago"
- journalctl -u pvedaemon --since "5 minutes ago"
- # Should show clean startup, no errors
- ```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#post-recovery-verification).
### Multi-Node Cluster Considerations
-**IMPORTANT**: Restoring config.db on one node of a multi-node cluster can cause cluster desynchronization.
-
-**Recommended Approaches**:
-
-The sequences below write `proxsave --restore` because they are meant to be followed
-command by command on a console. On a node whose terminal can still render the menu,
-run `proxsave` bare and pick **Tools > Restore** at that step instead; it is the same
-workflow.
-
-**Option 1: Standalone Node Restore (Safest)**
-```bash
-# Before restore: Remove node from cluster
-pvecm delnode
-
-# Perform restore
-proxsave --restore
-
-# After restore: Rejoin cluster (if applicable)
-# Or accept this node as new standalone cluster
-```
-
-**Option 2: Full Cluster Rebuild**
-```bash
-# On ALL nodes: Stop cluster communication
-systemctl stop corosync
-
-# On PRIMARY node: Perform restore
-proxsave --restore
-
-# On PRIMARY node: Restart corosync
-systemctl start corosync
-
-# On OTHER nodes: Remove old cluster data and rejoin
-rm -rf /etc/pve /var/lib/pve-cluster/*
-pvecm add
-```
-
-**Option 3: Isolated Node Recovery**
-```bash
-# Isolate node from cluster network
-# (Disconnect network cable or firewall rules)
-
-# Perform restore on isolated node
-proxsave --restore
-
-# Test recovered configuration
-# Verify all services working
-
-# Decide: Keep standalone OR rejoin cluster
-```
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#pre-recovery-checklist).
### Common Issues and Solutions
-**Issue: Services fail to start after restore**
-
-```bash
-# Check detailed logs
-journalctl -xe -u pve-cluster
-
-# Common causes:
-# - config.db corruption
-# - Hostname mismatch
-# - Certificate issues
-
-# Solution: Restore from safety backup
-# TIMESTAMP: the directory of the restore to undo, from its "Safety backup preserved at:" line
-tar -xzf /opt/proxsave/restore/TIMESTAMP/restore_backup_*.tar.gz -C /
-systemctl restart pve-cluster pvedaemon pveproxy pvestatd
-```
-
-**Issue: /etc/pve not mounting**
-
-```bash
-# Check if pmxcfs is running
-systemctl status pve-cluster
-
-# Try manual unmount and restart
-umount -f /etc/pve
-systemctl restart pve-cluster
-
-# Check logs
-journalctl -u pve-cluster --since "1 hour ago"
-```
-
-**Issue: Cluster shows wrong nodes**
-
-```bash
-# Edit corosync configuration
-vi /etc/pve/corosync.conf
-# Remove references to dead/wrong nodes
-
-# Update cluster
-pvecm updatecerts
-pvecm delnode
-
-# Restart services
-systemctl restart corosync pve-cluster
-```
-
-**Issue: Hostname changed since backup**
-
-```bash
-# Option 1: Change hostname to match backup
-hostnamectl set-hostname
-reboot
-
-# Option 2: Update cluster config for new hostname
-# Edit /etc/pve/corosync.conf
-# Change old hostname to new hostname
-# Regenerate certificates
-pvecm updatecerts
-systemctl restart pve-cluster
-```
-
----
+See the [cluster recovery procedure](CLUSTER_RECOVERY.md#common-issues-and-solutions).
## Export-Only Categories
@@ -1362,17 +998,17 @@ Certain paths are too sensitive to restore directly and are extracted to a separ
↑
Backend: /var/lib/pve-cluster/config.db
-Writing directly to /etc/pve:
- ✗ Bypasses cluster synchronization
- ✗ Conflicts with FUSE filesystem
- ✗ May corrupt cluster state
- ✗ Changes don't persist (only in RAM)
+Writes through mounted /etc/pve:
+ Persist in config.db and replicate within the cluster
+ Can change live storage, guest and access configuration
+ Need review before replacing existing settings
```
**Code Protection**:
```text
-Hard guard in code prevents ANY write to /etc/pve when restoring to /
-(see internal/orchestrator/restore.go:880-884)
+The archive extraction guard skips direct writes under /etc/pve when restoring to /
+(see internal/orchestrator/restore_archive_entries.go)
+Confirmed API and pmxcfs applies use separate paths
```
### Export-Only Category: pbs_config
@@ -1486,7 +1122,7 @@ Pass 3: Staged Categories
**Selection**:
```text
-Available categories:
+- categories:
[1] [ ] PVE Config Export
Export-only copy of /etc/pve (never written to system paths)
↑ Clear description warns user
@@ -1511,8 +1147,8 @@ Custom selection:
[X] PVE Config Export ← Exports /etc/pve/ for reference
Result:
- 1. config.db restored → New cluster configuration active
- 2. /etc/pve/ exported → Old configuration available for comparison
+ 1. config.db restored -> New cluster configuration active
+ 2. /etc/pve/ exported -> Old configuration available for comparison
3. User can review differences and selectively copy needed files
```
@@ -1553,7 +1189,8 @@ For each VM/CT config found in the export:
- Skips a VMID already owned by another node; SAFE does not move guests between nodes
- Skips a VMID whose live type (`qemu` or `lxc`) differs from the staged config type
- Updates a matching guest on the current node with `pvesh set /nodes////config --= ...`, excluding create-only keys
-- If that API update fails, writes the staged conf into pmxcfs only after the JSON status probe explicitly reports `stopped`; command errors, malformed status, `running`, and unknown states all skip the fallback
+- A recognized API schema refusal permits file fallback only if `status/current` explicitly reports `stopped`; other API failures do not qualify
+- For a schema refusal with a running or unverified guest, ProxSave may retry the API update with refused keys removed; it does not write the staged file
- Registers a VMID that is absent cluster-wide by writing the staged conf into pmxcfs on the current node
- Reports success/failure for each VM/CT
@@ -1652,11 +1289,11 @@ complete.** Check every definition the run named, with `pvesh get /storage/
--output-format=json` against the `storage.cfg` in the export, and set by hand anything that
differs.
-**Benefits of pvesh Apply**:
-- Non-destructive: works with running cluster
-- Selective: apply only what you need
-- Auditable: each action logged
-- Reversible: changes can be undone via GUI/API
+**Scope of pvesh Apply**:
+- Applies confirmed configuration groups without wholesale database replacement
+- Updates live state and can affect the entire cluster
+- Logs individual results, including skips and partial failures
+- Does not provide an automatic transaction rollback for every API change
---
@@ -1688,7 +1325,7 @@ These configurations are included in every backup and can be restored using **th
### Method 1: pvesh SAFE Apply (Recommended)
-**Best for**: Active clusters where you want to restore specific VMs without touching the cluster database.
+**Best for**: Applying an eligible guest configuration batch on an active cluster without replacing its whole database. For a single guest, decline the batch and follow the reviewed manual procedure.
**How it works**:
1. During restore, select **Cluster SAFE mode**
@@ -1696,20 +1333,17 @@ These configurations are included in every backup and can be restored using **th
3. Interactive prompt asks: "Apply all VM/CT configs via pvesh?"
4. Each config applied via Proxmox API: `pvesh set /nodes//qemu//config`
-**Advantages**:
-✅ Non-destructive (cluster database untouched)
-✅ Works with running cluster
-✅ Selective application (can skip specific VMs)
-✅ Auditable and reversible
-✅ No service interruption required
+**Behavior**:
+- Uses the running cluster and avoids a full database replacement
+- Confirms all eligible guest configurations from the selected source node as one batch
+- Checks cluster-wide VMID ownership and guest type before mutation
+- Changes live configuration; review per-guest results and the possible effect on workloads
**Step-by-Step Procedure**:
1. **Open the restore workflow**: run `proxsave` bare and pick **Tools > Restore** in
- the dashboard. On a host without a usable terminal, enter it directly:
- ```bash
- proxsave --restore
- ```
+ the dashboard. Direct entry options are in [CLI reference](CLI_REFERENCE.md):
+ Choose **Tools > Restore** in the dashboard; direct entry is in [CLI reference](CLI_REFERENCE.md).
2. **Select backup and decrypt** (standard workflow)
@@ -1790,16 +1424,15 @@ https://your-pve:8006
4. Manually copy desired configs to `/etc/pve/`
**Advantages**:
-✅ Full control over what gets restored
-✅ Review before applying
-✅ Compare with current configs
-✅ Extract individual values without full restore
+- Full control over what gets restored
+- Review before applying
+- Compare with current configs
+- Extract individual values without full restore
**Step-by-Step Procedure**:
1. **Open the restore workflow and select the pve_config_export category**: run
- `proxsave` bare and pick **Tools > Restore**, or enter it directly with
- `proxsave --restore` on a host without a usable terminal. Then select `CUSTOM`
+ `proxsave` without arguments and pick **Tools > Restore**. For direct entry when the dashboard cannot render, see [CLI reference](CLI_REFERENCE.md#restore-from-backup). Then select `CUSTOM`
mode and enable the `PVE Config Export` category.
2. **Locate exported files**:
@@ -1905,18 +1538,18 @@ grep "^scsi\|^virtio\|^ide\|^sata" qemu-server/100.conf
```text
Are you restoring to an active multi-node cluster?
-├─ YES → Use Method 1: pvesh SAFE Apply
-│ (Non-destructive, no downtime)
+├─ YES -> Use Method 1: pvesh SAFE Apply
+│ (Confirmed batch changes to live configuration)
│
-└─ NO → Is this a complete disaster recovery?
- ├─ YES → Use Method 3: Full Cluster Database Restore
+└─ NO -> Is this a complete disaster recovery?
+ ├─ YES -> Use Method 3: Full Cluster Database Restore
│ (Restores everything at once)
│
- └─ NO → Do you need to restore all VMs?
- ├─ YES → Use Method 1: pvesh SAFE Apply
+ └─ NO -> Do you need to restore all VMs?
+ ├─ YES -> Use Method 1: pvesh SAFE Apply
│ (Faster than manual copy)
│
- └─ NO → Use Method 2: Manual Copy
+ └─ NO -> Use Method 2: Manual Copy
(Review before applying)
```
@@ -1954,18 +1587,18 @@ Are you restoring to an active multi-node cluster?
**Configuration vs. Data**:
```text
What ProxSave Backs Up:
-✅ VM/CT configuration files (*.conf)
-✅ Cluster settings
-✅ Storage definitions
-✅ User/permissions
-✅ Network configuration
-✅ Backup job definitions
+- VM/CT configuration files (*.conf)
+- Cluster settings
+- Storage definitions
+- User/permissions
+- Network configuration
+- Backup job definitions
What ProxSave Does NOT Back Up:
-❌ VM/CT disk images (*.qcow2, *.raw, etc.)
-❌ Running VM memory state
-❌ Application data inside VMs
-❌ Storage pool data
+Not available VM/CT disk images (*.qcow2, *.raw, etc.)
+Not available Running VM memory state
+Not available Application data inside VMs
+Not available Storage pool data
```
**Best Practice Recommendation**:
@@ -1992,10 +1625,10 @@ Multiple layers of protection prevent data loss and corruption during restore.
- Full directory structures
- Preserved permissions, ownership, timestamps
-**Rollback Command**:
-```bash
-tar -xzf /opt/proxsave/restore/20251120_143052/restore_backup_20251120_143118.tar.gz -C /
-```
+**Rollback**: inspect the exact session archive and follow the
+[manual rollback prerequisites](#manual-rollback-prerequisites). A generic
+`tar -xzf ... -C /` command does not handle live services, pmxcfs or HA, and does not
+undo every API change made later in the workflow.
**If Safety Backup Fails**:
```text
@@ -2037,7 +1670,7 @@ Current auto-skip prompts:
- **PVE firewall apply**
- **PVE HA apply**
-On timeout every one of them resolves to the **non-applying** answer, so an unattended restore leaves fstab, network, access control, firewall and HA staged on disk but not applied.
+On timeout these prompts answer **No** to the requested operation. This does not undo earlier phases. In particular, skipping live network reload can still leave validated network files installed for the next restart; see [Network Safe Apply](#4-network-safe-apply-optional).
That is worth separating from the Enter-key default, which the countdown does not follow. The fstab prompt defaults to **Yes** when the backup root, and swap where comparable, match the current system, so pressing Enter applies the merge. Letting the countdown run out still answers No. In other words the fstab merge is never applied unattended, however well the systems match.
@@ -2089,7 +1722,7 @@ This protects SSH/GUI access during network changes.
- Diagnostics are saved under `/opt/proxsave/restore//network_apply_*` (snapshots `before.txt` / `after.txt` / `after_rollback.txt` when relevant, `health_before.txt` / `health_after.txt`, `preflight.txt`, `plan.txt`, and `ifquery_*`)
**NIC name repair**:
-- If physical NIC names changed after reinstall (e.g. `eno1` → `enp3s0`), ProxSave attempts an automatic mapping using backup network inventory (permanent MAC / MAC / PCI path / udev IDs like `ID_PATH`, `ID_NET_NAME_PATH`, `ID_NET_NAME_SLOT`, `ID_SERIAL`)
+- If physical NIC names changed after reinstall (e.g. `eno1` -> `enp3s0`), ProxSave attempts an automatic mapping using backup network inventory (permanent MAC / MAC / PCI path / udev IDs like `ID_PATH`, `ID_NET_NAME_PATH`, `ID_NET_NAME_SLOT`, `ID_SERIAL`)
- When a safe mapping is found, `/etc/network/interfaces` and `/etc/network/interfaces.d/*` are rewritten before applying the network config
- If you skip live network apply, ProxSave may still install the staged config to disk (no reload) after safe NIC repair + preflight; if validation fails, it rolls back and keeps the staged copy.
- If a mapping would overwrite an interface name that already exists on the current system, ProxSave prompts before applying it (conflict-safe)
@@ -2188,7 +1821,7 @@ If the restore includes filesystem configuration (notably `/etc/fstab`), ProxSav
**Safety behavior**:
- The user is prompted before any change is written.
-- The prompt includes a **90-second** countdown; if you do not answer in time, ProxSave uses a safe default (**Skip** unless root/swap match, in which case the default is **Yes**).
+- The **90-second** countdown always answers **No** when it expires. A matching root/swap can make **Yes** the Enter-key default, but never the timeout answer.
### 6. Hard Guards
@@ -2205,25 +1838,25 @@ if cleanDestRoot == "/" && strings.HasPrefix(target, "/etc/pve") {
return nil
}
```
-- Absolute prevention of `/etc/pve` corruption
+- Blocks direct archive extraction into `/etc/pve`; confirmed API and pmxcfs applies remain separate write paths
**PBS Datastore Mount Guards**:
- When restoring PBS datastore definitions, ProxSave can apply a temporary read-only bind-mount guard on mount roots that currently resolve to the root filesystem. If the bind mount cannot be created, it logs a warning and proceeds unguarded (no persistent `chattr +i` flag is set).
- Purpose: prevent accidental writes to `/` if a datastore mountpoint is missing/offline at restore time (PBS will show the datastore as unavailable until storage is mounted).
-- Optional cleanup: dashboard **Recovery > Cleanup guards**, or `proxsave --cleanup-guards` (use `--dry-run` to preview) on a headless host. See **Clearing mount guards after the storage is back** below.
+- Optional cleanup: dashboard **Recovery > Cleanup guards**. Its first screen is a read-only check before Apply. See **Clearing mount guards after the storage is back** below.
**PVE Storage Mount Guards**:
- When restoring PVE storage definitions (from `storage.cfg`), ProxSave applies the same "restore even if offline" strategy for mount-backed storage:
- Network storages (`nfs`, `cifs`, `cephfs`, `glusterfs`) use mountpoints under `/mnt/pve/`. ProxSave attempts `pvesm activate `; if the mountpoint still resolves to the root filesystem, it applies a temporary read-only bind-mount guard (or, if the bind mount cannot be created, logs a warning and proceeds unguarded).
- `dir` storages are guarded only when their `path` lives under a mountpoint restored via `/etc/fstab` (to avoid guarding local root filesystem paths).
- Purpose: prevent PVE from writing into `/mnt/pve/...` (or other mount roots) when the backing storage is offline at restore time.
-- Optional cleanup: dashboard **Recovery > Cleanup guards**, or `proxsave --cleanup-guards` (use `--dry-run` to preview) on a headless host. See **Clearing mount guards after the storage is back** below.
+- Optional cleanup: dashboard **Recovery > Cleanup guards**. Its first screen is a read-only check before Apply. See **Clearing mount guards after the storage is back** below.
**Clearing mount guards after the storage is back**:
-- The normal route is the dashboard: run `proxsave` bare and pick **Recovery > Cleanup guards**. It is a two-step screen, a read-only check first (which offers Apply only when it actually finds guards), then the cleanup itself, reporting `DONE` or `PENDING`. `proxsave --cleanup-guards` (preview with `--dry-run`) is the same operation from the command line, for a headless host or a script.
+- The normal route is the dashboard: run `proxsave` bare and pick **Recovery > Cleanup guards**. It is a two-step screen, a read-only check first (which offers Apply only when it actually finds guards), then the cleanup itself, reporting `DONE` or `PENDING`. For direct cleanup entry and preview flags, see [CLI reference](CLI_REFERENCE.md).
- Bringing the storage online again is enough to *use* it: a real mount stacks on top of a bind-mount guard automatically. The guard is not deleted, only shadowed; a reboot or a cleanup run removes the bind-mount leftover. A **legacy** `chattr +i` flag (set by older versions when a bind mount failed) leaves the directory immutable across reboots until it is cleared.
- The cleanup unmounts bind-mount guards **and** clears any **legacy** `chattr +i` immutable flags, but only on mountpoints that are **not currently mounted** (clearing a live mount would touch the wrong inode); it prints a summary of what was cleared vs left pending. The guard directory is kept until nothing is pending.
-- To clear a legacy flag while the storage is mounted: unmount it, run `--cleanup-guards` again (or `chattr -i `), then remount.
+- To clear a legacy flag while the storage is mounted: unmount it, choose **Recovery > Cleanup guards** again (or `chattr -i `), then remount.
- If you deleted the guard directory (`/guards`, or `/var/lib/proxsave/guards` from an older version) manually and a mountpoint is still read-only, ProxSave has no record left to clear: check `lsattr -d ` and run `chattr -i ` while the storage is unmounted.
### 7. Service Management Fail-Fast
@@ -2290,7 +1923,7 @@ grep -E "Failed to extract|Refusing hardlink" /opt/proxsave/restore/20251120_143
Verifying SHA256 checksum...
Expected: a1b2c3...
Actual: a1b2c3...
-✓ Checksum verified successfully.
+Yes Checksum verified successfully.
```
### 10. Deferred Service Restart
@@ -2298,42 +1931,14 @@ Actual: a1b2c3...
**Go defer pattern** ensures services restart even if restore fails:
```text
-Services stopped → Defer restart scheduled → Restore → (Failure) → Deferred restart executes
+Services stopped -> Defer restart scheduled -> Restore -> (Failure) -> Deferred restart executes
```
**Prevents**: System left with services stopped after failed restore
### 11. Kernel Command Line Merge (`boot` category)
-A restore usually runs on a new machine, whose root device, pool name and ESPs differ from the backed-up host. The `boot` category therefore never writes the old host's boot files: GRUB settings (`/etc/default/grub`, `/etc/default/grub.d/`), `/etc/kernel/cmdline` and `/etc/kernel/proxmox-boot-uuids` are kept in the archive under `var/lib/proxsave-info/boot/` and only reach the export directory. None of these files is written to the live system, in any mode, including the full-restore fallback, not even when `CUSTOM_BACKUP_PATHS` names `/etc/default` or `/etc/kernel` and the archive also holds them at their natural paths: those copies go to the export directory with `proxsave_info`. The rest of `/etc/default` is restored by `services` as before.
-
-**Source**: the backed-up host's effective kernel command line (`/proc/cmdline` at backup time), stored in `var/lib/proxsave-info/commands/system/kernel_cmdline.txt` by every backup.
-
-**Merge rule**:
-- Every parameter is carried except those that describe the backed-up host itself, and anything after `--` (arguments for init):
- - its root device and boot image: `root=`, `boot=`, `ro`, `rw`, `BOOT_IMAGE=`, `initrd=`;
- - how its root was mounted and where it resumed from: `rootflags=`, `rootfstype=`, `resume=`, `resume_offset=`. A `rootflags=` or `rootfstype=` of another filesystem makes this host's root mount fail, and the boot stops in the initramfs shell;
- - what was sized on its RAM or laid out on its memory map: `zfs.zfs_arc_max=` and `zfs.zfs_arc_min=` (the restore keeps this host's ARC limit), `hugepages=`, `hugepagesz=`, `default_hugepagesz=`, `sysctl.vm.nr_hugepages=`, `hugetlb_cma=`, `cma=`, `kernelcore=`, `movablecore=`, `mem=` and `memmap=` (a `memmap=` of another machine's firmware map can stop the boot);
- - `crashkernel=`: the kdump reservation. On GRUB hosts `kdump-tools` writes it through its own drop-in, sized for this host's RAM; without `kdump-tools` it only takes memory.
-- A parameter this host already has is not added again. When both hosts set the same parameter with different values, this host's value stays (the kernel treats `-` and `_` in parameter names as the same character, so `vfio-pci.ids` and `vfio_pci.ids` are one parameter).
-
-**Where the parameters are written** (Proxmox VE admin guide, *Host Bootloader*, *Editing the Kernel Commandline*):
-
-| This host | File written | Rebuild |
-|-----------|--------------|---------|
-| GRUB, no `/etc/kernel/proxmox-boot-uuids`; `/etc/default/grub`, `/boot/grub/grub.cfg` and `update-grub` present | the value of `GRUB_CMDLINE_LINUX_DEFAULT` in `/etc/default/grub`, the rest of the file untouched | `update-initramfs -u -k all`, then `update-grub` |
-| `proxmox-boot-tool status` reports every ESP as `uefi` (systemd-boot); `/etc/kernel/cmdline` is one line with `root=` | `/etc/kernel/cmdline` | `update-initramfs -u -k all`, then `proxmox-boot-tool refresh` |
-| `proxmox-boot-tool status` reports every ESP as `grub` | the value of `GRUB_CMDLINE_LINUX_DEFAULT` in `/etc/default/grub` | `update-initramfs -u -k all`, then `proxmox-boot-tool refresh` |
-
-Anything else is not recognized with certainty, and nothing is written: the ESPs disagree, `proxmox-boot-tool status` fails, `GRUB_CMDLINE_LINUX_DEFAULT` is not one plain assignment of a literal value, or a file in `/etc/default/grub.d/` sets it too. The restore logs a warning with the reason and the parameters the backup carries.
-
-**Rebuild**: runs once, at the end of the restore, when the merge changed a file or the restore wrote under `/etc/modprobe.d`, `/etc/modules`, `/etc/hostid` or `/etc/zfs`, which the initramfs copies. On a bootloader not recognized with certainty only `update-initramfs` runs, and the bootloader is left as it is. A failed command is a warning with the command and its error; the next command still runs and the restore goes on.
-
-**Safety backup**: the pre-restore `/etc/default/grub` and `/etc/kernel/cmdline` are in the safety backup, like every other file the restore may write.
-
-**Log**: every step is in the restore log, on lines starting with `Boot configuration -`: the backed-up command line, the bootloader found, the parameters added (or not carried because this host sets them differently), and each command run.
-
----
+See [Restore IOMMU, VFIO and passthrough settings](#restore-iommu-vfio-and-passthrough-settings) for the procedure, merge rules and bootloader limits.
## Troubleshooting
@@ -2345,16 +1950,13 @@ Anything else is not recognized with certainty, and nothing is written: the ESPs
**Solution**: become root first, then open the dashboard and pick **Tools > Restore**:
```bash
-sudo proxsave
+# Dashboard action: Tools > Restore
# Or
su -
-proxsave
+# Dashboard action: Tools > Restore
```
-On a headless host, the same applies to the flag:
-```bash
-sudo proxsave --restore
-```
+Root privileges are also required for direct restore entry; see [CLI reference](CLI_REFERENCE.md).
---
@@ -2422,7 +2024,7 @@ passphrase used for ``. Enter 0 to exit." Under `--cli` it is the s
line `Enter decryption key or passphrase for (0 = exit):`.
If the secret is genuinely lost, the backup cannot be decrypted. Creating a new key
-(dashboard **Maintenance > New key**, or `proxsave --newkey`) only changes what future
+(dashboard **Maintenance > New key**, or **Maintenance > New key** in the dashboard) only changes what future
backups are encrypted with.
---
@@ -2462,51 +2064,16 @@ apt install --reinstall pve-cluster
**Issue: "Services failed to restart after restore"**
-**Cause**: config.db corruption or configuration error
-
-**Solution**:
-```bash
-# Check service status
-systemctl status pve-cluster
-journalctl -xe -u pve-cluster
-
-# Restore from safety backup
-# TIMESTAMP: the directory of the restore to undo, from its "Safety backup preserved at:" line
-tar -xzf /opt/proxsave/restore/TIMESTAMP/restore_backup_*.tar.gz -C /
-
-# Restart services (the HA services last, once pve-cluster is up)
-systemctl restart pve-cluster pvedaemon pveproxy pvestatd
-systemctl start pve-ha-crm pve-ha-lrm
-
-# If still failing, check logs
-journalctl -u pve-cluster --since "10 minutes ago"
-```
-
----
+Inspect `systemctl status pve-cluster` and `journalctl -u pve-cluster` for the actual
+failure. For a database rollback, follow the
+[manual rollback prerequisites](#manual-rollback-prerequisites).
**Issue: "/etc/pve not mounting after restore"**
-**Cause**: pmxcfs unable to mount FUSE filesystem
-
-**Solution**:
-```bash
-# Check if already mounted
-mount | grep pve
-
-# Force unmount
-umount -f /etc/pve
-
-# Restart pve-cluster
-systemctl restart pve-cluster
-
-# Check logs
-journalctl -u pve-cluster | tail -50
-
-# If config.db corrupted, restore safety backup
-# TIMESTAMP: the directory of the restore to undo, from its "Safety backup preserved at:" line
-tar -xzf /opt/proxsave/restore/TIMESTAMP/restore_backup_*.tar.gz -C /
-systemctl restart pve-cluster
-```
+Check the mount and service state before attempting a repair. A database error and
+a still-mounted filesystem are different problems. Do not force-unmount pmxcfs or
+extract a safety archive onto `/` while the database is in use. The same
+[rollback prerequisites](#manual-rollback-prerequisites) apply.
---
@@ -2514,59 +2081,23 @@ systemctl restart pve-cluster
**Issue: "Cluster shows wrong nodes after restore"**
-**Cause**: Restored old cluster configuration
-
-**Solution**:
-```bash
-# Option 1: Remove wrong nodes
-pvecm delnode
-
-# Option 2: Edit corosync.conf
-vi /etc/pve/corosync.conf
-# Remove references to dead nodes
-# Update node list
-
-pvecm updatecerts
-systemctl restart corosync pve-cluster
-```
-
----
+Inspect the recovered membership and identify the authoritative cluster. Remove
+obsolete members only from a surviving node after the old machines and workloads
+are accounted for. Follow [Cluster Recovery](CLUSTER_RECOVERY.md); do not edit node
+lists and restart pmxcfs without the HA and isolation prerequisites.
**Issue: "Lost quorum after restore"**
-**Cause**: Single-node cluster with wrong expected votes
-
-**Solution**:
-```bash
-# Set expected votes to 1
-pvecm expected 1
-
-# Verify quorum
-pvecm status
-
-# Make permanent (edit corosync.conf)
-vi /etc/pve/corosync.conf
-# Update expected_votes in quorum section
-```
-
----
+A recovered multi-node database can still expect its former peers. Check membership,
+Corosync links and qdevice state. Do not lower votes to match the nodes currently
+visible during a partition. Use the [Lost Quorum procedure](CLUSTER_RECOVERY.md#issue-lost-quorum)
+to select the appropriate recovery path.
**Issue: "Hostname mismatch in cluster config"**
-**Cause**: Restored backup from different hostname
-
-**Solution**:
-```bash
-# Option 1: Change hostname to match
-hostnamectl set-hostname
-reboot
-
-# Option 2: Update cluster config
-vi /etc/pve/corosync.conf
-# Change old hostname to new hostname
-pvecm updatecerts
-systemctl restart corosync pve-cluster
-```
+See [Hostname Changed](CLUSTER_RECOVERY.md#scenario-5-hostname-changed). Prepare the
+final hostname before joining, or select the reviewed SAFE apply route; renaming a
+live member and copying its node directory is not a generic recovery procedure.
---
@@ -2647,8 +2178,7 @@ ls -ld /mnt/datastore /mnt/datastore/ 2>/dev/null
namei -l /mnt/datastore/ 2>/dev/null || true
# If you need to remove ProxSave mount guards (optional / troubleshooting, run as root):
-proxsave --cleanup-guards --dry-run
-proxsave --cleanup-guards
+# Dashboard action: Recovery > Cleanup guards
# Common fix (adjust to your datastore path)
chown backup:backup /mnt/datastore && chmod 750 /mnt/datastore
@@ -2773,9 +2303,9 @@ role-specific configurations. ProxSave now evaluates compatibility by
**role overlap**:
- `pve` ↔ `pbs`: only common categories are sensible
-- `dual` → `pve`: PVE + Common can be restored
-- `dual` → `pbs`: PBS + Common can be restored
-- `pve` or `pbs` → `dual`: the matching role + Common can be restored
+- `dual` -> `pve`: PVE + Common can be restored
+- `dual` -> `pbs`: PBS + Common can be restored
+- `pve` or `pbs` -> `dual`: the matching role + Common can be restored
When overlap exists, ProxSave continues with warnings and automatically filters
the selected categories to the roles supported by the current host.
@@ -2818,9 +2348,9 @@ A: Yes, with considerations:
**Q: What if I cancel during restore?**
A: Depends on when:
-- **Before extraction**: No changes made, completely safe
-- **During extraction**: Partial restore, use safety backup to rollback
-- **After extraction**: Restore completed, services may be in mixed state
+- **Before final confirmation**: No restore payload has been applied
+- **After service preparation or during extraction**: Cleanup attempts to restore service state; files may already have changed
+- **After extraction**: Later applies may still be pending or partial; inspect the session log before deciding what to recover
Use Ctrl+C carefully - wait for current file to finish.
@@ -2830,22 +2360,34 @@ Use Ctrl+C carefully - wait for current file to finish.
**Q: How do I rollback a failed restore?**
-A: Use the safety backup:
-```bash
-# Stop services (if cluster restore)
-systemctl stop pve-cluster pvedaemon pveproxy pvestatd
-
-# Extract safety backup
-# TIMESTAMP: the directory of the restore to undo, from its "Safety backup preserved at:" line
-tar -xzf /opt/proxsave/restore/TIMESTAMP/restore_backup_*.tar.gz -C /
-
-# Restart services
-systemctl restart pve-cluster pvedaemon pveproxy pvestatd
-
-# Verify
-pvecm status
-pvesm status
-```
+A: Start with the exact safety archive and log from that restore session. Its scope
+is the files captured before the selected restore; it is not a full host snapshot
+or a reversal of every API operation.
+
+#### Manual rollback prerequisites
+
+1. Use an out-of-band console and establish which node and backup are authoritative.
+ For cluster database recovery, isolate obsolete peers and account for guests and
+ shared storage before proceeding.
+2. Inspect the exact safety archive from the session's `Safety backup preserved at:`
+ line. List its contents with `tar -tzf /exact/path/to/restore_backup_TIMESTAMP.tar.gz`.
+ Do not combine archives with a wildcard or extract the whole tree onto `/`.
+3. If restoring `config.db`, gracefully stop `pve-ha-lrm`, then `pve-ha-crm`, before
+ `pve-cluster` and the other PVE services. Verify successful shutdown and that
+ `/etc/pve` is unmounted. Do not kill the HA LRM to force progress: that can trigger
+ watchdog fencing. Stop if these conditions cannot be established.
+4. Restore only the reviewed files needed for this failure. For `config.db`, follow
+ the [official pmxcfs recovery procedure](https://pve.proxmox.com/pve-docs/pmxcfs-plain.html),
+ including database mode `0600`, the correct hostname and `/etc/hosts`. ProxSave's
+ normal RECOVERY workflow manages the service sequence when using a complete
+ ProxSave backup; a safety tarball alone is not that complete backup format.
+5. Restart `pve-cluster` and verify the mounted configuration, then restore the API
+ services. Bring HA back only after the cluster and workload state are safe.
+ Review networking, firewall and access-control changes separately using the
+ session's logs and their own rollback files.
+
+For normal recovery from a complete backup, prefer **Tools > Restore** in the dashboard and the
+applicable [cluster scenario](CLUSTER_RECOVERY.md).
---
@@ -2854,25 +2396,24 @@ pvesm status
A: Yes, two approaches:
**Approach 1: Test on separate system**
-```bash
-# Copy backup to test system
-# Run restore on test system
-# Validate configuration
-# Apply learnings to production restore
-```
+
**Approach 2: Decrypt-only mode**
-Dashboard **Tools > Decrypt**, or the flag on a headless host:
+The output is an uncompressed `.decrypted.bundle.tar` holding the inner archive and
+sidecars. Unwrap it into a private inspection directory, then inspect the named
+inner archive using its actual compression format. Follow
+[Decrypting Backups](ENCRYPTION.md#decrypting-backups); the outer bundle does not
+contain host paths directly. Decryption writes plaintext output but does not apply
+host configuration.
+
+Choose **Tools > Decrypt** in the dashboard to prepare a plaintext bundle for inspection:
```bash
# Decrypt without restoring
-proxsave --decrypt
-
-# Manually inspect decrypted files
-tar -tzf /path/to/decrypted.tar.gz | less
+# Dashboard action: Tools > Decrypt
-# Review specific files
-tar -xzf /path/to/decrypted.tar.gz ./etc/pve/storage.cfg -O | less
+# Inspect the outer, uncompressed bundle at the path printed by ProxSave
+tar -tf /path/to/backup.decrypted.bundle.tar
```
---
@@ -2911,61 +2452,13 @@ A: **Risky and NOT recommended** without precautions:
**Q: How do I restore cluster database on new hardware?**
-A: Full procedure:
-
-```bash
-# 1. Install Proxmox VE on new hardware
-# 2. Configure same hostname as backup
-hostnamectl set-hostname
-
-# 3. Run restore: "proxsave" bare, then Tools > Restore in the dashboard,
-# or the flag below on a console that cannot render it
-proxsave --restore
-# Select: STORAGE mode or Custom (include pve_cluster)
-
-# 4. Verify services
-systemctl status pve-cluster pvedaemon pveproxy
-pvecm status
-
-# 5. Verify storage
-pvesm status
-
-# 6. Manually recreate any missing storage paths
-# 7. Import ZFS pools if needed
-zpool import
-
-# 8. Access web interface and verify
-https://:8006
-```
+A: Follow [Migration to New Hardware](CLUSTER_RECOVERY.md#scenario-4-migration-to-new-hardware), including the standalone, isolated-member or clean-join decision before selecting SAFE or RECOVERY. VM disks and datastore content need their own recovery.
---
**Q: What if backup hostname doesn't match current hostname?**
-A: Two options:
-
-**Option 1: Change hostname to match (easiest)**
-```bash
-hostnamectl set-hostname
-reboot
-# Then run restore
-```
-
-**Option 2: Update cluster config after restore**
-```bash
-# Restore as normal (hostname will mismatch)
-proxsave --restore
-
-# Update corosync configuration
-vi /etc/pve/corosync.conf
-# Change old hostname to new hostname
-
-# Regenerate certificates
-pvecm updatecerts
-
-# Restart services
-systemctl restart corosync pve-cluster pvedaemon pveproxy
-```
+A: Follow [Hostname Changed](CLUSTER_RECOVERY.md#scenario-5-hostname-changed). Never rename a live cluster member or edit corosync as a shortcut. On a fresh or isolated destination, SAFE can select an exported source node for guest configuration without moving live cluster ownership.
---
@@ -2973,12 +2466,11 @@ systemctl restart corosync pve-cluster pvedaemon pveproxy
**Q: Why can't I restore /etc/pve directly?**
-A: `/etc/pve` is a **FUSE mount** managed by pmxcfs daemon:
-- Writing directly bypasses cluster synchronization
-- Changes don't persist (only in RAM)
-- Can corrupt cluster state
-
-**Correct approach**: Restore `/var/lib/pve-cluster/config.db` (the database backend)
+A: `/etc/pve` is the filesystem interface to pmxcfs. Writes through the mounted
+filesystem persist in `config.db` and replicate within the cluster. ProxSave blocks
+blind archive extraction there because it can overwrite live cluster configuration.
+Use confirmed SAFE applies for selected configuration groups, a reviewed manual
+single-file change, or RECOVERY for whole-database replacement on an isolated host.
---
@@ -3006,11 +2498,7 @@ cp /opt/proxsave/proxmox-config-export-*/etc/pve/qemu-server/100.conf \
A: **Three methods available**:
**Method 1: pvesh SAFE Apply (Recommended)**
-```bash
-# During restore, select Cluster SAFE mode
-# Answer "yes" when prompted: "Apply all VM/CT configs via pvesh?"
-# Configs applied automatically via API
-```
+
**Method 2: Manual Copy**
```bash
@@ -3033,14 +2521,11 @@ See [VM/CT Configuration Restore](#vmct-configuration-restore) for detailed proc
A: Not directly. Categories are the smallest granularity.
-**Workaround**: decrypt the backup to a plaintext bundle (dashboard **Tools > Decrypt**,
-or `proxsave --decrypt`), then take the file out of it yourself:
-```bash
-proxsave --decrypt
-
-# Manually extract specific files
-tar -xzf /path/to/decrypted.tar.gz ./specific/file/path
-```
+**Workaround**: use dashboard **Tools > Decrypt** or **Tools > Decrypt** in the dashboard, then
+unwrap the resulting `.decrypted.bundle.tar` into a private directory. Select the
+inner archive by its printed name and inspect or extract the desired entry there,
+using the matching decompressor. See [Decrypting Backups](ENCRYPTION.md#decrypting-backups).
+Review any extracted configuration before copying it to a live path.
---
@@ -3048,7 +2533,7 @@ tar -xzf /path/to/decrypted.tar.gz ./specific/file/path
A: Yes:
- **Extraction**: ProxSave preserves UID/GID, mode bits and timestamps (mtime/atime) for extracted entries.
-- **Staged categories**: files are extracted under `/tmp/proxsave/restore-stage-*` and then applied to system paths using atomic replace; ProxSave explicitly applies mode bits (not left to `umask`) and preserves/derives ownership/group to match expected system defaults (important on PBS, where `proxmox-backup-proxy` runs as `backup`; ProxSave also repairs common `root:root` group regressions by inheriting the destination parent directory's group). On supported filesystems, staged writes also `fsync()` the temporary file and the destination directory to reduce the risk of incomplete writes after a crash/power loss.
+- **Staged categories**: files are extracted under `/tmp/proxsave/restore-stage-*` and then applied to system paths using individual file replacement, not a transaction across categories or API updates; ProxSave explicitly applies mode bits (not left to `umask`) and preserves/derives ownership/group to match expected system defaults (important on PBS, where `proxmox-backup-proxy` runs as `backup`; ProxSave also repairs common `root:root` group regressions by inheriting the destination parent directory's group). On supported filesystems, staged writes also `fsync()` the temporary file and the destination directory to reduce the risk of incomplete writes after a crash/power loss.
- **ctime**: Cannot be set (kernel-managed).
---
@@ -3141,6 +2626,51 @@ rm -r /opt/proxsave/restore/TIMESTAMP
---
+
+
+## Restore IOMMU, VFIO and passthrough settings
+
+Use this procedure after a reinstall or hardware change when recovering host passthrough configuration. Firmware IOMMU support, device IDs, PCI addresses, IOMMU groups and guest disk availability must be checked on the destination. ProxSave does not configure firmware or prove that an old passthrough assignment is safe on new hardware.
+
+1. Keep console or IPMI access and a verified backup with the boot inventory and system service files. Leave affected guests stopped while reviewing device assignments.
+2. Run `proxsave` without arguments as root and choose **Tools > Restore**. Select the backup and decrypt it if required.
+3. Choose **Custom** and select `boot` and `services` when available. The services category also includes systemd, package, sysctl and firewall-related files; inspect the full plan before accepting it. Select `pve_config_export` if you need exported guest configuration for comparison. FULL includes export-only categories; STORAGE and SYSTEM BASE do not.
+4. Review the plan and both overwrite confirmations. The boot merge keeps destination-specific root and memory settings as described below. `/etc/modprobe.d/` and `/etc/modules` are system-service files, so old driver bindings and blacklists still need review on different hardware.
+5. Inspect the restore log for `Boot configuration -` messages and any rebuild warning. Compare exported boot files and guest device references with the destination. A skipped bootloader merge requires a manual edit following the destination's Proxmox bootloader procedure, not copying the old file wholesale.
+6. Reboot only after checking the resulting settings and retaining recovery access. Verify the effective `/proc/cmdline`, IOMMU groups and device driver bindings before applying guest passthrough assignments and starting guests individually. Missing IOMMU groups, incorrect binding, a bootloader warning or an unavailable guest disk means recovery is incomplete.
+
+A restore usually runs on a new machine, whose root device, pool name and ESPs differ from the backed-up host. The `boot` category therefore never writes the old host's boot files: GRUB settings (`/etc/default/grub`, `/etc/default/grub.d/`), `/etc/kernel/cmdline` and `/etc/kernel/proxmox-boot-uuids` are kept in the archive under `var/lib/proxsave-info/boot/` and only reach the export directory. None of these files is written to the live system, in any mode, including the full-restore fallback, not even when `CUSTOM_BACKUP_PATHS` names `/etc/default` or `/etc/kernel` and the archive also holds them at their natural paths: those copies go to the export directory with `proxsave_info`. The rest of `/etc/default` is restored by `services` as before.
+
+**Source**: the backed-up host's effective kernel command line (`/proc/cmdline` at backup time), stored in `var/lib/proxsave-info/commands/system/kernel_cmdline.txt` by every backup.
+
+**Merge rule**:
+- Every parameter is carried except those that describe the backed-up host itself, and anything after `--` (arguments for init):
+ - its root device and boot image: `root=`, `boot=`, `ro`, `rw`, `BOOT_IMAGE=`, `initrd=`;
+ - how its root was mounted and where it resumed from: `rootflags=`, `rootfstype=`, `resume=`, `resume_offset=`. A `rootflags=` or `rootfstype=` of another filesystem makes this host's root mount fail, and the boot stops in the initramfs shell;
+ - what was sized on its RAM or laid out on its memory map: `zfs.zfs_arc_max=` and `zfs.zfs_arc_min=` (the restore keeps this host's ARC limit), `hugepages=`, `hugepagesz=`, `default_hugepagesz=`, `sysctl.vm.nr_hugepages=`, `hugetlb_cma=`, `cma=`, `kernelcore=`, `movablecore=`, `mem=` and `memmap=` (a `memmap=` of another machine's firmware map can stop the boot);
+ - `crashkernel=`: the kdump reservation. On GRUB hosts `kdump-tools` writes it through its own drop-in, sized for this host's RAM; without `kdump-tools` it only takes memory.
+- A parameter this host already has is not added again. When both hosts set the same parameter with different values, this host's value stays (the kernel treats `-` and `_` in parameter names as the same character, so `vfio-pci.ids` and `vfio_pci.ids` are one parameter).
+
+**Where the parameters are written** (Proxmox VE admin guide, *Host Bootloader*, *Editing the Kernel Commandline*):
+
+| This host | File written | Rebuild |
+|-----------|--------------|---------|
+| GRUB, no `/etc/kernel/proxmox-boot-uuids`; `/etc/default/grub`, `/boot/grub/grub.cfg` and `update-grub` present | the value of `GRUB_CMDLINE_LINUX_DEFAULT` in `/etc/default/grub`, the rest of the file untouched | `update-initramfs -u -k all`, then `update-grub` |
+| `proxmox-boot-tool status` reports every ESP as `uefi` (systemd-boot); `/etc/kernel/cmdline` is one line with `root=` | `/etc/kernel/cmdline` | `update-initramfs -u -k all`, then `proxmox-boot-tool refresh` |
+| `proxmox-boot-tool status` reports every ESP as `grub` | the value of `GRUB_CMDLINE_LINUX_DEFAULT` in `/etc/default/grub` | `update-initramfs -u -k all`, then `proxmox-boot-tool refresh` |
+
+Anything else is not recognized with certainty, and nothing is written: the ESPs disagree, `proxmox-boot-tool status` fails, `GRUB_CMDLINE_LINUX_DEFAULT` is not one plain assignment of a literal value, or a file in `/etc/default/grub.d/` sets it too. The restore logs a warning with the reason and the parameters the backup carries.
+
+**Rebuild**: runs once, at the end of the restore, when the merge changed a file or the restore wrote under `/etc/modprobe.d`, `/etc/modules`, `/etc/hostid` or `/etc/zfs`, which the initramfs copies. On a bootloader not recognized with certainty only `update-initramfs` runs, and the bootloader is left as it is. A failed command is a warning with the command and its error; the next command still runs and the restore goes on.
+
+**Safety backup**: the pre-restore `/etc/default/grub` and `/etc/kernel/cmdline` are in the safety backup, like every other file the restore may write.
+
+**Log**: every step is in the restore log, on lines starting with `Boot configuration -`: the backed-up command line, the bootloader found, the parameters added (or not carried because this host sets them differently), and each command run.
+
+For VM/CT configuration application, use [VM/CT Configuration Restore](#vmct-configuration-restore); for failures, use [diagnose failures](TROUBLESHOOTING.md#diagnose-backup-and-restore-failures). CLI entry options are in [CLI reference](CLI_REFERENCE.md).
+
+
+
## Additional Resources
**Related Documentation**:
@@ -3165,13 +2695,13 @@ rm -r /opt/proxsave/restore/TIMESTAMP
The restore workflow provides a **safe, interactive, and flexible** system for recovering Proxmox configurations:
-✅ **Category-based** granular control
-✅ **4 restore modes** for common scenarios
-✅ **Safety backups** before any changes
-✅ **Cluster-aware** service management
-✅ **Export-only protection** for sensitive paths
-✅ **Comprehensive logging** for audit trails
-✅ **Multiple abort points** for user control
+- **Category-based** granular control
+- **4 restore modes** for common scenarios
+- **Safety backups** before any changes
+- **Cluster-aware** service management
+- **Export-only protection** for sensitive paths
+- **Comprehensive logging** for audit trails
+- **Multiple abort points** for user control
**Remember**:
- Start from the dashboard: `proxsave` with no arguments, then **Tools > Restore**
diff --git a/docs/RESTORE_TECHNICAL.md b/docs/RESTORE_TECHNICAL.md
index f881969b..4a35d79d 100644
--- a/docs/RESTORE_TECHNICAL.md
+++ b/docs/RESTORE_TECHNICAL.md
@@ -26,6 +26,61 @@ and decision flow details.
### Entry Points
+### Diagram: Compatibility Validation
+
+```mermaid
+flowchart TD
+ Start([Backup Prepared]) --> DetectCurrent[Detect Current System]
+ DetectCurrent --> CheckSystem{PVE indicators?
PBS indicators?}
+
+ CheckSystem -->|PVE only| CurrentPVE[Current: PVE]
+ CheckSystem -->|PBS only| CurrentPBS[Current: PBS]
+ CheckSystem -->|Both| CurrentDual[Current: DUAL]
+ CheckSystem -->|Neither| CurrentUnknown[Current: Unknown]
+
+ CurrentPVE --> ReadManifest
+ CurrentPBS --> ReadManifest
+ CurrentDual --> ReadManifest
+ CurrentUnknown --> ReadManifest[Read Backup Manifest]
+
+ ReadManifest --> CheckBackupType{manifest.ProxmoxTargets
or ProxmoxType
or hostname pattern}
+ CheckBackupType -->|pve| BackupPVE[Backup: PVE]
+ CheckBackupType -->|pbs| BackupPBS[Backup: PBS]
+ CheckBackupType -->|dual| BackupDual[Backup: DUAL]
+ CheckBackupType -->|Unknown| BackupUnknown[Backup: Unknown]
+
+ BackupPVE --> Compare
+ BackupPBS --> Compare
+ BackupDual --> Compare
+ BackupUnknown --> Compare[Compare Capability Sets]
+
+ Compare --> SharedRole{Any shared role?}
+ SharedRole -->|Yes| ExactMatch{Same role set?}
+ ExactMatch -->|Yes| Compatible([Full Compatibility])
+ ExactMatch -->|No| Partial[Partial Compatibility]
+ Partial --> Filter["Warn user and filter to
supported categories"]
+ Filter --> ProceedAnyway([Proceed with Warning])
+
+ SharedRole -->|No| CheckUnknown{Either side unknown?}
+ CheckUnknown -->|Yes| WarnUnknown["Warn: compatibility
cannot be fully verified"]
+ WarnUnknown --> Proceed([Proceed])
+ CheckUnknown -->|No| Incompatible["No overlapping role"]
+
+ Incompatible --> DisplayWarning["Display Warning:
backup and host roles differ"]
+ DisplayWarning --> AskOverride{Type 'yes'
to continue?}
+
+ AskOverride -->|No| Abort([Abort])
+ AskOverride -->|Yes| ProceedAnyway
+
+ Compatible --> Proceed
+
+ style Start fill:#87CEEB
+ style Proceed fill:#90EE90
+ style ProceedAnyway fill:#FFD700
+ style Abort fill:#FFB6C1
+```
+
+
The restore workflow has one engine and two ways in. Both set the same field and run
the same dispatch, so nothing behaves differently between them.
@@ -149,10 +204,10 @@ Service Management (if cluster)
└─ Unmount /etc/pve
↓
File Extraction (three tiers)
- ├─ Normal categories → /
+ ├─ Normal categories -> /
├─ (RECOVERY) Restart PVE and HA services once config.db is written
- ├─ Export categories → export dir (read-only)
- ├─ Staged categories → stage dir, then applied
+ ├─ Export categories -> export dir (read-only)
+ ├─ Staged categories -> stage dir, then applied
└─ Log all operations
↓
Post-Restore Tasks
@@ -252,10 +307,10 @@ While the TUI session owns the terminal, console log output is swapped to `io.Di
screen.
**Key Sections** (the workflow body lives in `restore_workflow_ui_run.go`, driven by
-`run()` → `runSelectiveRestore()`; each step below names the implementing function(s)
+`run()` -> `runSelectiveRestore()`; each step below names the implementing function(s)
instead of line numbers, which drift on every edit):
-1. **Preparation** (`prepareBundleAndPlan()` → `prepareBundle()`, `detectTargetSystem()` /
+1. **Preparation** (`prepareBundleAndPlan()` -> `prepareBundle()`, `detectTargetSystem()` /
`DetectCurrentSystem()`, `analyzeArchive()` / `AnalyzeRestoreArchive()`,
`confirmCompatibility()` / `ValidateCompatibility()`):
- Decrypt backup if needed
@@ -263,7 +318,7 @@ instead of line numbers, which drift on every edit):
- Validate compatibility
- Analyze categories
-2. **Mode & Category Selection + Plan build** (`selectRestorePlan()` →
+2. **Mode & Category Selection + Plan build** (`selectRestorePlan()` ->
`selectModeAndCategories()` / `GetCategoriesForMode()`, then `PlanRestore()` in
`restore_plan.go` which splits the selection via `splitRestoreCategories()` in `staging.go`):
- User selects restore mode (Full/Storage/Base/Custom)
@@ -272,9 +327,9 @@ instead of line numbers, which drift on every edit):
single-role host the other role's categories go to export
(`redirectOtherProductCategoriesToExport()` in `restore_plan.go`)
-3. **PBS Behavior + Cluster SAFE/RECOVERY Prompt** (`configurePlanForRuntime()` →
- `selectPBSRestoreBehavior()` and `selectClusterRestoreMode()` → `applyClusterRestoreChoice()`
- in `restore_workflow_ui_plan.go`; SAFE redirect via `RestorePlan.ApplyClusterSafeMode()` →
+3. **PBS Behavior + Cluster SAFE/RECOVERY Prompt** (`configurePlanForRuntime()` ->
+ `selectPBSRestoreBehavior()` and `selectClusterRestoreMode()` -> `applyClusterRestoreChoice()`
+ in `restore_workflow_ui_plan.go`; SAFE redirect via `RestorePlan.ApplyClusterSafeMode()` ->
`redirectClusterCategoryToExport()` in `restore_archive.go`):
- Detect cluster payload in backup (`plan.ClusterBackup && plan.NeedsClusterRestore`)
- Prompt user: SAFE (export+API) vs RECOVERY (full restore)
@@ -289,12 +344,12 @@ instead of line numbers, which drift on every edit):
- User confirms (or aborts) before any data is written
5. **Safety Backup** (`createRollbackBackups()` in `restore_workflow_ui_backups_services.go`
- → `CreateSafetyBackup()` in `backup_safety.go`):
+ -> `CreateSafetyBackup()` in `backup_safety.go`):
- Backup files to be overwritten
- Handle backup failures
-6. **PVE Service Management** (`prepareRestoreServices()` → `preparePVEClusterRestore()`
- in `restore_workflow_ui_backups_services.go` → `stopPVEClusterServices()` /
+6. **PVE Service Management** (`prepareRestoreServices()` -> `preparePVEClusterRestore()`
+ in `restore_workflow_ui_backups_services.go` -> `stopPVEClusterServices()` /
`unmountEtcPVE()` / `startPVEClusterServices()` in `restore_services.go`):
- Detect cluster restore need (RECOVERY mode)
- Stop HA services, then PVE services: pve-ha-lrm, pve-ha-crm, pve-cluster, pvedaemon,
@@ -306,28 +361,28 @@ instead of line numbers, which drift on every edit):
restarts them only when the run ends before that point
7. **PBS Service Management** (`preparePBSServices()` in
- `restore_workflow_ui_backups_services.go` → `stopPBSServices()` / `startPBSServices()`
+ `restore_workflow_ui_backups_services.go` -> `stopPBSServices()` / `startPBSServices()`
in `restore_services.go`):
- Detect PBS-specific category restore need
- Stop PBS services: proxmox-backup-proxy, proxmox-backup
- Prompt to continue if stop fails
- Defer restart
-8. **File Extraction** (`prepareAndRestoreSelectedPayloads()` → `extractNormalCategories()` /
+8. **File Extraction** (`prepareAndRestoreSelectedPayloads()` -> `extractNormalCategories()` /
`exportCategories()` in `restore_workflow_ui_extract.go`; engine `extractSelectiveArchive()`
- in `restore_archive.go` → `extractArchiveNative()` in `restore_archive_extract.go`):
+ in `restore_archive.go` -> `extractArchiveNative()` in `restore_archive_extract.go`):
- Extract normal categories to /
- Extract export categories to timestamped directory
- Handle extraction errors
-9. **pvesh SAFE Apply** (`runClusterSafeApply()` in `restore_workflow_ui_extract.go` →
+9. **pvesh SAFE Apply** (`runClusterSafeApply()` in `restore_workflow_ui_extract.go` ->
`runSafeClusterApplyWithUI()` in `restore_workflow_ui_cluster_apply.go`, which drives
`safeClusterApplyUIFlow.run()`; the standalone `runSafeClusterApply()` in
`restore_cluster_apply.go` is the CLI wrapper, not used by this workflow):
- If SAFE cluster mode selected
- Apply VM/CT configs, storage.cfg, datacenter.cfg via API
-10. **Post-Restore** (`runPostRestoreApplyWorkflows()` in `restore_workflow_ui_run.go` →
+10. **Post-Restore** (`runPostRestoreApplyWorkflows()` in `restore_workflow_ui_run.go` ->
`recreateStorageDirectories()` / `applyNetworkConfig()` / `applyFirewallConfig()` /
`applyHAConfig()`; then `applyBootConfiguration()`, `logRestoreCompletion()` and
`checkZFSPoolsAfterRestore()`):
@@ -392,8 +447,8 @@ type Category struct {
**SSH Category Coverage**
-- `./etc/ssh/` → sshd configuration, host keys, authorized_keys
-- `./root/.ssh/` → root private/public keys and known_hosts
+- `./etc/ssh/` -> sshd configuration, host keys, authorized_keys
+- `./root/.ssh/` -> root private/public keys and known_hosts
(these are the paths matched by the `ssh` category during restore)
### File: internal/orchestrator/selective.go
@@ -431,6 +486,38 @@ type Category struct {
### File: internal/orchestrator/decrypt.go
+### Diagram: Decryption Workflow
+
+```mermaid
+flowchart TD
+ Start([Backup selected]) --> Stage[Unwrap bundle or stage complete raw set]
+ Stage --> Verify[Verify checksum of the stored archive before decryption]
+ Verify --> Integrity{Integrity available and valid?}
+ Integrity -->|No| Abort([Abort])
+ Integrity -->|Yes| CheckEnc{Encryption mode?}
+ CheckEnc -->|none| Plain[Use staged plaintext archive]
+ CheckEnc -->|age| Secret[Prompt for AGE key or passphrase]
+ Secret -->|Cancel| Abort
+ Secret --> Decrypt[Decrypt into private work directory]
+ Decrypt --> Result{Succeeded?}
+ Result -->|No| Retry{Retry?}
+ Retry -->|Yes| Secret
+ Retry -->|No| Abort
+ Result -->|Yes| Hash[Calculate plaintext checksum and update working manifest]
+ Plain --> Hash
+ Hash --> Ready([Prepared archive ready])
+ Ready --> Consumer{Workflow?}
+ Consumer -->|Restore| Restore[Analyze and restore selected categories]
+ Consumer -->|Decrypt only| Bundle[Write uncompressed .decrypted.bundle.tar with inner archive and sidecars]
+ Restore --> Cleanup[Remove temporary work directory on normal exit]
+ Bundle --> Cleanup
+
+ style Start fill:#87CEEB
+ style Abort fill:#FFB6C1
+ style Ready fill:#90EE90
+```
+
+
**Purpose**: Handle backup decryption
**Key Functions**:
@@ -463,6 +550,59 @@ type Category struct {
## Execution Flow
+### Diagram: Complete Restore Workflow
+
+This overview shows the normal path. Cancellation and fatal errors unwind through
+the registered cleanup; the summary does not imply every selected operation was
+applied. See the technical guide for the per-step error handling.
+
+```mermaid
+flowchart TD
+ Start(["Dashboard: Tools > Restore
or proxsave --restore"]) --> Select[Select a complete backup set]
+ Select --> Verify[Stage artifacts and verify stored archive integrity]
+ Verify --> Integrity{Valid?}
+ Integrity -->|No| Abort([Abort])
+ Integrity -->|Yes| Encrypted{Encrypted?}
+ Encrypted -->|Yes| Decrypt[Decrypt with AGE]
+ Encrypted -->|No| Compat
+ Decrypt --> Compat[Detect roles and validate compatibility]
+ Compat --> Scope[Select available categories and restore mode]
+ Scope --> Cluster["If cluster payload selected:
choose SAFE or RECOVERY"]
+ Cluster --> Guards["RECOVERY guards:
quorum and isolation checks"]
+ Guards --> Allowed{Can proceed?}
+ Allowed -->|No| Abort
+ Allowed -->|Yes| Plan[Review restore plan]
+ Plan --> Confirm{Both confirmations accepted?}
+ Confirm -->|No| Abort
+ Confirm -->|Yes| Safety[Create safety backup]
+ Safety --> SafetyOK{Created?}
+ SafetyOK -->|No| Continue{Continue without safety backup?}
+ Continue -->|No| Abort
+ Continue -->|Yes| Services
+ SafetyOK -->|Yes| Services["Prepare services when needed:
RECOVERY stops HA before PVE services"]
+ Services --> Normal[Extract normal categories with host-specific guards]
+ Normal --> Restart[Restart stopped PVE services after extraction]
+ Restart --> Fstab[Offer smart fstab merge]
+ Fstab --> Export[Extract export-only categories]
+ Export --> SafeApply[Offer applicable SAFE configuration applies]
+ SafeApply --> Stage[Extract selected sensitive categories strictly]
+ Stage --> StageOK{Stage complete?}
+ StageOK -->|No| Discard[Discard stage and mark its consumers to skip]
+ StageOK -->|Yes| Apply[Apply staged categories]
+ Apply --> Post
+ Discard --> Post["Post-restore tasks and optional live applies:
network, storage directories, DNS, firewall, HA
skip consumers of an incomplete stage"]
+ Post --> Boot[Merge boot settings and rebuild when selected]
+ Boot --> Summary[Report completed, partial or skipped operations]
+ Summary --> Cleanup[Deferred service cleanup and stage removal]
+ Cleanup --> End([Review results and verify host])
+
+ style Start fill:#90EE90
+ style End fill:#90EE90
+ style Abort fill:#FFB6C1
+ style Discard fill:#FFD700
+```
+
+
### Detailed Phase Breakdown
#### Phase 1: Initialization
@@ -495,7 +635,7 @@ err := orchestrator.RunRestoreWorkflowTUI(rt.ctx, rt.cfg, rt.logger, rt.toolVers
#### Phase 2: Backup Preparation
-**File**: `internal/orchestrator/restore_workflow_ui_plan.go` → `prepareBundle()`
+**File**: `internal/orchestrator/restore_workflow_ui_plan.go` -> `prepareBundle()`
```go
candidate, prepared, err := prepareRestoreBundleFunc(ctx, cfg, logger, version, ui)
@@ -546,7 +686,7 @@ type preparedBundle struct {
#### Phase 3: System Detection & Compatibility
-**File**: `internal/orchestrator/restore_workflow_ui_plan.go` → `detectTargetSystem()`, `confirmCompatibility()`
+**File**: `internal/orchestrator/restore_workflow_ui_plan.go` -> `detectTargetSystem()`, `confirmCompatibility()`
This section is the technical source of truth for restore compatibility.
User-facing examples and warning text live in
@@ -630,7 +770,7 @@ the analysis-failure fallback, where export means skipped.
#### Phase 4: Category Analysis
-**File**: `internal/orchestrator/restore_workflow_ui_plan.go` → `analyzeArchive()`
+**File**: `internal/orchestrator/restore_workflow_ui_plan.go` -> `analyzeArchive()`
```go
availableCategories, err := AnalyzeBackupCategories(
@@ -716,7 +856,7 @@ func PathMatchesCategory(filePath string, category Category) bool {
#### Phase 5: Category Selection
-**File**: `internal/orchestrator/restore_workflow_ui_plan.go` → `selectRestorePlan()`
+**File**: `internal/orchestrator/restore_workflow_ui_plan.go` -> `selectRestorePlan()`
```go
// Pick the mode and the categories (GetCategoriesForMode for FULL/STORAGE/BASE,
@@ -792,7 +932,7 @@ The TUI front-end renders the same list as a multi-select
#### Phase 6: Safety Backup
-**File**: `internal/orchestrator/restore_workflow_ui_backups_services.go` → `createSafetyBackup()`
+**File**: `internal/orchestrator/restore_workflow_ui_backups_services.go` -> `createSafetyBackup()`
```go
var safetyBackup *SafetyBackupResult
@@ -873,7 +1013,7 @@ func CreateSafetyBackup(
#### Phase 7: Service Management (Cluster Restore Only)
-**File**: `internal/orchestrator/restore_workflow_ui_backups_services.go` → `preparePVEClusterRestore()`
+**File**: `internal/orchestrator/restore_workflow_ui_backups_services.go` -> `preparePVEClusterRestore()`
```go
needsClusterRestore := systemType == SystemTypePVE &&
@@ -903,7 +1043,7 @@ if needsClusterRestore {
}
```
-**Stop Services** (`internal/orchestrator/restore_services.go` → `stopPVEClusterServices()`):
+**Stop Services** (`internal/orchestrator/restore_services.go` -> `stopPVEClusterServices()`):
```go
func stopPVEClusterServices(ctx context.Context, logger *logging.Logger) error {
commands := [][]string{
@@ -923,7 +1063,7 @@ func stopPVEClusterServices(ctx context.Context, logger *logging.Logger) error {
}
```
-**Start Services** (`internal/orchestrator/restore_services.go` → `startPVEClusterServices()`):
+**Start Services** (`internal/orchestrator/restore_services.go` -> `startPVEClusterServices()`):
```go
func startPVEClusterServices(ctx context.Context, logger *logging.Logger) error {
commands := [][]string{
@@ -943,7 +1083,7 @@ func startPVEClusterServices(ctx context.Context, logger *logging.Logger) error
}
```
-**Unmount** (`internal/orchestrator/restore_services.go` → `unmountEtcPVE()`):
+**Unmount** (`internal/orchestrator/restore_services.go` -> `unmountEtcPVE()`):
```go
func unmountEtcPVE(ctx context.Context, logger *logging.Logger) error {
cmd := exec.CommandContext(ctx, "umount", "/etc/pve")
@@ -997,8 +1137,9 @@ stageAndApplySensitiveCategories(...) // tier 2 -> stage dir, then Phase 10
Staged categories are extracted **strictly**:
`extractSelectiveArchiveStrict(..., failOnPartial=true)`. If any entry fails, the whole
-staged apply is skipped and the live system is left untouched (BH-002), so a partial tree
-is never applied to sensitive config. The plain (non-staged) tiers use
+staged apply is skipped and the incomplete stage is discarded (BH-002), so consumers
+cannot apply that partial tree. Earlier normal extraction, fstab merge and SAFE
+apply may already have changed the live system; this is not a whole-restore rollback. The plain (non-staged) tiers use
`extractSelectiveArchive`, a thin wrapper over `extractSelectiveArchiveStrict(..., false)`
that creates the detailed log in the restore's own directory (`RestoreRunDir()`,
`/restore/`) and calls `extractArchiveNative`.
@@ -1060,6 +1201,66 @@ and anything under `var/lib/proxmox-backup/lock/`.
## Category System
+### Diagram: Category Decision Tree
+
+```mermaid
+flowchart TD
+ Start([Select Restore Mode]) --> Mode{Which Mode?}
+
+ Mode -->|1. FULL| Full[FULL Mode]
+ Mode -->|2. STORAGE| Storage[STORAGE Mode]
+ Mode -->|3. BASE| Base[BASE Mode]
+ Mode -->|4. CUSTOM| Custom[CUSTOM Mode]
+
+ Full --> SystemFull{System Type?}
+ SystemFull -->|PVE| PVEFull[PVE Categories:
- pve_cluster
- storage_pve
- pve_jobs
- pve_notifications
- pve_access_control
- pve_firewall
- pve_ha
- pve_sdn
- corosync
- ceph
+ Common]
+ SystemFull -->|PBS| PBSFull[PBS Categories:
- pbs_host
- datastore_pbs
- maintenance_pbs
- pbs_jobs
- pbs_remotes
- pbs_notifications
- pbs_access_control
- pbs_tape
+ Common]
+ SystemFull -->|DUAL| DualFull[Dual Categories:
- PVE categories
- PBS categories
- Common categories]
+ SystemFull -->|Unknown| CommonFull[Common Only:
- filesystem
- storage_stack
- network
- ssl
- ssh
- scripts
- crontabs
- services
- accounts
- user_data
- zfs
- boot
- proxsave_info]
+
+ Storage --> SystemStorage{System Type?}
+ SystemStorage -->|PVE| PVEStorage[- pve_cluster
- storage_pve
- pve_jobs
- filesystem
- storage_stack
- zfs]
+ SystemStorage -->|PBS| PBSStorage[- datastore_pbs
- maintenance_pbs
- pbs_jobs
- pbs_remotes
- filesystem
- storage_stack
- zfs]
+ SystemStorage -->|DUAL| DualStorage[- PVE storage categories
- PBS storage categories
- filesystem
- storage_stack
- zfs]
+
+ Base --> BaseCats[- network
- ssl
- ssh
- services
- filesystem]
+
+ Custom --> CheckboxMenu[Interactive Menu]
+ CheckboxMenu --> ToggleLoop{Toggle Categories}
+ ToggleLoop -->|Number| Toggle[Toggle Category]
+ Toggle --> ToggleLoop
+ ToggleLoop -->|'a'| SelectAll[Select All]
+ SelectAll --> ToggleLoop
+ ToggleLoop -->|'n'| DeselectAll[Deselect All]
+ DeselectAll --> ToggleLoop
+ ToggleLoop -->|'c'| CustomSelected[User Selection]
+ ToggleLoop -->|'0'| Cancel([Cancel])
+
+ PVEFull --> KeepFull[Include all available categories, including export-only]
+ PBSFull --> KeepFull
+ DualFull --> KeepFull
+ CommonFull --> KeepFull
+ PVEStorage --> FilterExport[Filter Export-Only]
+ PBSStorage --> FilterExport
+ DualStorage --> FilterExport
+ BaseCats --> FilterExport
+ CustomSelected --> NoFilter[Include Export if Selected]
+
+ KeepFull --> Split[Split: Normal, Export-only and Staged]
+ FilterExport --> Split
+ NoFilter --> Split
+ Split --> Result([Selected Categories])
+
+ style Start fill:#90EE90
+ style Result fill:#90EE90
+ style Cancel fill:#FFB6C1
+ style Custom fill:#87CEEB
+ style CheckboxMenu fill:#87CEEB
+```
+
+**Note (PBS)**: ProxSave applies supported PBS staged categories via `proxmox-backup-manager` by default. In **Clean 1:1** mode it may fall back to writing staged `*.cfg` files back to `/etc/proxmox-backup` when API apply is unavailable or fails.
+
+
### Category Definition Structure
```go
@@ -1076,6 +1277,43 @@ type Category struct {
### Category Types
+### Diagram: Category Type Filter
+
+```mermaid
+flowchart TD
+ Start([All Categories]) --> CheckSystem{System Type?}
+
+ CheckSystem -->|PVE| FilterPVE[Filter Categories]
+ CheckSystem -->|PBS| FilterPBS[Filter Categories]
+ CheckSystem -->|DUAL| FilterDual[Filter Categories]
+ CheckSystem -->|Unknown| FilterCommon[Filter Categories]
+
+ FilterPVE --> IncludePVE["Include:
- CategoryTypePVE
- CategoryTypeCommon"]
+ FilterPBS --> IncludePBS["Include:
- CategoryTypePBS
- CategoryTypeCommon"]
+ FilterDual --> IncludeDual["Include:
- CategoryTypePVE
- CategoryTypePBS
- CategoryTypeCommon"]
+ FilterCommon --> IncludeOnlyCommon["Include:
- CategoryTypeCommon only"]
+
+ IncludePVE --> CheckMode{Restore Mode?}
+ IncludePBS --> CheckMode
+ IncludeDual --> CheckMode
+ IncludeOnlyCommon --> CheckMode
+
+ CheckMode -->|Storage/Base| RemoveExport[Remove ExportOnly = true]
+ CheckMode -->|Full| KeepAll[Keep available export-only categories]
+ CheckMode -->|Custom| KeepChosen[Keep selected export-only categories]
+
+ RemoveExport --> Available{In Archive?}
+ KeepAll --> Available
+ KeepChosen --> Available
+
+ Available --> CheckAvailable[Check IsAvailable]
+ CheckAvailable --> Result([Final Category List])
+
+ style Start fill:#87CEEB
+ style Result fill:#90EE90
+```
+
+
```go
const (
CategoryTypePVE CategoryType = "pve" // PVE-specific
@@ -1086,6 +1324,50 @@ const (
### Path Matching Algorithm
+### Diagram: Path Matching Algorithm
+
+```mermaid
+flowchart TD
+ Start([Archive Entry]) --> GetName[Get Entry Name]
+ GetName --> Normalize{Starts with ./ ?}
+ Normalize -->|No| AddPrefix["Prepend './'"]
+ Normalize -->|Yes| LoopCats[For Each Category]
+ AddPrefix --> LoopCats
+
+ LoopCats --> LoopPaths[For Each Category Path]
+ LoopPaths --> CheckExact{Exact Match?}
+ CheckExact -->|Yes| Match([MATCH])
+ CheckExact -->|No| CheckDir{Path Ends with / ?}
+
+ CheckDir -->|No| NextPath[Next Path]
+ CheckDir -->|Yes| CheckPrefix{Entry Starts with Path?}
+ CheckPrefix -->|Yes| Match
+ CheckPrefix -->|No| CheckParent{Entry == Path without / ?}
+ CheckParent -->|Yes| Match
+ CheckParent -->|No| NextPath
+
+ NextPath --> MorePaths{More Paths?}
+ MorePaths -->|Yes| LoopPaths
+ MorePaths -->|No| NextCat[Next Category]
+ NextCat --> MoreCats{More Categories?}
+ MoreCats -->|Yes| LoopCats
+ MoreCats -->|No| NoMatch([NO MATCH])
+
+ style Start fill:#87CEEB
+ style Match fill:#90EE90
+ style NoMatch fill:#FFB6C1
+```
+
+**Examples**:
+
+| Archive Entry | Category Path | Result |
+|--------------|---------------|--------|
+| `./etc/network/interfaces` | `./etc/network/` | Available Prefix match |
+| `./etc/hostname` | `./etc/network/` | Not available No match |
+| `etc/hostname` | `./etc/hostname` | Available After normalize |
+| `./var/lib/pve-cluster/config.db` | `./var/lib/pve-cluster/` | Available Prefix match |
+
+
**File**: `internal/orchestrator/categories.go` (`PathMatchesCategory()`)
```go
@@ -1174,6 +1456,99 @@ func GetStorageModeCategories(systemType string) []Category {
## Service Management
+### Diagram: Service Management Flow
+
+```mermaid
+sequenceDiagram
+ participant User
+ participant Restore
+ participant Services
+ participant FS as Filesystem
+ participant DB as config.db
+
+ User->>Restore: Start restore with pve_cluster, choose RECOVERY
+ Restore->>Services: pvecm status (only with corosync.conf present)
+ alt Quorate with more than one node online
+ break Recovery refused
+ Restore-->>User: Abort before service stop or extraction
+ end
+ else Quorum or node count unreadable
+ Restore->>Services: Read corosync service state
+ alt Corosync inactive or failed
+ Services-->>Restore: Recovery guard passes
+ else Corosync running or state unknown
+ break Recovery refused
+ Restore-->>User: Establish isolation and stopped Corosync first
+ end
+ end
+ else Not quorate or verified one-node quorum
+ Restore->>Restore: Recovery guard passes
+ end
+ Restore->>Restore: Detect needsClusterRestore = true
+
+ Note over Restore,Services: Service Stop Phase
+ Restore->>Services: systemctl stop --no-block pve-ha-lrm (wait up to 180 s, never killed)
+ Services-->>Restore: Stopped (HA resources frozen, watchdog closed)
+ Restore->>Services: systemctl stop pve-ha-crm
+ Services-->>Restore: Stopped (CRM lock released)
+ Restore->>Services: systemctl stop pve-cluster
+ Services->>FS: Unmount /etc/pve (FUSE)
+ Services->>DB: Close file handles
+ Services-->>Restore: Stopped
+
+ Restore->>Services: systemctl stop pvedaemon
+ Services-->>Restore: Stopped
+ Restore->>Services: systemctl stop pveproxy
+ Services-->>Restore: Stopped
+ Restore->>Services: systemctl stop pvestatd
+ Services-->>Restore: Stopped
+
+ Note over Restore,FS: Unmount Phase
+ Restore->>FS: umount /etc/pve
+ FS-->>Restore: Unmounted (or already unmounted)
+
+ Note over Restore: Arm fallback restart (defer), used only if the run ends before the restart below
+
+ Note over Restore,DB: Restore Phase
+ Restore->>DB: Extract /var/lib/pve-cluster/
+ Restore->>DB: Extract config.db
+ DB-->>Restore: Files restored
+
+ Note over Restore,Services: Restart right after the extraction
+ Restore->>Services: systemctl start pve-cluster
+ Services->>DB: Open config.db
+ Services->>FS: Mount /etc/pve (FUSE)
+ Services-->>Restore: Started
+
+ Restore->>Services: systemctl start pvedaemon
+ Services->>FS: Read /etc/pve config
+ Services-->>Restore: Started
+
+ Restore->>Services: systemctl start pveproxy
+ Services-->>Restore: Started
+
+ Restore->>Services: systemctl start pvestatd
+ Services-->>Restore: Started
+
+ Restore->>Services: systemctl start pve-ha-crm
+ Services-->>Restore: Started
+ Restore->>Services: systemctl start pve-ha-lrm
+ Services-->>Restore: Started (HA resources resumed)
+
+ Note over Restore,Services: Later steps (network apply with PVE health checks, boot rebuild)
+
+ Restore-->>User: Restore Complete
+
+ Note over User,Services: Verification Phase
+ User->>Services: pvecm status
+ Services->>DB: Query cluster state
+ Services-->>User: Report actual membership and quorum for review
+ User->>FS: ls /etc/pve/
+ FS->>DB: Query via pmxcfs
+ FS-->>User: Config files visible
+```
+
+
### Lifecycle Management Pattern
**Go defer pattern** ensures cleanup even on errors:
@@ -1217,8 +1592,8 @@ pvestatd
pve-ha-crm, pve-ha-lrm
(need /etc/pve; pve-ha-lrm holds the node's watchdog open)
-Stop order: pve-ha-lrm → pve-ha-crm → pve-cluster → pvedaemon → pveproxy → pvestatd
-Start order: pve-cluster → pvedaemon → pveproxy → pvestatd → pve-ha-crm → pve-ha-lrm
+Stop order: pve-ha-lrm -> pve-ha-crm -> pve-cluster -> pvedaemon -> pveproxy -> pvestatd
+Start order: pve-cluster -> pvedaemon -> pveproxy -> pvestatd -> pve-ha-crm -> pve-ha-lrm
```
The HA services are stopped first because a running `pve-ha-lrm` fences the node
@@ -1252,8 +1627,8 @@ proxmox-backup-proxy
proxmox-backup
(provides backup/restore operations)
-Stop order: proxmox-backup-proxy → proxmox-backup
-Start order: proxmox-backup → proxmox-backup-proxy
+Stop order: proxmox-backup-proxy -> proxmox-backup
+Start order: proxmox-backup -> proxmox-backup-proxy
```
**PBS Service Management Code**:
@@ -1291,6 +1666,62 @@ func shouldStopPBSServices(categories []Category) bool {
### Error Handling Philosophy
+### Diagram: Error Handling Flow
+
+```mermaid
+flowchart TD
+ Start([Operation]) --> Operation{Operation Type}
+
+ Operation -->|User Action| UserAbort{User Cancels?}
+ UserAbort -->|Yes| ReturnAbort[Return ErrRestoreAborted]
+ UserAbort -->|No| Continue[Continue]
+
+ Operation -->|Service Stop| ServiceStop[Stop Service]
+ ServiceStop --> StopResult{Success?}
+ StopResult -->|No| FailFast[FAIL-FAST: Abort Restore]
+ StopResult -->|Yes| Continue
+
+ Operation -->|Safety Backup| CreateBackup[Create Safety Backup]
+ CreateBackup --> BackupResult{Success?}
+ BackupResult -->|No| AskUser{Ask User Continue?}
+ AskUser -->|No| ReturnAbort
+ AskUser -->|Yes| Continue
+ BackupResult -->|Yes| Continue
+
+ Operation -->|File Extract| ExtractFile[Extract File]
+ ExtractFile --> ExtractResult{Success?}
+ ExtractResult -->|No| LogWarning[Log Warning, Increment Failed]
+ ExtractResult -->|Yes| Continue
+ LogWarning --> ContinueLoop[Continue to Next File]
+
+ Operation -->|Service Restart| RestartService[Restart Service - Deferred]
+ RestartService --> RestartResult{Success?}
+ RestartResult -->|No| WarnOnly[Log Warning Only]
+ RestartResult -->|Yes| Continue
+ WarnOnly --> ContinueFinal[Continue Anyway]
+
+ Operation -->|Unmount| UnmountFS[Unmount /etc/pve]
+ UnmountFS --> UnmountResult{Success?}
+ UnmountResult -->|No| WarnContinue[Log Warning, Continue]
+ UnmountResult -->|Yes| Continue
+ WarnContinue --> Continue
+
+ FailFast --> Abort([Abort Restore])
+ ReturnAbort --> Abort
+ Continue --> Success([Success])
+ ContinueLoop --> Success
+ ContinueFinal --> Success
+
+ style Start fill:#87CEEB
+ style Success fill:#90EE90
+ style Abort fill:#FFB6C1
+ style FailFast fill:#FF6347
+ style LogWarning fill:#FFD700
+ style WarnOnly fill:#FFD700
+ style WarnContinue fill:#FFD700
+```
+
+
**Stop Phase**: **FAIL-FAST**
```go
if err := stopPVEClusterServices(ctx, logger); err != nil {
@@ -1314,6 +1745,95 @@ defer func() {
## Cluster SAFE/RECOVERY Mode
+### Diagram: Cluster Database Restore Sequence
+
+```mermaid
+stateDiagram-v2
+ [*] --> Running: Initial State
+
+ state Running {
+ [*] --> ServicesActive
+ ServicesActive: pve-cluster active
+ ServicesActive: pvedaemon active
+ ServicesActive: pveproxy active
+ ServicesActive: /etc/pve mounted
+ }
+
+ Running --> Stopping: User initiates restore
+
+ state Stopping {
+ [*] --> StopLRM
+ StopLRM: systemctl stop --no-block pve-ha-lrm (up to 180 s, never killed)
+ StopLRM --> StopCRM
+ StopCRM: systemctl stop pve-ha-crm
+ StopCRM --> StopCluster
+ StopCluster: systemctl stop pve-cluster
+ StopCluster --> StopDaemon
+ StopDaemon: systemctl stop pvedaemon
+ StopDaemon --> StopProxy
+ StopProxy: systemctl stop pveproxy
+ StopProxy --> StopStatd
+ StopStatd: systemctl stop pvestatd
+ StopStatd --> UnmountPVE
+ UnmountPVE: umount /etc/pve
+ UnmountPVE --> [*]
+ }
+
+ Stopping --> Stopped: All services stopped
+
+ state Stopped {
+ [*] --> ServicesStopped
+ ServicesStopped: All services inactive
+ ServicesStopped: /etc/pve unmounted
+ ServicesStopped: config.db not in use
+ }
+
+ Stopped --> Restoring: Extract files
+
+ state Restoring {
+ [*] --> ExtractDB
+ ExtractDB: Extract /var/lib/pve-cluster/
+ ExtractDB --> WriteFiles
+ WriteFiles: Write config.db
+ WriteFiles: Write supporting files
+ WriteFiles --> [*]
+ }
+
+ Restoring --> Restarting: Files restored
+
+ state Restarting {
+ [*] --> StartCluster
+ StartCluster: systemctl start pve-cluster
+ StartCluster --> ReadDB
+ ReadDB: pmxcfs reads config.db
+ ReadDB --> MountPVE
+ MountPVE: Mount /etc/pve (FUSE)
+ MountPVE --> StartDaemon
+ StartDaemon: systemctl start pvedaemon
+ StartDaemon --> StartProxy
+ StartProxy: systemctl start pveproxy
+ StartProxy --> StartStatd
+ StartStatd: systemctl start pvestatd
+ StartStatd --> StartCRM
+ StartCRM: systemctl start pve-ha-crm
+ StartCRM --> StartLRM
+ StartLRM: systemctl start pve-ha-lrm
+ StartLRM --> [*]
+ }
+
+ Restarting --> Restored: Services restarted right after the extraction
+
+ state Restored {
+ [*] --> ServicesRestored
+ ServicesRestored: All services active
+ ServicesRestored: /etc/pve mounted with RESTORED config
+ ServicesRestored: Membership and quorum verify separately
+ }
+
+ Restored --> [*]: Database phase complete, continue remaining restore steps
+```
+
+
### Standalone vs Cluster Detection
The analyzed archive payload determines restore behavior. `AnalyzeRestoreArchive()`
@@ -1342,8 +1862,9 @@ if plan.ClusterBackup && plan.NeedsClusterRestore {
| Archive analysis failed and full-restore fallback is used | No | Intentionally skipped |
A standalone PVE backup commonly contains `pve_cluster` data, so it normally gets
-the same choice. SAFE moves that category to export-only and leaves
-`/var/lib/pve-cluster/config.db` untouched. RECOVERY keeps it in the normal
+the same choice. SAFE moves that category to export-only instead of replacing
+`/var/lib/pve-cluster/config.db`; later confirmed applies can change live database
+contents through Proxmox interfaces. RECOVERY keeps it in the normal
restore set, stops the HA services and the PVE cluster services, unmounts `/etc/pve`,
restores the database, then restarts the services right after that extraction, before
the later steps (network apply, boot rebuild). Staged `/etc/pve` applies are skipped in
@@ -1407,10 +1928,10 @@ After extraction in SAFE mode, `runSafeClusterApply()` offers API-based restorat
- `scanVMConfigs()`: Scans `/etc/pve/nodes//qemu-server/` and `lxc/`
- `loadPVEGuestInventory()`: Loads and strictly validates the cluster-wide `qemu`/`lxc` ownership map from `/cluster/resources`
- `applyVMConfigs()`: Classifies every VMID before mutation; skips remote/type-mismatched guests, updates matching local guests through `pvesh`, and registers cluster-wide-absent guests through pmxcfs
-- `applyStorageCfg()`: Parses storage.cfg blocks and applies via `pvesh set /cluster/storage/`
+- `applyStorageCfg()`: Parses storage.cfg blocks, creates definitions through `/storage`, and updates existing ones through `/storage/`
- `runPvesh()`: Executes pvesh commands with logging
-Guest apply is fail-closed. The inventory is loaded once before the loop; any command, JSON validation, incomplete-record, or duplicate-VMID error marks the selected guest entries failed without mutating them. A failed API update may fall back to the staged pmxcfs file only when a JSON `status/current` response explicitly says `stopped`.
+Guest apply is fail-closed. The inventory is loaded once before the loop; any command, JSON validation, incomplete-record, or duplicate-VMID error marks the selected guest entries failed without mutating them. File fallback requires both a recognized API schema refusal and a JSON `status/current` response explicitly saying `stopped`. Other API errors do not qualify. After a schema refusal, a running or unverified guest may instead receive an API retry with refused keys removed.
**Flow**:
```go
@@ -1442,9 +1963,65 @@ func runSafeClusterApply(ctx context.Context, reader *bufio.Reader, exportRoot s
## Extraction Engine
+### Diagram: Three-Tier Extraction
+
+`splitRestoreCategories` divides the selected categories into three tiers. Normal
+categories go straight to `/`, export-only categories go to a read-only export
+directory, and staged (sensitive) categories are extracted strictly into a stage
+directory and then applied (Phase 10). If any staged entry fails, the staged apply is
+skipped and the incomplete stage is discarded (BH-002). Normal extraction, fstab
+merge and SAFE apply may already have changed the host; this guard only prevents
+consumers from applying an incomplete staged payload.
+
+```mermaid
+flowchart LR
+ subgraph Input
+ Archive[backup archive]
+ end
+
+ subgraph "Tier 1: Normal categories"
+ Filter1{Matches a
Normal category?}
+ Extract1[Extract to /]
+ end
+
+ subgraph "Tier 2: Export-only categories"
+ Filter2{Matches an
Export-only category?}
+ Extract2[Extract to
Export Dir, read-only]
+ end
+
+ subgraph "Tier 3: Staged (sensitive) categories"
+ Filter3{Matches a
Staged category?}
+ Stage3[Extract to
stage dir, strict]
+ Apply3[Staged apply
PBS/PVE/SDN/ACL/accounts/notify]
+ end
+
+ subgraph Output
+ SystemRoot[System Root /
- /var/lib/pve-cluster/ in RECOVERY
- other normal categories]
+ ExportDir[Export Directory
BASE_DIR/proxmox-config-export-TIMESTAMP/
- etc/pve/storage.cfg
- etc.]
+ Live[Per-category live applies
only from a complete stage - BH-002]
+ end
+
+ Archive --> Filter1
+ Filter1 -->|Yes| Extract1 --> SystemRoot
+
+ Archive --> Filter2
+ Filter2 -->|Yes| Extract2 --> ExportDir
+
+ Archive --> Filter3
+ Filter3 -->|Yes| Stage3 --> StageOK{Complete?}
+ StageOK -->|Yes| Apply3 --> Live
+ StageOK -->|No| Discard[Discard incomplete stage and skip its consumers]
+
+ style Archive fill:#87CEEB
+ style SystemRoot fill:#90EE90
+ style ExportDir fill:#FFD700
+ style Live fill:#FFA500
+```
+
+
### Archive Format Support
-**Decompression** (`internal/orchestrator/restore_decompression.go` → `createDecompressionReader()`):
+**Decompression** (`internal/orchestrator/restore_decompression.go` -> `createDecompressionReader()`):
```go
func createDecompressionReader(ctx context.Context, file *os.File, archivePath string) (io.ReadCloser, error) {
@@ -1477,7 +2054,7 @@ func createDecompressionReader(ctx context.Context, file *os.File, archivePath s
### Selective Extraction Logic
-**File**: `internal/orchestrator/restore_archive_extract.go` → `extractArchiveNative()`
+**File**: `internal/orchestrator/restore_archive_extract.go` -> `extractArchiveNative()`
```go
func extractArchiveNative(ctx context.Context, opts restoreArchiveOptions) error {
@@ -1630,9 +2207,54 @@ corrupt backup) is left as a symlink and does not block cleanup.
## Safety Mechanisms
+### Diagram: Safety Backup Process
+
+The diagram includes the generic extraction command printed by the current code.
+It is not safe to run blindly on a live host, especially for `config.db`. Follow
+[manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites)
+before using a safety archive. It does not undo every API operation.
+
+```mermaid
+flowchart TD
+ Start([Categories Selected]) --> CreatePath[Create /opt/proxsave/restore/TIMESTAMP/]
+ CreatePath --> CreateArchive[Create restore_backup_TIMESTAMP.tar.gz]
+ CreateArchive --> LoopCats[For Each Category]
+
+ LoopCats --> LoopPaths[For Each Path in Category]
+ LoopPaths --> BuildFull["Build Full Path:
/ + path"]
+ BuildFull --> CheckExists{Path Exists?}
+
+ CheckExists -->|No| NextPath[Next Path]
+ CheckExists -->|Yes| CheckType{Type?}
+
+ CheckType -->|File| BackupFile[Add File to TAR]
+ CheckType -->|Directory| WalkDir[Walk Directory Recursively]
+
+ WalkDir --> BackupTree[Add All Files/Dirs to TAR]
+ BackupTree --> NextPath
+ BackupFile --> NextPath
+
+ NextPath --> MorePaths{More Paths?}
+ MorePaths -->|Yes| LoopPaths
+ MorePaths -->|No| NextCat[Next Category]
+
+ NextCat --> MoreCats{More Categories?}
+ MoreCats -->|Yes| LoopCats
+ MoreCats -->|No| CloseTar[Close TAR Archive]
+
+ CloseTar --> Success([Safety Backup Created])
+ Success --> DisplayPath["Display:
/opt/proxsave/restore/TIMESTAMP/restore_backup_TIMESTAMP.tar.gz"]
+ DisplayPath --> Rollback["Show Rollback Command:
tar -xzf backup.tar.gz -C /"]
+
+ style Start fill:#87CEEB
+ style Success fill:#90EE90
+ style DisplayPath fill:#FFD700
+```
+
+
### 1. Path Traversal Prevention
-**Security Check** (`internal/orchestrator/restore_archive_paths.go` → `sanitizeRestoreEntryTargetWithFS()`):
+**Security Check** (`internal/orchestrator/restore_archive_paths.go` -> `sanitizeRestoreEntryTargetWithFS()`):
```go
// Simplified illustration of the containment check. The real implementation is
@@ -1665,7 +2287,7 @@ func targetWithinRoot(target string, destRoot string) bool {
### 2. /etc/pve Hard Guard
-**Absolute Block** (`internal/orchestrator/restore_archive_entries.go` → `shouldSkipRestoreEntryTarget()`):
+**Absolute Block** (`internal/orchestrator/restore_archive_entries.go` -> `shouldSkipRestoreEntryTarget()`):
```go
// only when restoring to the real system root
@@ -1720,6 +2342,116 @@ When restoring to the real system root (`/`), ProxSave avoids blindly overwritin
### 4. PBS Datastore Mount Guards (Offline Storage)
+### Diagram: PBS Datastore Mount Guards
+
+When restoring PBS configuration, a datastore's backing mount may be **offline**
+(not yet mounted). Without protection, restoring the datastore layout, or PBS
+starting afterwards, would write into the empty mount-point directory on the
+**root filesystem**, filling `/` and creating a "ghost" datastore. The mount
+guard blocks that path until the real storage is back.
+
+```mermaid
+flowchart TD
+ Start([Apply PBS datastore guards
Clean 1:1 restore]) --> Each{For each staged
datastore mount target}
+ Each --> Valid{In fstab + valid target?}
+ Valid -->|No| Skip[Leave unguarded]
+ Valid -->|Yes| Root{Mount-point dir on the ROOT
filesystem? i.e. real mount offline}
+ Root -->|No, real mount present| NoOp[No-op]
+ Root -->|Yes| Try{Real storage mounts now?}
+ Try -->|Yes| NoOp
+ Try -->|No| Bind[Bind-mount empty read-only guard dir
RO + nodev + nosuid + noexec]
+ Bind -->|success| Guarded[Path guarded:
writes cannot land on root FS]
+ Bind -->|bind unavailable| Warn[Warn-only: log that the mountpoint
is unguarded; no persistent flag set]
+
+ style Start fill:#87CEEB
+ style Guarded fill:#90EE90
+ style NoOp fill:#90EE90
+ style Warn fill:#FFD700
+ style Skip fill:#FFB6C1
+```
+
+**Auto-restore (shadowing)**: when the real datastore mount comes back online it
+stacks **on top of** the guard (overlay), so the datastore is usable again, but
+the guard is only **shadowed**, not removed.
+
+**Warn-only fallback**: if the read-only bind mount cannot be created, ProxSave logs
+a warning and proceeds **without** a persistent guard. Older versions set a
+`chattr +i` immutable flag here; it survived reboots and could silently re-block the
+mountpoint once the storage was later unmounted, so it was removed.
+
+**Cleanup** (dashboard **Recovery > Cleanup guards**, or `proxsave --cleanup-guards`
+on a headless host):
+- bind-mount guards are unmounted (they also disappear on reboot);
+- **legacy** `chattr +i` immutable flags (from older versions) are cleared, but
+ **skipped while the target is masked by a real mount** (clearing would touch the
+ mounted filesystem);
+- a summary line reports unmounted / hidden-remaining / immutable-cleared /
+ immutable-pending.
+
+Code: `internal/orchestrator/mount_guard.go` (`guardMountPoint` ->
+`bindReadOnlyGuard`), `mount_guard_apply.go`
+(`maybeApplyPBSDatastoreMountGuards` -> `protectOfflineTarget`), and
+`guards_cleanup.go` (`CleanupMountGuards`).
+
+
+### Diagram: Storage Directory Recreation
+
+```mermaid
+flowchart TD
+ Start([Post-Restore]) --> CheckSystem{System Type?}
+
+ CheckSystem -->|PVE| CheckPVECat{storage_pve
Restored?}
+ CheckSystem -->|PBS| CheckPBSCat{datastore_pbs
Restored?}
+ CheckSystem -->|Unknown| Skip([Skip])
+
+ CheckPVECat -->|No| Skip
+ CheckPVECat -->|Yes| ParsePVE[Parse /etc/pve/storage.cfg]
+
+ CheckPBSCat -->|No| Skip
+ CheckPBSCat -->|Yes| ParsePBS[Parse /etc/proxmox-backup/datastore.cfg]
+
+ ParsePVE --> LoopPVE[For Each Storage]
+ LoopPVE --> CheckPVEMount{"Unmounted ZFS/
dedicated mount?
(resolves to rootfs)"}
+
+ CheckPVEMount -->|Yes| WarnPVEMount["Warn: Don't create
(mount disk / import pool first)"]
+ CheckPVEMount -->|No| CheckPVEType{Storage Type?}
+
+ CheckPVEType -->|dir| CreateDirStruct["Create:
- dump/
- images/
- template/
- snippets/
- private/"]
+ CheckPVEType -->|nfs/cifs| CreateNFSStruct["Create:
- dump/
- images/
- template/"]
+ CheckPVEType -->|Other| NextPVE[Next Storage]
+
+ CreateDirStruct --> NextPVE
+ CreateNFSStruct --> NextPVE
+ WarnPVEMount --> NextPVE
+ NextPVE --> MorePVE{More Storage?}
+ MorePVE -->|Yes| LoopPVE
+ MorePVE -->|No| Done([Done])
+
+ ParsePBS --> LoopPBS[For Each Datastore]
+ LoopPBS --> CheckZFSMount{Likely ZFS Mount?}
+
+ CheckZFSMount -->|Yes| WarnZFS["Warn: Don't create
(would block mount)"]
+ CheckZFSMount -->|No| CreatePBSStruct["Create:
- .chunks/ directory
- .lock regular file"]
+
+ WarnZFS --> LogOwner["Log: Should be
backup:backup"]
+ CreatePBSStruct --> LogOwner
+ LogOwner --> NextPBS[Next Datastore]
+
+ NextPBS --> MorePBS{More Datastores?}
+ MorePBS -->|Yes| LoopPBS
+ MorePBS -->|No| CheckZFSCat{zfs Category
Restored?}
+
+ CheckZFSCat -->|Yes| WarnZFSImport["Info: ZFS pools
importable, not imported"]
+ CheckZFSCat -->|No| Done
+ WarnZFSImport --> DisplayCmds["Display:
zpool import
zpool import pool-name"]
+ DisplayCmds --> Done
+
+ style Start fill:#87CEEB
+ style Done fill:#90EE90
+ style Skip fill:#D3D3D3
+```
+
+
For PBS datastores whose paths live under typical mount roots (for example `/mnt/...`), ProxSave aims for a "restore even if offline" behavior:
- PBS datastore definitions are applied even when the underlying storage is offline/not mounted, so PBS shows them as **unavailable** rather than silently dropping them.
@@ -1746,7 +2478,7 @@ This prevents accidental writes into the root filesystem when storage is offline
### 5. Root Privilege Check
-**Pre-Extraction Check** (`internal/orchestrator/restore_archive.go` → `extractPlainArchive()`, `extractSelectiveArchiveStrict()`):
+**Pre-Extraction Check** (`internal/orchestrator/restore_archive.go` -> `extractPlainArchive()`, `extractSelectiveArchiveStrict()`):
```go
// For system-path restoration on the REAL filesystem only
@@ -1772,7 +2504,7 @@ if checksumFile exists {
return fmt.Errorf("checksum mismatch")
}
- logger.Info("✓ Checksum verified successfully")
+ logger.Info("Yes Checksum verified successfully")
} else if manifest.SHA256 != "" {
// Use manifest checksum
actualChecksum := calculateSHA256(archivePath)
@@ -2051,7 +2783,7 @@ func (h *NetworkConfigHook) PreRestore(ctx context.Context, categories []Categor
for _, cat := range categories {
if cat.ID == "network" {
// Warn about network disruption
- fmt.Println("⚠ WARNING: Network configuration will be changed")
+ fmt.Println("Warning: WARNING: Network configuration will be changed")
fmt.Println(" You may lose connection during restore")
return askConfirmation()
}
@@ -2197,28 +2929,23 @@ func TestPathMatchesCategory(t *testing.T) {
### Integration Tests
**Full Restore Workflow**:
-```bash
-#!/bin/bash
-# Test full restore workflow. Both commands are flag invocations on purpose: a
-# script has no TTY, so the dashboard never opens and the CLI front-end is used.
-
-# 1. Create test backup
-proxsave --backup
-# 2. Modify system files
-echo "test" > /etc/hostname
-
-# 3. Run restore (with test responses)
-echo -e "1\n1\n1\nRESTORE\n" | proxsave --restore
-
-# 4. Verify restoration
-if grep -q "original-hostname" /etc/hostname; then
- echo "✓ Restore successful"
-else
- echo "✗ Restore failed"
- exit 1
-fi
-```
+Run destructive integration checks only on a disposable PVE/PBS installation with
+console access and no production cluster or shared-storage membership.
+
+1. Record the host identity, service state and representative configuration contents.
+2. Create a test backup and record its exact artifact names and encryption setup.
+3. Change only the test fixture settings chosen for the scenario.
+4. Run `proxsave --restore --cli` interactively, review the selected backup and scope,
+ and answer the actual prompts. The prompt sequence depends on the payload,
+ encryption, platform, cluster mode and confirmation stages; a fixed list of
+ piped answers is not a valid general driver.
+5. Compare the restored configuration with the recorded baseline and inspect the
+ detailed restore log for skipped or partially applied items.
+6. Revert or destroy the test installation before another scenario.
+
+Use the repository's mocked workflow tests for repeatable checks without modifying
+a real `/etc`; see [Test Strategy](TEST_STRATEGY.md).
### Mocking External Dependencies
diff --git a/docs/SECURITY.md b/docs/SECURITY.md
index a9d80875..82131ce1 100644
--- a/docs/SECURITY.md
+++ b/docs/SECURITY.md
@@ -1,5 +1,7 @@
# Security
+For operational instructions, use [encryption](ENCRYPTION.md), [release verification](PROVENANCE_VERIFICATION.md) and [support preparation](TROUBLESHOOTING.md#getting-help). This reference explains the implementation boundaries behind those procedures
+
This document describes the ProxSave runtime security model: the trust boundary,
how external commands are executed, the preflight checks, and the layers that keep
secrets and untrusted data from doing harm. For the notification and relay security
@@ -265,13 +267,14 @@ aborts the run rather than letting it proceed on an unverified binary or config.
The bound is per syscall and it does not cover the whole preflight. Once the executable is
open, the fstat on it and the SHA256 read of the entire binary are raw unbounded calls, and
inside the private-key scan the directory walk is bounded but the per-file open and read
-are not. A mount that goes stale inside one of those windows still wedges the preflight, and
-**the daemon watchdog does not save you there**. A child that merely overruns
-`MAX_RUN_DURATION` gets `SIGTERM`, then `SIGKILL` after a 30s grace, and is reported as a
-hang. A child stuck in uninterruptible sleep is not reported at all: the daemon reports only
-after the child is reaped, and a D-state process is never reaped, so the daemon blocks in the
-same wedge and stops scheduling. Only the monitor's silence on the missing finish ping
-catches that case (see [DAEMON.md](DAEMON.md)). The daemon also supervises `--backup`
+are not. A mount that goes stale inside one of those windows can still wedge the preflight.
+For a supervised child, the daemon applies `MAX_RUN_DURATION`, sends `SIGTERM`, then
+`SIGKILL` after the grace period, and bounds the final reap wait. If the child still cannot
+be reaped, the daemon reports abandonment, persists the orphan's identity and exits for
+systemd to restart it. The restarted daemon retains the degraded monitoring state while
+that orphan remains. This reports the outage; it cannot repair the mount or kill a task
+stuck in kernel I/O. See the [D-state caveat](DAEMON.md#caveat-uninterruptible-sleep-d-state)
+for the timeout sequence and recovery conditions. The daemon supervises `--backup`
children only, so a restore, a manual run, or a dashboard **Backup** has no watchdog at all
(the dashboard backup is not a daemon child: it runs in the same process as the menu, which
keeps its session open and hands it to the run).
diff --git a/docs/STORAGE.md b/docs/STORAGE.md
new file mode 100644
index 00000000..39cb09ab
--- /dev/null
+++ b/docs/STORAGE.md
@@ -0,0 +1,282 @@
+# Backup destinations, retention and native PBS
+
+
+
+## Choose and verify backup destinations
+
+ProxSave collects host configuration into a working tree. Primary, secondary and rclone
+storage receive an archive of that tree, normally with its metadata and checksum in a
+single `.bundle.tar`. Native PBS receives the tree as a `proxsave.pxar` snapshot instead.
+These are configuration backups, not a replacement for VM, container or PBS datastore
+payload backups. See [backup scope](BACKUP_GUIDE.md#what-proxsave-backs-up).
+
+| Destination | What you configure | Recovery source |
+| --- | --- | --- |
+| Primary filesystem | `BACKUP_PATH` | Primary archive source in Restore or Decrypt |
+| Secondary filesystem or mounted NAS | `SECONDARY_ENABLED`, `SECONDARY_PATH` | Secondary archive source |
+| rclone remote | `CLOUD_ENABLED`, remote and path | Cloud archive source |
+| Native PBS | PVE PBS storage definition and `PBS_TARGET_STORAGE` | External PBS client or PBS interface |
+
+### Configure primary and secondary storage
+
+Run `proxsave` without arguments on an interactive terminal, then choose
+**Maintenance** > **Install** > **Edit install**. Review the installation paths and
+enable `Secondary storage` if needed. Fill in `Secondary backup path` and optionally
+`Secondary log path`. The backup path is required when enabled; the log path can be
+empty. Other storage and retention settings are hand edits of `configs/backup.env`.
+
+The primary archive directory normally resolves to `${BASE_DIR}/backup` through
+`BACKUP_PATH`. The primary copy provides a convenient local recovery source, but a
+copy on the protected host alone cannot survive loss of that host or disk.
+
+A secondary path is an absolute local filesystem path. For NAS storage, mount the
+NFS or SMB share outside ProxSave before configuring it. Check the mount itself,
+read/write access under the backup account and persistence after reboot. Creating a
+directory at the intended mount point does not establish that the NAS is mounted.
+Use rclone if you need remote access without a filesystem mount; see
+[cloud backups](CLOUD_STORAGE.md#set-up-and-recover-cloud-backups).
+
+```bash
+# Example: inspect an existing NAS mount, using your actual path.
+findmnt --target /mnt/nas-backup
+```
+
+Do not place secondary backups inside the primary backup directory. Ensure paths have
+private permissions and enough space. The disk thresholds are
+`MIN_DISK_SPACE_PRIMARY_GB`, `MIN_DISK_SPACE_SECONDARY_GB`,
+`MIN_DISK_SPACE_CLOUD_GB` and `MIN_DISK_SPACE_PBS_GB`. They are checks, not a reservation
+of space for the run. Refer to [configuration](CONFIGURATION.md) for path validation,
+timeouts, permission repair and required-space checks.
+
+### Prove a destination works
+
+1. Choose **Backup** in the dashboard and inspect the initialization and storage
+ results for every enabled destination. An enabled destination that could not
+ initialize is not proof of a saved copy.
+2. Confirm the named bundle exists on primary and secondary storage. With
+ `BUNDLE_ASSOCIATED_FILES=false`, keep the archive and matching `.metadata`,
+ `.sha256` and `.manifest.json` sidecars together.
+3. Choose **Tools** > **Decrypt** for an encrypted archive inspection test, or
+ **Tools** > **Restore** to select the saved archive and review the restore plan.
+ Do not apply configuration to a production host merely to check that a backup is
+ listed. Use a suitable isolated recovery host for a full restore test.
+4. Keep remote credentials and decryption material independently accessible. A
+ credential stored only inside the backup it unlocks cannot bootstrap recovery.
+
+For retention, continue with [retention policies](#set-backup-retention). For native
+PBS, use the [dedicated procedure](#create-native-pbs-backups); its snapshot is not an
+archive listed by the current Restore or Decrypt source selector.
+Command-line equivalents belong in [CLI_REFERENCE.md](CLI_REFERENCE.md).
+
+
+
+
+
+## Set backup retention
+
+Retention deletes old backups after a usable copy has been saved to that destination.
+Plan it against the number and age of recovery points you need, not just free space.
+Changes apply to subsequent runs; reducing a limit can delete older recovery points.
+Keep an independent copy before tightening a policy you have not tested.
+
+There is no dedicated retention form in the dashboard. Edit the active
+`configs/backup.env`, then use **Backup** to run the new policy and inspect the retention
+result. For daemon scheduling changes, use **Daemon** > **Status** and **Restart** as
+needed; see [scheduling](DAEMON.md#schedule-and-supervise-backups).
+
+### Keep the newest backups
+
+`RETENTION_POLICY=simple` keeps a count of newest eligible backups at each destination.
+The `MAX_*_BACKUPS` values are counts, not days, even though older aliases and internal
+field names use the word `days`. Two backups in one day consume two slots.
+
+```bash
+RETENTION_POLICY=simple
+MAX_LOCAL_BACKUPS=15
+MAX_SECONDARY_BACKUPS=15
+MAX_CLOUD_BACKUPS=15
+MAX_PBS_TARGET_BACKUPS=15
+```
+
+These values are an example matching the current shipped template. The compiled
+fallbacks when keys are absent are 7 local, 14 secondary, 30 cloud and 15 native PBS.
+For simple retention, `0` disables deletion for that destination. Logs follow the
+backup retention policy; cloud deletion batching is controlled separately by
+`CLOUD_BATCH_SIZE` and `CLOUD_BATCH_PAUSE`, not upload-worker settings.
+
+### Spread recovery points over time
+
+`RETENTION_POLICY=gfs` uses shared daily, weekly, monthly and yearly tiers across
+enabled destinations. A recovery point selected for more than one tier is kept once.
+The effective daily tier is at least one, including when `RETENTION_DAILY` is empty
+or `0`; GFS cannot be disabled by setting every tier to zero.
+
+```bash
+RETENTION_POLICY=gfs
+RETENTION_DAILY=7
+RETENTION_WEEKLY=4
+RETENTION_MONTHLY=12
+RETENTION_YEARLY=3
+```
+
+Daily points cover the recent window. Weekly points represent past ISO weeks,
+monthly points past months and yearly points past years. This is a distribution
+policy, not a promise that a fixed number of files will always be present: missing
+runs cannot create missing recovery points. Do not add tier counts and interpret the
+sum as a guaranteed minimum.
+
+### Verify retention and understand skipped entries
+
+Choose **Backup**, inspect the reported policy, kept tiers and deletion result, then
+list the remaining recovery points at each destination. Verify a retained old point
+is recoverable as well as the newest point.
+
+Archive retention scopes ownership using backup identity and available metadata.
+Unverifiable entries without a completion manifest/checksum, or without a reliable
+timestamp, are left untouched and do not consume keep slots. Such entries can explain
+why more files remain than the configured limit. Never interpret a filename alone as
+proof that it is safe to delete another host's backup.
+
+Native PBS retention applies to this host's `host/proxsave-` group in the
+configured namespace. Protected snapshots remain protected. A successful upload with
+failed pruning is a saved backup with a retention warning; it does not reclaim space.
+Pruning removes snapshot references. PBS garbage collection and datastore maintenance
+remain separate PBS administration tasks, so pruning does not guarantee immediate disk
+space recovery. Avoid competing PBS server prune jobs unless their policy is deliberate.
+
+See the [configuration key reference](CONFIGURATION.md) for supported values and the
+[native PBS procedure](#create-native-pbs-backups) for pruning permissions.
+
+
+
+
+
+## Create native PBS backups
+
+Native PBS storage sends the collected configuration tree directly to Proxmox Backup
+Server as `proxsave.pxar`, under `host/proxsave-`. It does not upload the AGE
+archive or its `.bundle.tar`. Primary, secondary and cloud archive copies can remain
+enabled alongside it and use their own recovery workflow.
+
+### Prepare PBS and the PVE storage
+
+This destination requires a Proxmox VE host with a resolved hostname and
+`proxmox-backup-client` available in `PATH`. A standalone PBS host is not an eligible
+sender for this destination. ProxSave can still back up a PBS host's configuration
+through its ordinary archive destinations.
+
+Before enabling the destination:
+
+1. On PBS create or select the datastore and, if used, create the namespace. The
+ namespace must already exist; ProxSave checks access and does not create it.
+2. Set up an account or API token with access to the datastore and namespace for
+ listing, backup and recovery. Retention additionally needs `Datastore.Prune` or
+ `Datastore.Modify`. If token privilege separation is enabled, check the token's
+ effective permissions as well as the user account's permissions.
+3. In the Proxmox VE interface add or verify a storage of type **Proxmox Backup Server**.
+ Record its storage ID, server, port if nondefault, datastore, namespace, username
+ or token ID, and certificate fingerprint. Confirm the storage is enabled.
+4. Configure its credentials and encryption through PVE. ProxSave reads the existing
+ storage definition from `/etc/pve/storage.cfg` and credentials from
+ `/etc/pve/priv/storage/.pw`; it has no independent PBS credential form.
+5. Preserve credentials, the chosen repository/namespace and any encryption key
+ outside the node. Test that this independent recovery material is readable.
+
+ProxSave's dashboard has no native PBS setup form. Edit the active `configs/backup.env`:
+
+```bash
+PBS_TARGET_ENABLED=true
+PBS_TARGET_STORAGE=pbs-config-backups
+MAX_PBS_TARGET_BACKUPS=15
+```
+
+Replace `pbs-config-backups` with the actual PVE storage ID, not a datastore name,
+filesystem path or rclone remote. Review `MIN_DISK_SPACE_PBS_GB` and the shared
+[retention policy](#set-backup-retention). The current template disables this destination
+until explicitly configured.
+
+### Check the actual encryption key
+
+The storage's existing `/etc/pve/priv/storage/.enc` controls native PBS
+encryption. When it exists, ProxSave checks it and supplies it as `--keyfile`; it also
+supplies `.master.pem` when that master public key exists. A key that requires a passphrase or whose fingerprint does not match the
+storage definition prevents initialization when the client can inspect it. If key
+inspection itself fails or returns unreadable output, the key is still passed to the
+upload; that upload may fail, but it never silently switches to plaintext. Native
+uploads run with closed stdin, so interactive key passphrases are unsupported.
+
+Without the `.enc` file, ProxSave explicitly uses `--crypt-mode none`, even if
+`ENCRYPT_ARCHIVE=true` and AGE recipients are configured. Conversely an existing PBS
+key is used regardless of the AGE archive toggle. **AGE private identities and AGE
+passphrases do not decrypt PBS snapshots.** Retain the PBS encryption key independently;
+a master public key alone is not recovery material. If you rely on master-key recovery,
+keep the corresponding private master key and validate that recovery separately.
+
+### Run and verify the snapshot
+
+1. Run `proxsave` without arguments and choose **Backup**.
+2. Check `PBS storage: initialized` and the datastore access result. A wrong storage
+ type, disabled definition, missing password, invalid key, inaccessible datastore
+ or missing namespace prevents initialization. An enabled uninitialized block
+ remains visible and later reports that its backup was not saved.
+3. In the storage result confirm the exact snapshot name and `PBS Storage: backup saved`.
+ ProxSave lists the uploaded snapshot and checks its reported encryption mode before
+ treating it as usable. Review exclusion-rule warnings: `.pxarexclude` files in the
+ collected tree affect what the PBS client includes.
+4. In PBS verify the snapshot in the intended namespace and group, inspect
+ `proxsave.pxar`, and review the attached run log. Review retention separately: a
+ pruning permission error can leave a usable snapshot with a warning.
+5. Test recovery to a private directory on another suitable host before relying on
+ this destination as the only surviving recovery copy.
+
+Snapshots use 64 KiB chunks. Client versions supporting it use metadata change
+detection; older clients omit that option. PBS chunk reuse belongs to this native
+format; archive destinations do not gain PBS chunk deduplication by storing a bundle.
+
+### Recover a native PBS snapshot
+
+The current dashboard **Tools** > **Restore** and **Tools** > **Decrypt** select primary,
+secondary or rclone archives. They do not browse native PBS snapshots or convert a
+`pxar` snapshot into a ProxSave restore bundle. Native recovery therefore uses PBS
+outside ProxSave.
+
+Prepare a recovery host with `proxmox-backup-client`, independently recovered access
+credentials and, for encrypted snapshots, the original PBS key or a tested master-key
+recovery path. Use the same repository and namespace as the backup. Confirm the TLS
+fingerprint against a trusted record before providing credentials.
+
+This example runs in a root shell. Replace the repository, namespace and exact
+snapshot timestamp with values from your independent record and PBS listing. Keep
+credentials out of command arguments and shell history:
+
+```bash
+umask 077
+export PBS_REPOSITORY='backup-user@pbs!token@pbs.example:datastore'
+read -r -s -p 'PBS password or token secret: ' PBS_PASSWORD
+printf '\n'
+export PBS_PASSWORD
+export PBS_FINGERPRINT='TRUSTED-CERTIFICATE-FINGERPRINT'
+proxmox-backup-client snapshot list --repository "$PBS_REPOSITORY" --ns config-backups
+install -d -m 700 /root/proxsave-pbs-recovery
+proxmox-backup-client restore \
+ 'host/proxsave-node.example/2026-10-10T02:00:00Z' proxsave.pxar \
+ /root/proxsave-pbs-recovery \
+ --repository "$PBS_REPOSITORY" --ns config-backups \
+ --keyfile /root/recovered-pbs-storage.enc
+unset PBS_PASSWORD
+```
+
+Omit `--ns` for the root namespace. Omit `--keyfile` only for a snapshot known to be
+unencrypted. Ensure the destination is an empty private inspection directory; do not
+use `/` as an extraction destination. Inspect the recovered tree and ensure expected
+configuration files are present. PBS recovery authentication and key handling are
+external client tasks; check the installed client's help if its options differ.
+
+Do not copy the entire tree onto a live host. Applying recovered cluster, network,
+boot or storage configuration needs the same target compatibility and service safety
+planning described in the [restore guide](RESTORE_GUIDE.md#restore-modes) and
+[cluster recovery guide](CLUSTER_RECOVERY.md). Keep an archive destination enabled
+when you need ProxSave's category-based restore workflow. A tested native snapshot
+recovery and a tested archive restore prove different recovery paths.
+
+
diff --git a/docs/TROUBLESHOOTING.md b/docs/TROUBLESHOOTING.md
index 6583fa5a..828b2041 100644
--- a/docs/TROUBLESHOOTING.md
+++ b/docs/TROUBLESHOOTING.md
@@ -4,6 +4,8 @@ Complete troubleshooting guide for Proxsave with common issues, solutions, and d
## Table of Contents
+- [Diagnose backup and restore failures](#diagnose-backup-and-restore-failures)
+- [Prepare a support request](#prepare-a-support-request)
- [Overview](#overview)
- [Common Issues](#common-issues)
- [Build Failures](#1-build-failures)
@@ -21,6 +23,75 @@ Complete troubleshooting guide for Proxsave with common issues, solutions, and d
---
+
+
+
+
+## Diagnose backup and restore failures
+
+Begin with the first failed stage and preserve its log before retrying. A restore retry, support session or debug backup can change the host or write to configured destinations. Determine what completed and what was skipped, especially after a partial restore, rather than treating the final summary as a transaction result.
+
+### Use the dashboard checks
+
+Run `proxsave` without arguments on a real terminal. Use **Daemon > Status** for scheduler/service state, **Diagnostic Checks > Healthchecks** for monitoring, **Diagnostic Checks > Telegram** for relay pairing, and **Maintenance > Upgrade > Check upgrade** for the installed/released version. **Maintenance > Upgrade > Check config** checks the configuration merge before you apply it; **Maintenance > Install > Edit install** is the configuration setup route. A custom configuration file path requires the [CLI reference](CLI_REFERENCE.md#all-flags) direct-entry options, because any argument bypasses the dashboard.
+
+Choose the diagnostic check that matches the failure. A clean backup with exit 1 may have warnings rather than a failed archive. The [exit-code reference](#exit-codes) distinguishes errors, warnings, benign skipped backups, cancelled runs and pending guard cleanup. Read the logged cause before deleting a lock, reinstalling or changing cluster settings.
+
+### Capture useful debug evidence
+
+`--log-level debug` is the principal diagnostic flag. This invocation bypasses the dashboard and enters the normal backup path with debug logging, subject to configuration and runtime checks:
+
+```bash
+proxsave --log-level debug
+```
+
+It can create archives, copy to destinations, apply retention and send notifications. It does not open a dashboard in debug mode. If you want preparation diagnostics first, use:
+
+```bash
+proxsave --dry-run --log-level debug
+```
+
+Dry-run skips storage, retention and notification delivery and does not create a complete backup. It cannot confirm that those stages work. For a restore-specific failure, the explicit diagnostic entry is:
+
+```bash
+proxsave --restore --log-level debug
+```
+
+This opens the interactive restore workflow with debug logging. Plan review and confirmations still apply; accepting them can change the host. Keep console/IPMI access and follow [Restore a host](RESTORE_GUIDE.md#restore-a-host). Cancel before overwrite when you only need selection/scan evidence.
+
+Find the newest relevant log in configured `LOG_PATH`, normally `/opt/proxsave/log`, or the restore log path printed at startup. Check your configuration for changed log paths rather than guessing a hostname-specific filename. Session logs, detailed extraction logs and stage warnings have different purposes. Record the first error, adjacent lines, version, invocation, time, destination/backend and which phase failed. Review secrets before sharing any output; registered-secret redaction does not guarantee arbitrary command output contains no sensitive information.
+
+### Triage by stage
+
+| Failed stage | What to establish | Detailed reference |
+| --- | --- | --- |
+| Build or launch | Repository/module location, binary availability and platform prerequisites. These are external build/install tasks. | [Build Failures](#1-build-failures) |
+| Configuration or permissions | Actual config path, parsed values, directory access and container privilege limits. Use Edit install for setup; do not assume a dashboard custom-path action exists. | [Configuration Issues](#2-configuration-issues) |
+| Archive, encryption or space | Complete archive and sidecars, correct recipient/key, source and destination capacity. A new key cannot decrypt an old archive. | [Encryption Issues](#4-encryption-issues), [Disk Space Issues](#5-disk-space-issues) |
+| Cloud discovery or transfer | Correct rclone remote/config, accessible directory, network/authentication and provider limits. Discovery is non-recursive. A single-file `copyto` does not gain file concurrency from `RCLONE_TRANSFERS`. | [Cloud Storage Issues](#3-cloud-storage-issues) |
+| Retention | Host attribution, identity and complete manifests before renaming or deleting anything. Different-host archives can be intentionally left untouched. | [Disk Space Issues](#5-disk-space-issues) |
+| Notification delivery | Backend selected, channel configuration and provider/API error, separately from successful archive creation. | [Email Notification Issues](#6-email-notification-issues) |
+| Restore preparation or apply | Integrity, decryption, compatibility, selected scope, quorum guard and exact successful/failed category operations. | [Restore Issues](#7-restore-issues), [Restore a host](RESTORE_GUIDE.md#restore-a-host) |
+| Scheduler or monitoring | Daemon alignment, configured checks, provisioning/connectivity and whether the warning preceded notification delivery. | [Backup Monitoring Issues](#8-backup-monitoring-issues) |
+
+### Handle restore warnings conservatively
+
+An incomplete sensitive stage is discarded and its consumers are skipped, but normal extraction, fstab changes or SAFE operations may already have changed the host. Skipping live network reload may still leave validated network files installed for the next restart. Inspect the actual paths and apply log before assuming the original configuration remains intact.
+
+For read-only storage after a restore, confirm the real mount or pool is online first. **Recovery > Cleanup guards** starts with a read-only check and offers Apply when guards exist. A real mount shadows a guard instead of removing it; legacy immutable flags may remain pending while masked. A failed bind guard is warning-only and leaves the target unguarded. Do not create empty datastore content on the root disk to mask a missing backing filesystem.
+
+For cluster problems, use the matching [cluster recovery scenario](CLUSTER_RECOVERY.md#recover-a-proxmox-cluster). Do not bypass a quorum refusal, kill HA LRM, rename a live node or blindly restore a safety archive. The [manual rollback prerequisites](RESTORE_GUIDE.md#manual-rollback-prerequisites) establish the conditions and scope for rollback.
+
+If a clean backup warns about unseen release notes after an upgrade, reopen bare `proxsave` on a real terminal and acknowledge the release-notes screen shown before the menu. There is no separate What's new dashboard action.
+
+### Verify the correction or request help
+
+After a configuration/preparation fix, rerun the relevant read-only check or dry-run first. Then exercise the affected real stage only when its writes and external effects are intended, and verify its resulting archive, transfer, notification or service state. Preserve the original and follow-up log excerpts so a successful retry can be compared with the failure.
+
+If the cause is still unclear, prepare a [support request](#prepare-a-support-request) with the reviewed evidence. **Recovery > Support** runs a debug backup and sends its full log after explicit initial consent; choose a normal debug run instead if you want to inspect the log before sending. Detailed log-reading and external component probes remain in [Debug Procedures](#debug-procedures).
+
+
+
## Overview
This guide covers the most common issues encountered when using Proxsave, along with step-by-step solutions and debugging procedures.
@@ -34,18 +105,17 @@ you to press `Check`, because it has to run a full dry-run first:
|-----------------|-----------------|
| `Daemon` > `Status` | is the scheduler installed, running, beating, and on the binary now on disk |
| `Diagnostic Checks` > `Healthchecks` | is backup monitoring provisioned, and is the daemon really transmitting |
-| `Upgrade` > `Check upgrade` / `Check config` | is this the latest release, and is `backup.env` missing variables the template added |
+| `Maintenance` > `Upgrade` > `Check upgrade` / `Check config` | is this the latest release, and is `backup.env` missing variables the template added |
| `Diagnostic Checks` > `Post-install` | which collectors are enabled here but have nothing to collect, so they warn on every run |
`Recovery` > `Support` runs a debug backup and mails the log to the maintainer, and
`Recovery` > `Cleanup guards` clears leftover restore mount guards. The dashboard opens only when
`proxsave` is invoked with no flags at all on a real terminal; see [DASHBOARD.md](DASHBOARD.md).
-The flags used in the recipes below reach the same code another way. Use them on a headless host,
-from a script or a cron job, or when the TUI cannot run.
+CLI equivalents and automation options are in [CLI reference](CLI_REFERENCE.md). External tools below investigate the host or provider directly; debug commands are explicit diagnostic exceptions.
**Before troubleshooting**:
-1. Check you're running the latest version: the dashboard's `Upgrade` > `Check upgrade`, or `proxsave --version`
+1. Check you're running the latest version: the dashboard's `Maintenance` > `Upgrade` > `Check upgrade`
2. Try dry-run mode first: `proxsave --dry-run --log-level debug`
3. Review the newest log in `LOG_PATH` (default `/opt/proxsave/log`; use your own directory if `LOG_PATH` or `LOCAL_LOG_PATH` is set in `configs/backup.env`). The filename carries the FQDN, so glob the directory rather than guessing: `ls -t /opt/proxsave/log/backup-*.log | head -1`
@@ -122,23 +192,9 @@ installer against the current configuration and writes the file. `Wipe install`
installer after resetting the install directory (`build/`, `daemon_state/`, `env/`, `guards/`, `identity/` and `restore/` are preserved);
it asks you to confirm the wipe first.
-The same two flows without the TUI:
-```bash
-# Run installer to create config
-proxsave --install
-# For a clean reinstall (keeps build/, daemon_state/, env/, guards/, identity/, and restore/), run:
-# proxsave --new-install
+For the existing installation, choose **Maintenance > Install > Edit install**. CLI alternatives are in [CLI reference](CLI_REFERENCE.md#installation-wizard). Wipe install requires explicit confirmation and resets the installation while retaining the documented recovery/state directories; use it only for that intended task.
-# Or copy template manually
-cp internal/config/templates/backup.env configs/backup.env
-nano configs/backup.env
-```
-
-**Using custom path**:
-```bash
-# Specify custom config location
-proxsave --config /etc/pbs/prod.env
-```
+**Using a custom path**: the dashboard does not select an arbitrary configuration file. A non-default configuration path needs the direct-entry options in [CLI reference](CLI_REFERENCE.md#all-flags), which bypass the dashboard.
---
@@ -241,7 +297,7 @@ cat /proc/self/gid_map
usual reasons it never starts are a missing shebang, a value that is a command line rather
than a bare path (no shell is used, so arguments, pipes and redirections are not interpreted),
a path edited in `backup.env` without restarting the daemon, or a run that was not the
- daemon's (a manual `proxsave --backup` and a cron-mode run start neither script).
+ daemon's (a manual **Backup** in the dashboard and a cron-mode run start neither script).
- **A script ProxSave refused to start is not silent.** Before every invocation the daemon
re-opens the configured file and re-checks the opened inode. If that gate refuses, the daemon
log carries one line per refusal:
@@ -366,7 +422,7 @@ rclone lsf gdrive:
**Verify remote in config**:
```bash
# Check rclone config
-rclone config show gdrive
+rclone config redacted gdrive
# Verify backup.env points to correct remote
grep CLOUD_REMOTE configs/backup.env
@@ -443,7 +499,7 @@ RCLONE_TIMEOUT_CONNECTION=120
proxsave --restore --log-level debug
# Or use support mode to capture full diagnostics
-proxsave --restore --support
+# Dashboard action: Tools > Restore
```
If it still fails, run the equivalent manual checks:
@@ -476,7 +532,7 @@ BACKUP_CLUSTER_CONFIG=false
BACKUP_ROOT_HOME=false
```
-> Note: `BACKUP_CLUSTER_CONFIG=false` also skips cluster runtime collection (`pvecm status`, `pvecm nodes`, HA status), which helps avoid non-critical cluster warnings on standalone nodes.
+> Note: `BACKUP_CLUSTER_CONFIG=false` skips Corosync configuration and cluster-specific data/runtime collection (`pvecm status`, `pvecm nodes`, HA status). The pmxcfs database `config.db` is collected independently, including on standalone hosts. Missing Corosync files do not warn on a confirmed standalone host. To exclude the database and its sidecars explicitly, add `config.db*` to `BACKUP_EXCLUDE_PATTERNS`; this removes the database recovery artifact.
---
@@ -486,25 +542,25 @@ BACKUP_ROOT_HOME=false
**Solution**:
```bash
-# Reduce parallel transfers
-nano configs/backup.env
-RCLONE_TRANSFERS=2
+# Edit configs/backup.env: reduce ProxSave workers for raw-file uploads
+CLOUD_UPLOAD_MODE=sequential
+CLOUD_PARALLEL_MAX_JOBS=1
CLOUD_BATCH_SIZE=10
CLOUD_BATCH_PAUSE=3 # Wait 3 seconds between batches
```
-**Provider-specific tuning**:
+**Provider-specific starting settings** (batch settings affect retention deletions, not upload chunks):
**Google Drive**:
```bash
-RCLONE_TRANSFERS=2
+CLOUD_PARALLEL_MAX_JOBS=1
CLOUD_BATCH_SIZE=10
CLOUD_BATCH_PAUSE=2
```
**Backblaze B2**:
```bash
-RCLONE_TRANSFERS=2
+CLOUD_PARALLEL_MAX_JOBS=1
CLOUD_BATCH_SIZE=20
CLOUD_BATCH_PAUSE=2
```
@@ -547,13 +603,7 @@ rm /tmp/test.txt
**Cause**: Trying to run encryption wizard in non-interactive environment (cron, systemd).
**Solution 1: Pre-generate keys**:
-```bash
-# Run key generation interactively first
-proxsave --newkey
-
-# Then run backup (uses existing keys)
-proxsave
-```
+Choose **Maintenance > New key** in the dashboard, then **Backup > Backup** once recipients are configured.
**Solution 2: Set recipient directly**:
```bash
@@ -589,7 +639,7 @@ age --decrypt -i configs/age-keys.txt backup.tar.xz.age > test.tar.xz
> **Passphrase-based backups**: the archive is encrypted to an X25519 recipient
> *derived* from your passphrase, not with age's native passphrase (scrypt) mode,
> so `age --decrypt` will not prompt for a passphrase and cannot decrypt it on its
-> own. Use `proxsave --decrypt` and enter the passphrase when prompted: proxsave
+> own. Use **Tools > Decrypt** in the dashboard and enter the passphrase when prompted: proxsave
> re-derives the matching identity using the per-installation salt recorded in the
> backup manifest (`passphrase_salt`).
@@ -665,7 +715,7 @@ COMPRESSION_LEVEL=3
---
-#### Warning: `⚠ Backups deleted: , named not rotated`
+#### Warning: `Warning: Backups deleted: , named not rotated`
**Symptoms**: under `Applying retention policy...` the run prints ` Named , not rotated: backups`, then the warning above. The location can keep growing past `MAX_LOCAL_BACKUPS` / `MAX_SECONDARY_BACKUPS` / `MAX_CLOUD_BACKUPS`.
@@ -676,7 +726,7 @@ COMPRESSION_LEVEL=3
Related lines, no action needed:
-- ` Adopted: backups named , same server identity`: archives named for another host that record this host's server identity. They rotate with the others. A clone of this machine that kept its server identity and writes to the same location has its archives rotated here too. While that clone is still writing, the run also warns `⚠ Server identity shared with ` (next section).
+- ` Adopted: backups named , same server identity`: archives named for another host that record this host's server identity. They rotate with the others. A clone of this machine that kept its server identity and writes to the same location has its archives rotated here too. While that clone is still writing, the run also warns `Warning: Server identity shared with ` (next section).
- ` Other server identity: backups owned by name, still rotated`: archives with this host's name and a different server identity (reinstalling ProxSave or restoring `BASE_DIR` from elsewhere mints a new one). They rotate as before.
- Archives of other hosts, and pre-Go archives that name no host, are not reported and are never deleted. A run with `--log-level debug` lists them on `retention out of scope` lines.
@@ -753,11 +803,11 @@ Never pipe the listing straight into `rm`: the same directory may hold another m
grep -E "not rotated|Backups: [0-9]+, limit|Backups deleted" \
"$(ls -t /opt/proxsave/log/backup-*.log | head -1)"
```
-No `not rotated` line is left, and the run reports ` Backups: N, limit: M` and `✓ Backups deleted: K` with a `K` that matches what you expect.
+No `not rotated` line is left, and the run reports ` Backups: N, limit: M` and `Yes Backups deleted: K` with a `K` that matches what you expect.
---
-#### Warning: `⚠ Server identity shared with `
+#### Warning: `Warning: Server identity shared with `
**Symptoms**: under `Applying retention policy...` the run prints ` Adopted: backups named , same server identity` and ` Still writing here: `, then the warning above, right after the backups outcome. The run ends with exit code 1 and the warning is listed in the notifications.
@@ -805,8 +855,8 @@ This mode uses Proxmox Notifications via `proxmox-mail-forward`. It is the recom
- Set `EMAIL_RECIPIENT=...`, or
- Leave it empty and set an email for `root@pam` inside Proxmox (auto-detect).
- Recipient auto-detection details (when `EMAIL_RECIPIENT` is empty):
- - **PVE**: `pvesh get /access/users/root@pam` → fallback to `pveum user list` → fallback to `/etc/pve/user.cfg`
- - **PBS**: `proxmox-backup-manager user list` → fallback to `/etc/proxmox-backup/user.cfg`
+ - **PVE**: `pvesh get /access/users/root@pam` -> fallback to `pveum user list` -> fallback to `/etc/pve/user.cfg`
+ - **PBS**: `proxmox-backup-manager user list` -> fallback to `/etc/proxmox-backup/user.cfg`
- **Dual**: intentionally reuses the **PVE** path for `root@pam` email discovery
- Relay blocks `root@...` recipients; use a real non-root mailbox for `EMAIL_RECIPIENT`.
- If `EMAIL_FALLBACK_SENDMAIL=true`, ProxSave will fall back to local `/usr/sbin/sendmail` when relay delivery fails. If relay cannot start because no recipient is available, sendmail cannot help either; configure `EMAIL_RECIPIENT` or the `root@pam` email in Proxmox.
@@ -865,7 +915,7 @@ This mode uses `/usr/sbin/sendmail`, so your node must have a working local MTA
---
-#### Warning: `⚠ disk space: insufficient, copy may fail`
+#### Warning: `Warning: disk space: insufficient, copy may fail`
**Cause**: a non-critical destination (secondary or cloud) is below its required free space, so the run warns and carries on. The lines above the warning show `Available:`, `Required:` and, in the check after the collection, the `Rule:` that set the requirement. The primary destination is critical instead: if it is short of space the run stops with a disk-space error rather than warning.
@@ -900,10 +950,9 @@ pvesm status
mount -t nfs : /mnt/pve/  -
-
 -
-