
一、安装
地址:MaskRCNN-Benchmark(Pytorch版本)
首先要阅读官网说明的环境要求,千万不要一股脑直接安装,不然后面程序很有可能会报错!!!
- PyTorch 1.0 from a nightly release. It will not work with 1.0 nor 1.0.1. Installation instructions can be found in https://pytorch.org/get-started/locally/
- torchvision from master
- cocoapi
- yacs
- matplotlib
- GCC >= 4.9
- OpenCV
# first, make sure that your conda is setup properly with the right environment
# for that, check that `which conda`, `which pip` and `which python` points to the
# right path. From a clean conda env, this is what you need to do

conda create --name maskrcnn_benchmark
conda activate maskrcnn_benchmark

# this installs the right pip and dependencies for the fresh python
conda install ipython

# maskrcnn_benchmark and coco api dependencies
pip install ninja yacs cython matplotlib tqdm opencv-python

# follow PyTorch installation in https://pytorch.org/get-started/locally/
# we give the instructions for CUDA 9.0
conda install -c pytorch pytorch-nightly torchvision cudatoolkit=9.0

export INSTALL_DIR=$PWD

# install pycocotools
cd $INSTALL_DIR
git clone https://github.com/cocodataset/cocoapi.git
cd cocoapi/PythonAPI
python setup.py build_ext install

# install apex
cd $INSTALL_DIR
git clone https://github.com/NVIDIA/apex.git
cd apex
python setup.py install --cuda_ext --cpp_ext

# install PyTorch Detection
cd $INSTALL_DIR
git clone https://github.com/facebookresearch/maskrcnn-benchmark.git
cd maskrcnn-benchmark

# the following will install the lib with
# symbolic links, so that you can modify
# the files if you want and won't need to
# re-build it
python setup.py build develop


unset INSTALL_DIR

# or if you are on macOS
# MACOSX_DEPLOYMENT_TARGET=10.9 CC=clang CXX=clang++ python setup.py build develop
一定要按上面的说明一步一步来,千万别省略,不然后面程序很有可能会报错!!!
二、数据准备
转换成COCO格式即可!
三、文件配置
在训练自己的数据集过程中需要修改的地方可能很多,下面我就列出常用的几个:
- 修改
maskrcnn_benchmark/config/paths_catalog.py中数据集路径:
class DatasetCatalog(object):
    # 看自己的实际情况修改路径!!!
    # 看自己的实际情况修改路径!!!
    # 看自己的实际情况修改路径!!!
    DATA_DIR = ""
    DATASETS = {
        "coco_2017_train": {
            "img_dir": "coco/train2017",
            "ann_file": "coco/annotations/instances_train2017.json"
        },
        "coco_2017_val": {
            "img_dir": "coco/val2017",
            "ann_file": "coco/annotations/instances_val2017.json"
        },
        # 改成训练集所在路径!!!
        # 改成训练集所在路径!!!
        # 改成训练集所在路径!!!
        "coco_2014_train": {
            "img_dir": "/data1/hqj/traffic-sign-identification/trained",
            "ann_file": "/data1/hqj/traffic-sign-identification/trained.json"
        },
        # 改成验证集所在路径!!!
        # 改成验证集所在路径!!!
        # 改成验证集所在路径!!!
        "coco_2014_val": {
            "img_dir": "/data1/hqj/traffic-sign-identification/val",
            "ann_file": "/data1/hqj/traffic-sign-identification/val.json"
        },
        # 改成测试集所在路径!!!
        # 改成测试集所在路径!!!
        # 改成测试集所在路径!!!
        "coco_2014_test": {
            "img_dir": "/data1/hqj/traffic-sign-identification/test"
        ...
- config下的配置文件:
由于这个文件下的参数很多,往往需要根据自己的具体需求改,我就列出自己的配置(使用的是e2e_faster_rcnn_X_101_32x8d_FPN_1x.yaml,其中我有注释的必须改,比如 NUM_CLASSES):
INPUT:
  MIN_SIZE_TRAIN: (1000,)
  MAX_SIZE_TRAIN: 1667
  MIN_SIZE_TEST: 1000
  MAX_SIZE_TEST: 1667
MODEL:
  META_ARCHITECTURE: "GeneralizedRCNN"
  WEIGHT: "catalog://ImageNetPretrained/FAIR/20171220/X-101-32x8d"
  BACKBONE:
    CONV_BODY: "R-101-FPN"
  RPN:
    USE_FPN: True
    BATCH_SIZE_PER_IMAGE: 128
    ANCHOR_SIZES: (16, 32, 64, 128, 256)
    ANCHOR_STRIDE: (4, 8, 16, 32, 64)
    PRE_NMS_TOP_N_TRAIN: 2000
    PRE_NMS_TOP_N_TEST: 1000
    POST_NMS_TOP_N_TEST: 1000
    FPN_POST_NMS_TOP_N_TEST: 1000
    FPN_POST_NMS_TOP_N_TRAIN: 1000
    ASPECT_RATIOS : (1.0,)
  FPN:
    USE_GN: True
  ROI_HEADS:
    # 是否使用FPN
    USE_FPN: True
  ROI_BOX_HEAD:
    USE_GN: True
    POOLER_RESOLUTION: 7
    POOLER_SCALES: (0.25, 0.125, 0.0625, 0.03125)
    POOLER_SAMPLING_RATIO: 2
    FEATURE_EXTRACTOR: "FPN2MLPFeatureExtractor"
    PREDICTOR: "FPNPredictor"
    # 修改成自己任务所需要检测的类别数+1
    NUM_CLASSES: 22
  RESNETS:
    BACKBONE_OUT_CHANNELS: 256
    STRIDE_IN_1X1: False
    NUM_GROUPS: 32
    WIDTH_PER_GROUP: 8
DATASETS:
  # paths_catalog.py文件中的配置,数据集指定时如果仅有一个数据集不要忘了逗号(如:("coco_2014_val",))
  TRAIN: ("coco_2014_train",)
  TEST: ("coco_2014_val",)
DATALOADER:
  SIZE_DIVISIBILITY: 32
SOLVER:
  BASE_LR: 0.001
  WEIGHT_DECAY: 0.0001
  STEPS: (240000, 320000)
  MAX_ITER: 360000
  # 很重要的设置,具体可以参见官网说明:https://github.com/facebookresearch/maskrcnn-benchmark/blob/master/README.md
  IMS_PER_BATCH: 1
  # 保存模型的间隔
  CHECKPOINT_PERIOD: 18000
# 输出文件路径
OUTPUT_DIR: "./weight/"
- 如果只做检测任务的话,删除
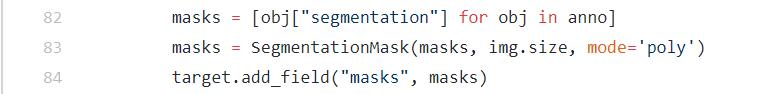
maskrcnn-benchmark/maskrcnn_benchmark/data/datasets/coco.py中 82-84这三行比较保险。 maskrcnn_benchmark/engine/trainer.py中 第 90 行可设置输出日志的间隔(默认20,我感觉输出太频繁,看你自己)
四、模型训练
- 单GPU
官网给出的是:
python /path_to_maskrcnn_benchmark/tools/train_net.py --config-file "/path/to/config/file.yaml"
但是这个默认会使用第一个GPU,如果想指定GPU的话,可以使用以下命令:
# 3是要使用GPU的ID
CUDA_VISIBLE_DEVICES=3 python /path_to_maskrcnn_benchmark/tools/train_net.py --config-file "/path/to/config/file.yaml"
如果出现内存溢出的情况,这时候就需要调整参数,具体可以参见官网:内存溢出解决
- 多GPU
官网给出的是:
export NGPUS=8
python -m torch.distributed.launch --nproc_per_node=$NGPUS /path_to_maskrcnn_benchmark/tools/train_net.py --config-file "path/to/config/file.yaml" MODEL.RPN.FPN_POST_NMS_TOP_N_TRAIN images_per_gpu x 1000
但是这个默认会随机使用GPU,如果想指定GPU的话,可以使用以下命令:
# --nproc_per_node=4 是指使用GPU的数目为4
CUDA_VISIBLE_DEVICES=0,1,2,3 python -m torch.distributed.launch --nproc_per_node=4  /path_to_maskrcnn_benchmark/tools/train_net.py --config-file "path/to/config/file.yaml"
遗憾的是,多GPU在我的服务器上一直运行不成功,还请大家帮忙解决!!!
五、模型验证
- 修改 config 配置文件中
WEIGHT: "../weight/model_final.pth"(此处应为训练完保存的权重) - 运行命令:
CUDA_VISIBLE_DEVICES=5 python tools/test_net.py --config-file "/path/to/config/file.yaml" TEST.IMS_PER_BATCH 8
其中TEST.IMS_PER_BATCH 8也可以在config文件中直接配置:
TEST:
  IMS_PER_BATCH: 8
六、模型预测
- 修改 config 配置文件中
WEIGHT: "../weight/model_final.pth"(此处应为训练完保存的权重) - 修改
demo/predictor.py中 CATEGORIES ,替换成自己数据的物体类别(如果想可视化结果,没有可以不改,可以参考demo/下面的例子):
class COCODemo(object):
    # COCO categories for pretty print
    CATEGORIES = [
        "__background",
        ...
    ]
- 新建一个文件
demo/predict.py(需要修改的地方已做注释)
#!/usr/bin/env python
# coding=UTF-8
'''
@Description:
@Author: HuangQinJian
@LastEditors: HuangQinJian
@Date: 2019-05-01 12:36:04
@LastEditTime: 2019-05-03 17:29:23
'''
import os

import matplotlib.pylab as pylab
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
from PIL import Image

from maskrcnn_benchmark.config import cfg
from predictor import COCODemo
from tqdm import tqdm

# this makes our figures bigger
pylab.rcParams['figure.figsize'] = 20, 12

# 替换成自己的配置文件
# 替换成自己的配置文件
# 替换成自己的配置文件
config_file = "../configs/e2e_faster_rcnn_R_50_FPN_1x.yaml"

# update the config options with the config file
cfg.merge_from_file(config_file)
# manual override some options
cfg.merge_from_list(["MODEL.DEVICE", "cuda"])


def load(img_path):
    pil_image = Image.open(img_path).convert("RGB")
    # convert to BGR format
    image = np.array(pil_image)[:, :, [2, 1, 0]]
    return image

# 根据自己的需求改
# 根据自己的需求改
# 根据自己的需求改
coco_demo = COCODemo(
    cfg,
    min_image_size=1600,
    confidence_threshold=0.7,
)

# 测试图片的路径
# 测试图片的路径
# 测试图片的路径
imgs_dir = '/data1/hqj/traffic-sign-identification/test'
img_names = os.listdir(imgs_dir)

submit_v4 = pd.DataFrame()
empty_v4 = pd.DataFrame()

filenameList = []

X1List = []
X2List = []
X3List = []
X4List = []

Y1List = []
Y2List = []
Y3List = []
Y4List = []

TypeList = []

empty_img_name = []

# for img_name in img_names:
for i, img_name in enumerate(tqdm(img_names)):
    path = os.path.join(imgs_dir, img_name)
    image = load(path)
    # compute predictions
    predictions = coco_demo.compute_prediction(image)
    try:
        scores = predictions.get_field("scores").numpy()
        bbox = predictions.bbox[np.argmax(scores)].numpy()
        labelList = predictions.get_field("labels").numpy()
        label = labelList[np.argmax(scores)]

        filenameList.append(img_name)
        X1List.append(round(bbox[0]))
        Y1List.append(round(bbox[1]))
        X2List.append(round(bbox[2]))
        Y2List.append(round(bbox[1]))
        X3List.append(round(bbox[2]))
        Y3List.append(round(bbox[3]))
        X4List.append(round(bbox[0]))
        Y4List.append(round(bbox[3]))
        TypeList.append(label)
        # print(filenameList, X1List, X2List, X3List, X4List, Y1List,
        #       Y2List, Y3List, Y4List, TypeList)
        print(label)
    except:
        empty_img_name.append(img_name)
        print(empty_img_name)

submit_v4['filename'] = filenameList
submit_v4['X1'] = X1List
submit_v4['Y1'] = Y1List
submit_v4['X2'] = X2List
submit_v4['Y2'] = Y2List
submit_v4['X3'] = X3List
submit_v4['Y3'] = Y3List
submit_v4['X4'] = X4List
submit_v4['Y4'] = Y4List
submit_v4['type'] = TypeList

empty_v4['filename'] = empty_img_name

submit_v4.to_csv('submit_v4.csv', index=None)
empty_v4.to_csv('empty_v4.csv', index=None)
- 运行命令:
CUDA_VISIBLE_DEVICES=5 python demo/predict.py
七、结束语
-
若有修改
maskrcnn-benchmark文件夹下的代码,一定要重新编译!一定要重新编译!一定要重新编译! -
欢迎大家关注我的 CSDN,干货满满!