
A Streamlit web app that predicts whether a loan applicant represents a good or bad credit risk, based on the German Credit Risk dataset. The app uses a trained ExtraTrees classifier and label encoders to turn user input into a prediction in real time.

App Screenshots
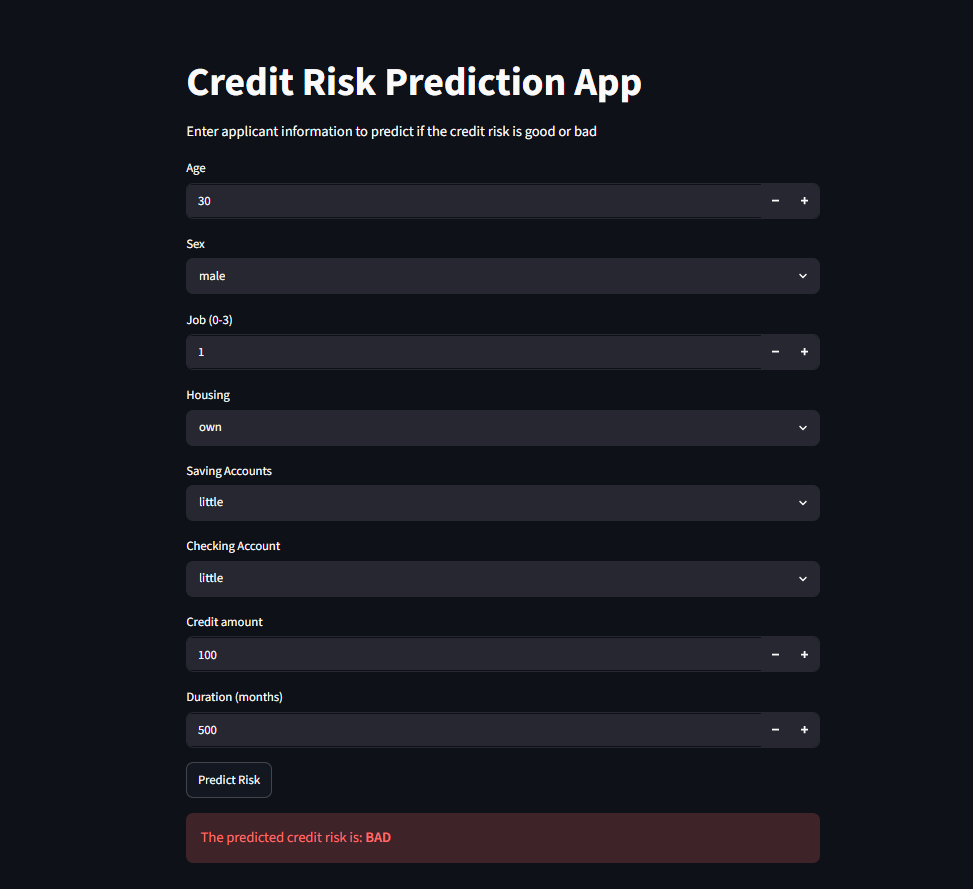 |
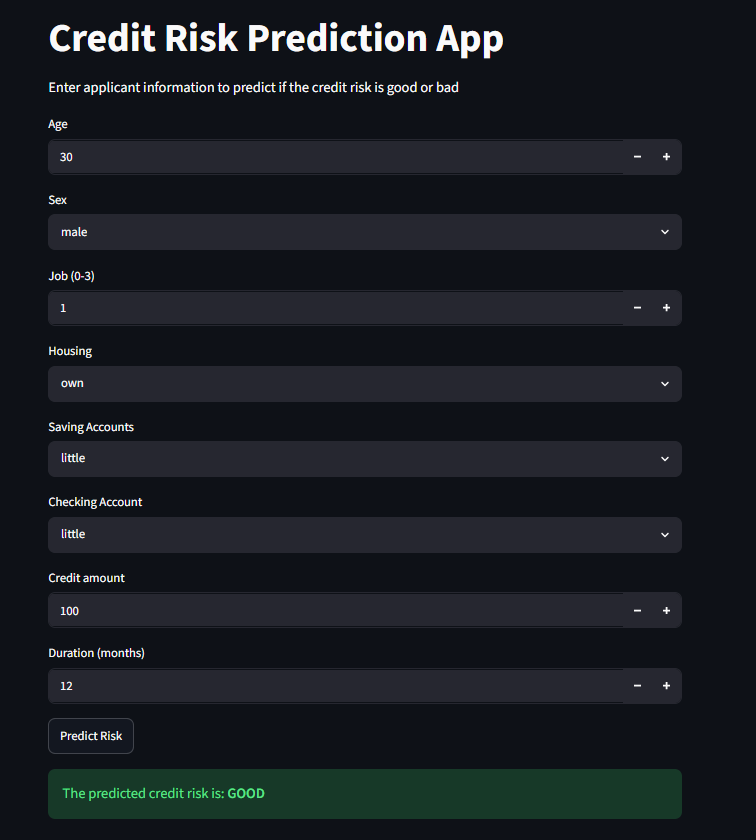 |
Enter applicant details (age, sex, job category, housing, savings, checking account, credit amount, loan duration) into the form, click Predict Risk, and the app returns a GOOD or BAD credit risk classification.
.
├── app.py                          # Streamlit app
├── train_model.ipynb                # Notebook used to train the model and encoders
├── extra_trees_credit_model.pkl    # Trained ExtraTrees classifier
├── Sex_encoder.pkl                 # Label encoder for "Sex"
├── Housing_encoder.pkl              # Label encoder for "Housing"
├── Saving accounts_encoder.pkl      # Label encoder for "Saving accounts"
├── Checking account_encoder.pkl     # Label encoder for "Checking account"
├── requirements.txt
└── README.md
This project uses the German Credit Risk dataset, originally from the UCI Machine Learning Repository and commonly hosted on Kaggle. It contains 1,000 entries of loan applicants with attributes such as age, sex, job, housing situation, savings and checking account status, credit amount, and loan duration, labeled as good or bad credit risk.
- The model and encoders are trained offline (see the training notebook/script) and saved as
.pklfiles usingjoblib. app.pyloads the trained model and encoders.- The user fills out a form in the browser with applicant details.
- Categorical fields (Sex, Housing, Saving accounts, Checking account) are transformed using the saved label encoders to match the format the model was trained on.
- The model predicts credit risk, and the result is displayed as GOOD or BAD.
- Python 3.9+
- pip
-
Clone the repository:
git clone https://github.com/<thomasmamaila33>/<Credit-Risk-App>.git
cd <Credit-Risk-App>
-
(Optional but recommended) Create and activate a virtual environment:
python -m venv venv
# Windows
venv\Scripts\activate
# macOS/Linux
source venv/bin/activate
-
Install dependencies:
pip install -r requirements.txt
streamlit run app.pyThe app will open automatically in your browser at http://localhost:8501. If it doesn't, copy that URL into your browser manually.
- Algorithm: Extra Trees Classifier (
ExtraTreesClassifierfrom scikit-learn) - Features used: Age, Sex, Job, Housing, Saving accounts, Checking account, Credit amount, Duration
- Target: Credit risk (Good / Bad)
- Preprocessing: Categorical features encoded with
LabelEncoder, saved per-column as separate.pklfiles
- Add input validation and friendlier error messages for unseen category values
- Display model confidence/probability alongside the prediction
- Add feature importance visualization
- Containerize with Docker for easier deployment
- Deploy to Streamlit Community Cloud for a live demo link
This project is open source and available under the MIT License.
- Dataset: German Credit Risk dataset (UCI Machine Learning Repository)
- Built with Streamlit and scikit-learn